
- Requirements
- Metadata Ingestion
- Query Usage
- Data Profiler
- Data Quality
- Lineage
- dbt Integration
- Enable Security
- Troubleshooting
- Reverse Metadata
Requirements
Metadata
Redshift user must grantSELECT privilege on table SVV_TABLE_INFO to fetch the metadata of tables and views. For more information, see Redshift Data Visibility.
Note: The Redshift connector supports both Amazon Redshift Provisioned (cluster) and Amazon Redshift Serverless starting from release 1.11.5. The connector automatically detects the deployment type during ingestion and uses the appropriate system views for query and lineage extraction. No additional configuration changes are required.
Profiler and Data Quality
Executing the profiler workflow or data quality tests requires the user to haveSELECT permission on the tables/schemas where the profiler/tests will be executed. For more information, see Profiler Workflow and Data Quality.
Usage and Lineage
For the usage and lineage workflow, the user will needSELECT privilege on STL_QUERY table. For more information, see Usage Workflow and Lineage Workflow.
Datashare Databases
On a consumer cluster, Collate also ingests databases created from a datashare. The connector identifies these non-local databases and reads their schemas, tables, columns, and descriptions through Redshift’s cross-database catalog views. No additional configuration is required.Metadata Ingestion
To ingest metadata from Redshift, you need to create a service connection. The service connects Redshift with Collate. Once you create a service, Collate automatically starts ingesting metadata.Step 1: Add New Service
Open the Services page and start a new service.-
Navigate to Settings > Services and select Database Services.
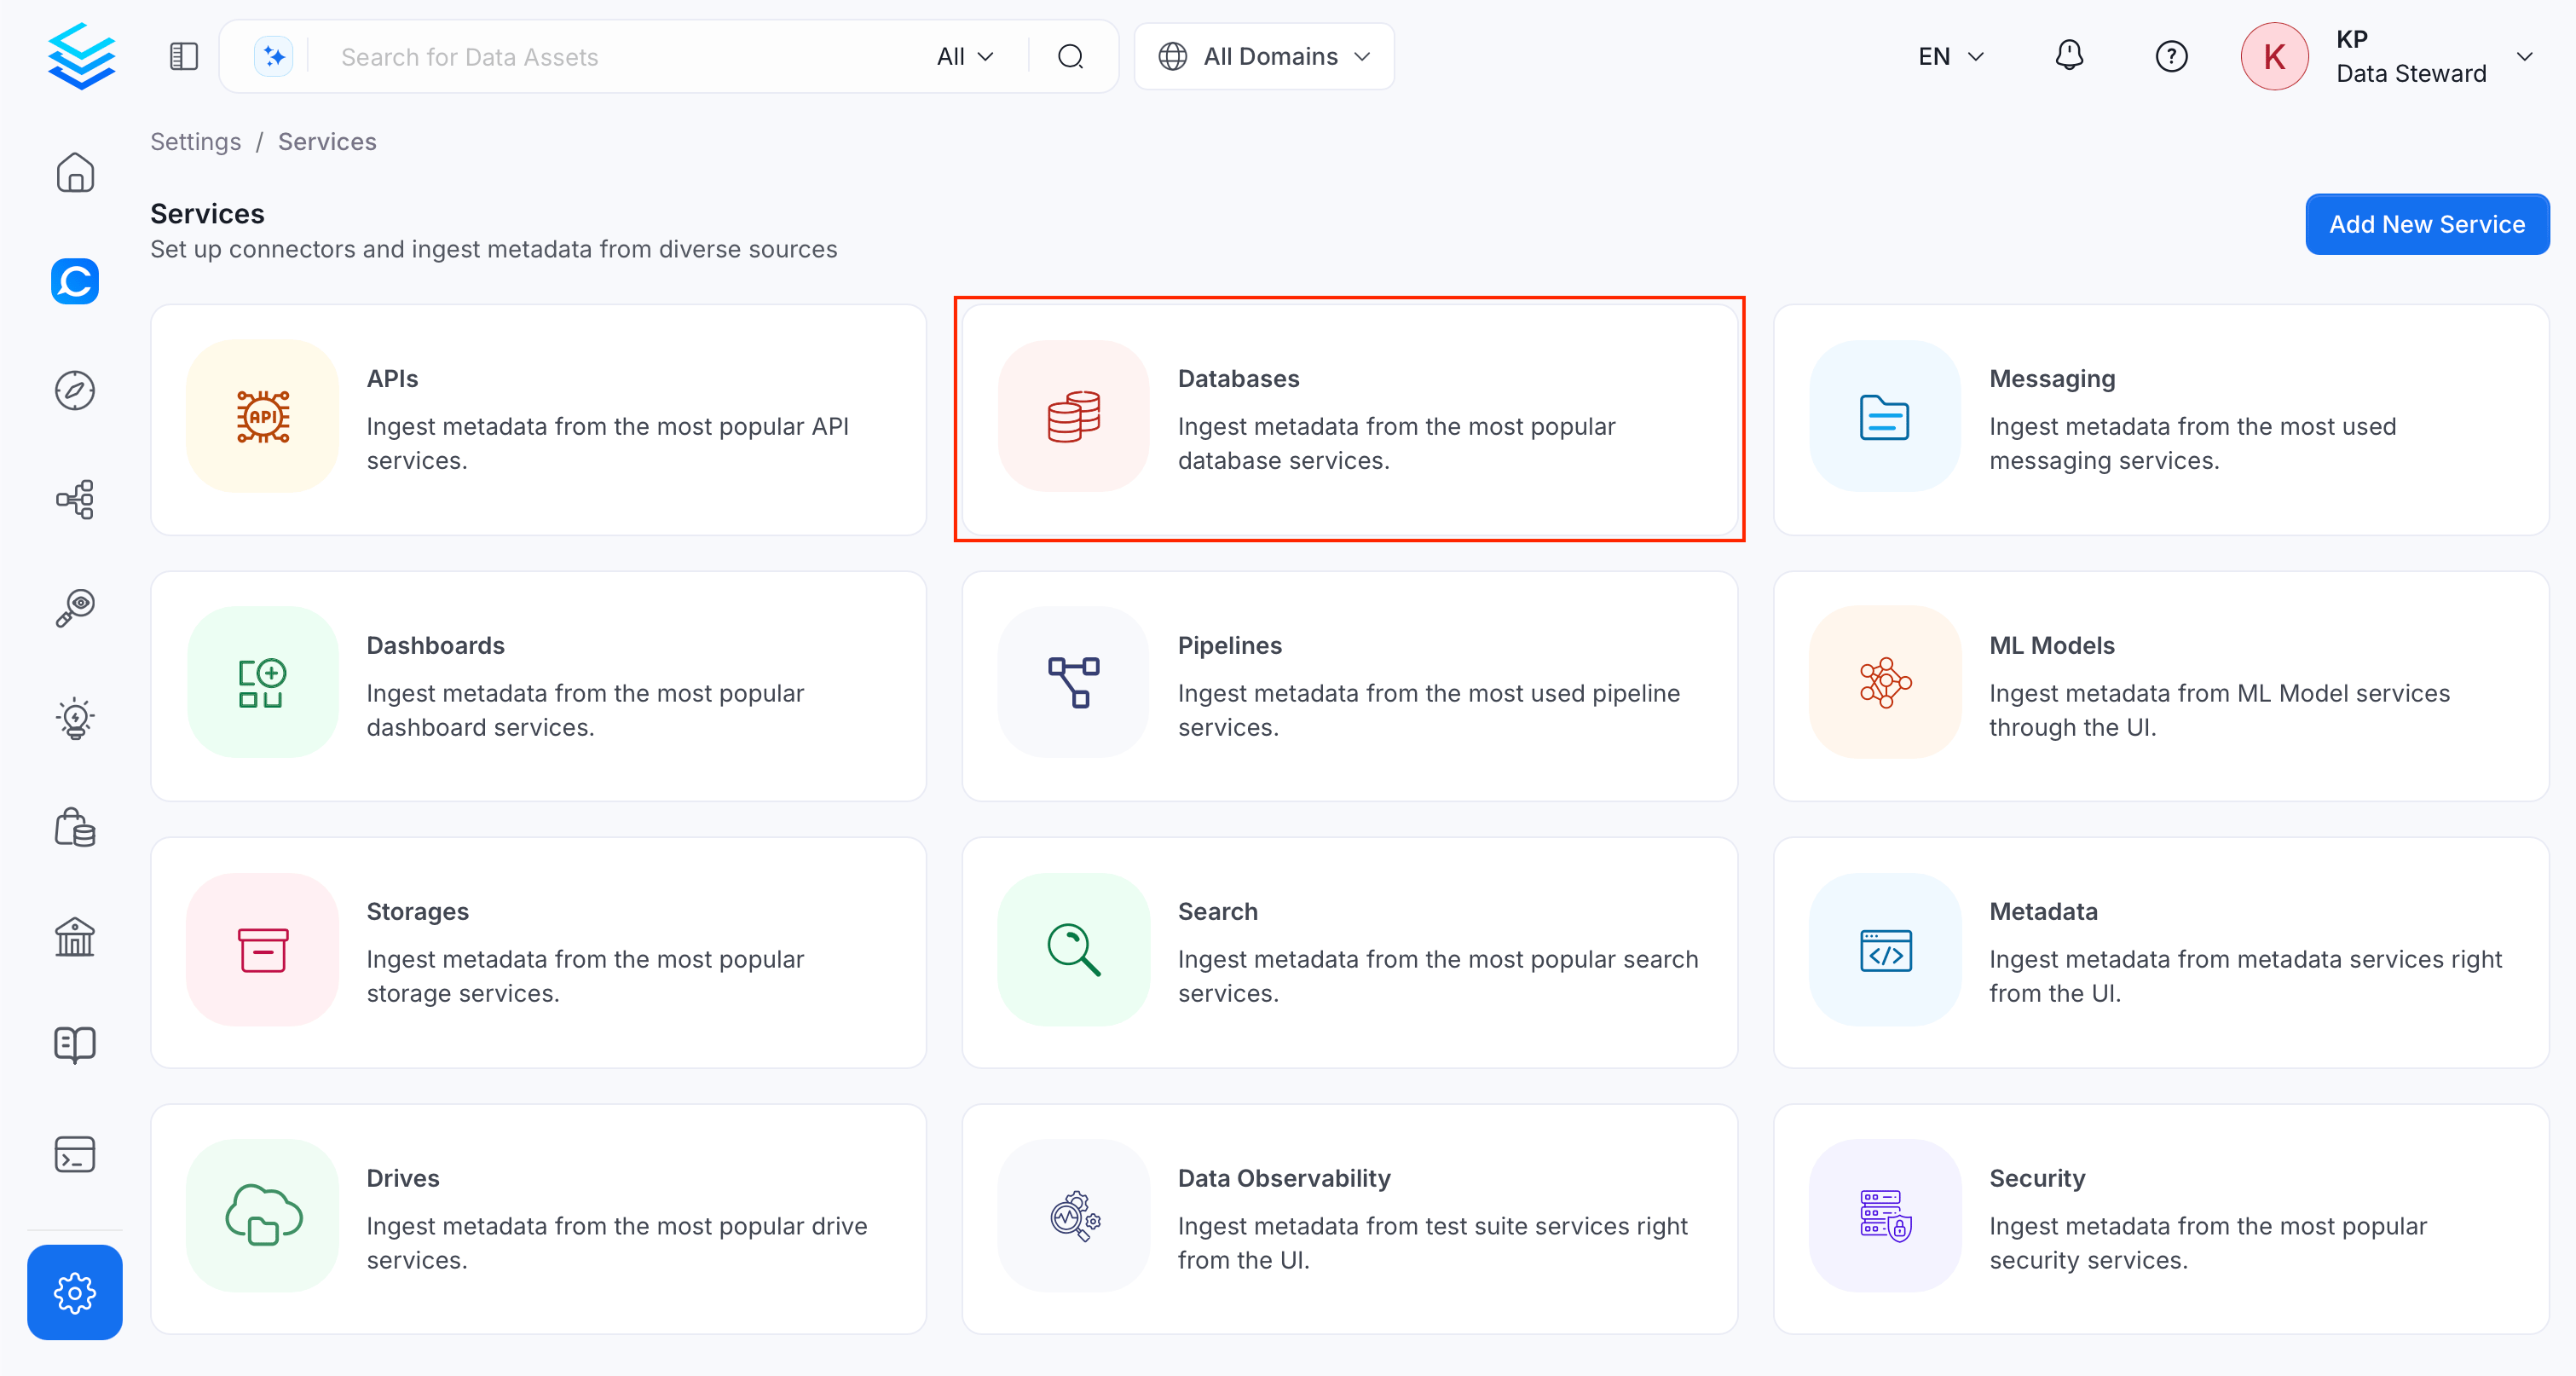
-
Click Add New Service.
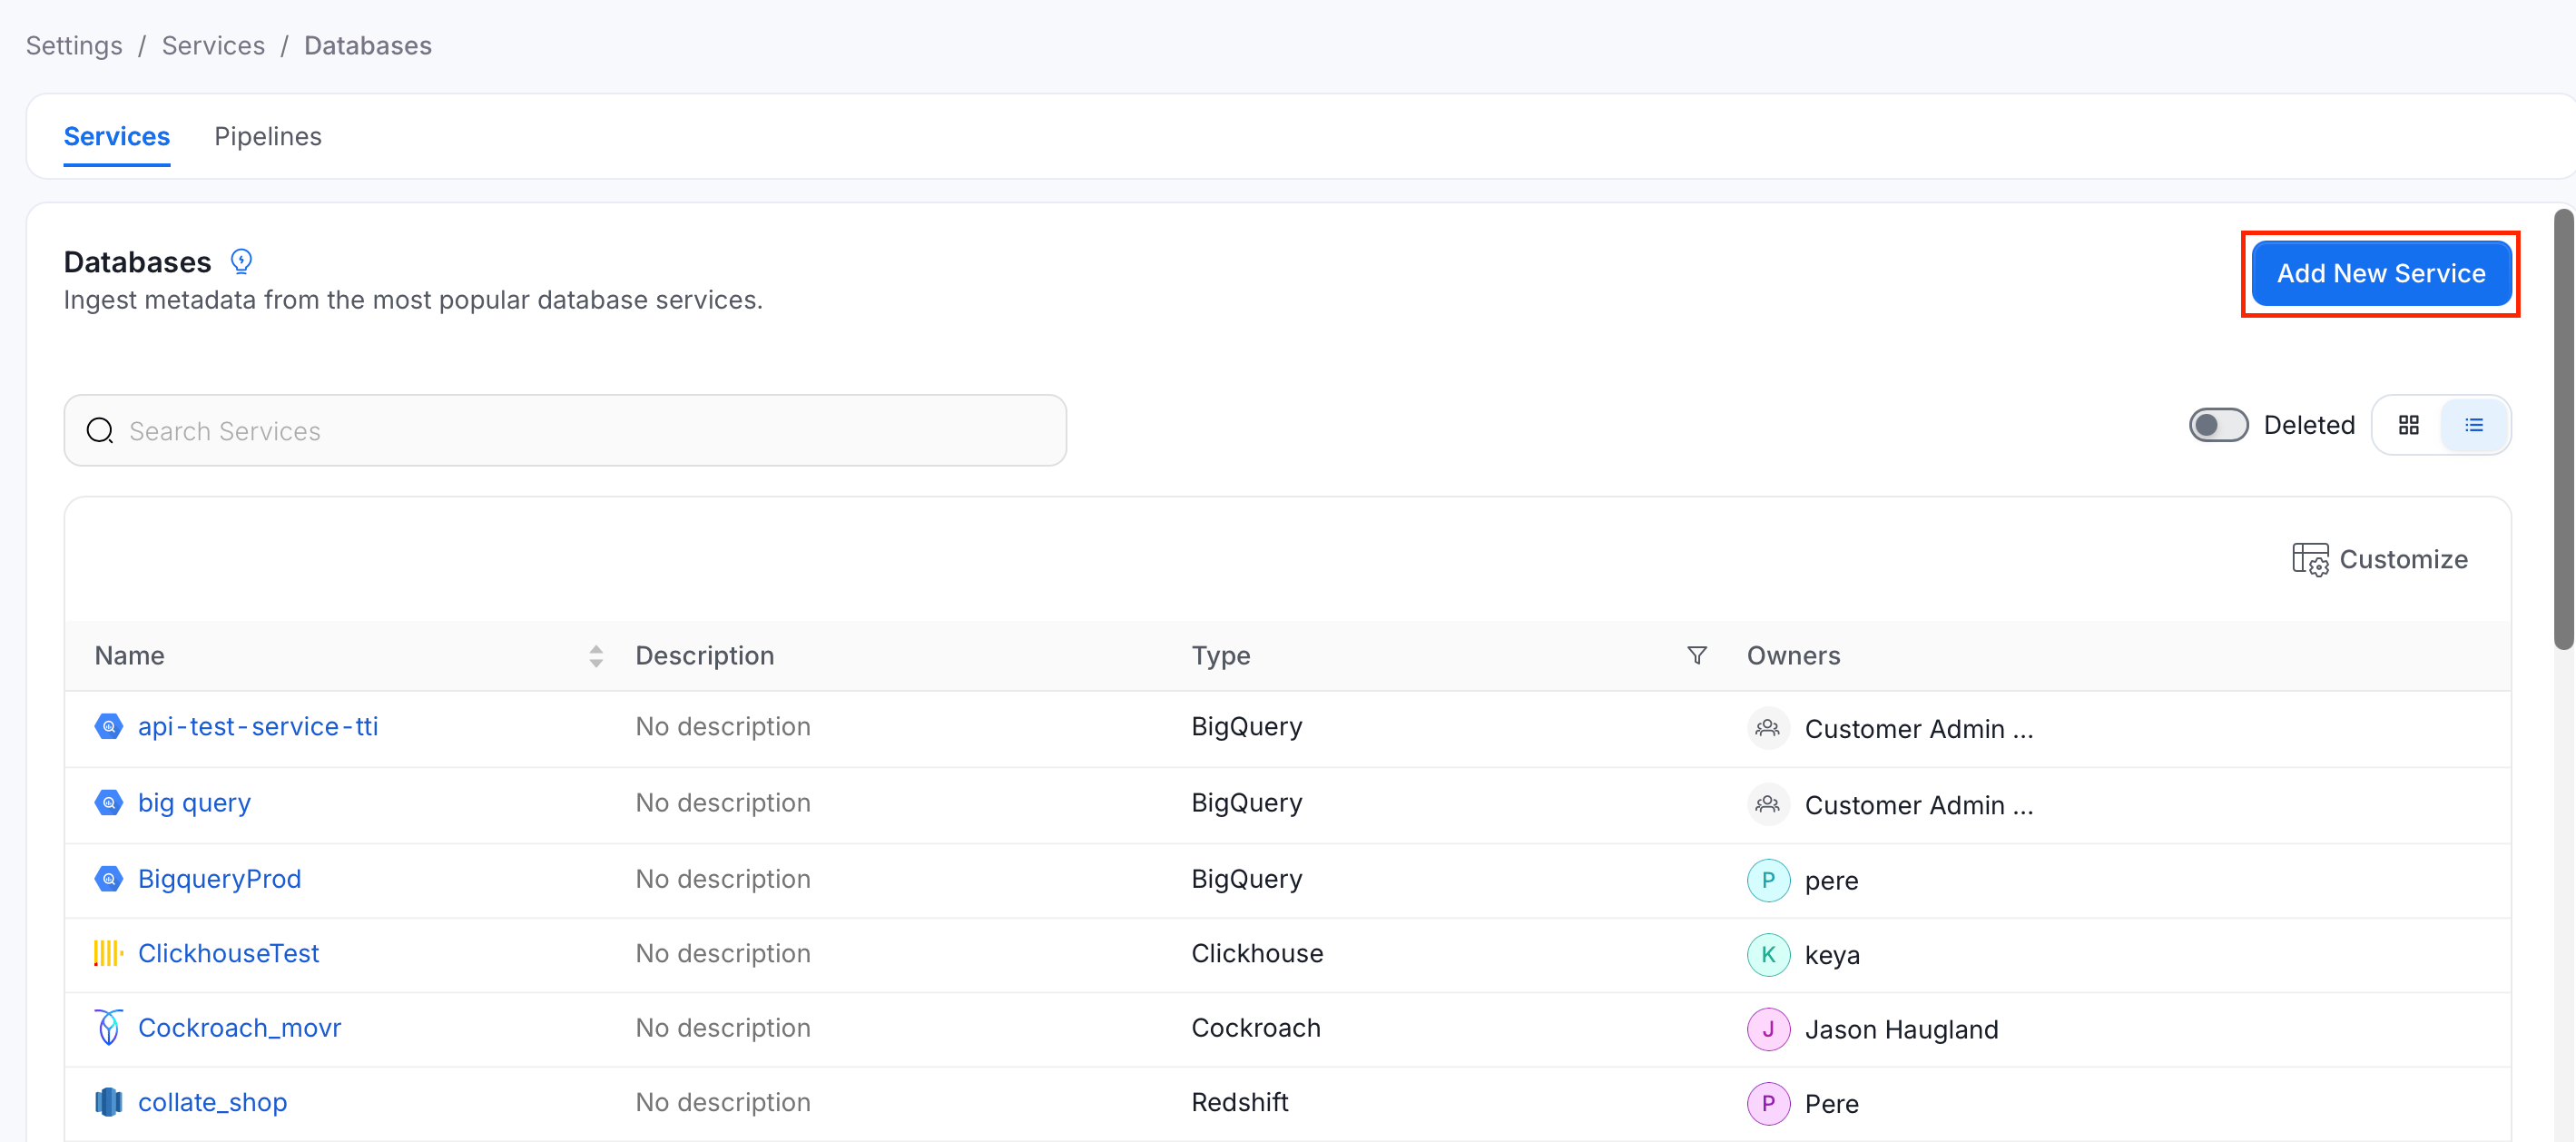
Step 2: Select a Service and Connector
From the service type dropdown, select Database Services, then click the Redshift connector tile.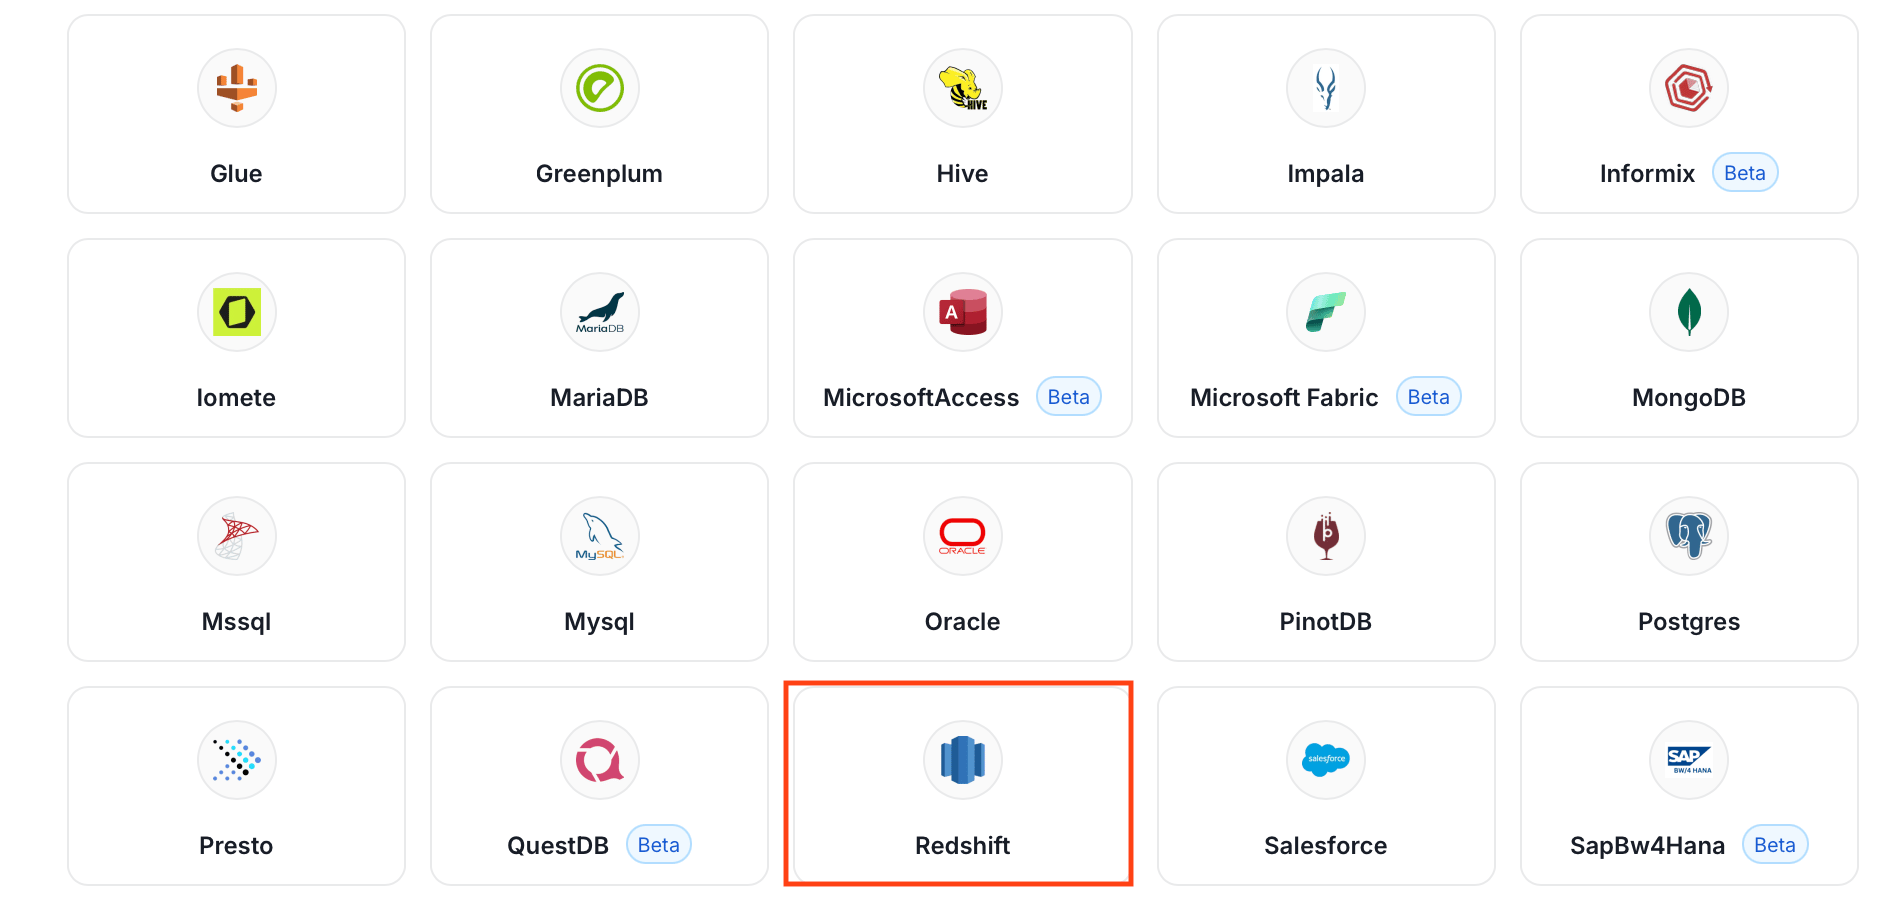
Step 3: Add Service Name and Description
- Enter a unique, descriptive Service Name. Collate identifies services by their service name. Enter a name that distinguishes this deployment from other Redshift services you are ingesting metadata from.
- Optional: Enter a Description for the service.

Note: The service name can’t be changed after you set it.
Step 4: Configure Connection Options
Specify where ingestion runs, provide your source credentials, and verify the connection.Select Ingestion Runner
Select an Ingestion Runner: the runner where the ingestion pipeline will execute.
Enter Connection Details
Enter the connection details for Redshift. The right-hand panel in the UI displays inline help for each field.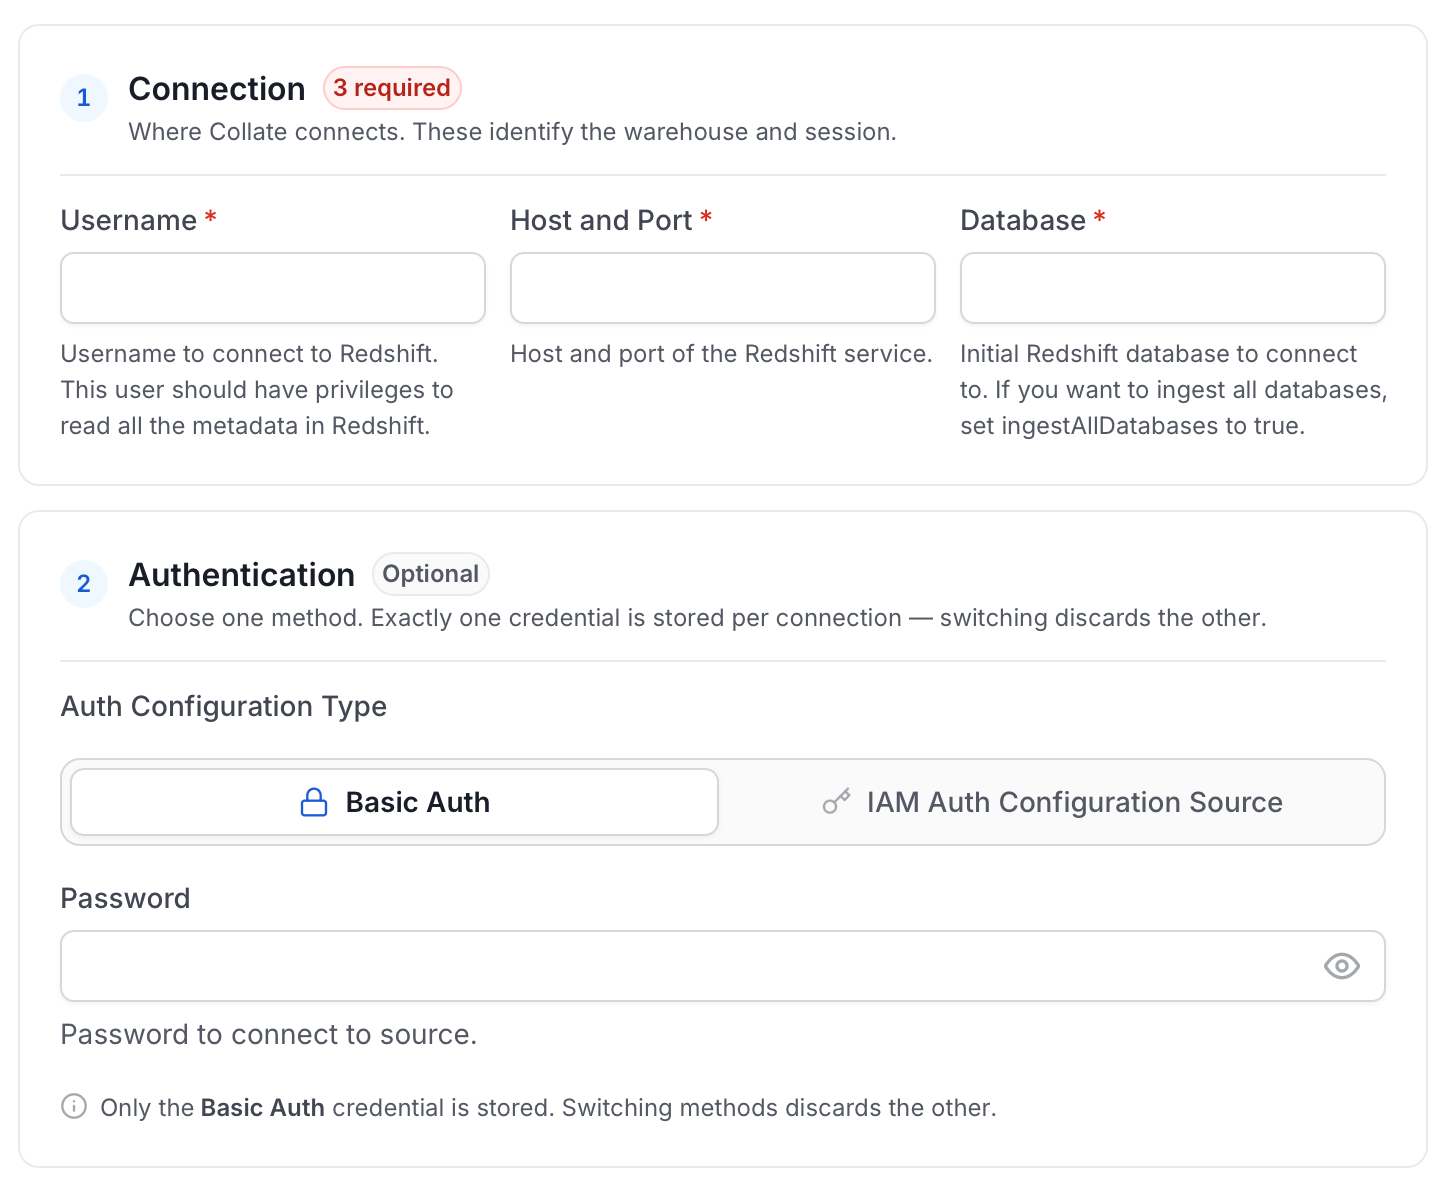
- Username: Specify the user to connect to Redshift. It should have enough privileges to read all the metadata.
- Password: Password to connect to Redshift.
- Database: The database of the data source is an optional parameter, if you would like to restrict the metadata reading to a single database. If left blank, Collate ingestion attempts to scan all the databases.
SSL Configuration
To integrate SSL in the Metadata Ingestion Config, the user will have to add the SSL config under connectionArguments which is placed in the source.SSL Modes
There are a couple of types of SSL modes that Redshift supports which can be added to ConnectionArguments, they are as follows:- disable: SSL is disabled and the connection is not encrypted.
- allow: SSL is used if the server requires it.
- prefer: SSL is used if the server supports it. Amazon Redshift supports SSL, so SSL is used when you set sslmode to prefer.
- require: SSL is required.
- verify-ca: SSL must be used and the server certificate must be verified.
- verify-full: SSL must be used. The server certificate must be verified and the server hostname must match the hostname attribute on the certificate. For more information, you can visit Redshift SSL documentation
Advanced Configuration
Database Services include an Advanced Configuration section for passing extra arguments to the connector and, if needed, changing the connection scheme. You need this only for advanced connectivity scenarios or customizations.- Connection Options (Optional): Enter the details for any additional connection options that can be sent to the database during the connection. These details must be added as key-value pairs.
- Connection Arguments (Optional): Enter the details for any additional connection arguments such as security or protocol configs that can be sent during the connection. These details must be added as key-value pairs.
Test Connection
- Click Test Connection to verify the credentials.
- After the test succeeds, click Save.
Step 5: Configure Ingestion Options
In the What to Ingest step, use filter patterns to control which assets Collate ingests from your database service. Filter rules match asset names using the following match types.How Filter Patterns Work
- Include: Add one or more comma-separated values. Each value uses one of the following match types. Collate ingests only assets whose names match at least one rule. Leave blank to include all assets.
- Exclude: Add one or more comma-separated values. Each value uses one of the following match types. Collate skips any asset whose name matches a rule. Leave blank to exclude nothing.
- contains: matches any name containing the value. For example,
salesmatchesmy_sales_dataandsales_2024. - starts with: matches names beginning with the value. For example,
prod_matchesprod_dbandprod_schema. - ends with: matches names ending with the value. For example,
_rawmatchesevents_rawandlogs_raw. - is exactly: matches the exact name only. For example,
analyticsmatches onlyanalytics. - matches regex: matches names using a regular expression. For example,
^prod_.*_v\d+$matchesprod_events_v1.
Filter Options
The Database, Schema, Table, and Stored Procedure sections each include the following filter options:- Database: Controls which databases Collate ingests from the source.
- Schema: Controls which schemas within the ingested databases are included.
- Table: Controls which tables and views within the ingested schemas are included.
- Stored Procedure: Controls which stored procedures are included in metadata ingestion.
- Scan Mode: Choose between the following scan modes:
- Scan all: Ingests every asset of that type the connector can access. This is the default.
- Only specific: Enables include rules so only assets matching at least one rule are ingested.
- Exclude system toggle: Use this toggle to filter out system-reserved names defined by the connector for that asset type.
- Always exclude: Add permanent exclusion rules (shown in red). Assets matching these rules are never ingested, regardless of include rules.
- Preview: Shows a real-time summary of what will be in scope based on your current rules.
- Include rules: In Only specific mode, click + Add to define a rule. Added rules appear as chips. An asset is included if it matches any rule.
Step 6: Create & Deploy
Click Create & Deploy to deploy the agent and start the first metadata ingestion run. Collate saves the service configuration and immediately begins pulling metadata from the source. To monitor ingestion progress or view the service you just added, go to Settings > Services and select your service.Configure Metadata Agent and Schedule Ingestion
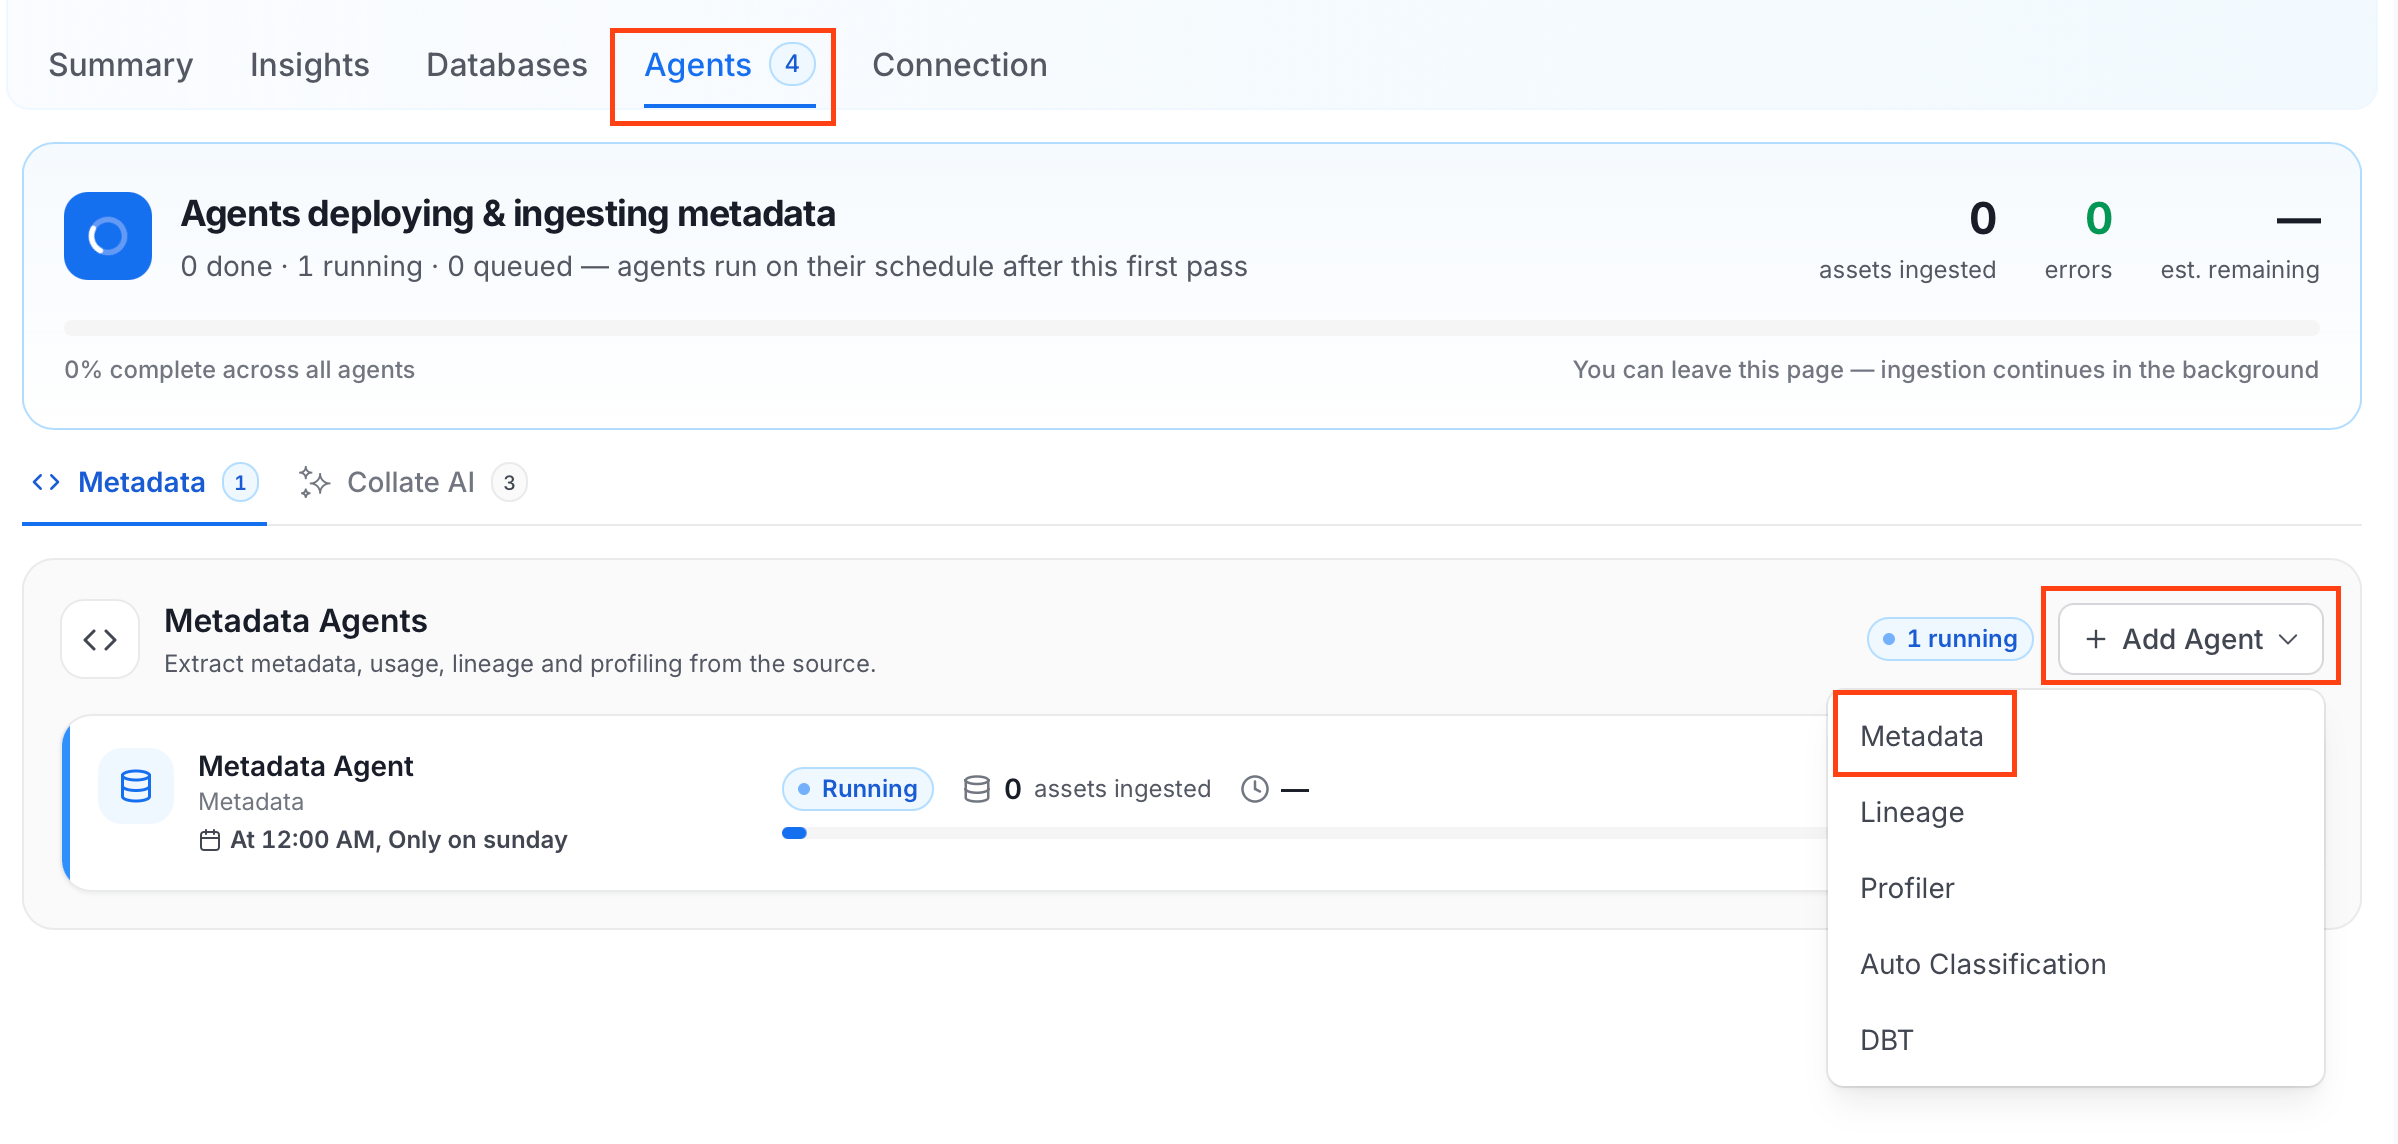
The Metadata Agent extracts schemas, tables, columns, and other structural metadata from your source and keeps your Collate catalog in sync. It powers discovery, lineage, and governance across your data assets. When you click Create & Deploy, Collate automatically deploys a Metadata Agent for this service and triggers the first ingestion run. View its status and run history from the Agents tab on the service detail page. To configure the additional Metadata Agent and schedule ingestion, follow these steps:- Navigate to Settings > Services and select the Databases service.
- Select your service and click the Agents tab.
-
Click Add Agent and select Metadata from the dropdown.
-
On the Configure Ingestion page, do the following and click Next.
-
Name this Ingestion: Enter a unique, recognizable name for this ingestion pipeline.

-
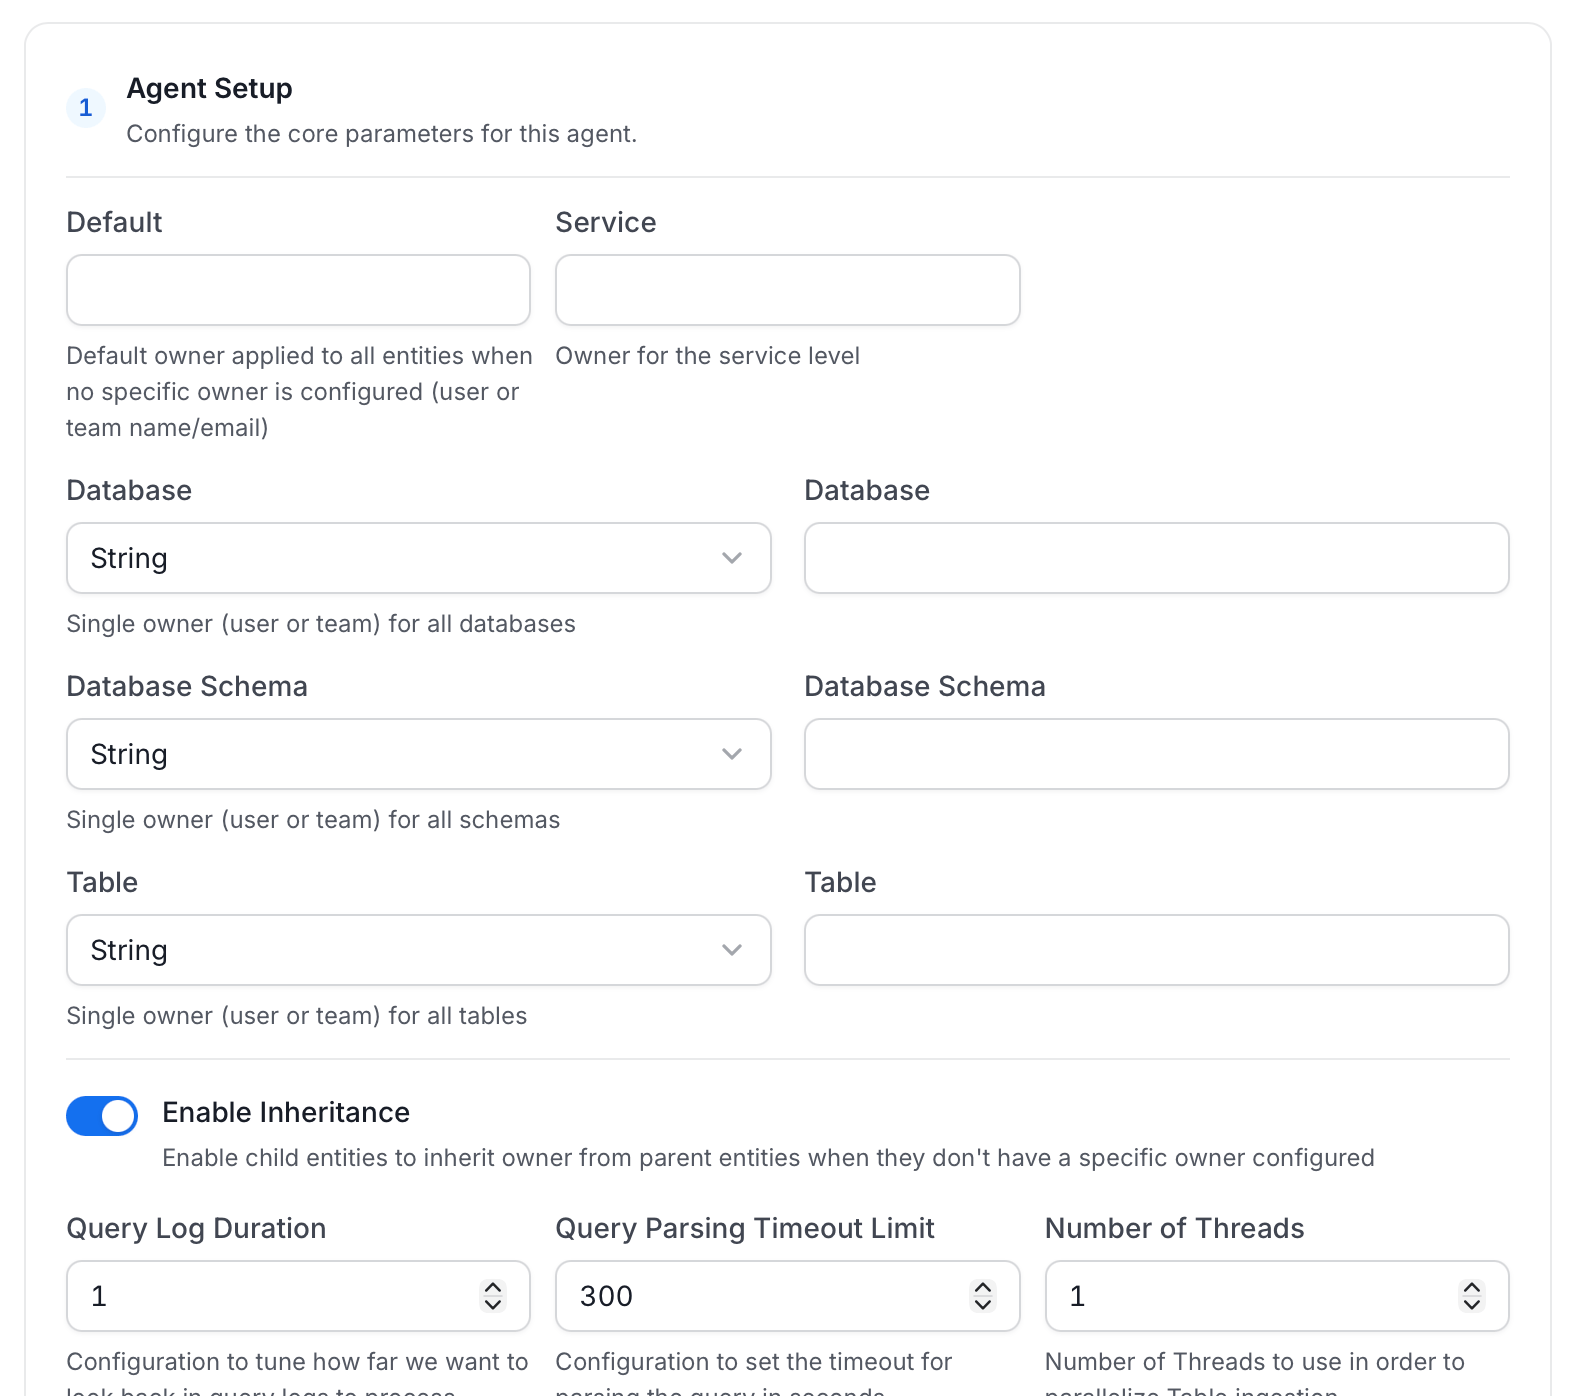
Agent Setup: Configure core parameters for metadata extraction. The following fields are available:
For more information, see Hierarchical Owner Configuration.
-
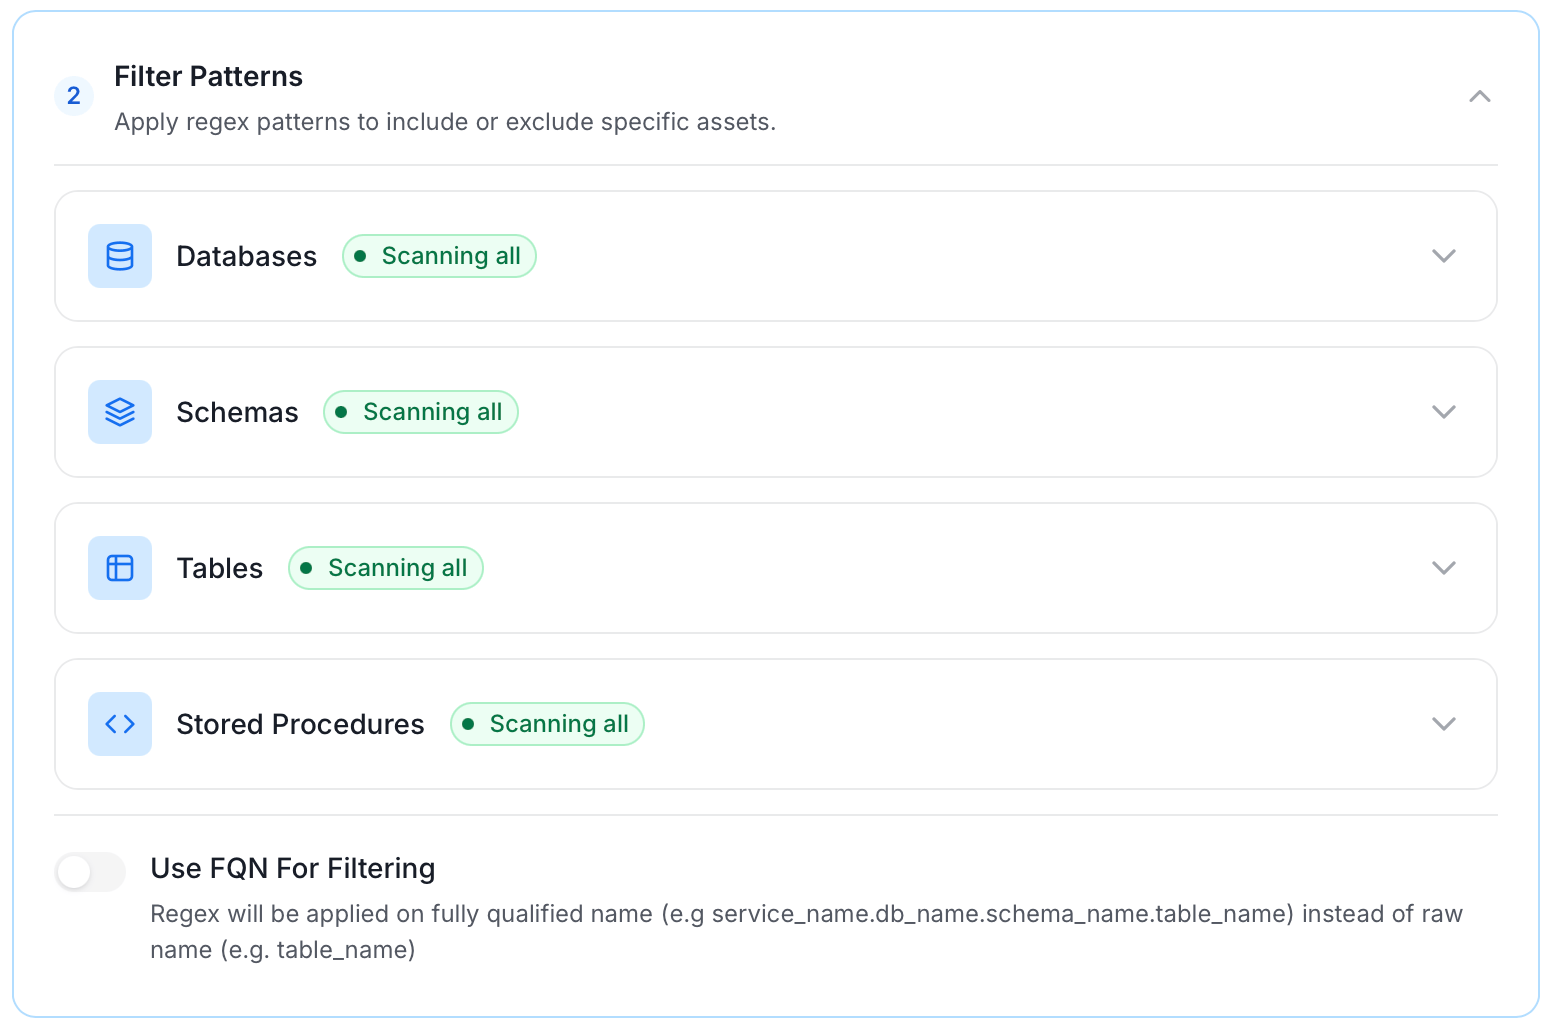
Filter Patterns: Apply include or exclude rules to scope which databases, schemas, tables, and stored procedures this agent ingests. These follow the same filter options described in Step 5.
-
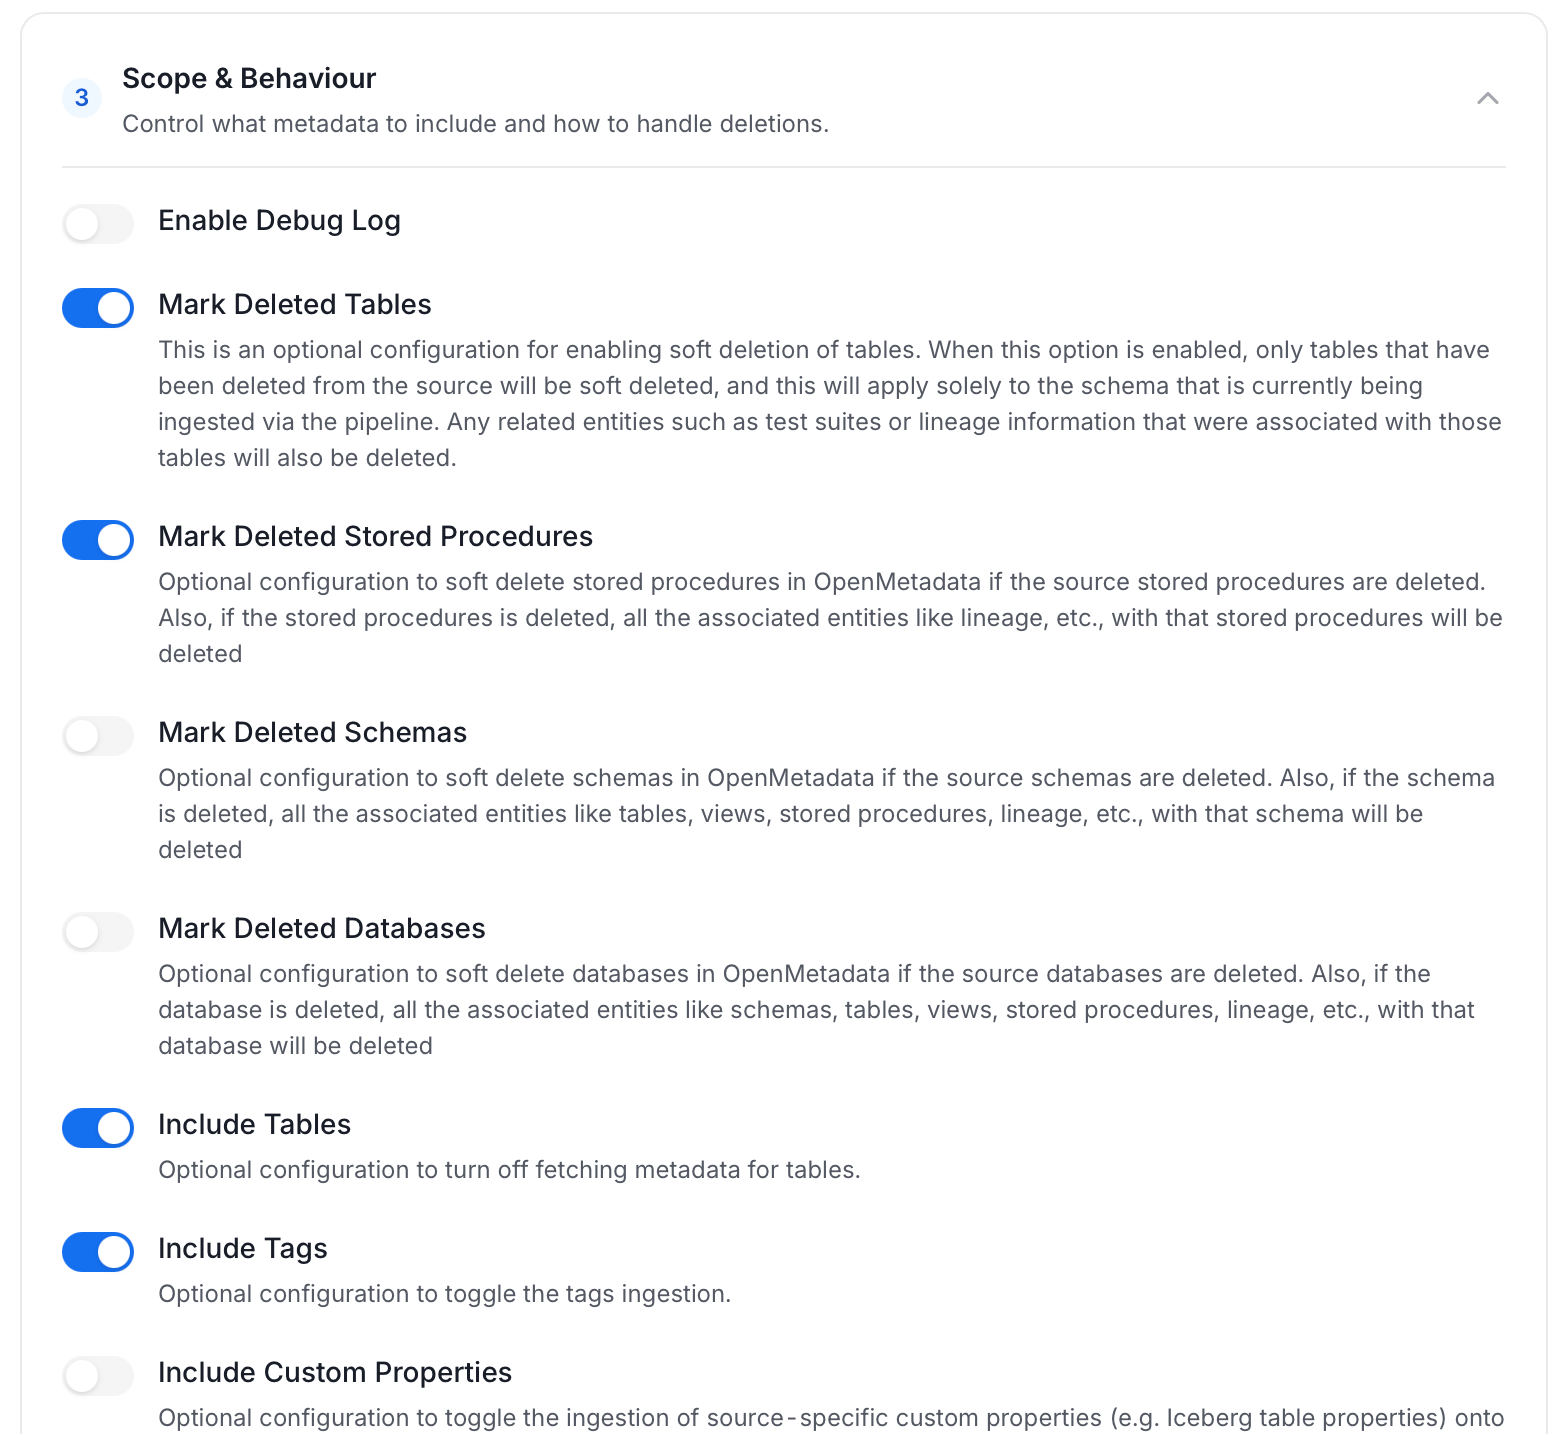
Scope & Behaviour: Control how the agent handles metadata during ingestion. Toggle each option on or off based on your needs:
Note: Available toggles vary by connector. Stored procedure options only appear for connectors that support stored procedures.
-
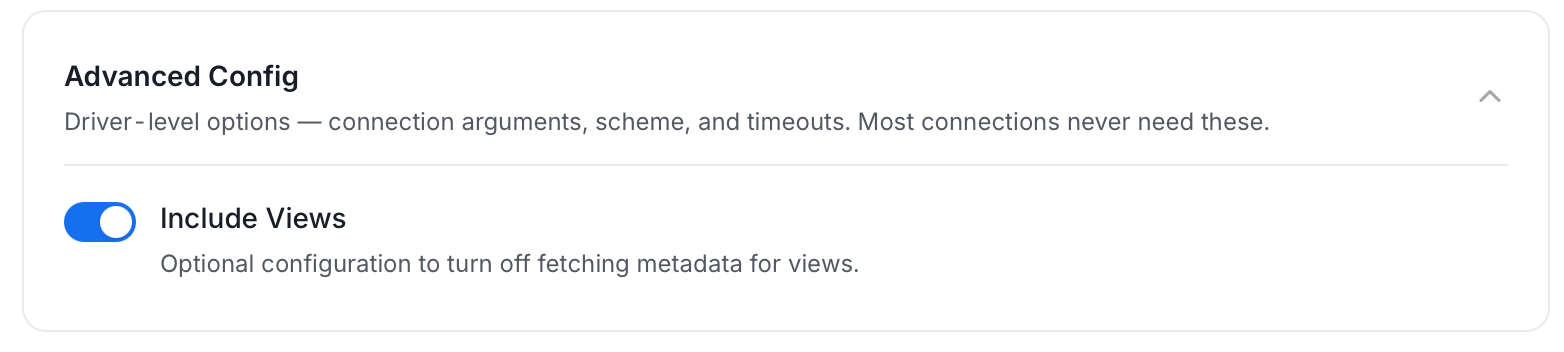
Advanced Config: Driver-level options (connection arguments, scheme, and timeouts). Most connections never need these, and they vary by connector. This section also has one ingestion-scope toggle:
-
Name this Ingestion: Enter a unique, recognizable name for this ingestion pipeline.
-
On the Schedule Interval page, set when the agent runs:
- Schedule: Choose a preset interval (Hourly, Daily, Weekly, Monthly) or enter a custom cron expression.
- On-Demand: No automatic schedule. Trigger the agent manually when needed.
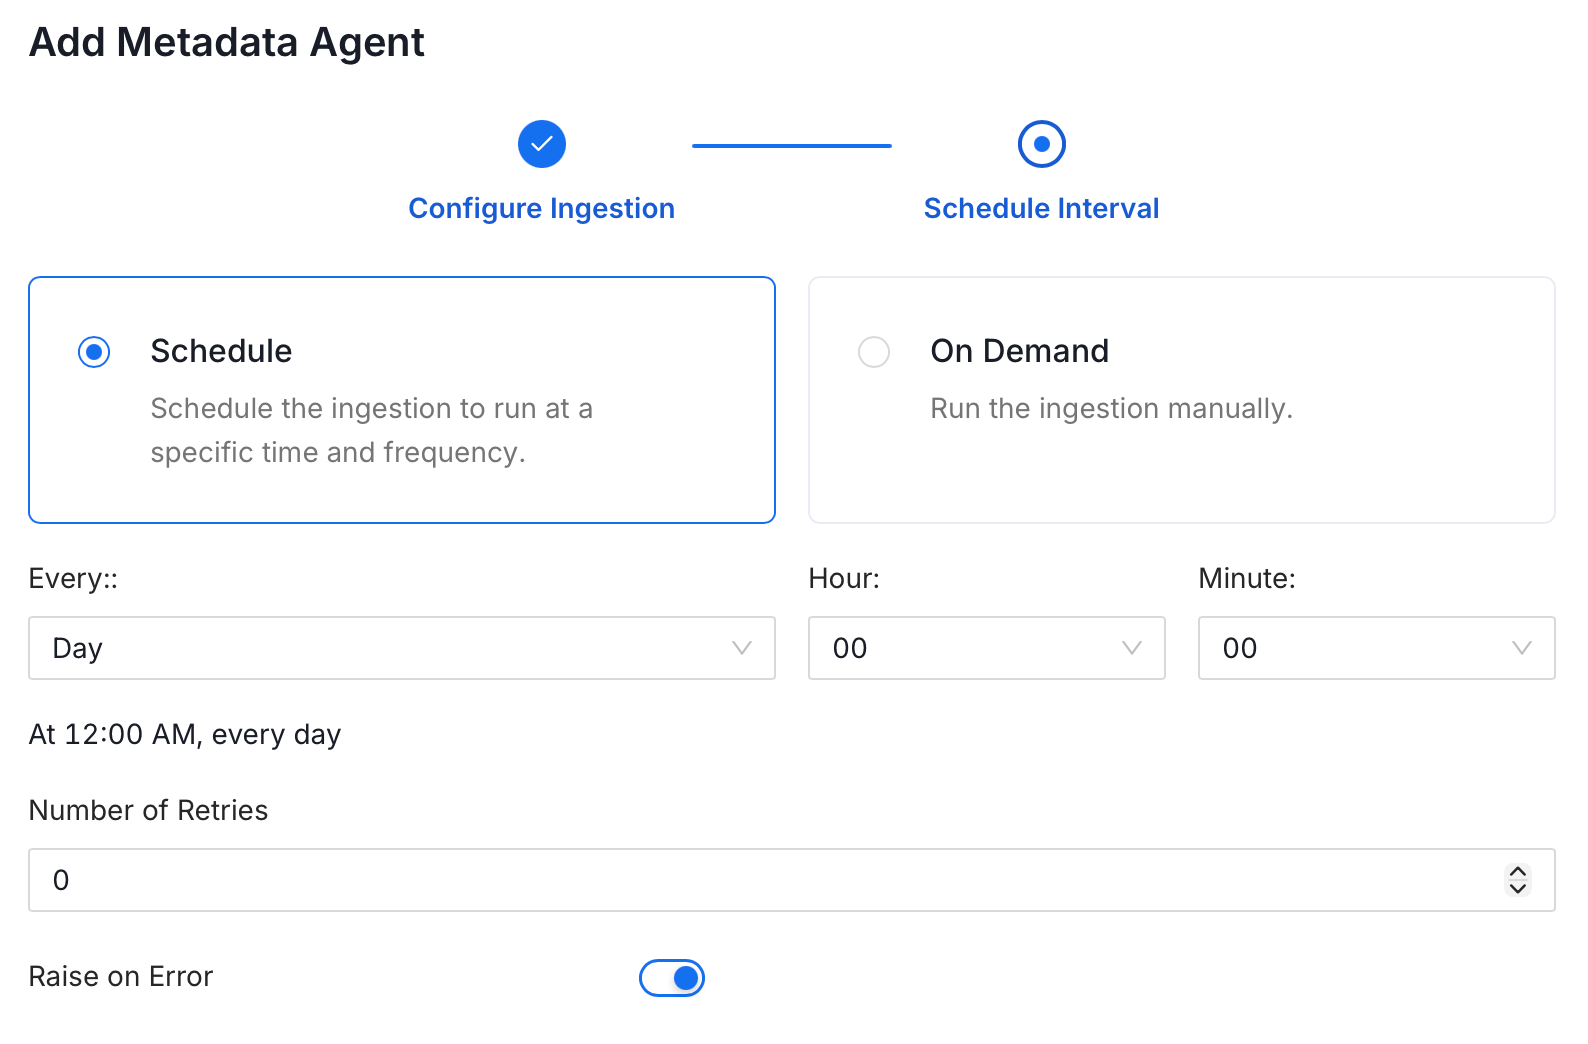
- Click Add to deploy the agent.
Securing Redshift Connection with SSL in Collate
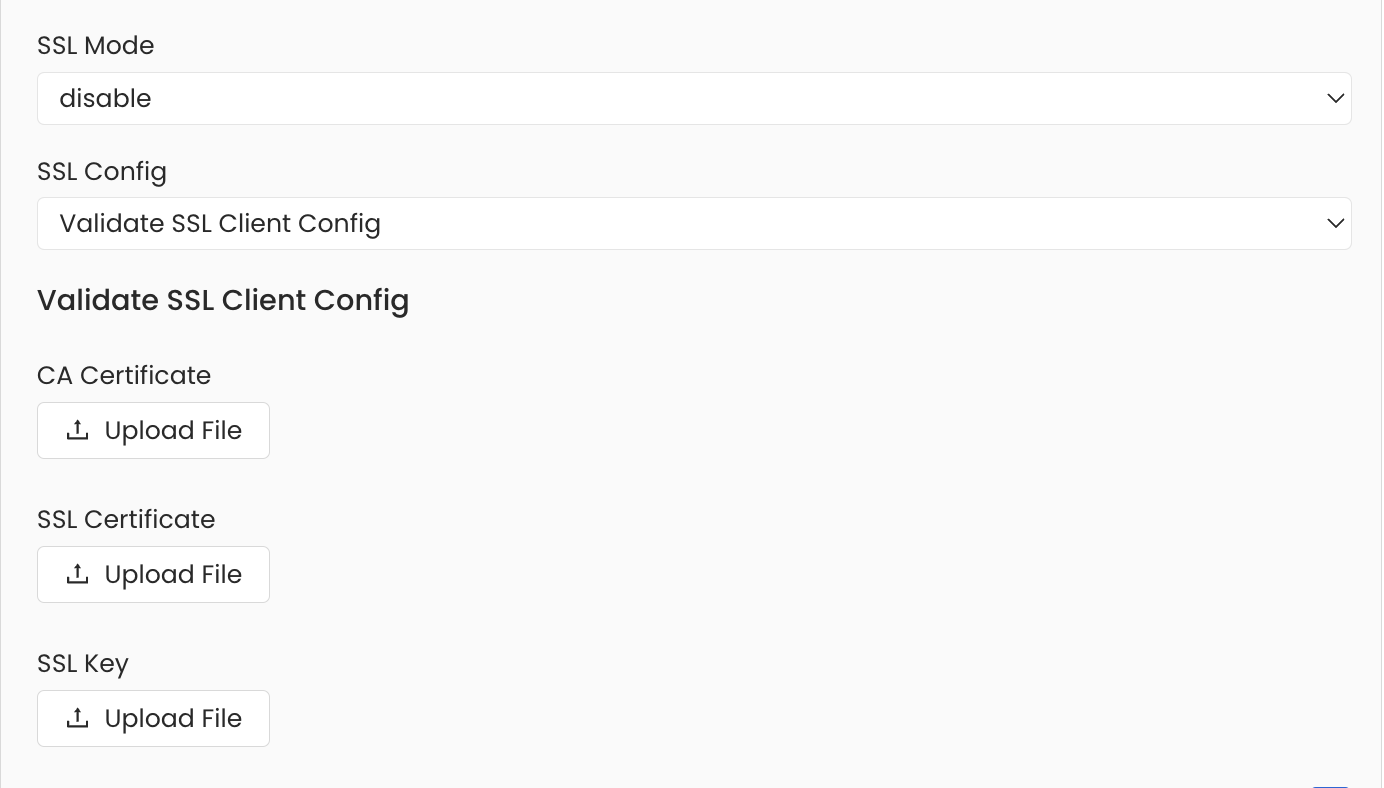
To establish secure connections between Collate and a Redshift database, you can configure SSL using different SSL modes provided by Redshift, each offering varying levels of security. UnderAdvanced Config, specify the SSL mode appropriate for your connection, such as prefer, verify-ca, allow, and others. After selecting the SSL mode, provide the CA certificate used for SSL validation (caCertificate). Note that Redshift requires only the CA certificate for SSL validation.
Reverse Metadata
1
Reverse Metadata
Description Management
Redshift supports description updates at all levels:- Database level
- Schema level
- Table level
- Column level
Owner Management
Redshift supports owner management at the following levels:- Database level
- Schema level
- Table level
Tag Management
❌ Tag management is not supported for Redshift.Custom SQL Template
Redshift supports custom SQL templates for metadata changes. The template is interpreted using python f-strings.Here are examples of custom SQL queries for metadata changes:Requirements for Reverse Metadata
In addition to the basic ingestion requirements, for reverse metadata ingestion the user needs:SUPERUSERprivilege to the user
Troubleshooting
Redshift Troubleshooting
Learn more about how to troubleshoot common Redshift connector issues and resolve configuration or ingestion errors.