
Explore the Lineage View
Collate displays end-to-end lineage for the table and column levels, for Database, Dashboard, and Pipeline assets. Search for a data asset and expand the graph to see its lineage:- Each node expands to show its upstream and downstream edges.
- Each edge carries details such as the SQL query, pipeline information, and column-level lineage.
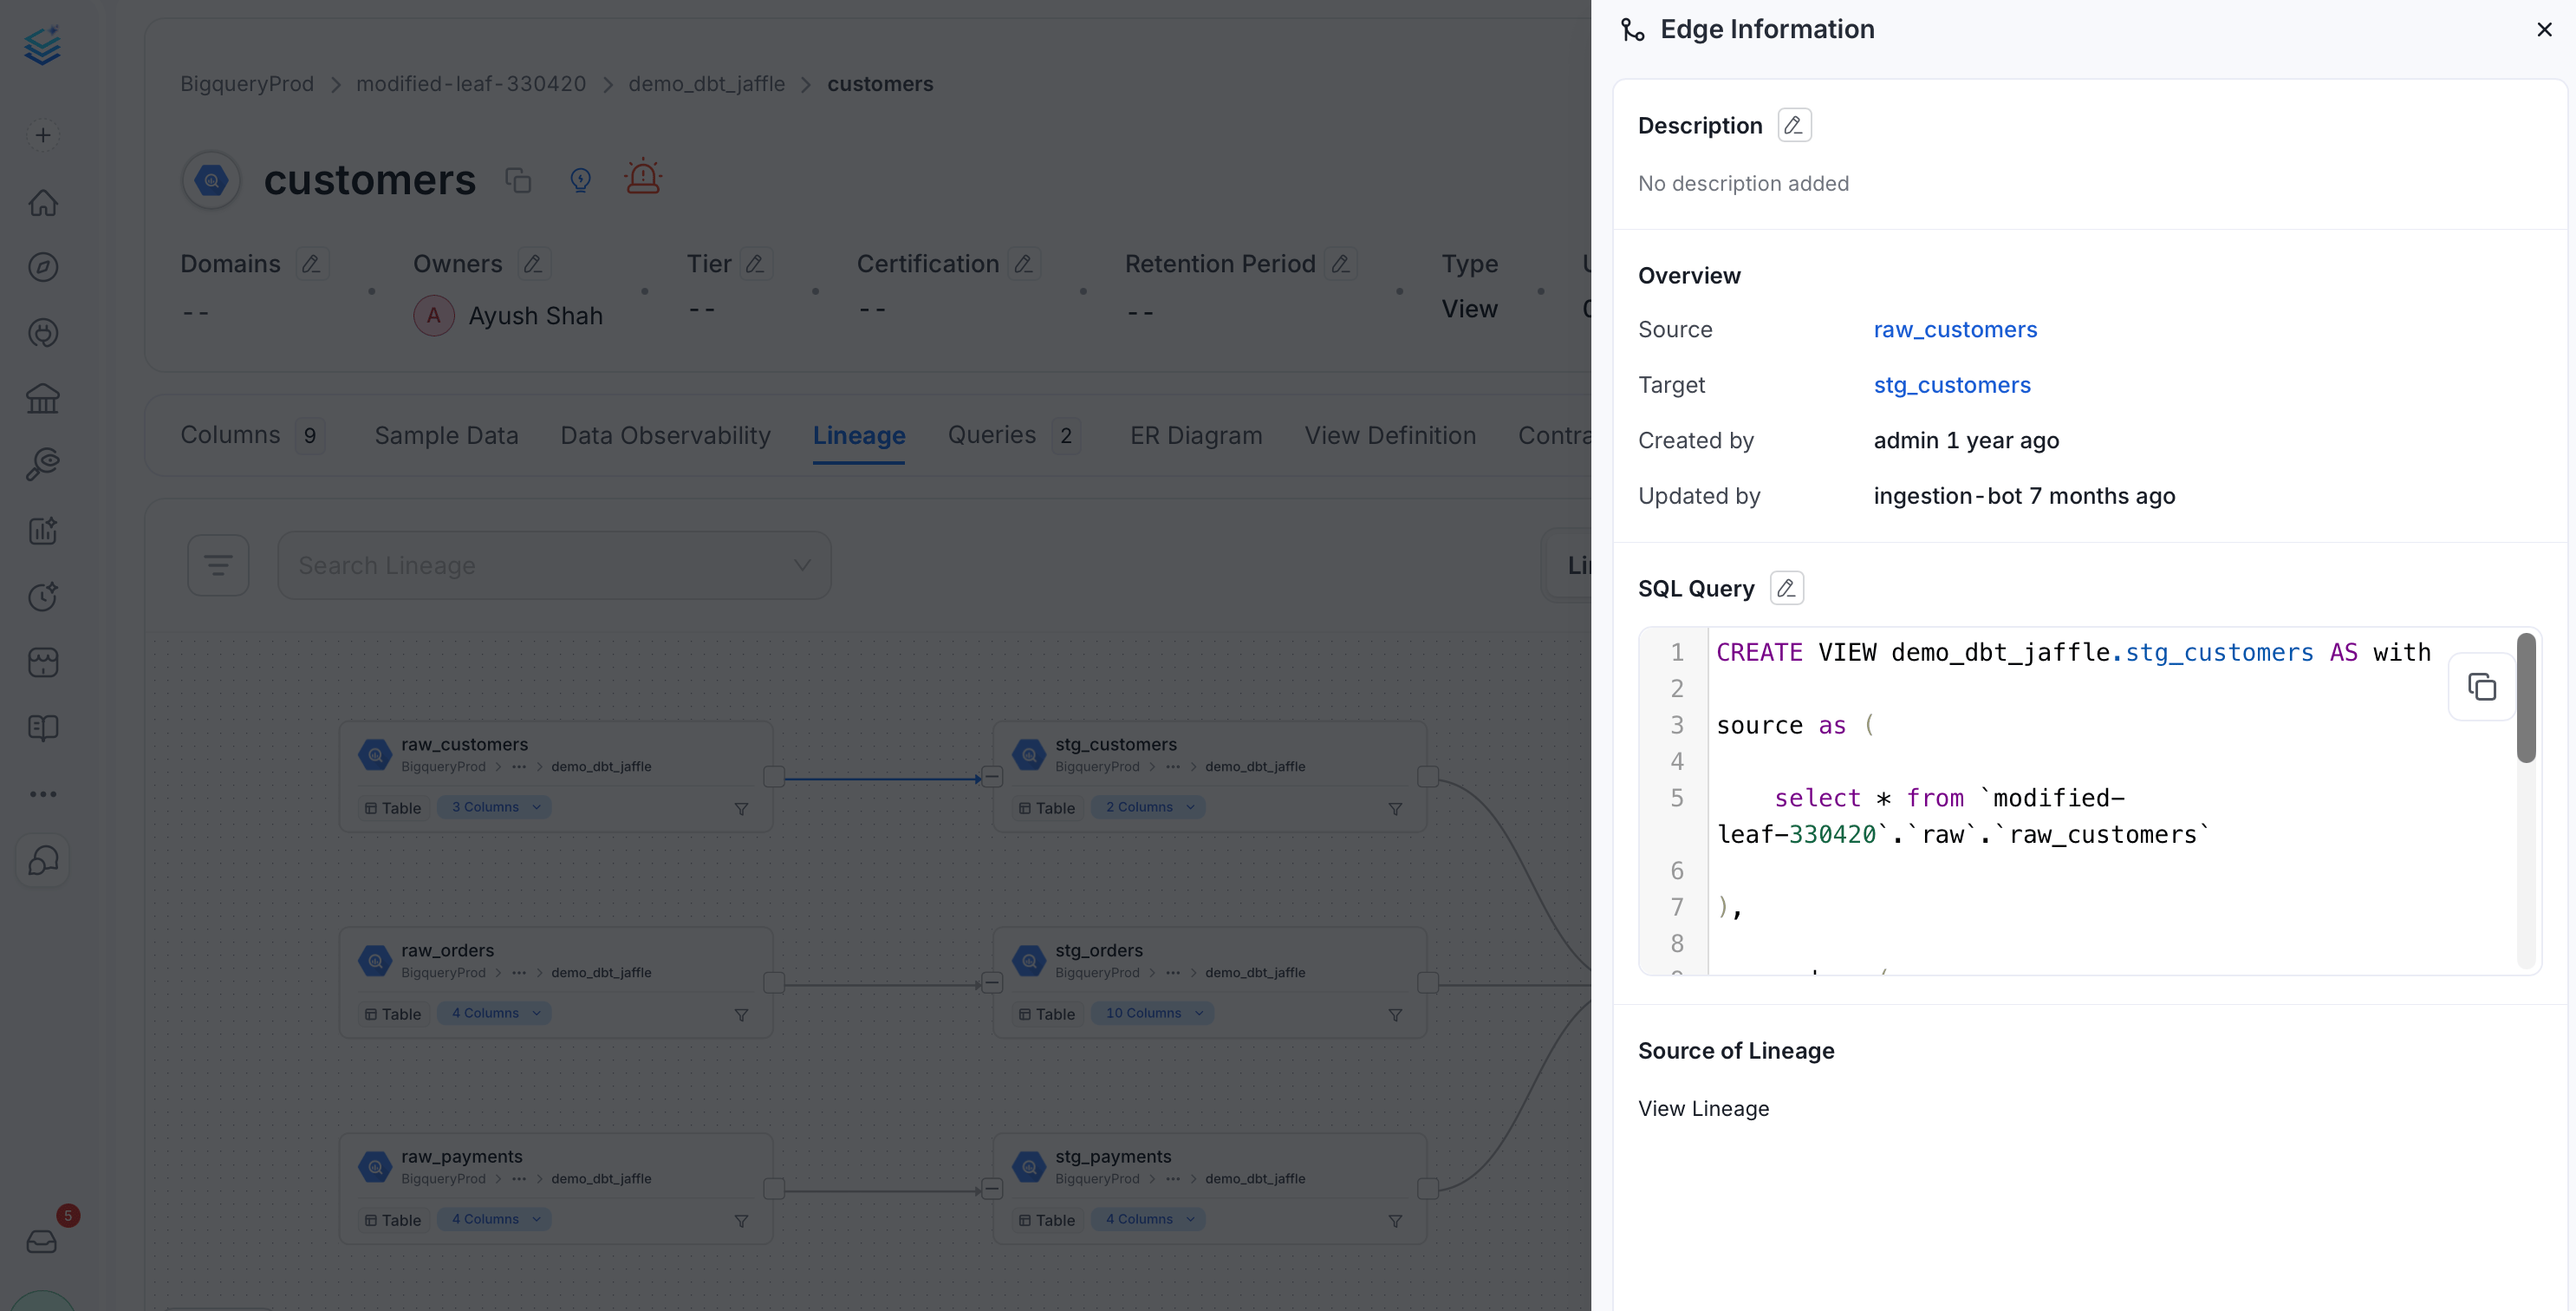
Source, Target, and Edges
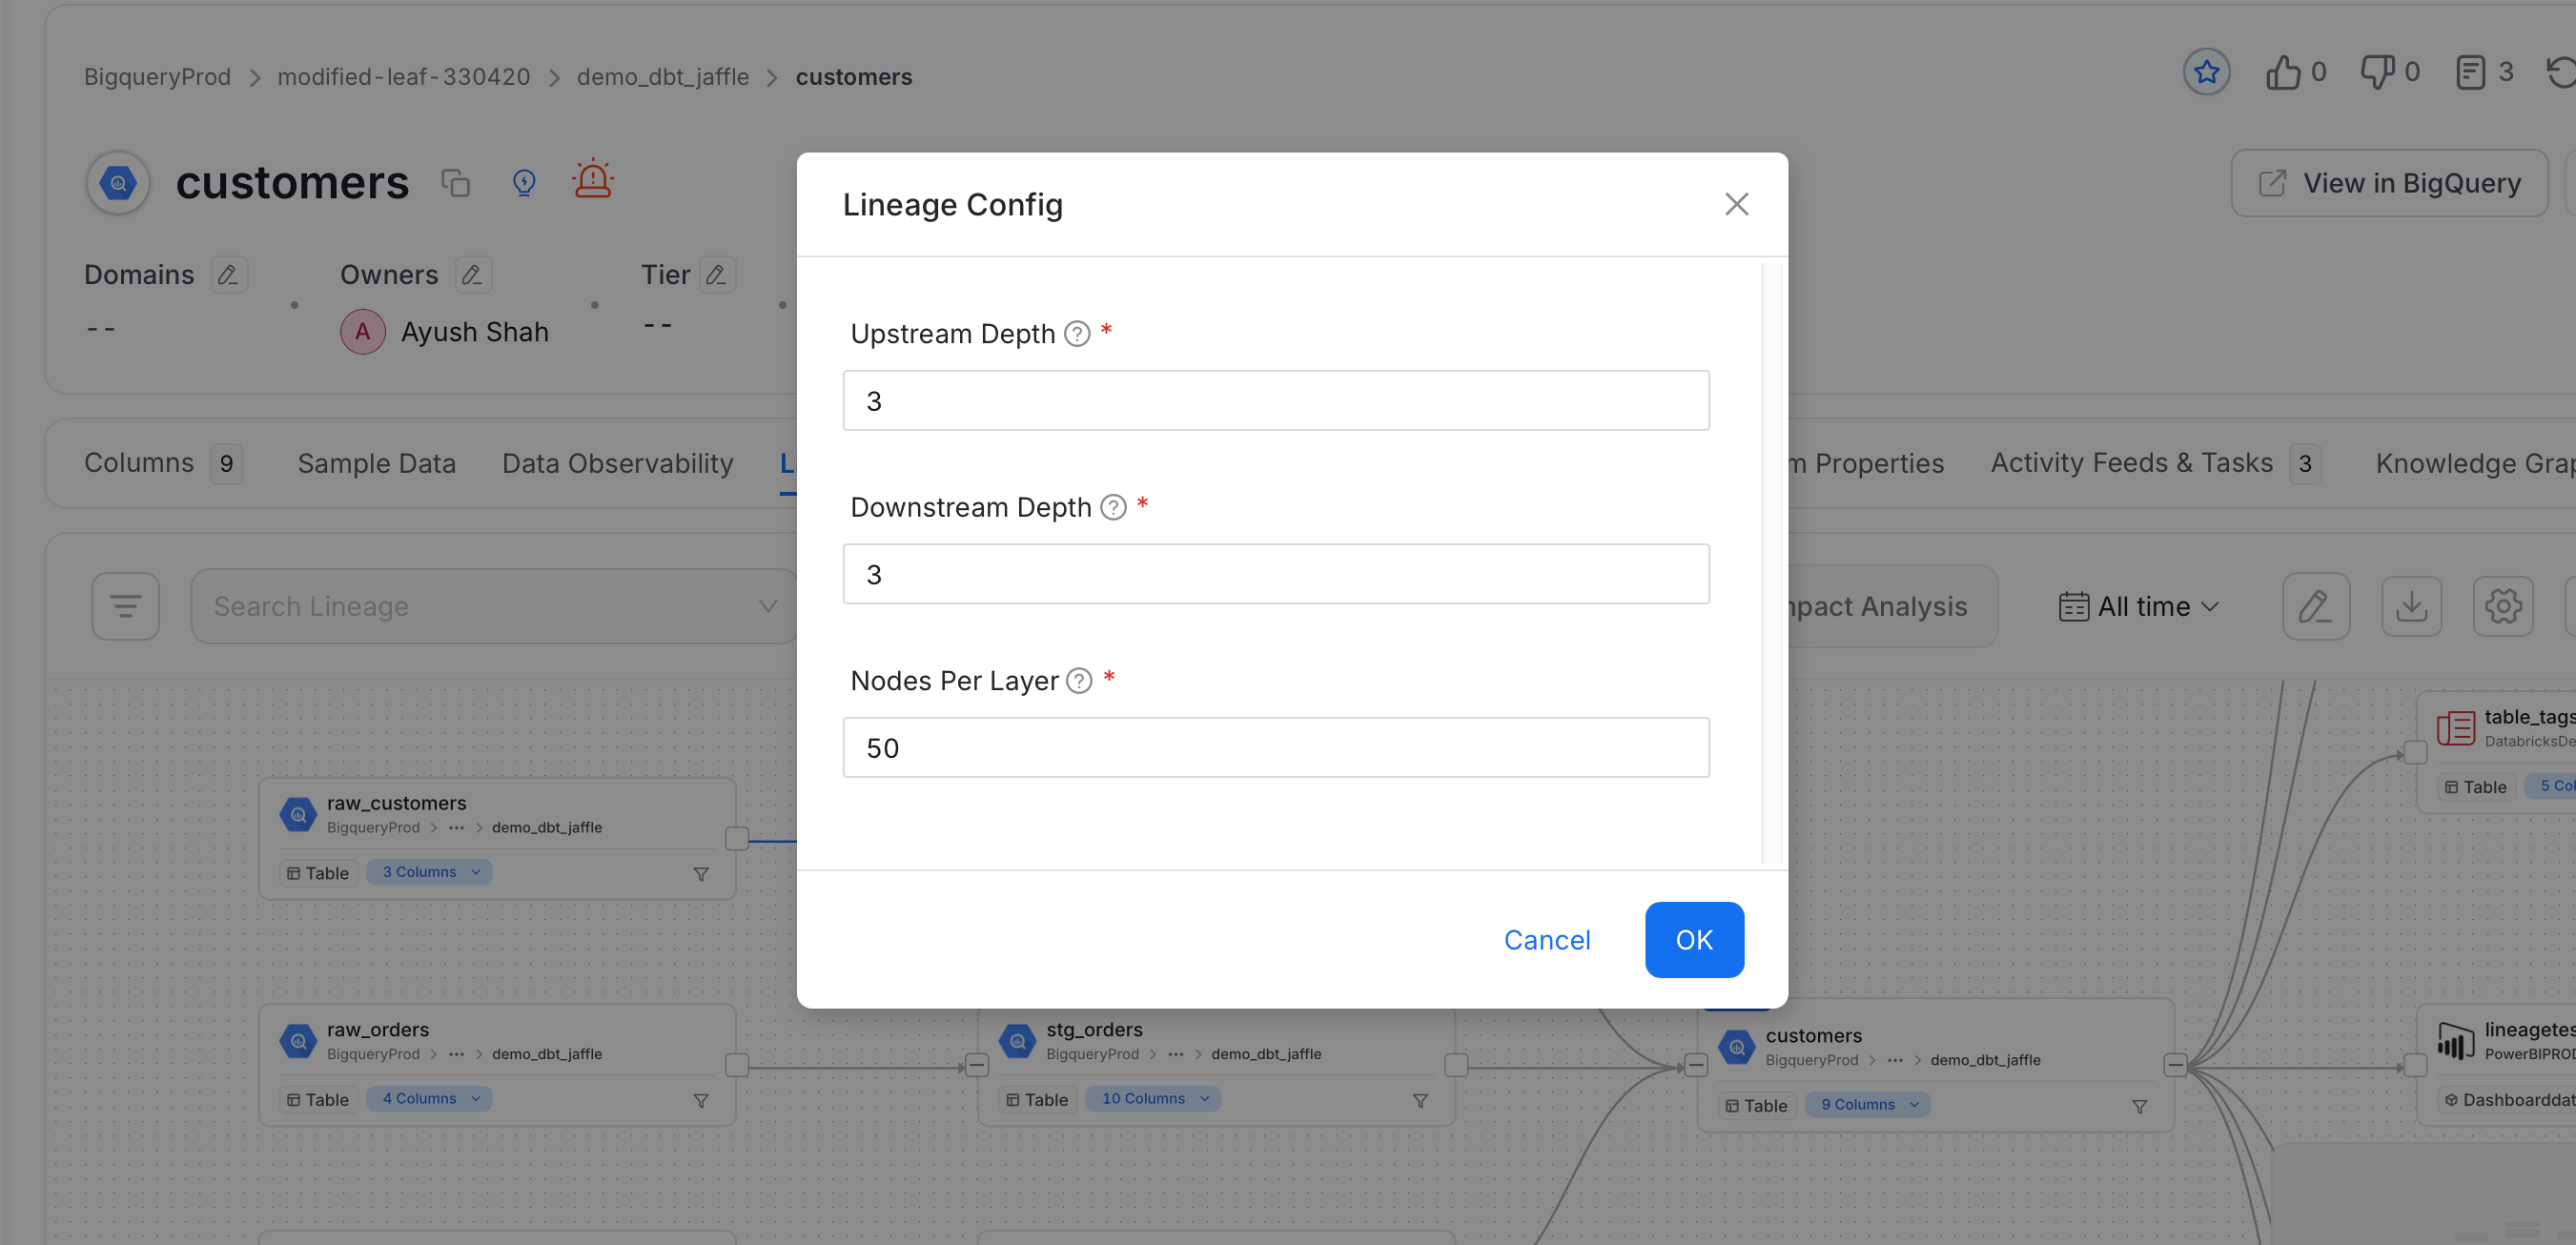
In the example below:- The table on the left is the parent, or Source node.
- The table on the right is the Target node, identifiable by the arrow pointing into it.
- The arrow connecting them is the Edge.
Lineage Config
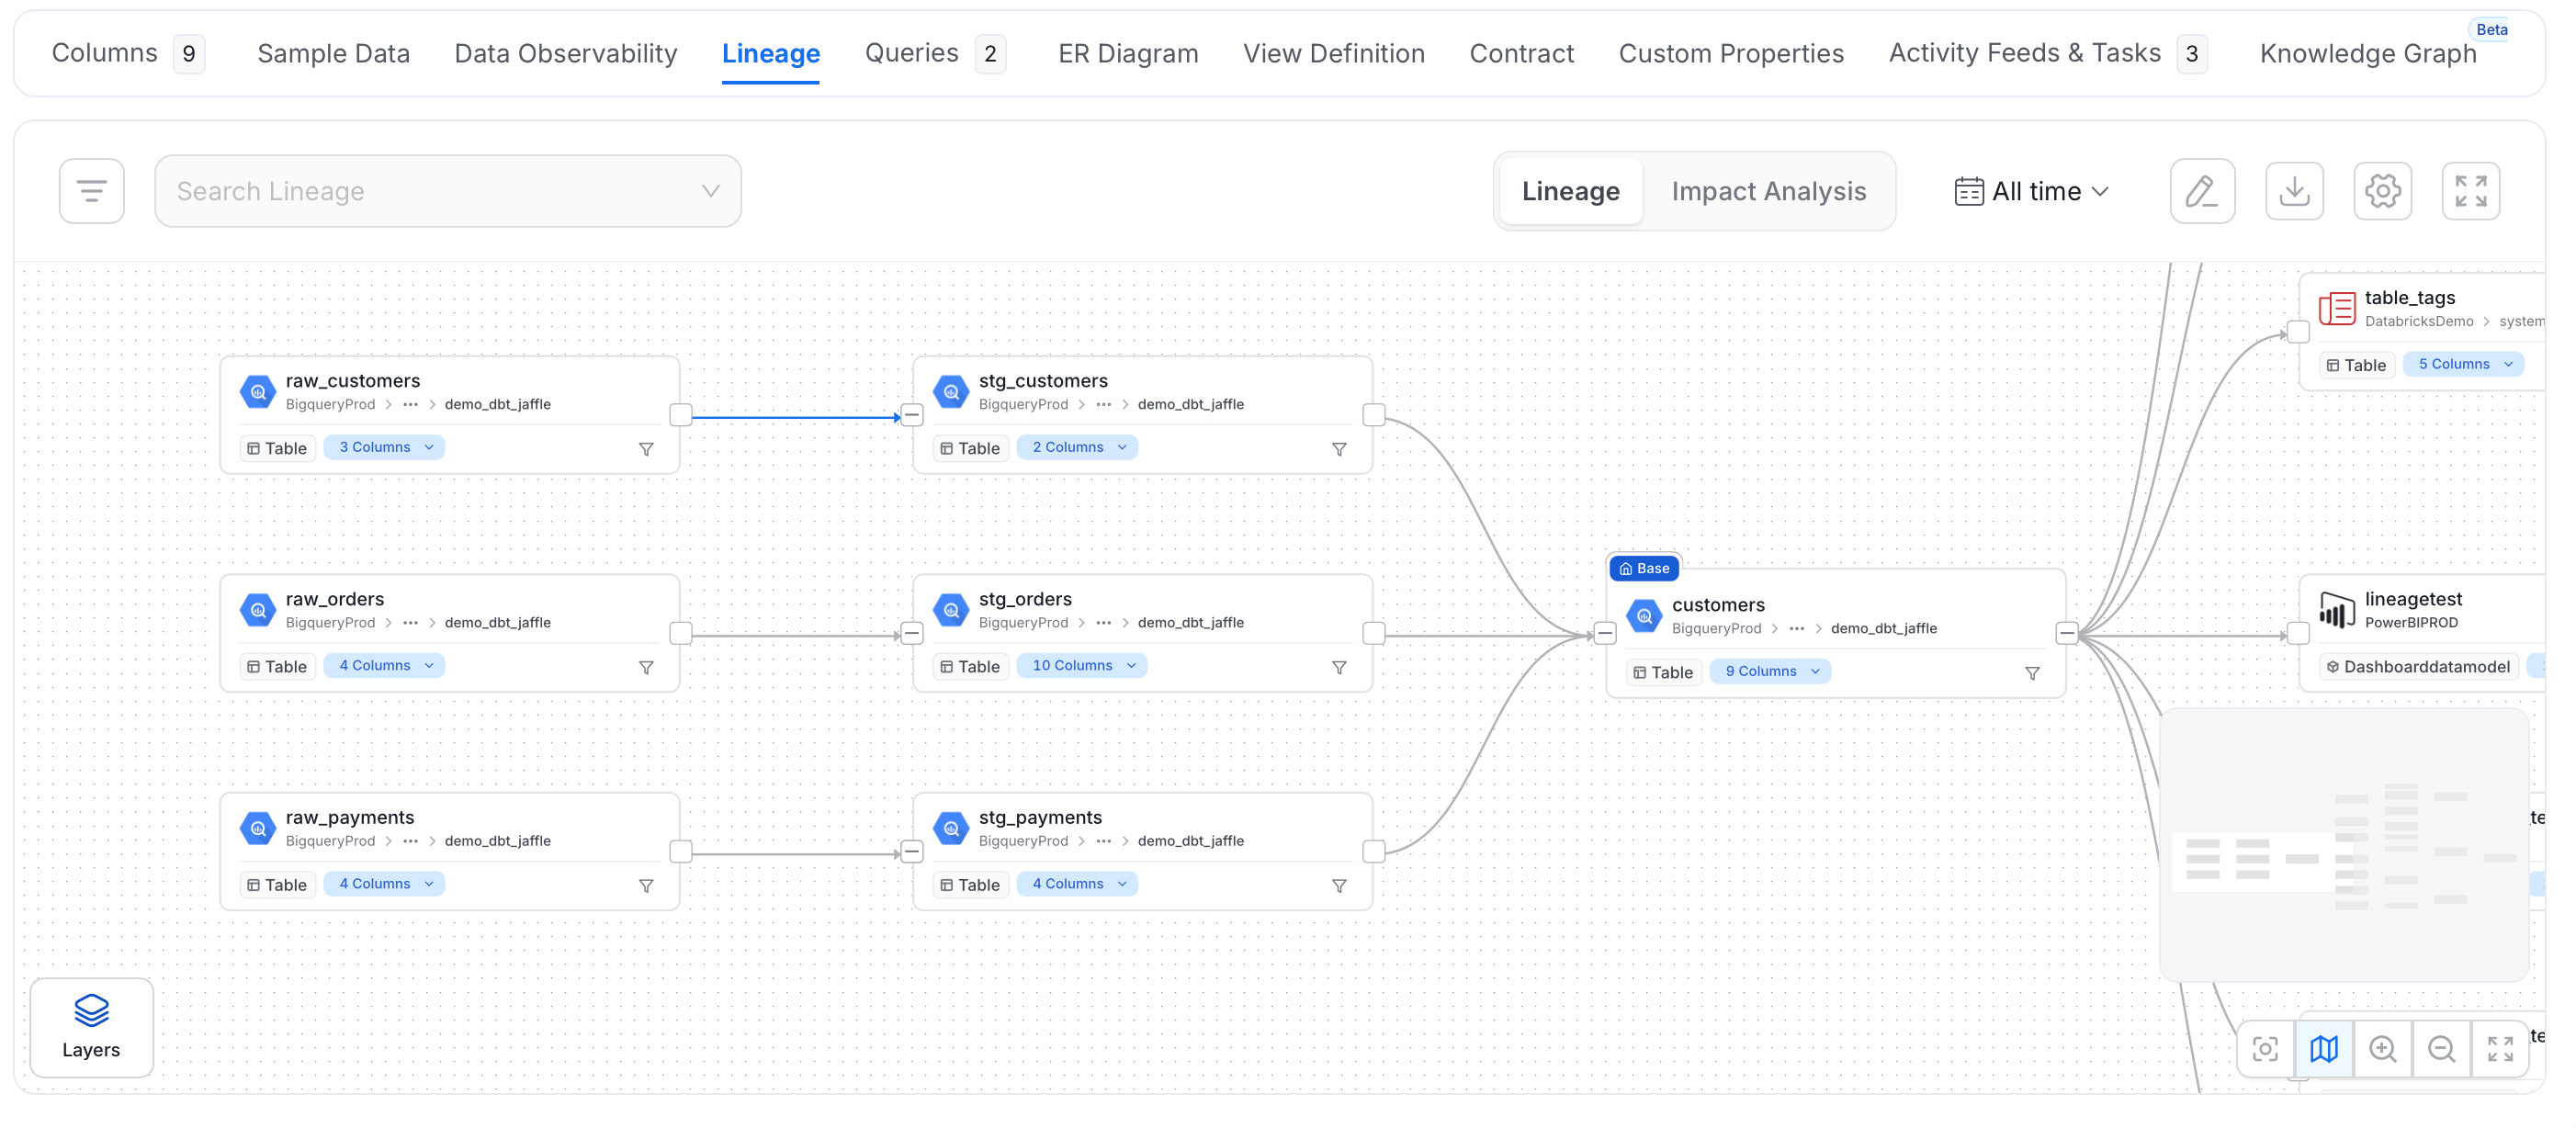
You can set up the Lineage Config to display the required number of Upstream and Downstream Nodes, as well as the Nodes per layer. There’s no fixed maximum for these fields. This only affects your current view: it resets to the platform default the next time you open a lineage graph. To configure the lineage nodes, follow the steps below:-
Click the Setting icon.
-
Set the following fields:
- Upstream Depth: Number of upstream hops shown by default when opening a lineage graph, to identify parent-level sources.
- Downstream Depth: Number of downstream hops shown by default when opening a lineage graph, to identify child-level targets.
- Nodes Per Layer: Maximum number of nodes shown per layer. If a layer has more nodes than this, the rest are paginated instead of all being rendered at once.
Impact Analysis View
The Lineage page has two tabs at the top: Lineage (the graph you’ve seen so far) and Impact Analysis, a table that lists the same upstream and downstream assets as rows instead of nodes on a graph. This is easier to scan, search, and sort when an asset has a large number of dependencies.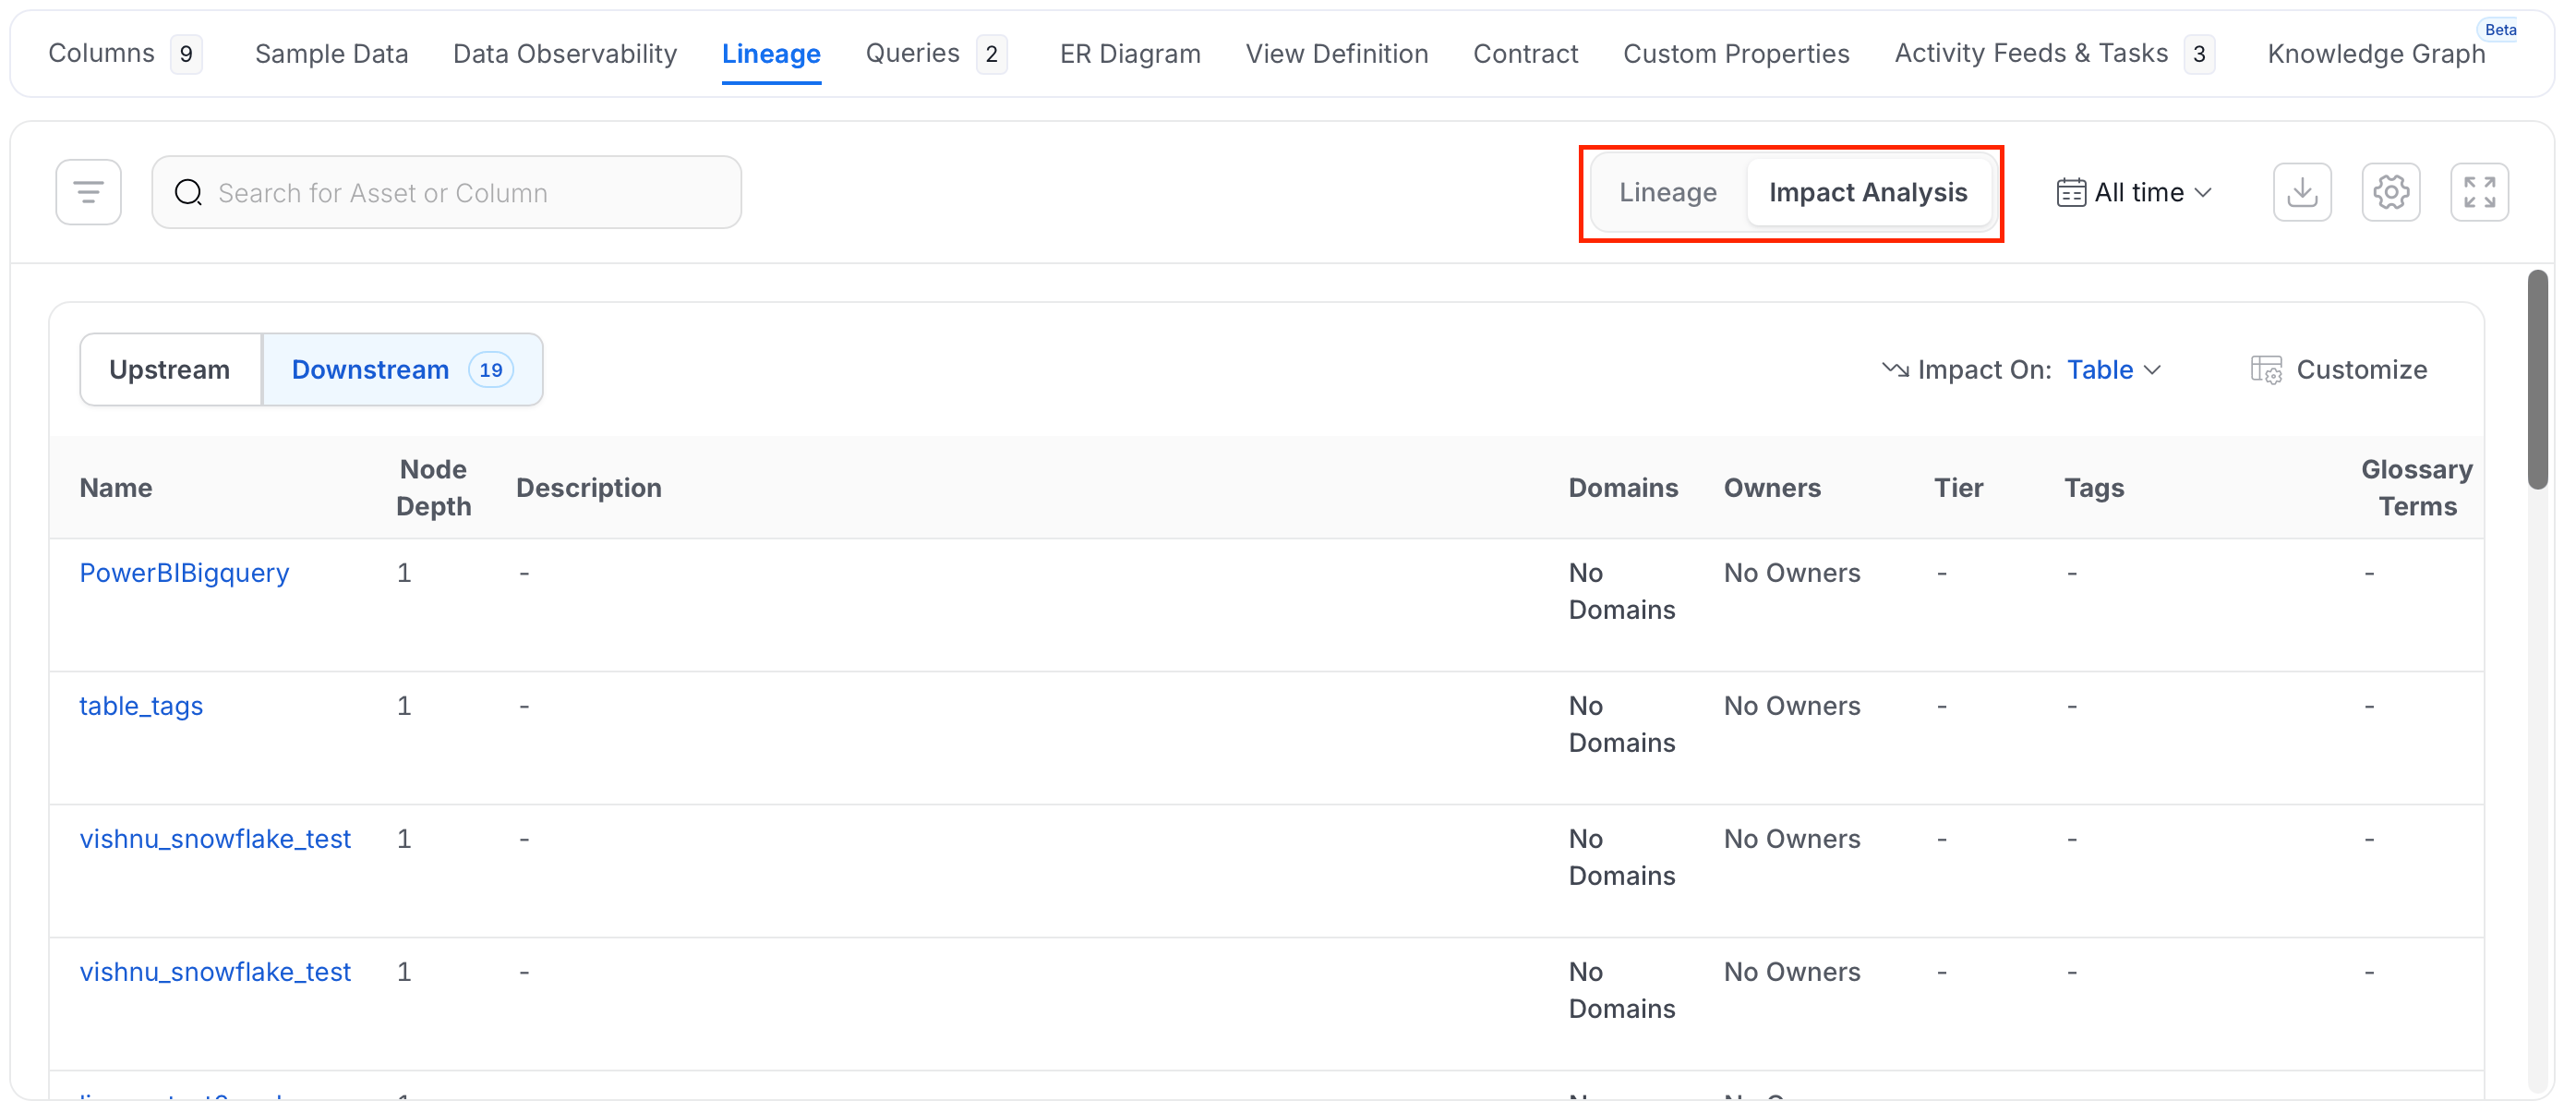
- Upstream / Downstream: Switch direction. Each option shows a count of how many assets lie in that direction.
- Impact On: Choose whether the table lists Asset Level impact (one row per table, pipeline, dashboard, and so on) or Column Level impact (one row per source-to-target column mapping).
- Customize: Choose which columns to show. Name (or Source/Impacted Column, in Column Level mode) always stays visible. Every other column can be toggled off.
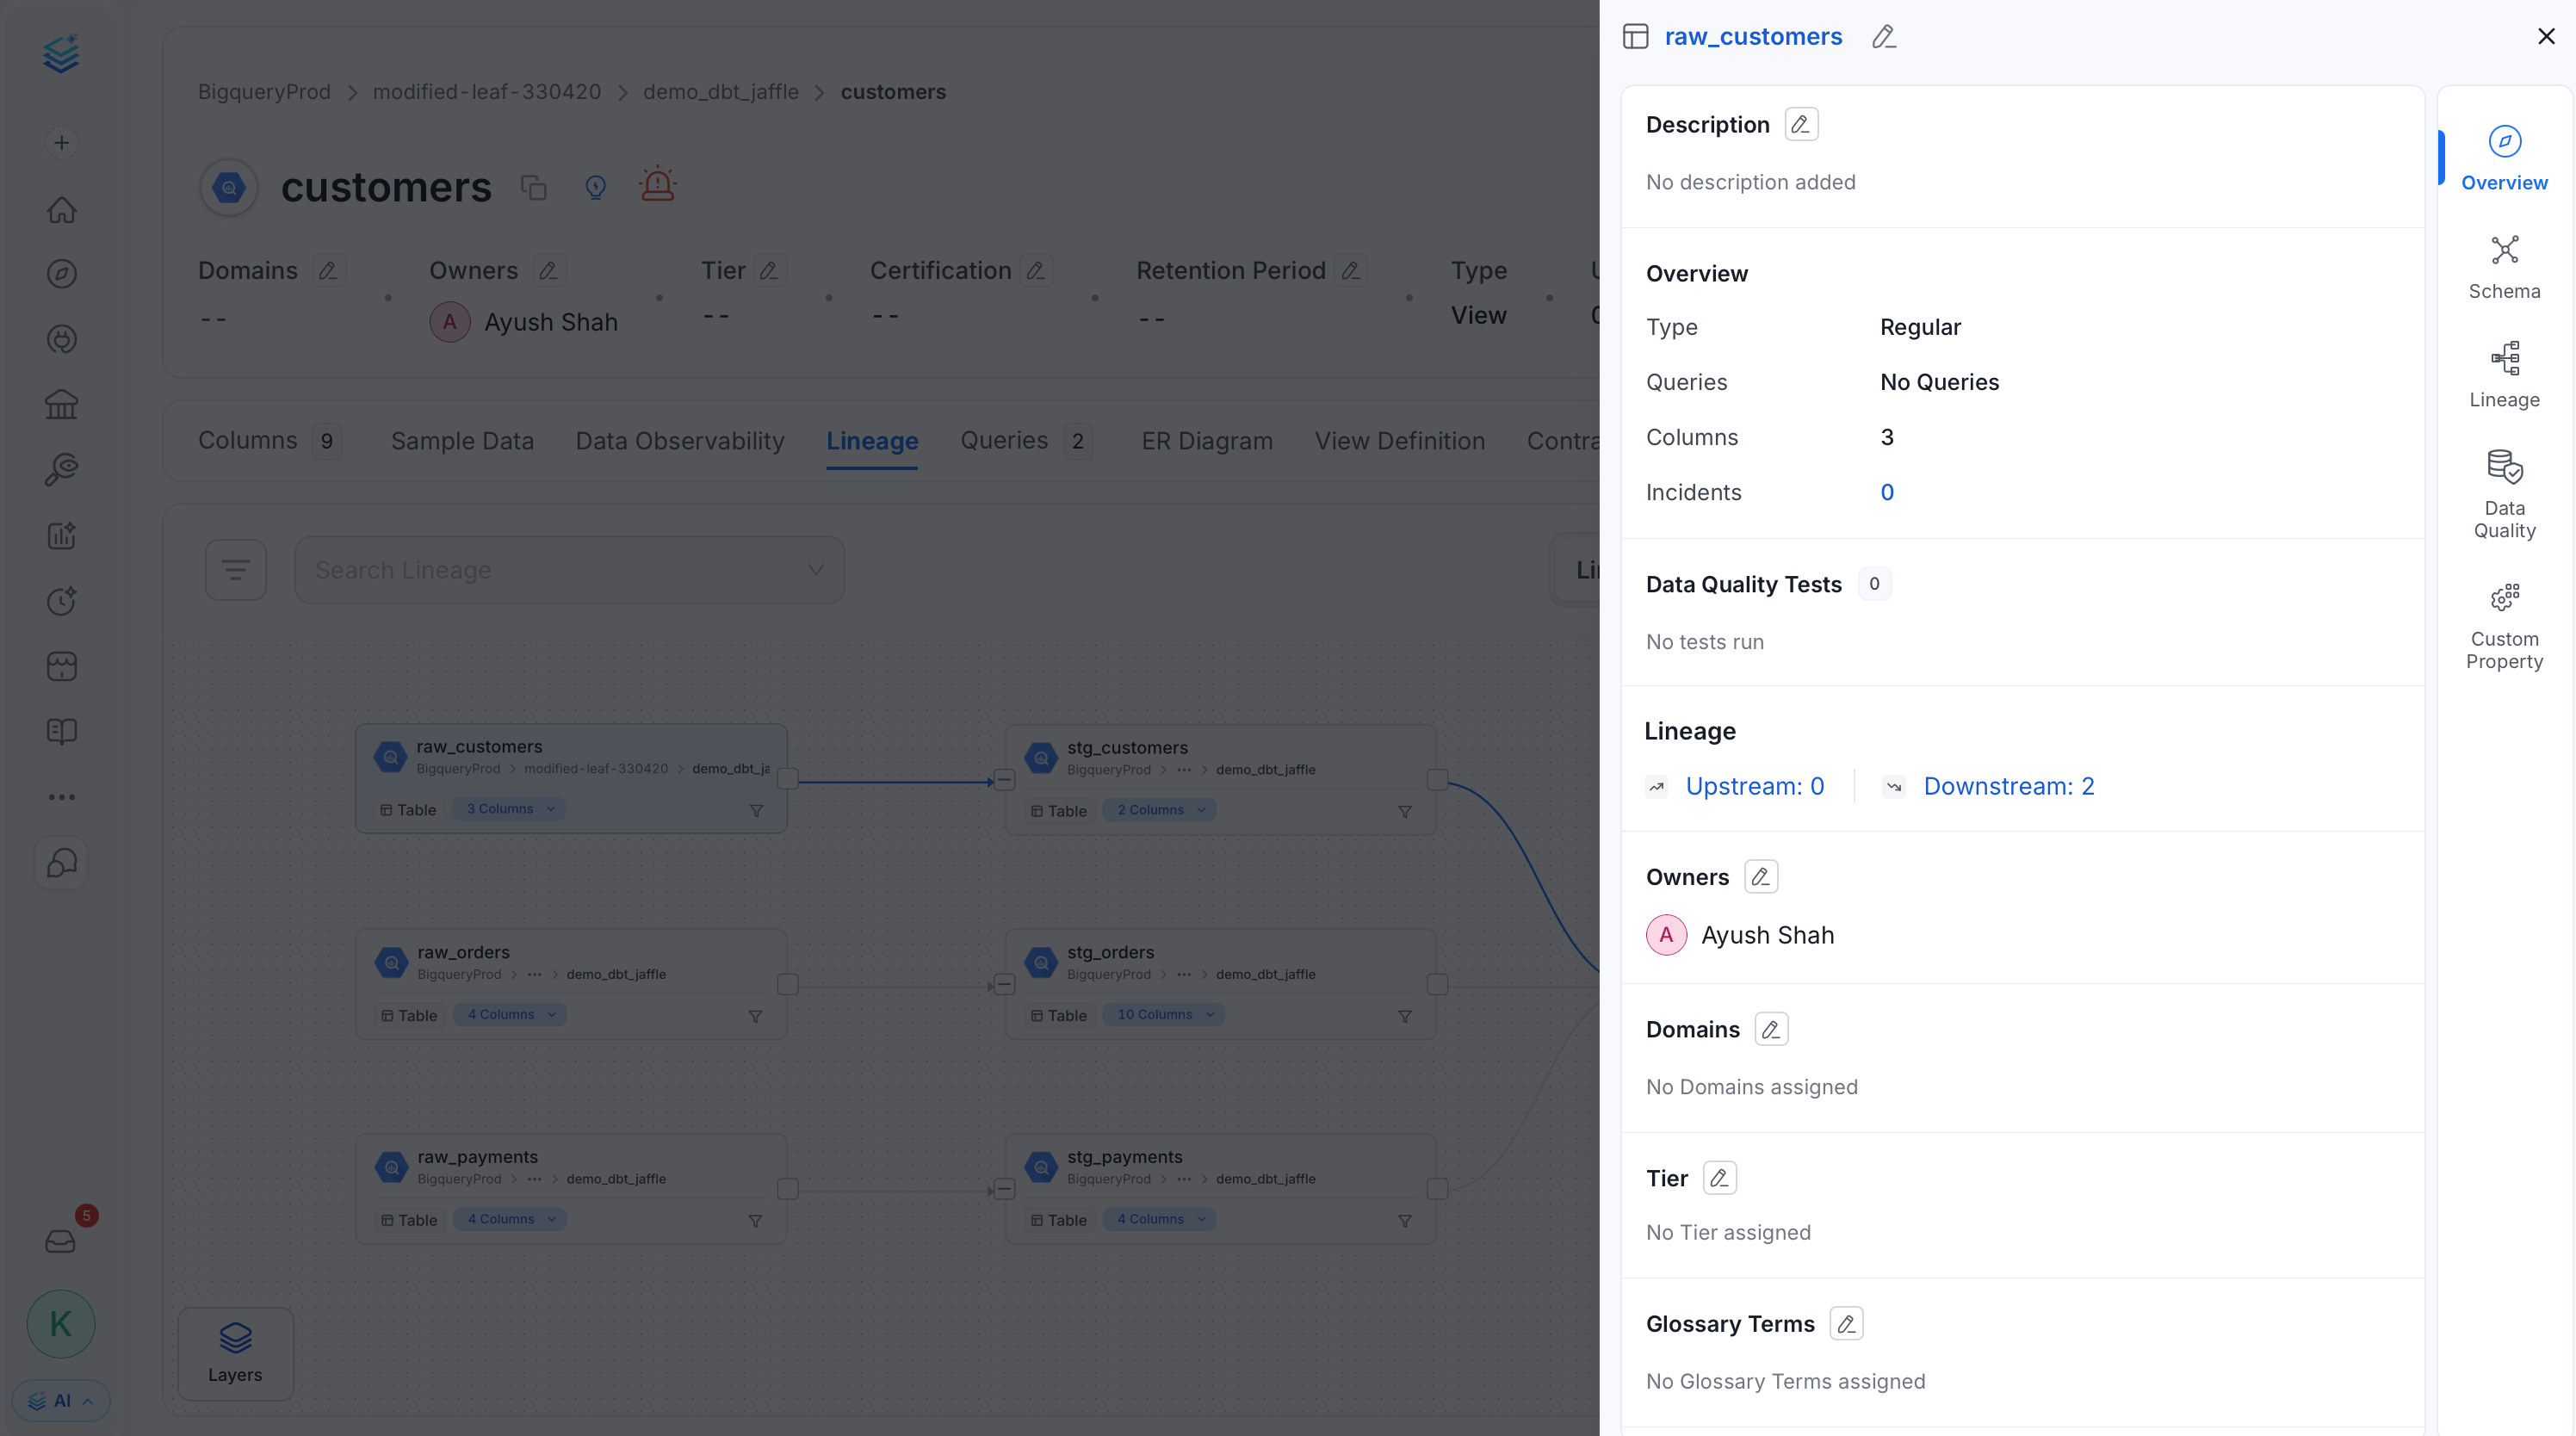
Data Asset Details
Click a data asset to view its details:- Source, Name, Description, Owner (team/user), Tier, and Usage information.
- Additional details based on the type of data asset (Table, Topic, Dashboard, Pipeline, ML Model, Container). For example, a table’s type, number of queries, and columns.
- Data quality and profiler metrics, including tests passed, aborted, and failed.
- Tags associated with the data asset.
- Schema details: column names, column types, and column descriptions.
Column-Level Lineage
Click a table to expand its list of columns and see column-level lineage.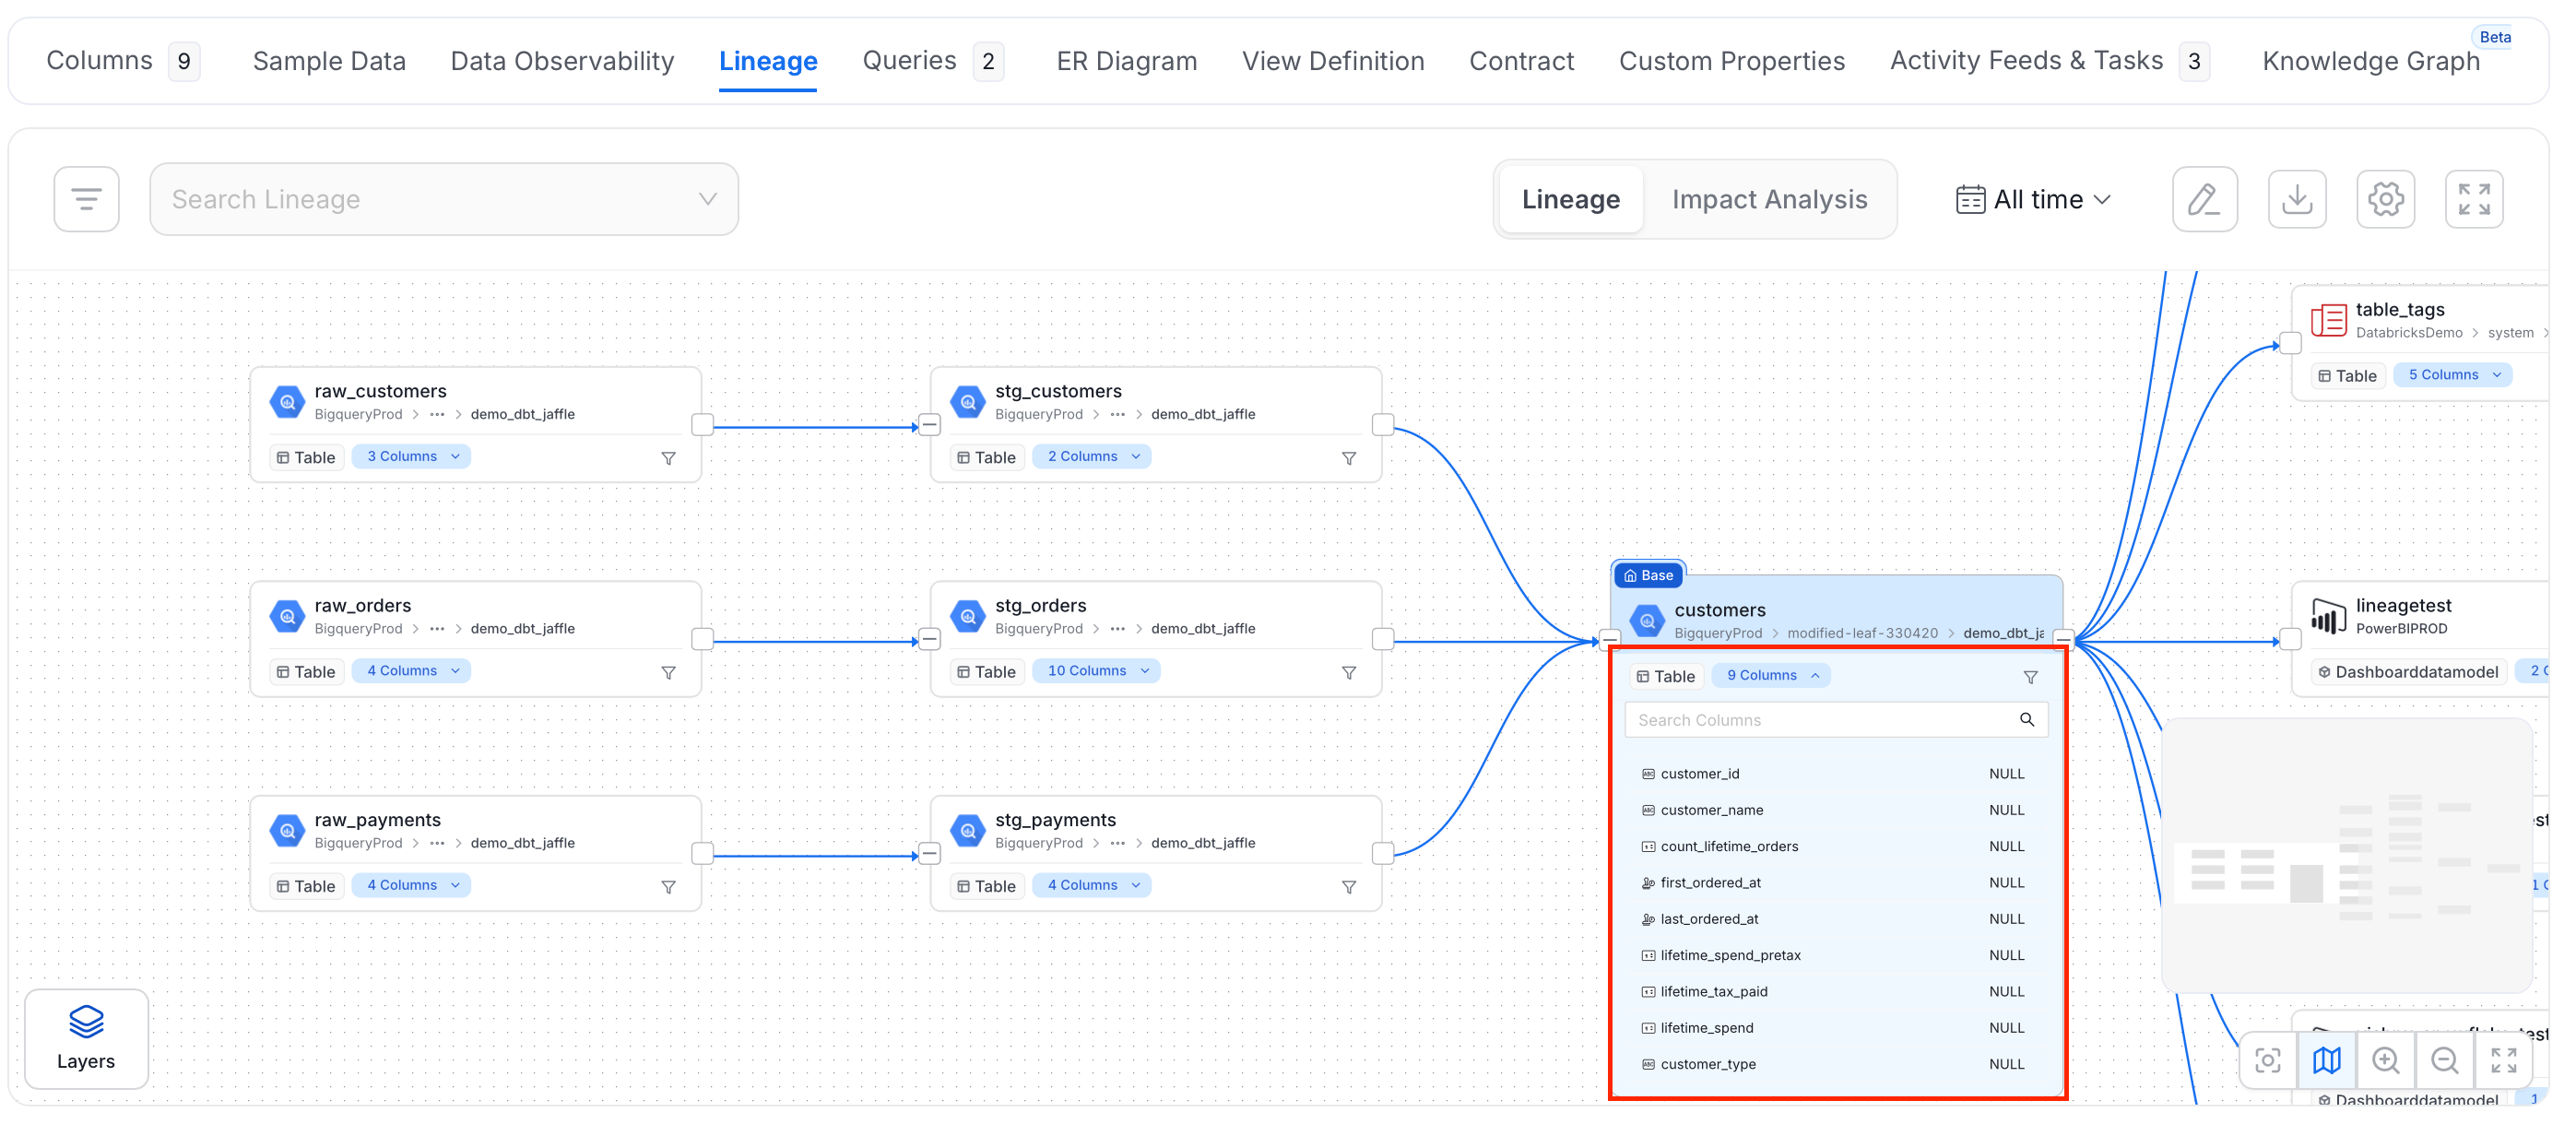
Pipeline and Dashboard Lineage
For Pipelines:- Lineage first comes from the metadata ingested from the databases.
- Setting up pipeline ingestion with a database service name links the pipeline to the database tables it reads from and writes to.
- If a pipeline creates the lineage, that shows up in the edge information too.
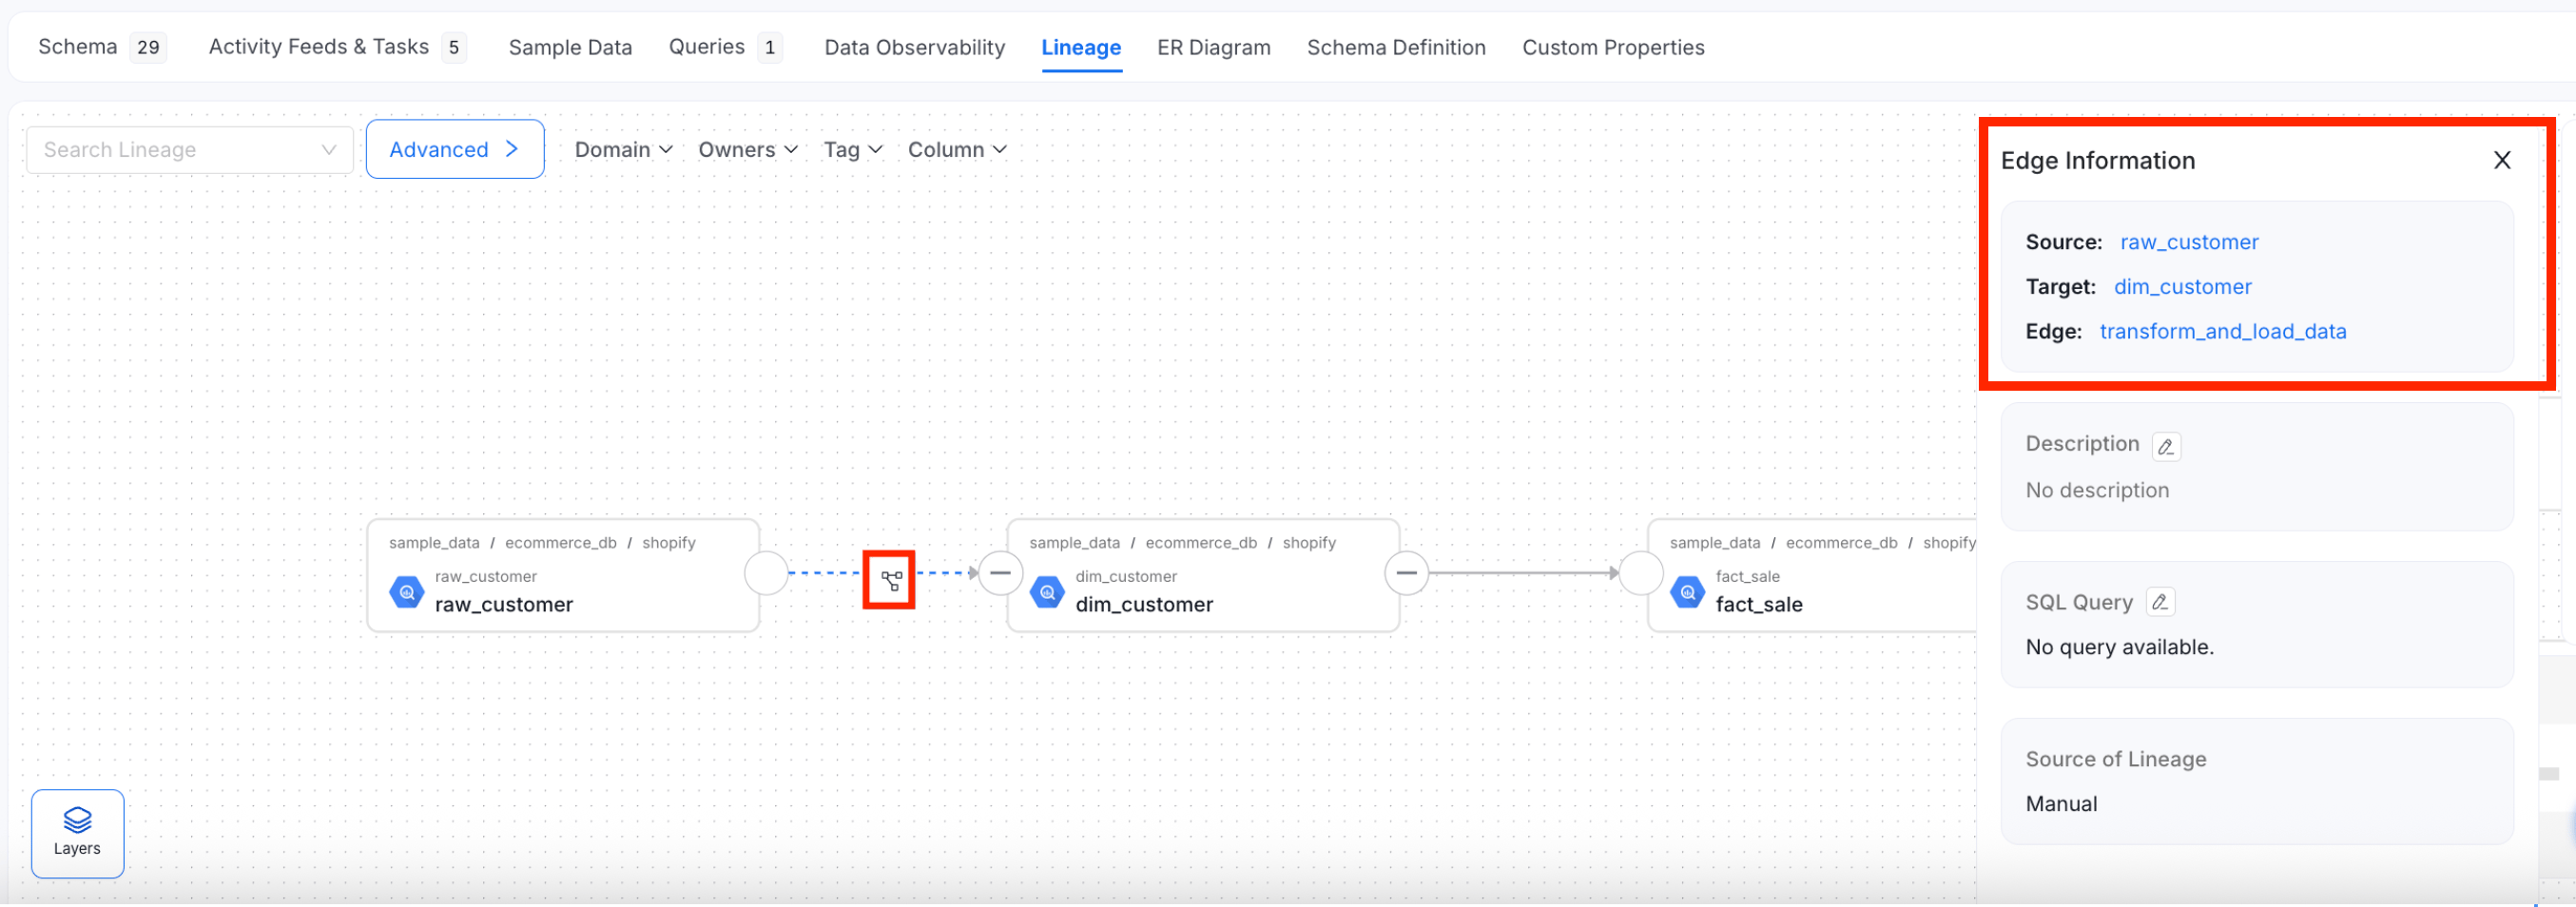
- Lineage first comes from the metadata ingested from the databases.
- Dashboard ingestion then adds the data models and charts, linking them back to the database tables they’re built on.
Lineage Layers
Lineage view supports multiple exploration layers that provide deeper insights into the structure, flow, and quality of data across your ecosystem. These layers help users visualize lineage not just at the dataset level, but also across services, domains, and business-critical data products.Column Layer
The Column layer enables detailed exploration of column-level lineage, allowing users to trace the flow and transformation of specific fields (e.g., customer_id, first_name) across tables and pipelines. This granularity helps in understanding data dependencies at the attribute level.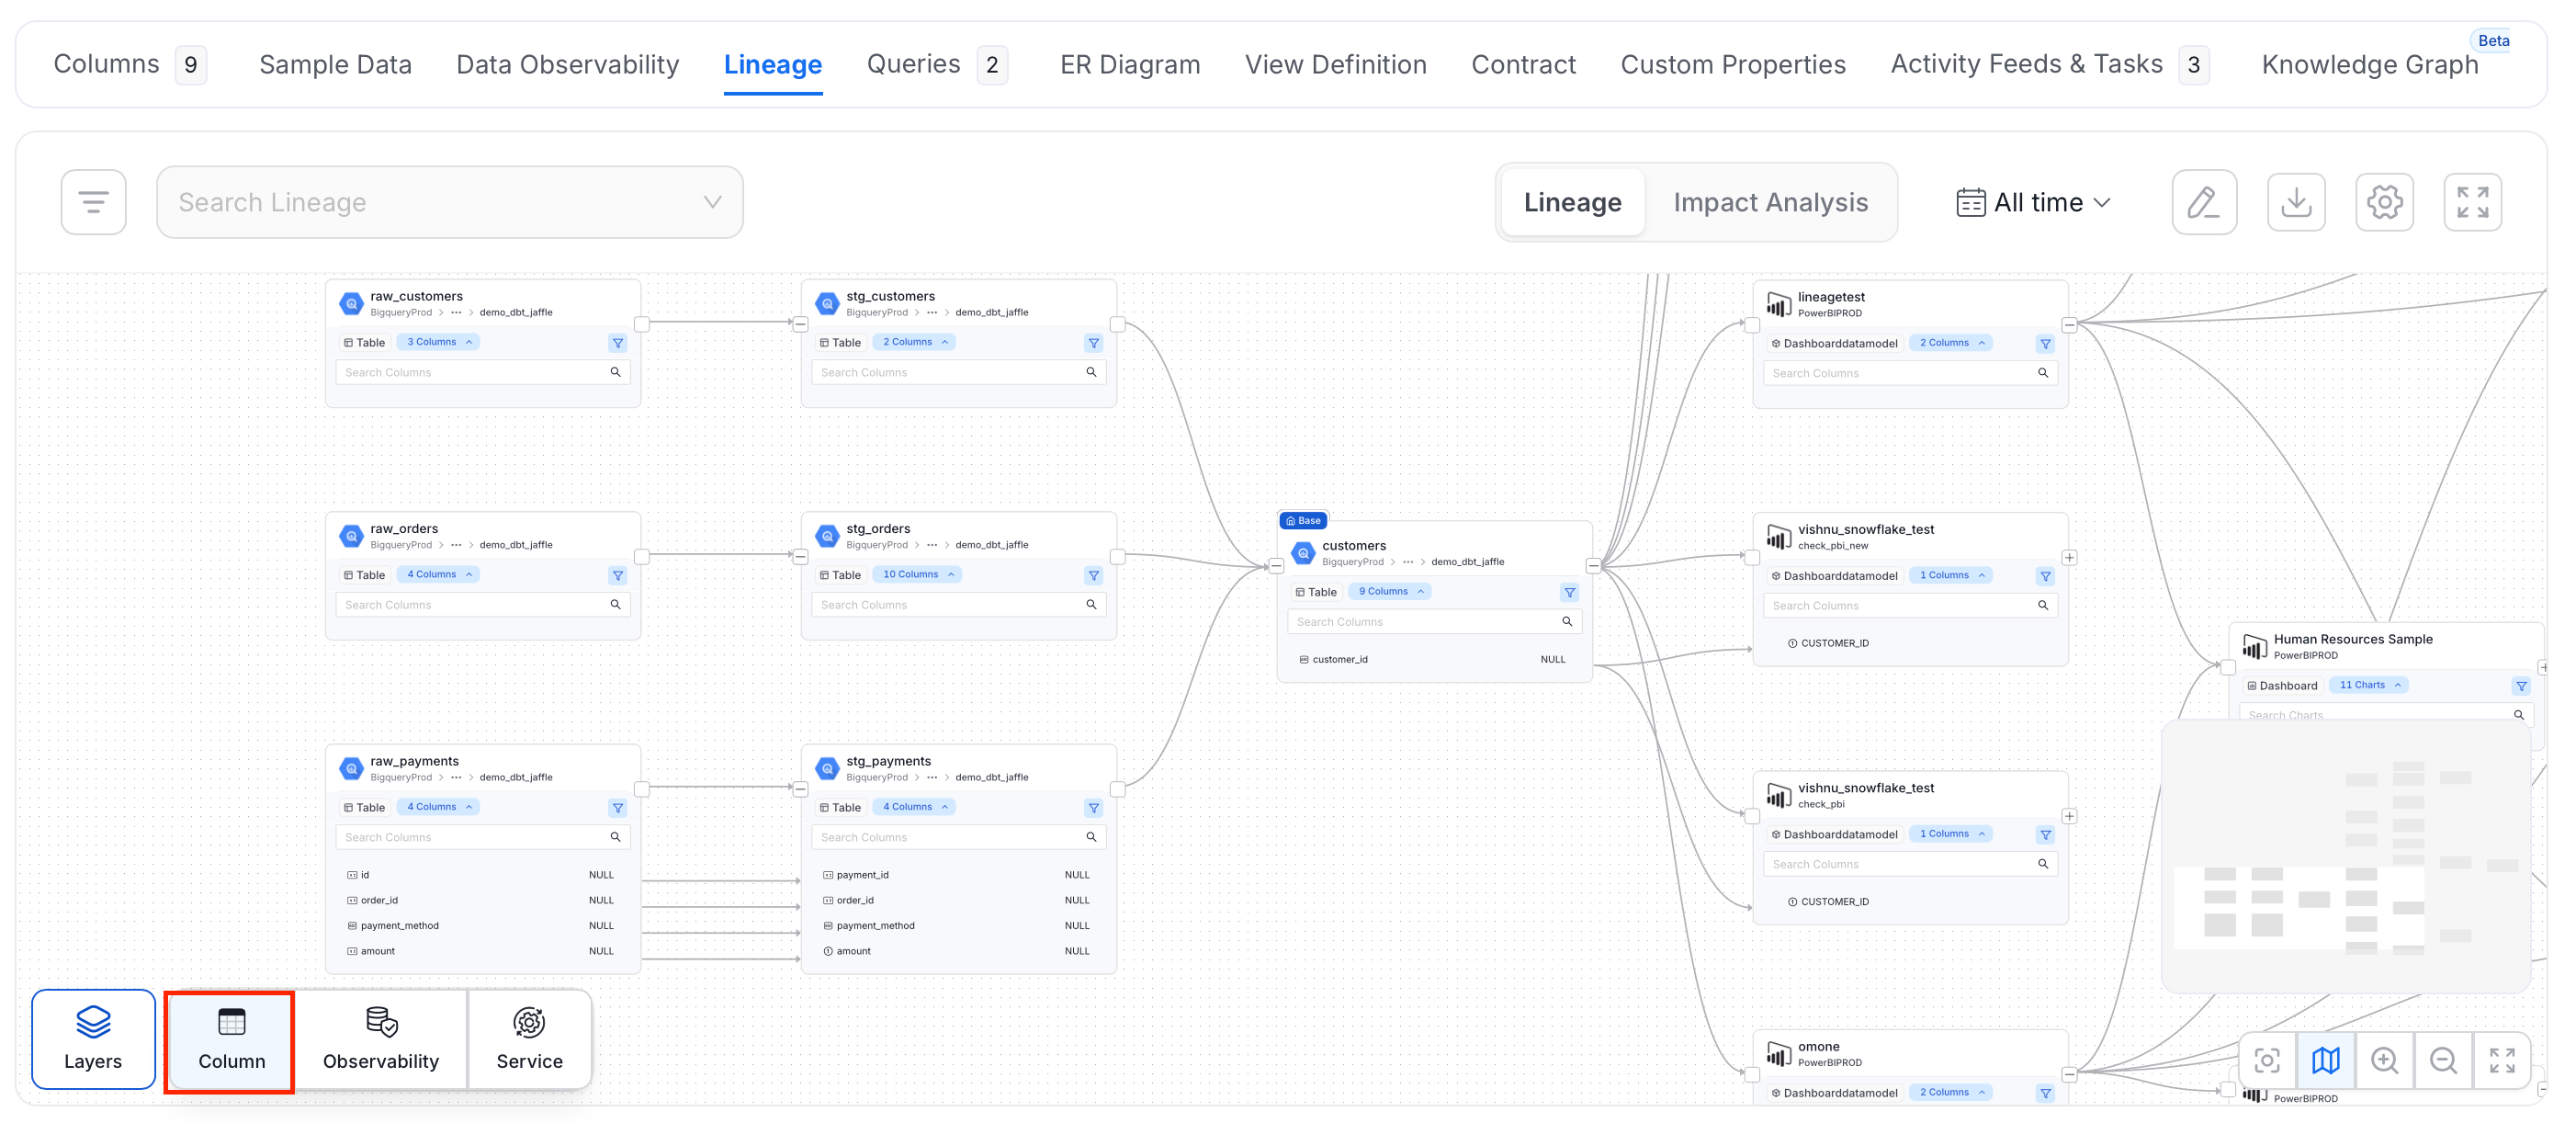
Observability Layer
The Observability layer integrates data quality insights directly into lineage by displaying test outcomes such as passes, failures, and pending checks. This helps users identify potential issues and assess the trustworthiness of data as it moves through the pipeline.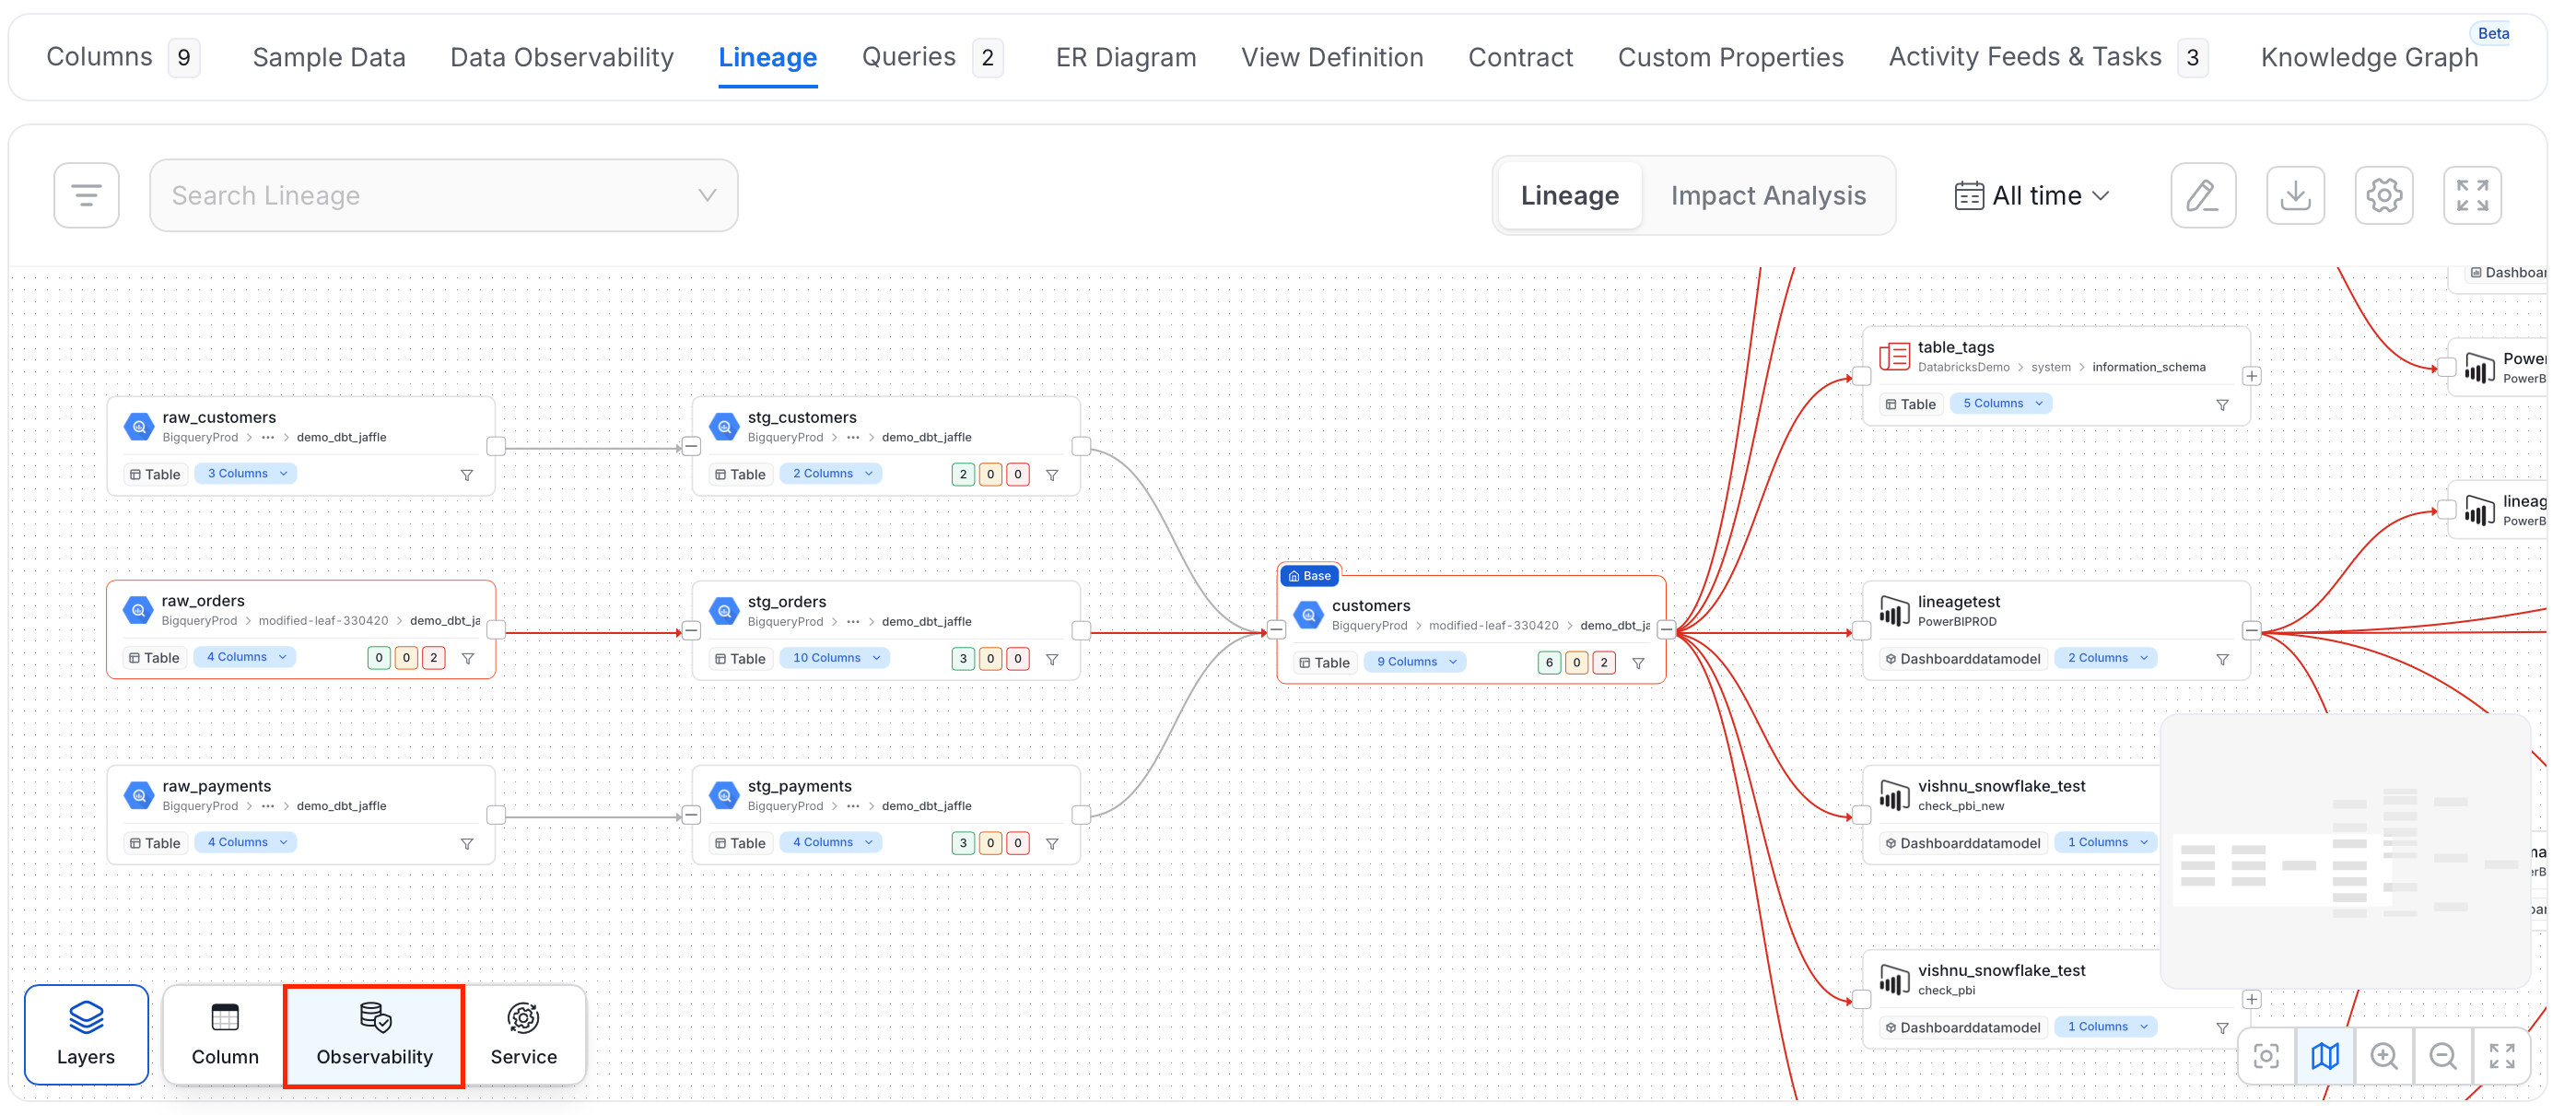
Service Layer
The Service layer visualizes how data flows across different platforms and services like Hive, Redshift, Power BI, and Tableau. It connects ingestion, transformation, and consumption points, offering a system-level view of the end-to-end data journey.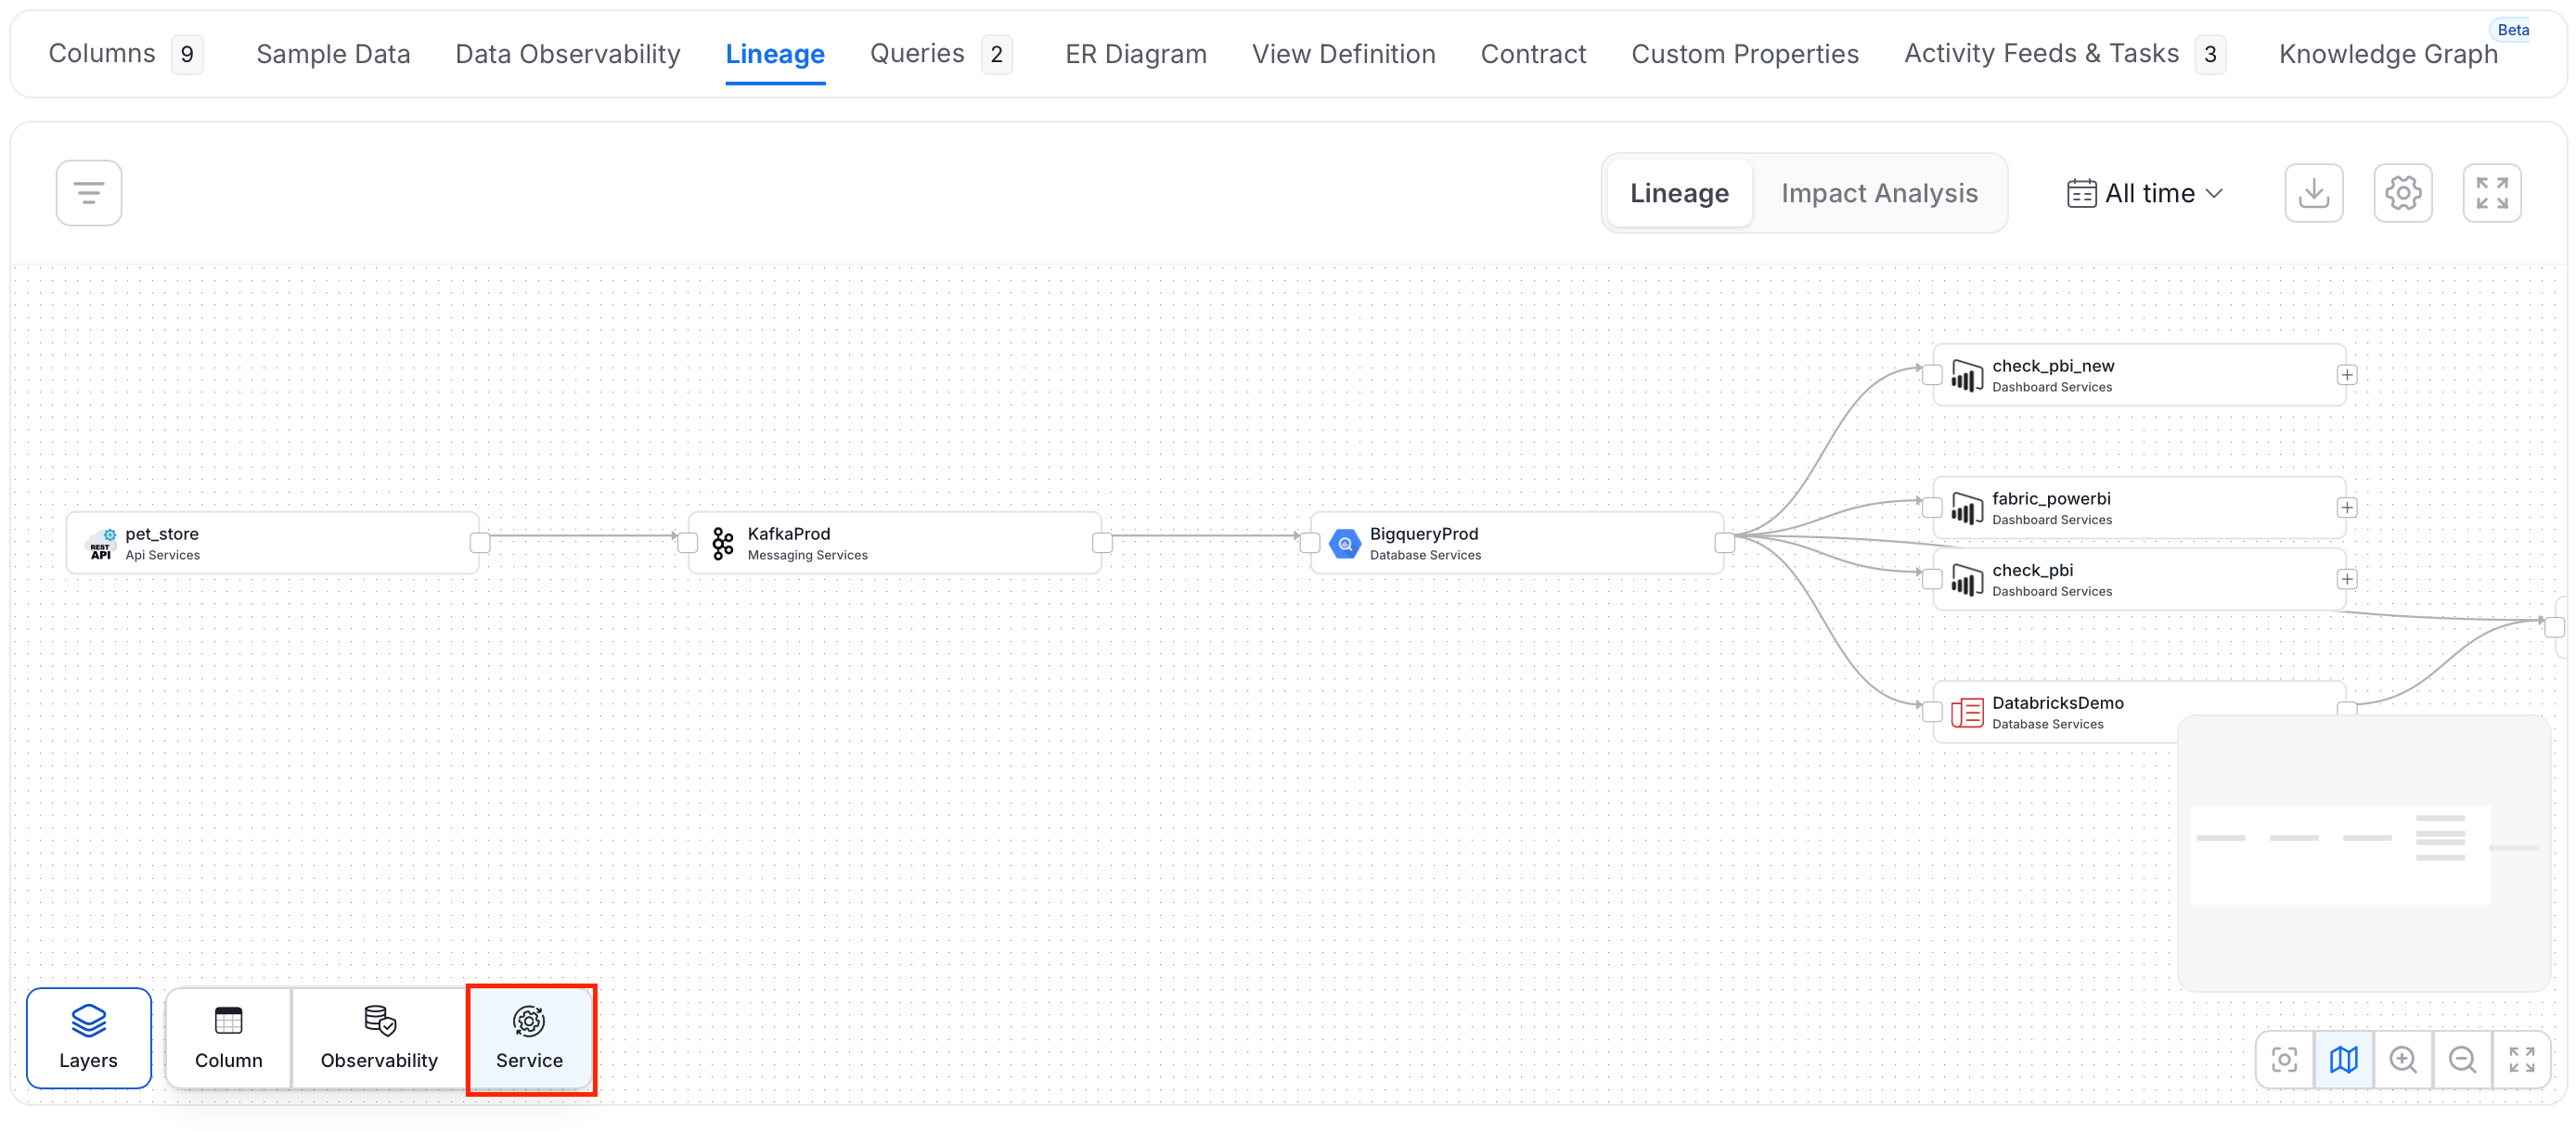
Domain Layer
The Domain layer organizes datasets and assets into business-relevant categories such as “Ecommerce” or “Customer Data.” This classification provides contextual clarity and supports governance by aligning technical assets with business functions.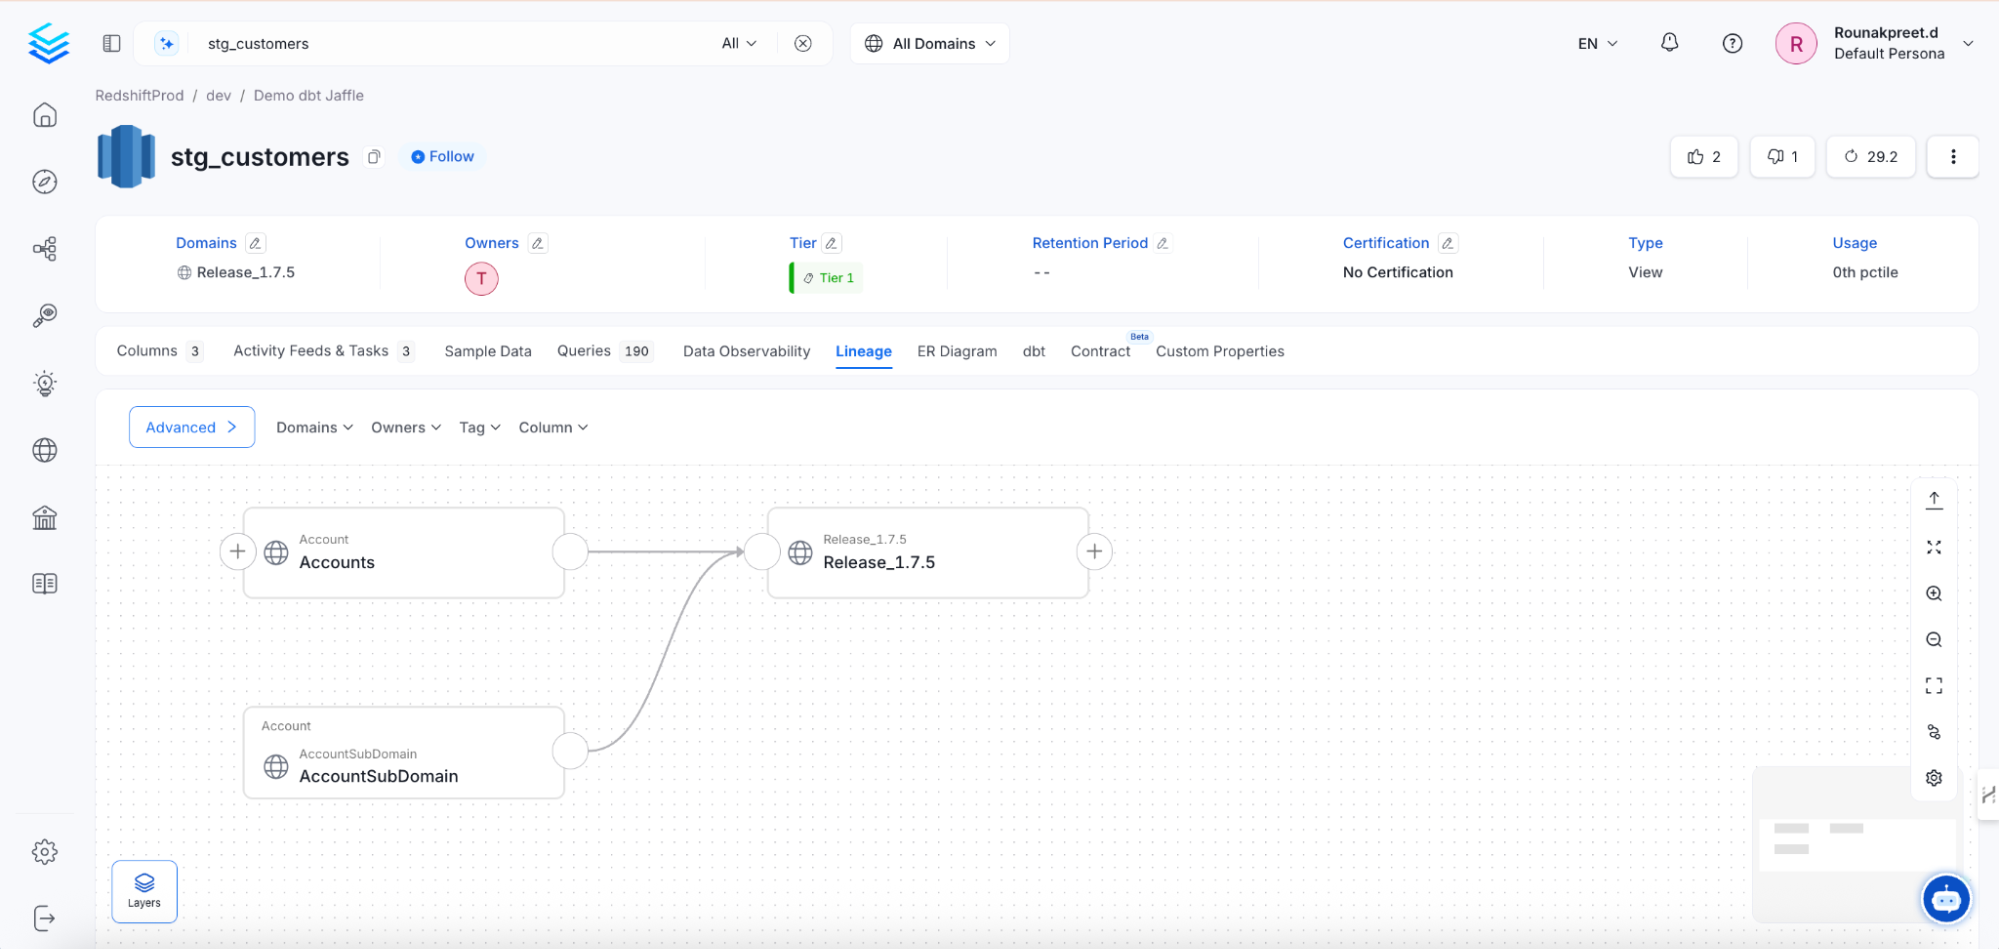
Data Product Layer
The Data Product layer highlights curated outputs like Customer Registry or Superstore, representing the final, value-delivering datasets within a domain. It enables teams to track the lineage of trusted, consumption-ready data products across the organization.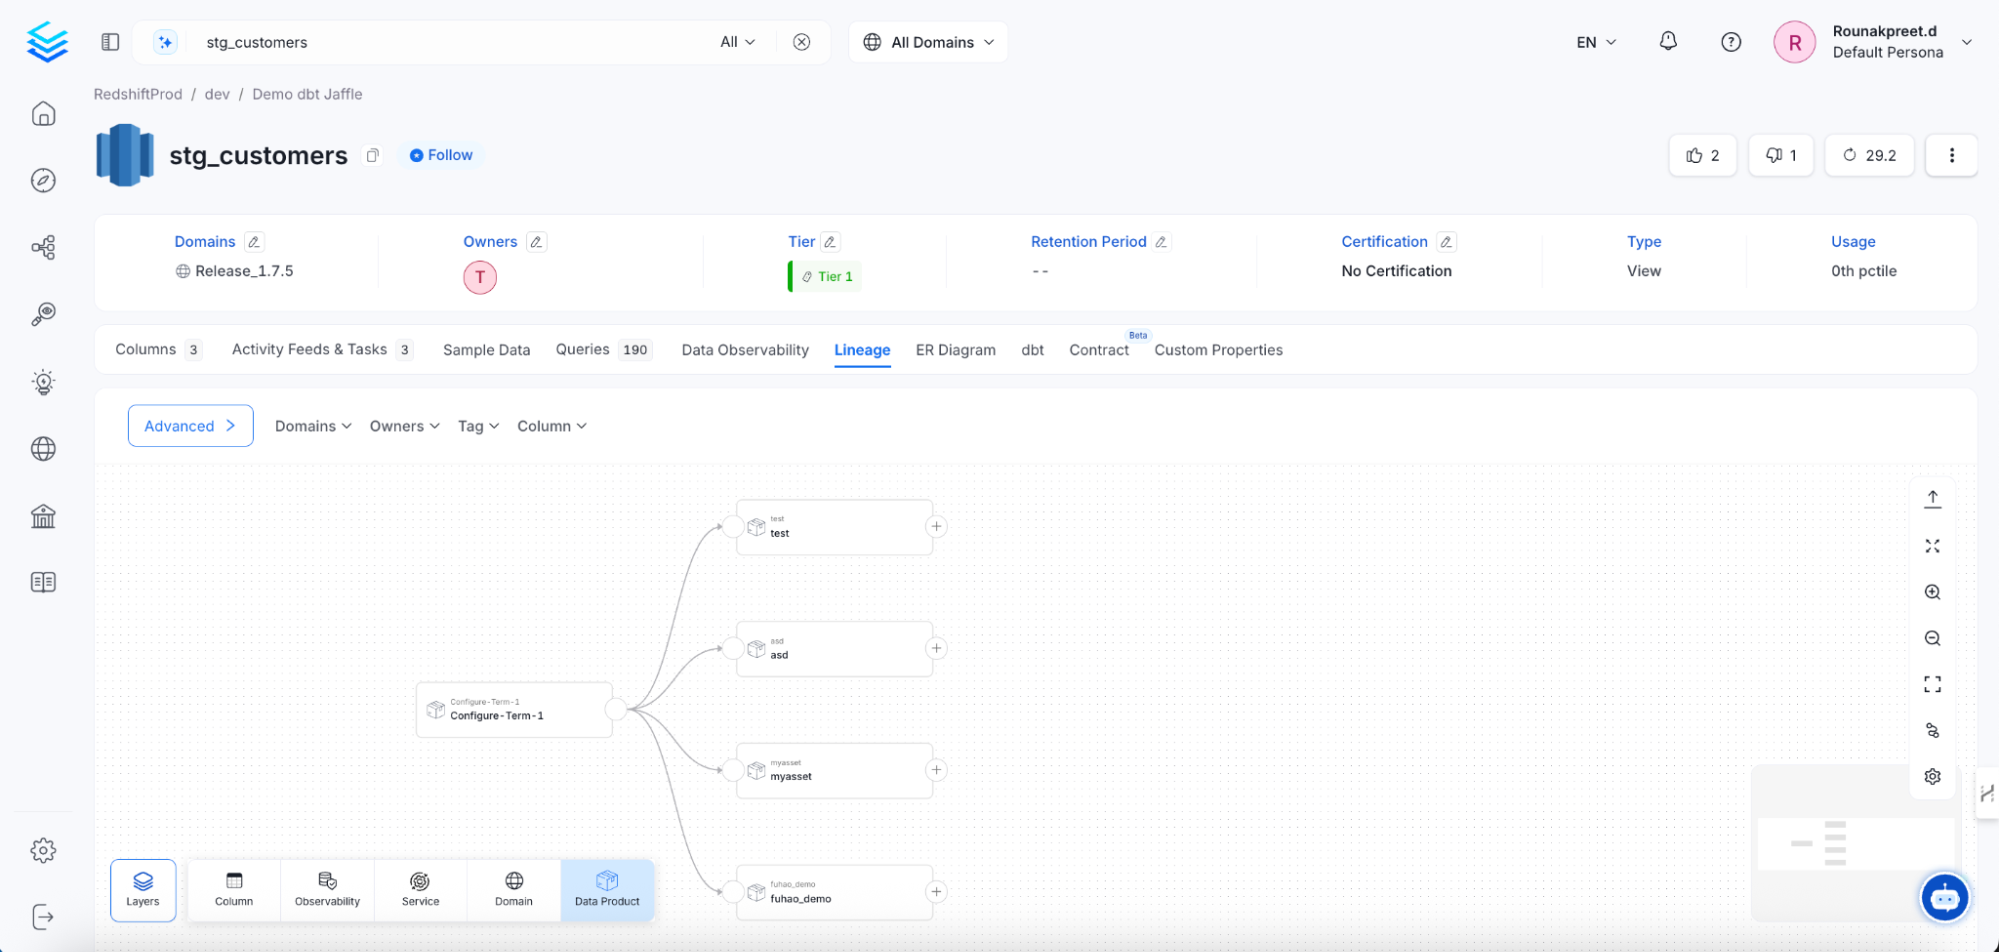
How Column-Level Lineage Works
Explore and edit the rich column-level lineage.