
Requirements
GCP Credentials
To connect to Google Drive, you’ll need to set up a Google Cloud Platform (GCP) service account with the necessary permissions.1. Create a Service Account
- Go to the Google Cloud Console
- Navigate to IAM & Admin > Service Accounts
- Click Create Service Account
- Provide a name and description for the service account
- Grant the service account the necessary roles (at minimum: Viewer role)
- Click Done
2. Enable Google Drive API
- In the Google Cloud Console, navigate to APIs & Services > Library
- Search for “Google Drive API”
- Click on it and enable the API
3. Create and Download Service Account Key
- Navigate back to IAM & Admin > Service Accounts
- Click on your newly created service account
- Go to the Keys tab
- Click Add Key > Create new key
- Choose JSON as the key type
- Download the JSON key file
4. Domain-Wide Delegation (Optional)
If you need to access files owned by other users in your organization:- In the service account details, click Show Domain-Wide Delegation
- Enable Enable Google Workspace Domain-wide Delegation
- Note the Client ID
- In Google Workspace Admin Console:
- Navigate to Security > API Controls > Domain-wide Delegation
- Add the Client ID with the following OAuth scopes:
https://www.googleapis.com/auth/drive.readonlyhttps://www.googleapis.com/auth/spreadsheets.readonly
- Specify the delegated email address in the connection configuration
Permissions Required
The service account needs:- Read access to the Google Drive files and folders you want to ingest
- If using shared drives: Access to the specific shared drive
- If using domain-wide delegation: Domain-wide delegation enabled with appropriate scopes
Metadata Ingestion
Connection Details
1
Connection Details
-
GCP Credentials: Provide the GCP credentials to access Google Drive API. You can provide the credentials in one of the following ways:
- GCP Credentials Path: Path to the GCP service account credentials JSON file
- GCP Credentials Values: Paste the content of the GCP service account credentials JSON file directly
- Delegated Email (Optional): Email address to impersonate using domain-wide delegation. This is required if you want to access files owned by other users in your organization using domain-wide delegation.
- Drive ID (Optional): Specific shared drive ID to connect to. If provided, only this shared drive will be processed. Leave empty to process all accessible drives.
-
Include Team Drives: Enable to include shared/team drives in metadata extraction. Default is
true. -
Include Google Sheets: Enable to extract metadata only for Google Sheets files. When enabled, only Google Sheets will be processed. Default is
false. - Directory Filter Pattern (Optional): Regex pattern to include or exclude directories from metadata extraction.
- File Filter Pattern (Optional): Regex pattern to include or exclude files from metadata extraction.
- Spreadsheet Filter Pattern (Optional): Regex pattern to include or exclude spreadsheets from metadata extraction (only applies when Include Google Sheets is enabled).
- Worksheet Filter Pattern (Optional): Regex pattern to include or exclude worksheets within spreadsheets from metadata extraction (only applies when Include Google Sheets is enabled).
2
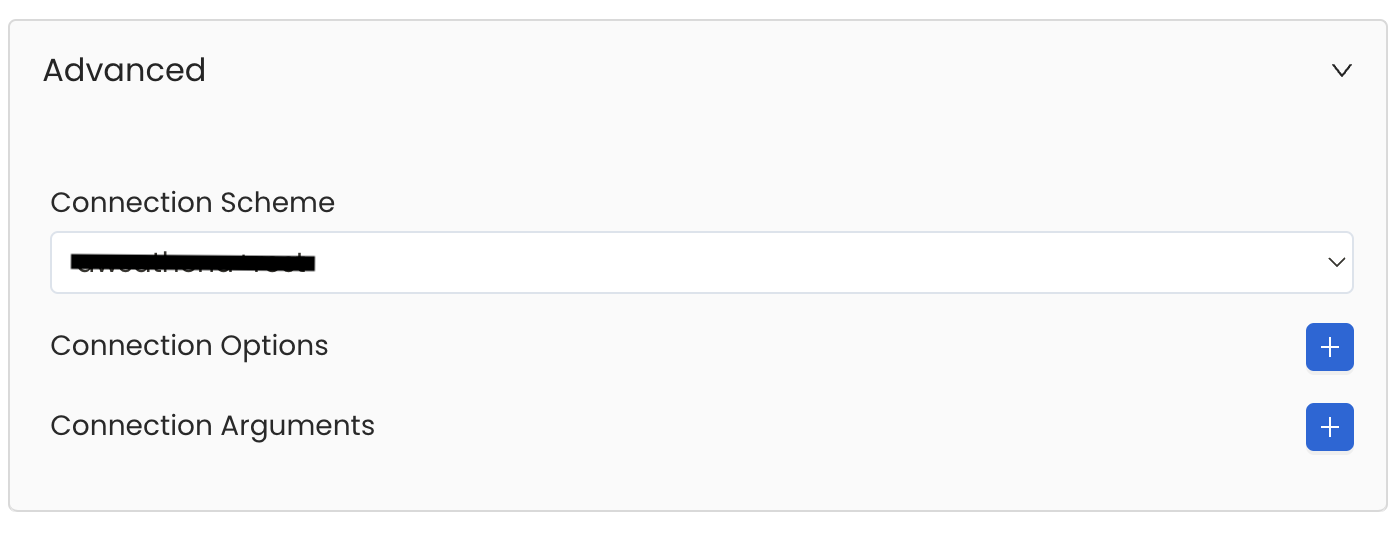
Advanced Configuration
Drive Services have an Advanced Configuration section, where you can pass extra arguments to the connector.This would only be required to handle advanced connectivity scenarios or customizations.
- Connection Options (Optional): Additional connection options to build the URL that can be sent to the service during the connection. These details must be added as Key-Value pairs.
-
Connection Arguments (Optional): Additional connection arguments such as security or protocol configs that can be sent to the service during the connection. These details must be added as Key-Value pairs.
3
Test the Connection
Once the credentials have been added, click on Test Connection and Save the changes.
4
Configure Metadata Ingestion
This step configures the metadata ingestion pipeline. Follow the instructions below.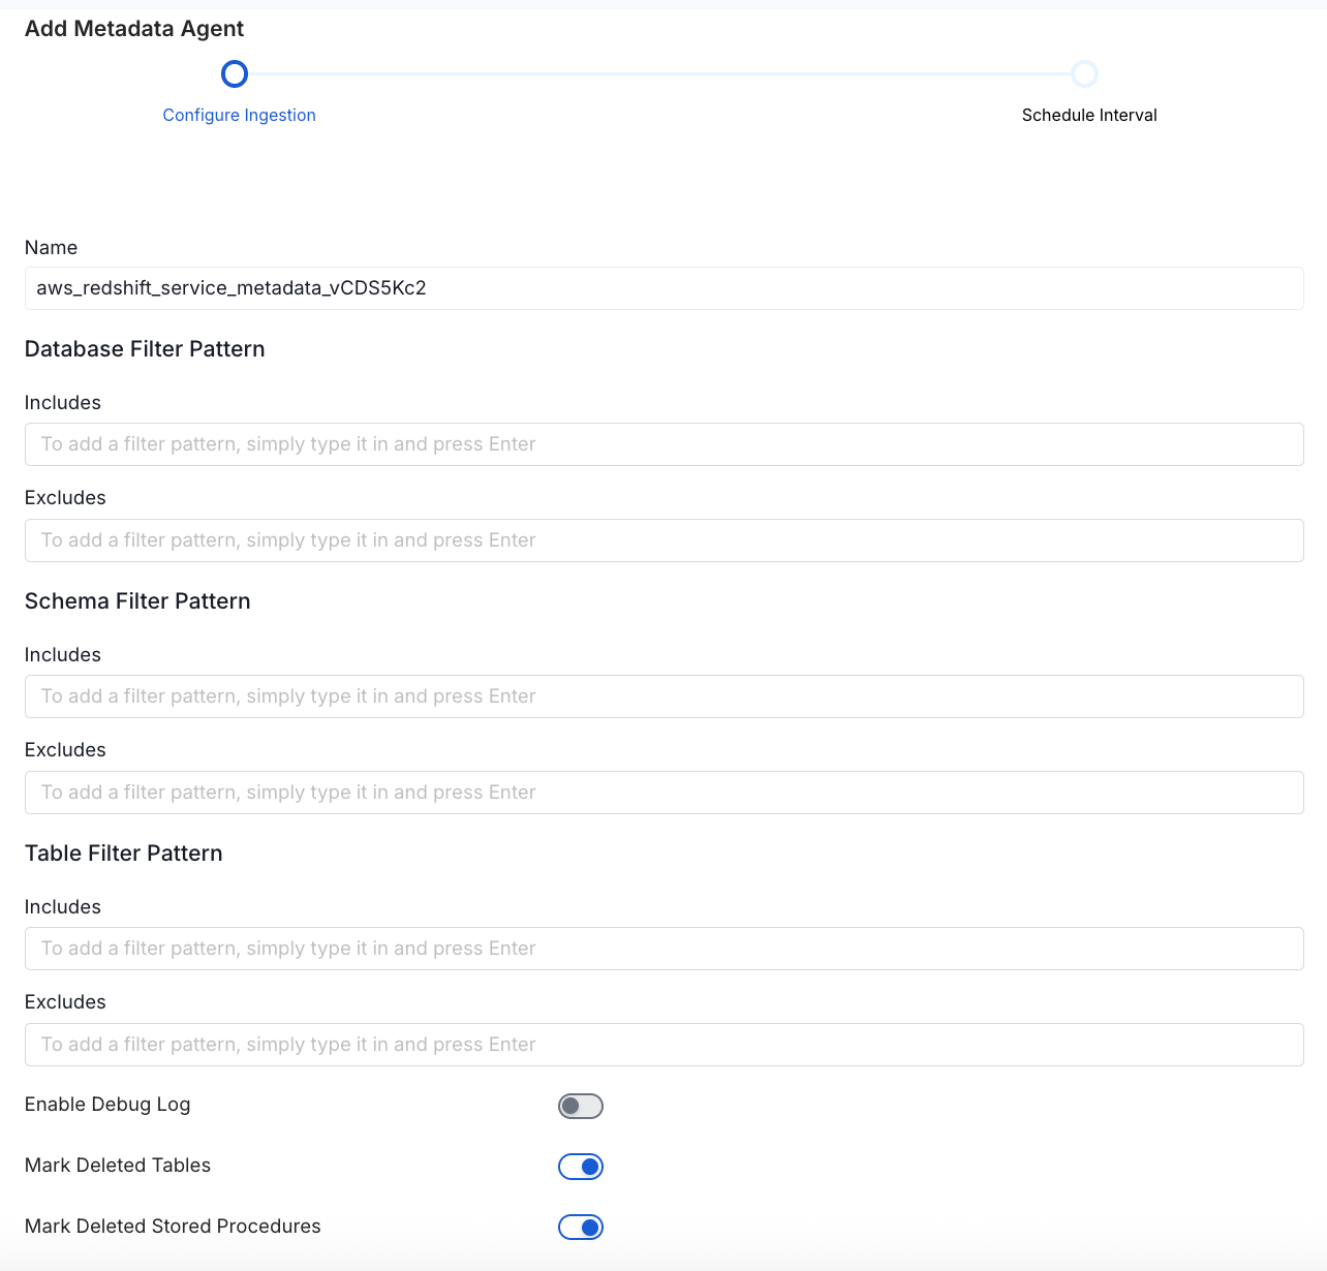
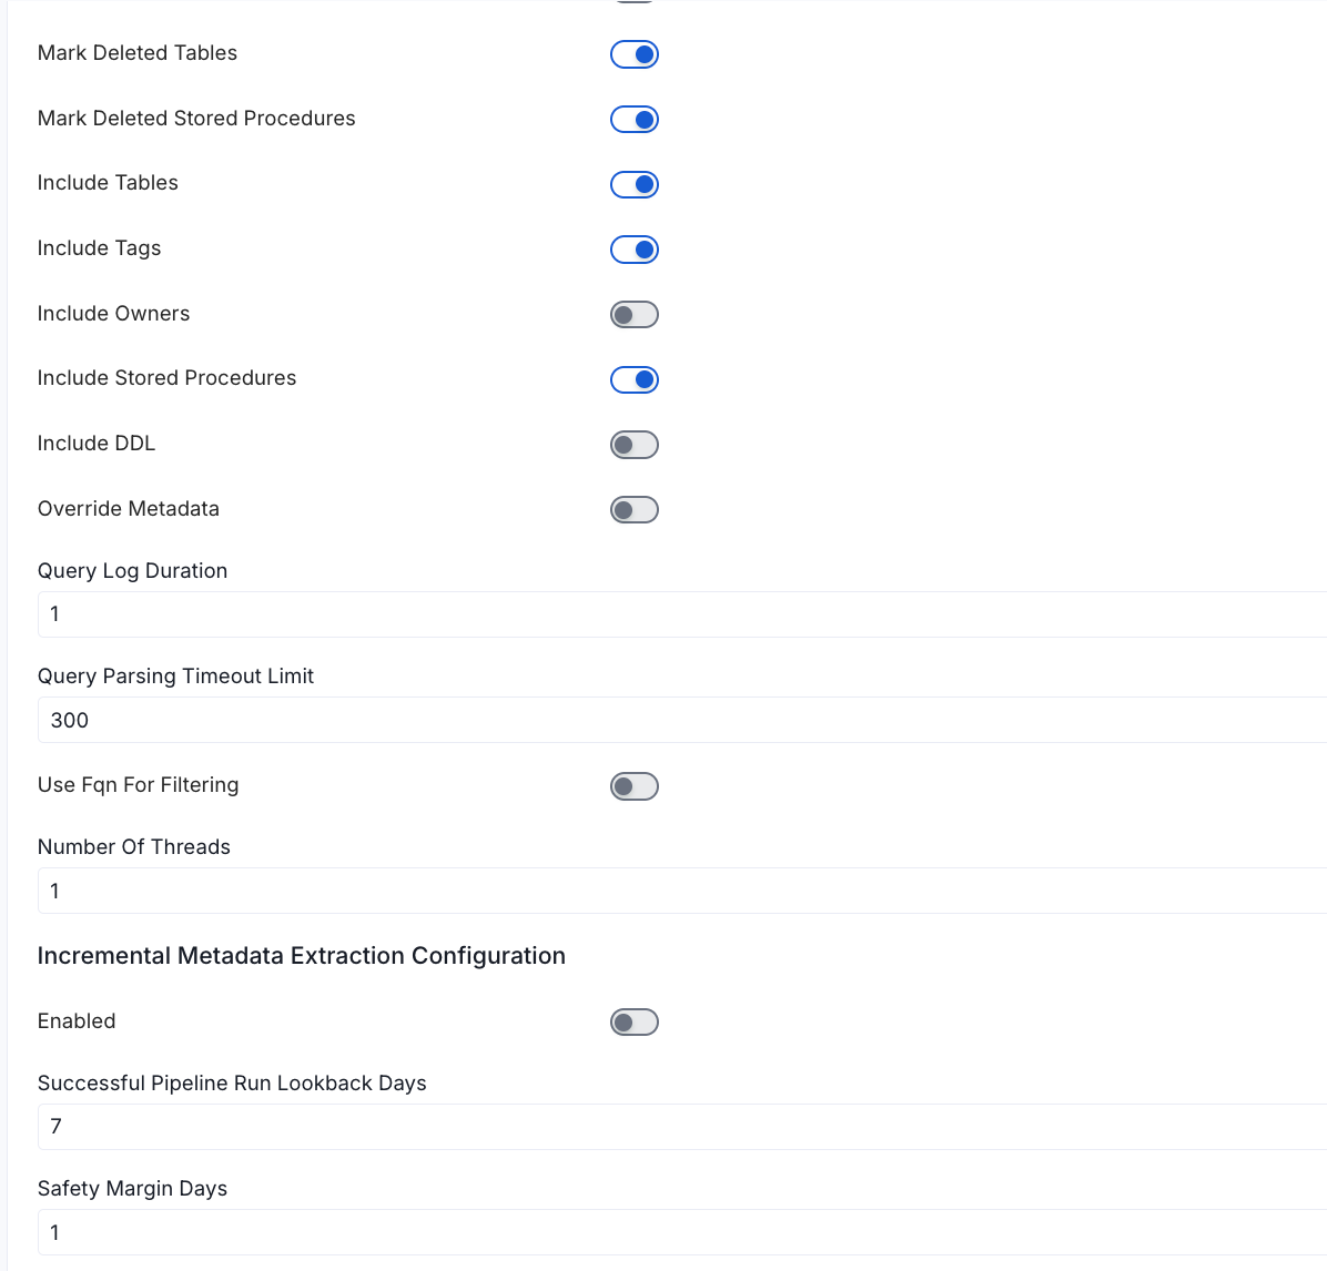
Metadata Ingestion Options
- Name: This field is the name of the ingestion pipeline. Customize it, or use the generated name.
- Directory Filter Pattern (Optional): Use directory filter patterns to control whether or not to include a directory as part of metadata ingestion.
- Include: Explicitly include directories by adding a list of comma-separated regular expressions to the Include field. OpenMetadata will include all directories with names matching one or more of the supplied regular expressions. All other directories will be excluded.
- Exclude: Explicitly exclude directories by adding a list of comma-separated regular expressions to the Exclude field. OpenMetadata will exclude all directories with names matching one or more of the supplied regular expressions. All other directories will be included.
- File Filter Pattern (Optional): Use file filter patterns to control whether or not to include a file as part of metadata ingestion.
- Include: Explicitly include files by adding a list of comma-separated regular expressions to the Include field. OpenMetadata will include all files with names matching one or more of the supplied regular expressions. All other files will be excluded.
- Exclude: Explicitly exclude files by adding a list of comma-separated regular expressions to the Exclude field. OpenMetadata will exclude all files with names matching one or more of the supplied regular expressions. All other files will be included.
- Spreadsheet Filter Pattern (Optional): Use spreadsheet filter patterns to control whether or not to include a spreadsheet as part of metadata ingestion. Only applies to connectors that support spreadsheet-type sources.
- Include: Explicitly include spreadsheets by adding a list of comma-separated regular expressions to the Include field. OpenMetadata will include all spreadsheets with names matching one or more of the supplied regular expressions. All other spreadsheets will be excluded.
- Exclude: Explicitly exclude spreadsheets by adding a list of comma-separated regular expressions to the Exclude field. OpenMetadata will exclude all spreadsheets with names matching one or more of the supplied regular expressions. All other spreadsheets will be included.
- Worksheet Filter Pattern (Optional): Use worksheet filter patterns to control whether or not to include a worksheet as part of metadata ingestion. Only applies to connectors that support worksheet-type sources.
- Include: Explicitly include worksheets by adding a list of comma-separated regular expressions to the Include field. OpenMetadata will include all worksheets with names matching one or more of the supplied regular expressions. All other worksheets will be excluded.
- Exclude: Explicitly exclude worksheets by adding a list of comma-separated regular expressions to the Exclude field. OpenMetadata will exclude all worksheets with names matching one or more of the supplied regular expressions. All other worksheets will be included.
- includeDirectories (toggle): Optional configuration to turn off fetching metadata for directories.
- includeFiles (toggle): Optional configuration to turn off fetching metadata for files.
- includeSpreadsheets (toggle): Optional configuration to turn off fetching metadata for spreadsheets.
- includeWorksheets (toggle): Optional configuration to turn off fetching metadata for worksheets.
- includeTags (toggle): Optional configuration to toggle the tags ingestion.
- includeOwners (toggle): Set the ‘Include Owners’ toggle to control whether to include owners to the ingested entity if the owner email matches with a user stored in the OM server as part of metadata ingestion. If the ingested entity already exists and has an owner, the owner will not be overwritten.
- Mark Deleted Directories (toggle): Optional configuration to soft delete directories in OpenMetadata if the source directories are deleted. Also, if the directory is deleted, all the associated entities like files, spreadsheets, worksheets, lineage, etc., with that directory will be deleted.
- Mark Deleted Files (toggle): Optional configuration to soft delete files in OpenMetadata if the source files are deleted. Also, if the file is deleted, all the associated entities like lineage, etc., with that file will be deleted.
- Mark Deleted Spreadsheets (toggle): Optional configuration to soft delete spreadsheets in OpenMetadata if the source spreadsheets are deleted. Also, if the spreadsheet is deleted, all the associated entities like worksheets, lineage, etc., with that spreadsheet will be deleted.
- Mark Deleted Worksheets (toggle): Optional configuration to soft delete worksheets in OpenMetadata if the source worksheets are deleted. Also, if the worksheet is deleted, all the associated entities like lineage, etc., with that worksheet will be deleted.
- Override Metadata (toggle): Set the ‘Override Metadata’ toggle to control whether to override the existing metadata in the OpenMetadata server with the metadata fetched from the source. If the toggle is set to true, the metadata fetched from the source will override the existing metadata in the OpenMetadata server. If the toggle is set to false, the metadata fetched from the source will not override the existing metadata in the OpenMetadata server. This is applicable for fields like description, tags, owner and displayName.
- useFqnForFiltering (toggle): Regex will be applied on fully qualified name (e.g service_name.directory_name.file_name) instead of raw name (e.g. file_name).
- Enable Debug Log (toggle): Set the Enable Debug Log toggle to set the default log level to debug.
- Threads (Optional): Number of Threads to use in order to parallelize Drive ingestion.
Spreadsheet and Worksheet options apply only to connectors that support spreadsheet-type sources, such as Google Drive. For file-only sources such as SFTP, these options have no effect.
5
Schedule the Ingestion and Deploy
Scheduling can be set up at an hourly, daily, weekly, or manual cadence. The
timezone is in UTC. Select a Start Date to schedule for ingestion. It is
optional to add an End Date.Review your configuration settings. If they match what you intended,
click Deploy to create the service and schedule metadata ingestion.If something doesn’t look right, click the Back button to return to the
appropriate step and change the settings as needed.After configuring the workflow, you can click on Deploy to create the
pipeline.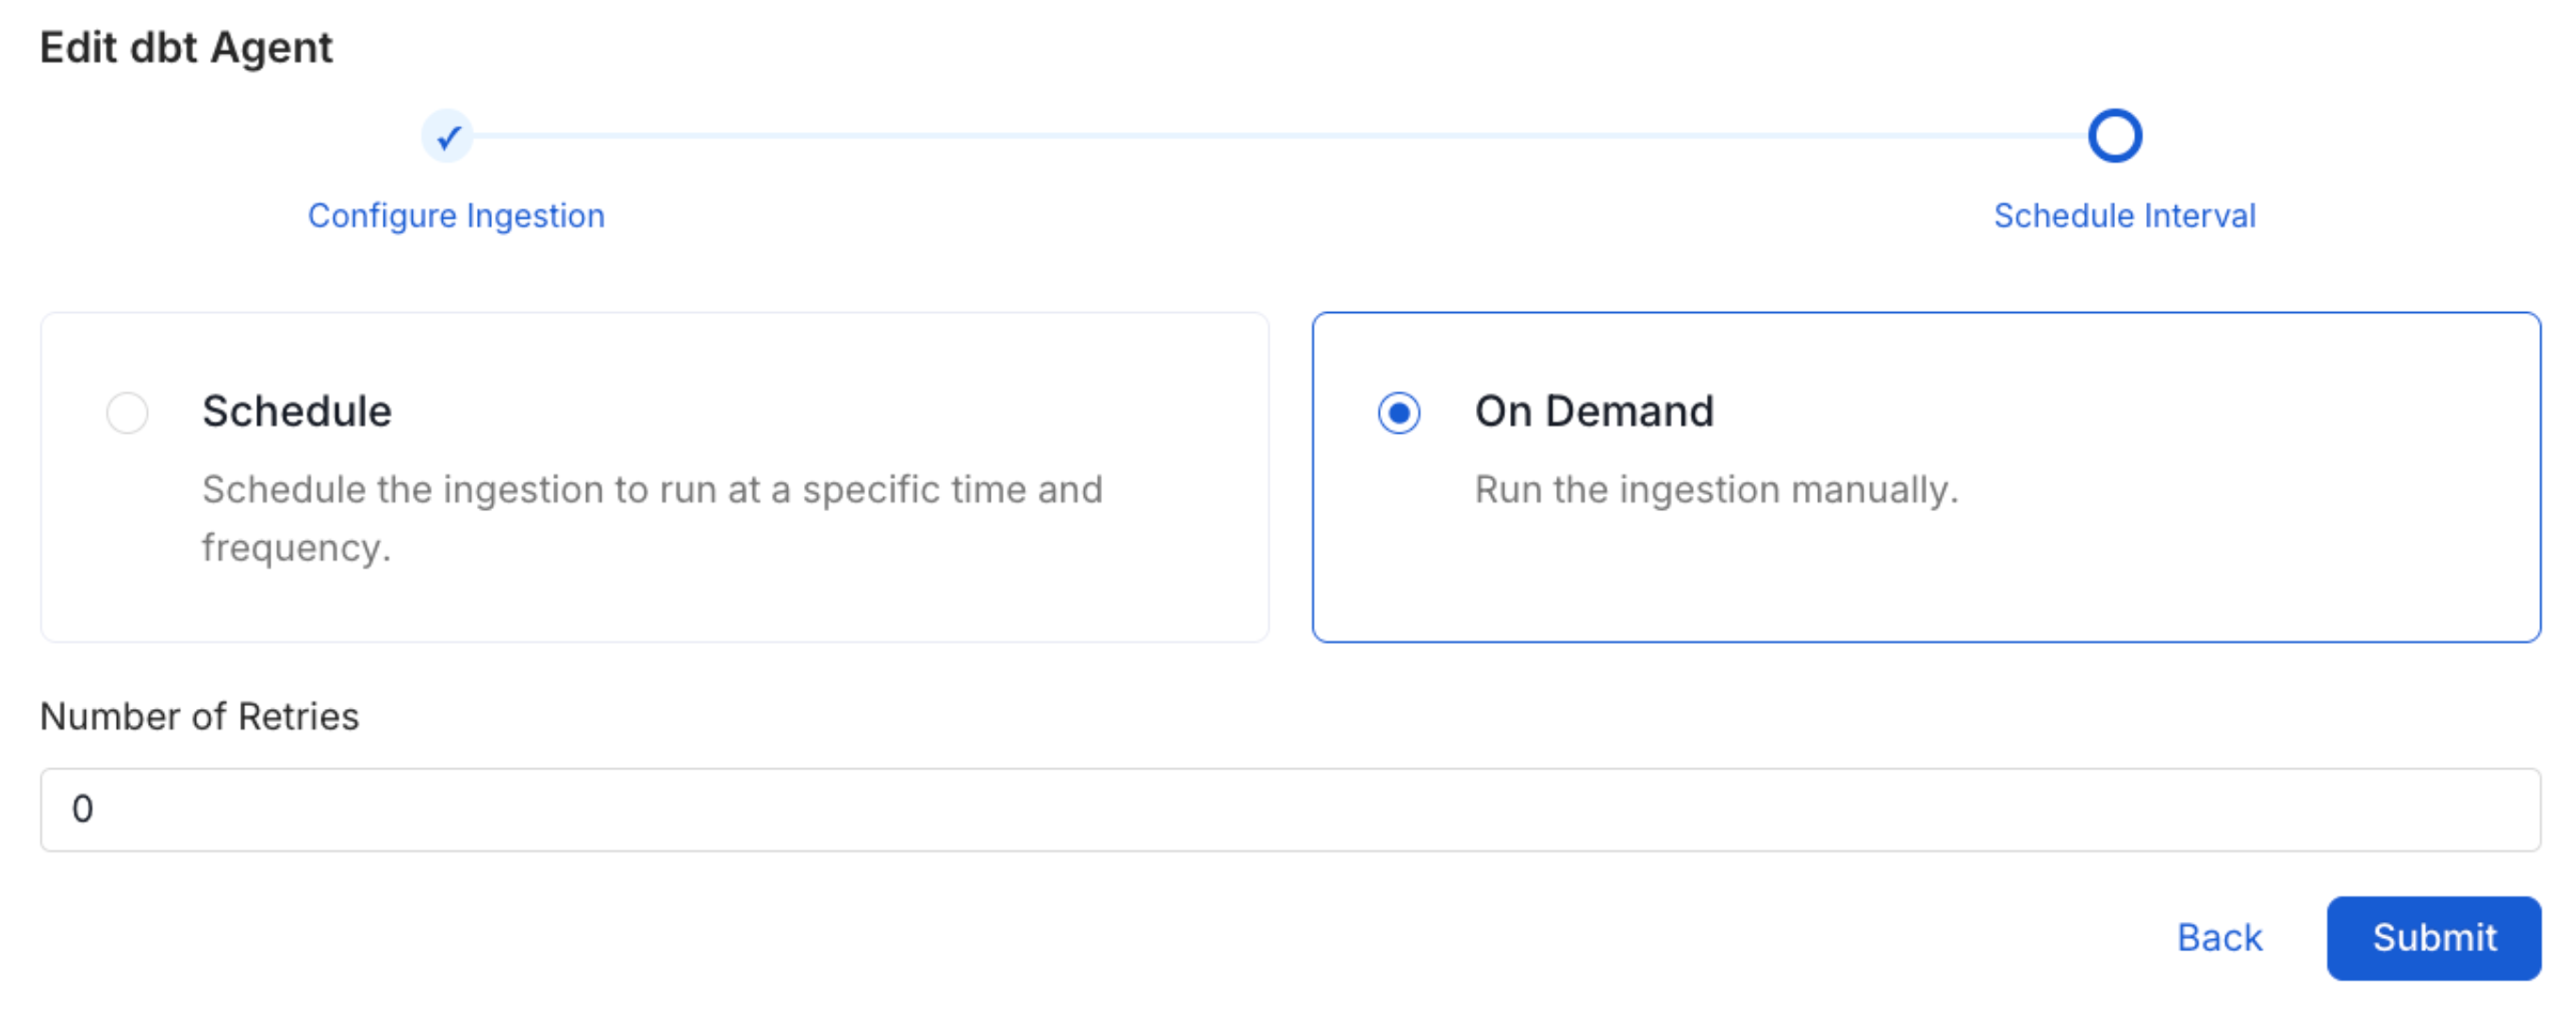
6
View the Ingestion Pipeline
Once the workflow has been successfully deployed, you can view the
Ingestion Pipeline running from the Service Page.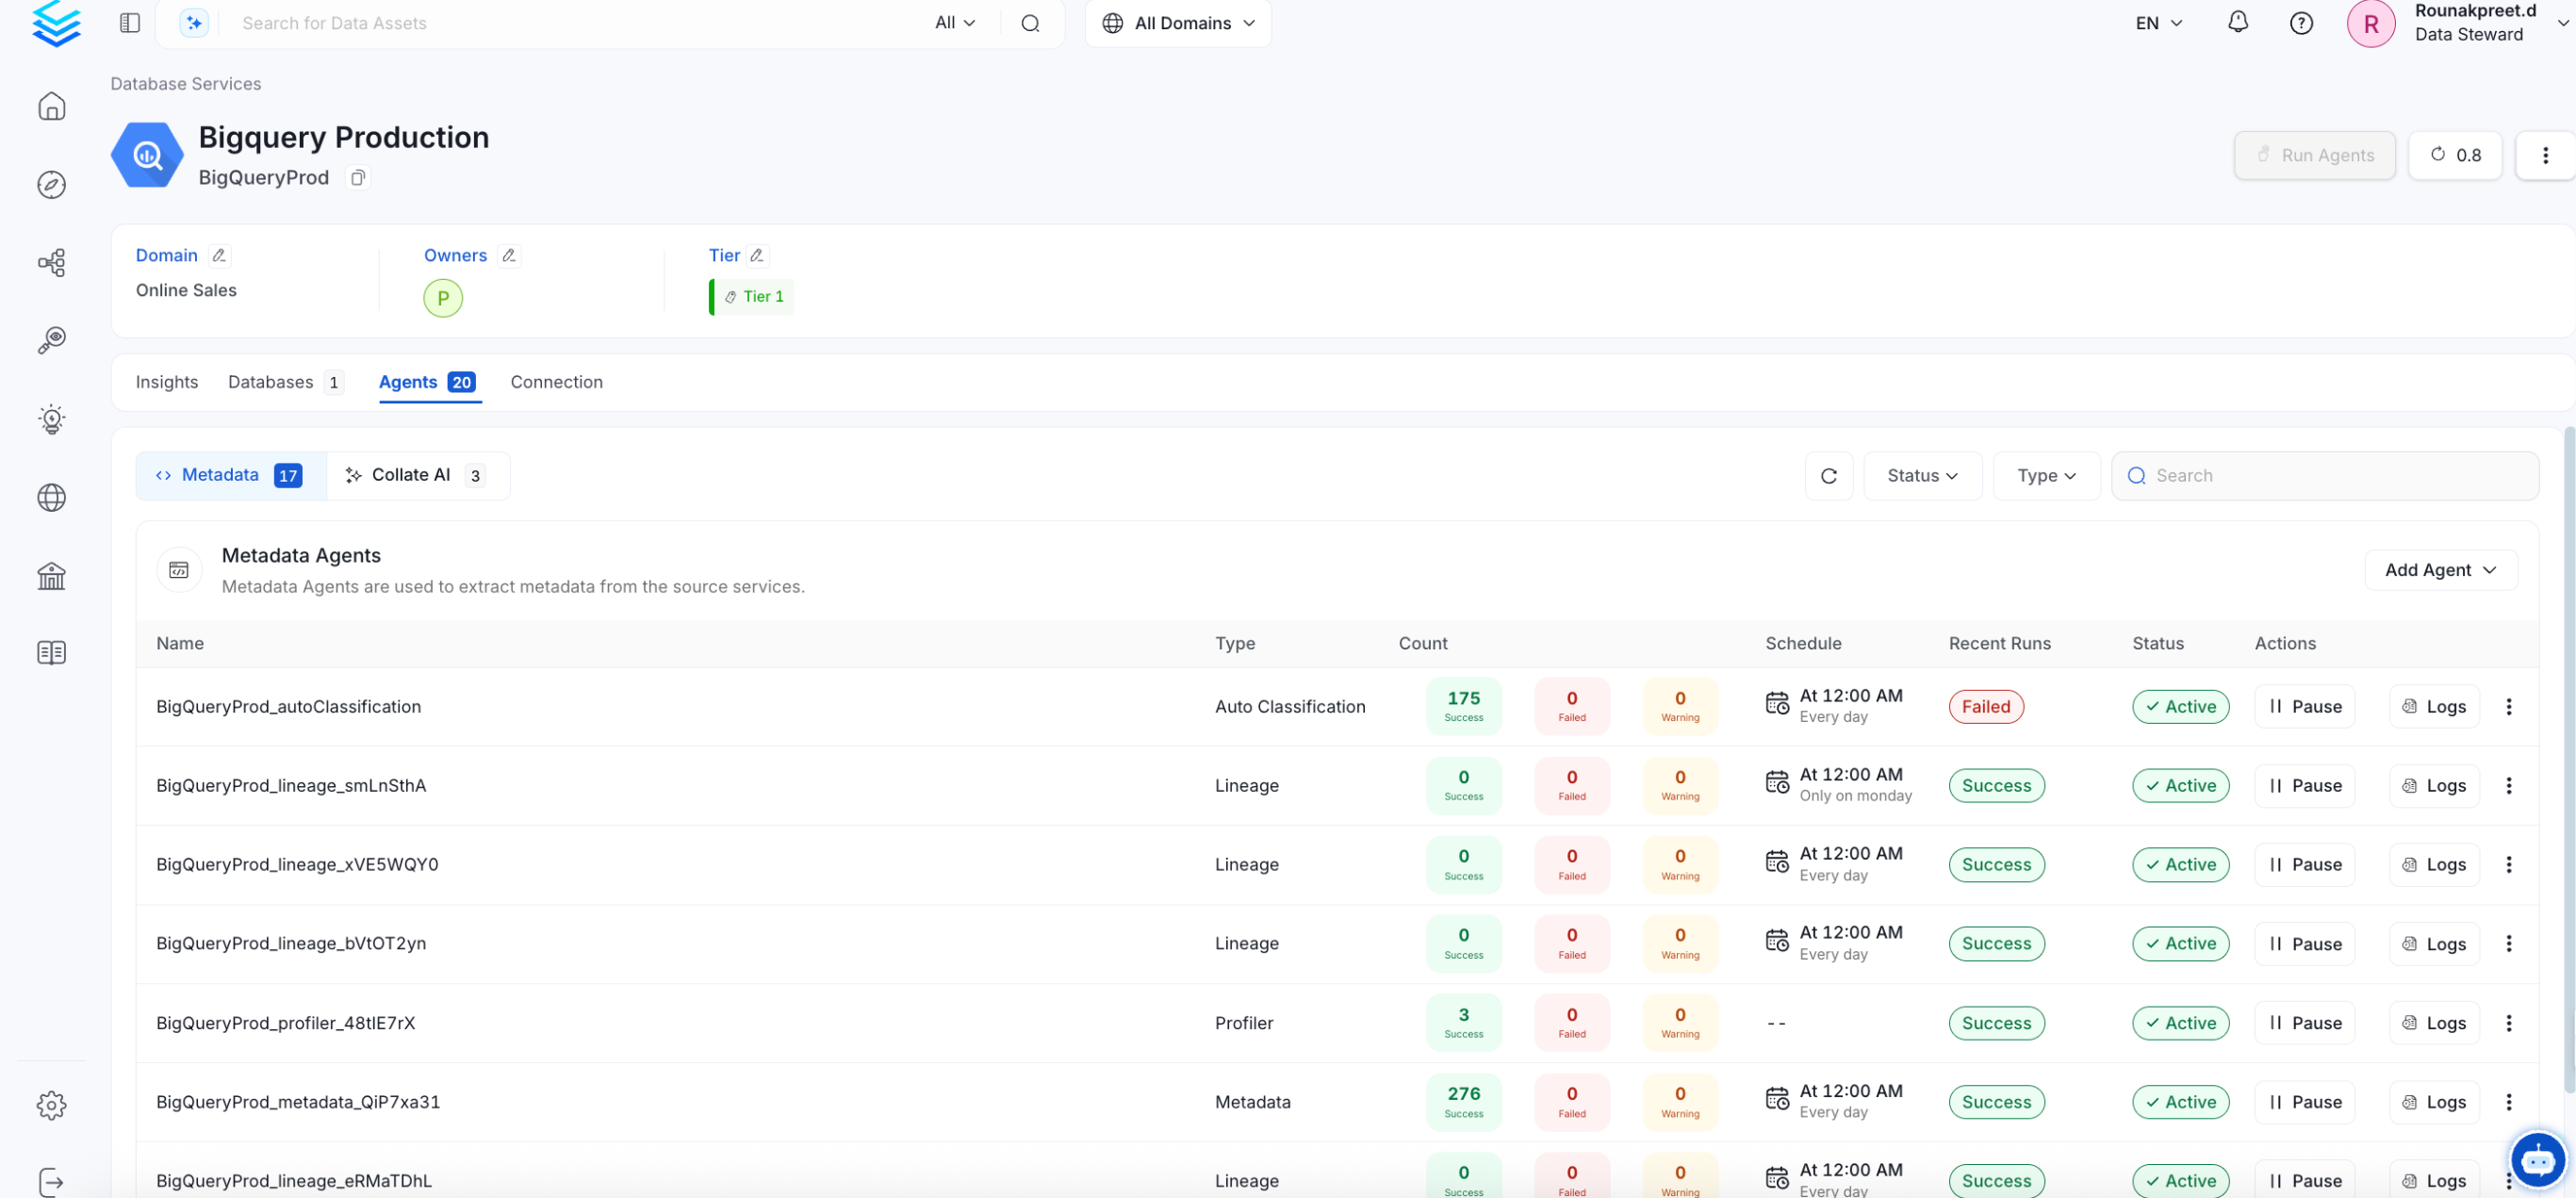
Troubleshooting
Google Drive Troubleshooting
Learn more about how to troubleshoot common Google Drive connector issues and resolve configuration or ingestion errors.
Related
Usage Workflow
Learn more about how to configure the Usage Workflow to ingest Query information from the UI.
Lineage Workflow
Learn more about how to configure the Lineage from the UI.
Profiler Workflow
Learn more about how to configure the Data Profiler from the UI.
Data Quality Workflow
Learn more about how to configure the Data Quality tests from the UI.
dbt Integration
Learn more about how to ingest dbt models’ definitions and their lineage.