
Requirements
To extract metadata, Collate needs two elements:- Tracking URI: Address of local or remote tracking server. More information on the MLflow documentation here
- Registry URI: Address of local or remote model registry server.
ML Features
Collate builds ML Features from the input columns of each model’s signature. Columns of typestring become categorical features, and every other type becomes numerical. Inputs without a name, such as unnamed tensors, produce no ML Features.
MLflow 2.x records the signature on the run that logged the model. MLflow 3.x doesn’t, so for MLflow 3.x models, Collate reads the signature from the model’s MLmodel file in the artifact store. Collate downloads only that file, never the model weights. The ingestion therefore needs read access to the model artifacts. If your tracking server doesn’t proxy artifacts, for example because it runs with --no-serve-artifacts, give the Hybrid Runner its own credentials for the artifact store. If Collate can’t read the file, it still ingests the model without ML Features and logs a warning.
Databricks Unity Catalog
Ingesting models from Databricks Unity Catalog requires the Hybrid Runner, because the connector reads the Databricks credentials from environment variables rather than from the connection form. Use these connection values:- trackingUri:
databricks - registryUri:
databricks-uc
DATABRICKS_HOST: Your Databricks workspace URL, for examplehttps://<workspace>.cloud.databricks.comDATABRICKS_TOKEN: A personal access token for a user or service principal that can access the registered models
config.ingestionPods.extraEnvs. Helm saves those values in the release and writes them in plain text into the runner’s Deployment. The runner then copies them into every ingestion pod it creates.
These steps update a Hybrid Runner that’s already installed. If you haven’t installed one yet, follow Set Up Hybrid Ingestion Runner first, then return to these steps.
-
Create the Secret in the namespace where the ingestion pods run, which is the chart’s namespace by default:
-
In the runner’s
values.yaml, add both variables to the ingestion pods’ container config. The token entry references the Secret, so the token itself never appears in your values: -
If the runner uses the Simple Kubernetes executor, which is the default when Argo Workflows isn’t installed, also add the following to
values.yaml. The chart applies the container config automatically only for the Argo Workflows executor: -
Apply the updated values to the runner with the Helm CLI, using your own release name and namespace:
<catalog>.<schema>.<model>, and filter patterns match against the full name. Databricks also lists its built-in foundation models under system.ai. These models aren’t backed by runs in your workspace, so Collate can’t ingest them and reports each one as failed. To skip them, add an Always exclude rule to the ML Model section that matches regex ^system\.ai\..*.
Metadata Ingestion
To ingest metadata from MLflow, you need to create a service connection. The service connects MLflow with Collate. Once you create a service, Collate automatically starts ingesting metadata.Step 1: Add New Service
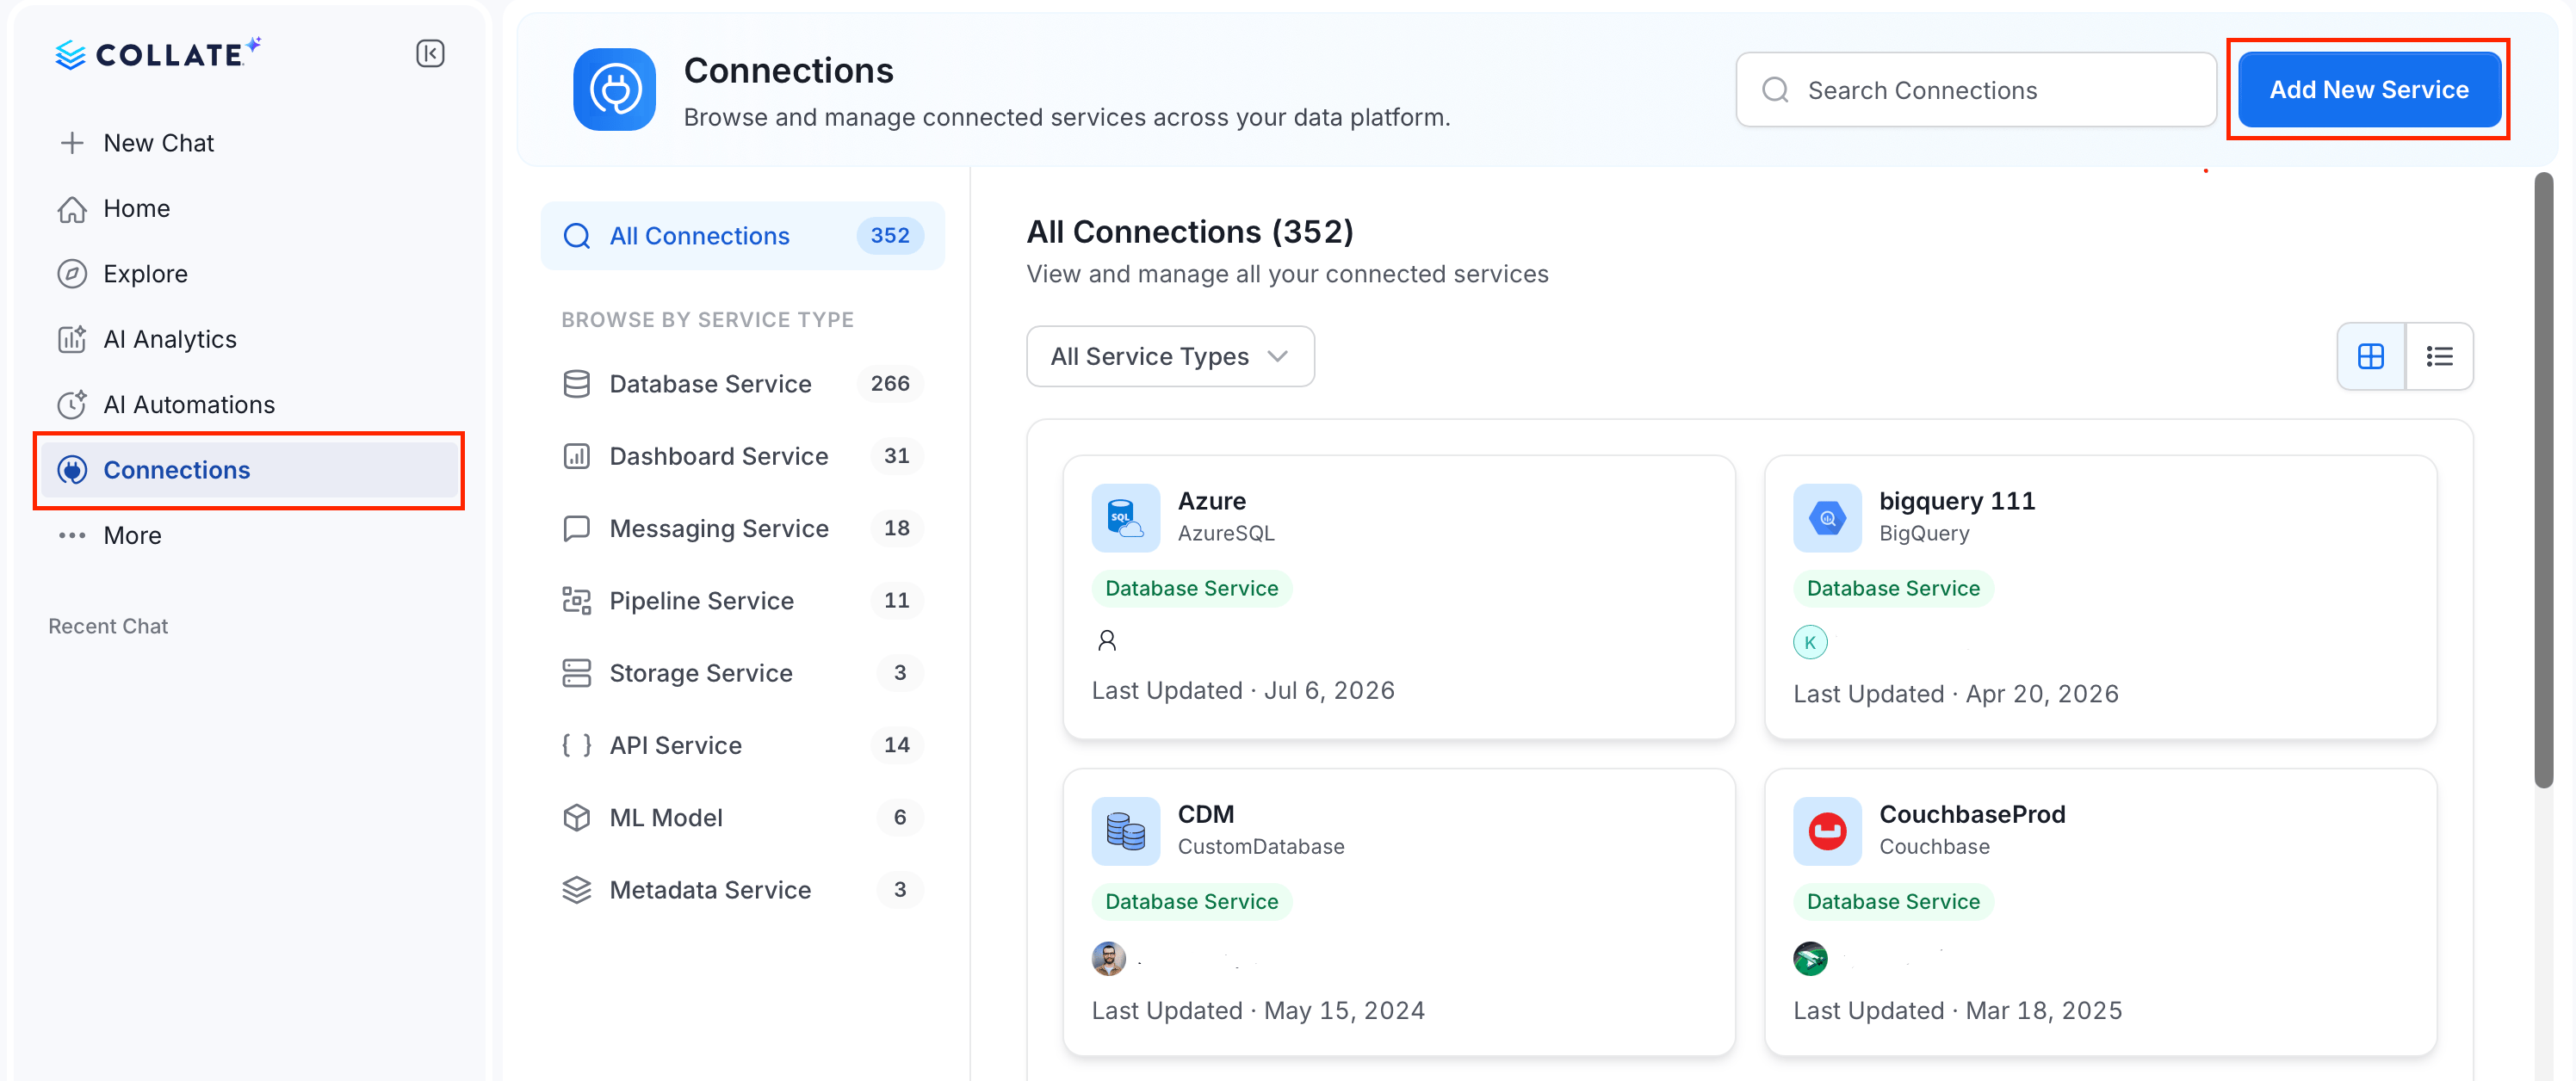
- In the left navigation, click Connections.
- On the Connections page, click Add New Service.
Step 2: Select a Service and Connector
From the service type dropdown, select Mlmodel Services, then click the MLflow connector tile.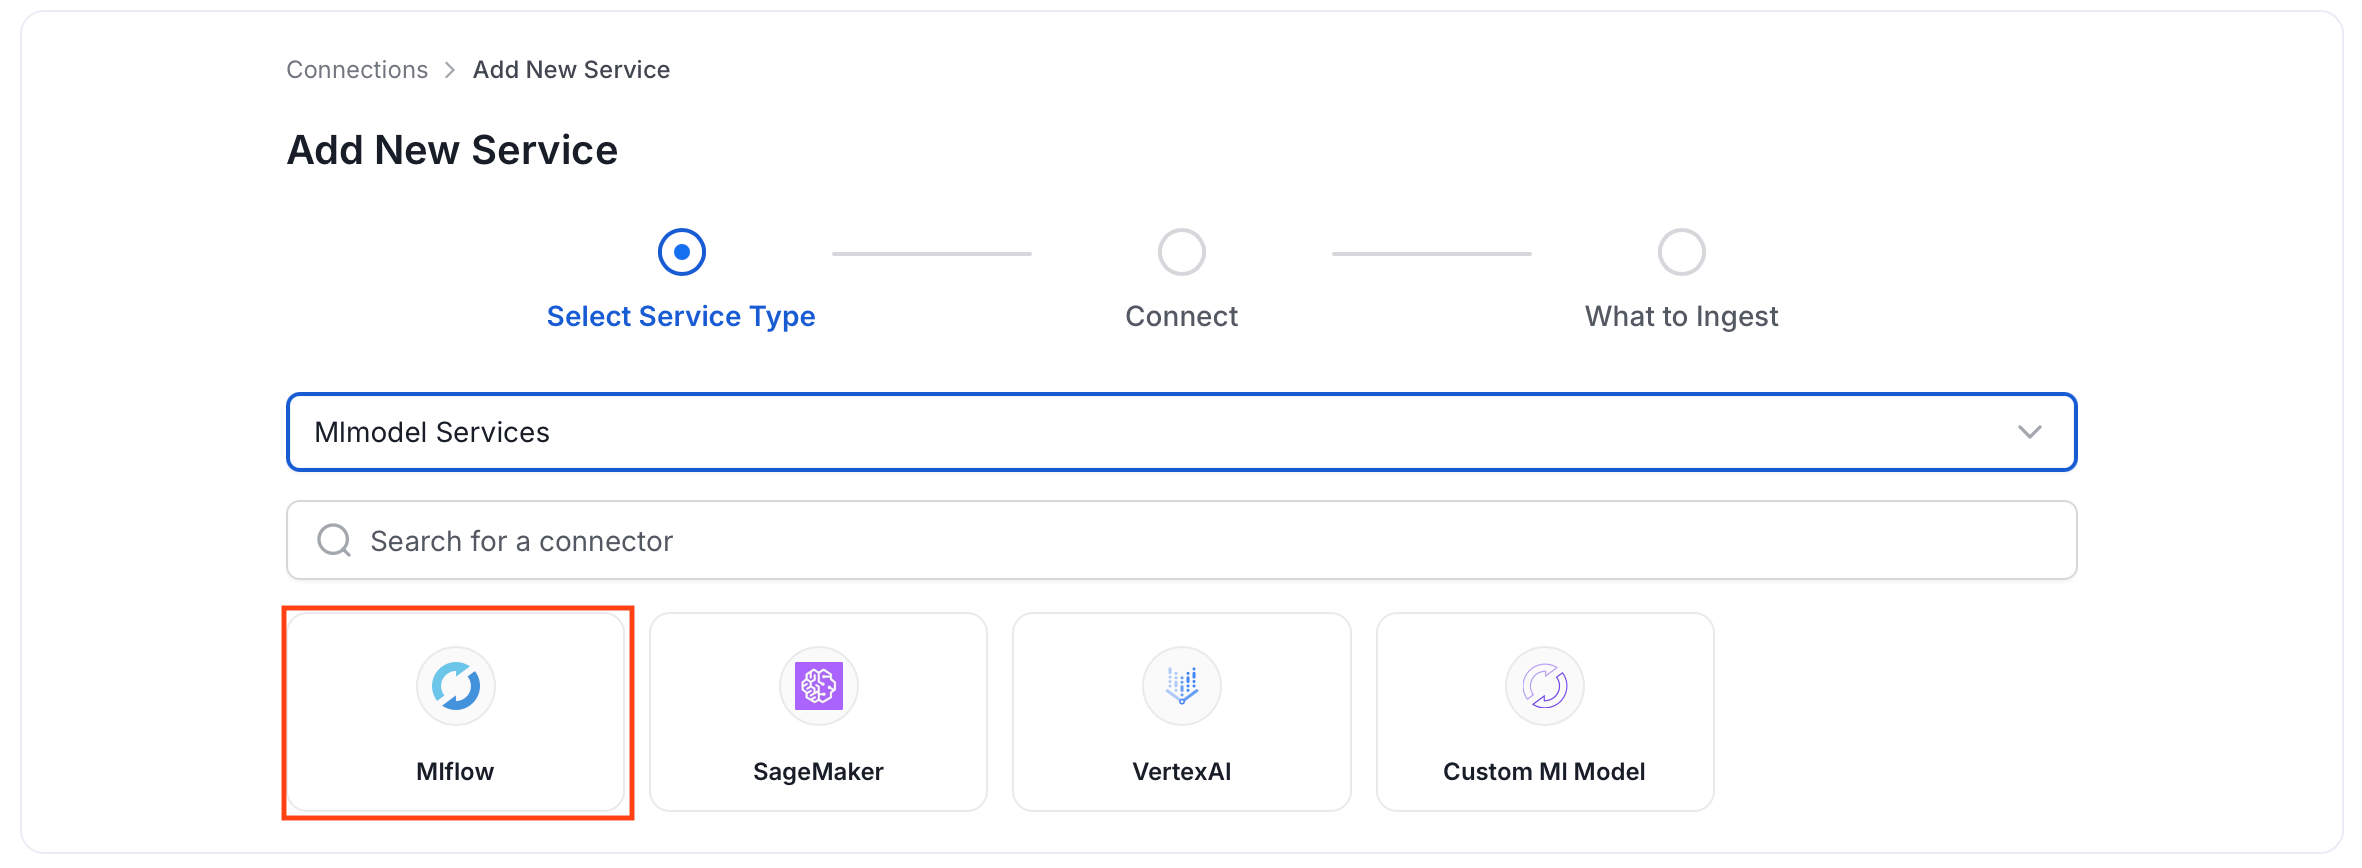
Step 3: Add Service Name and Description
- Enter a unique, descriptive Service Name. Collate identifies services by their service name. Enter a name that distinguishes this deployment from other MLflow services you are ingesting metadata from.
- Optional: Enter a Description for the service.
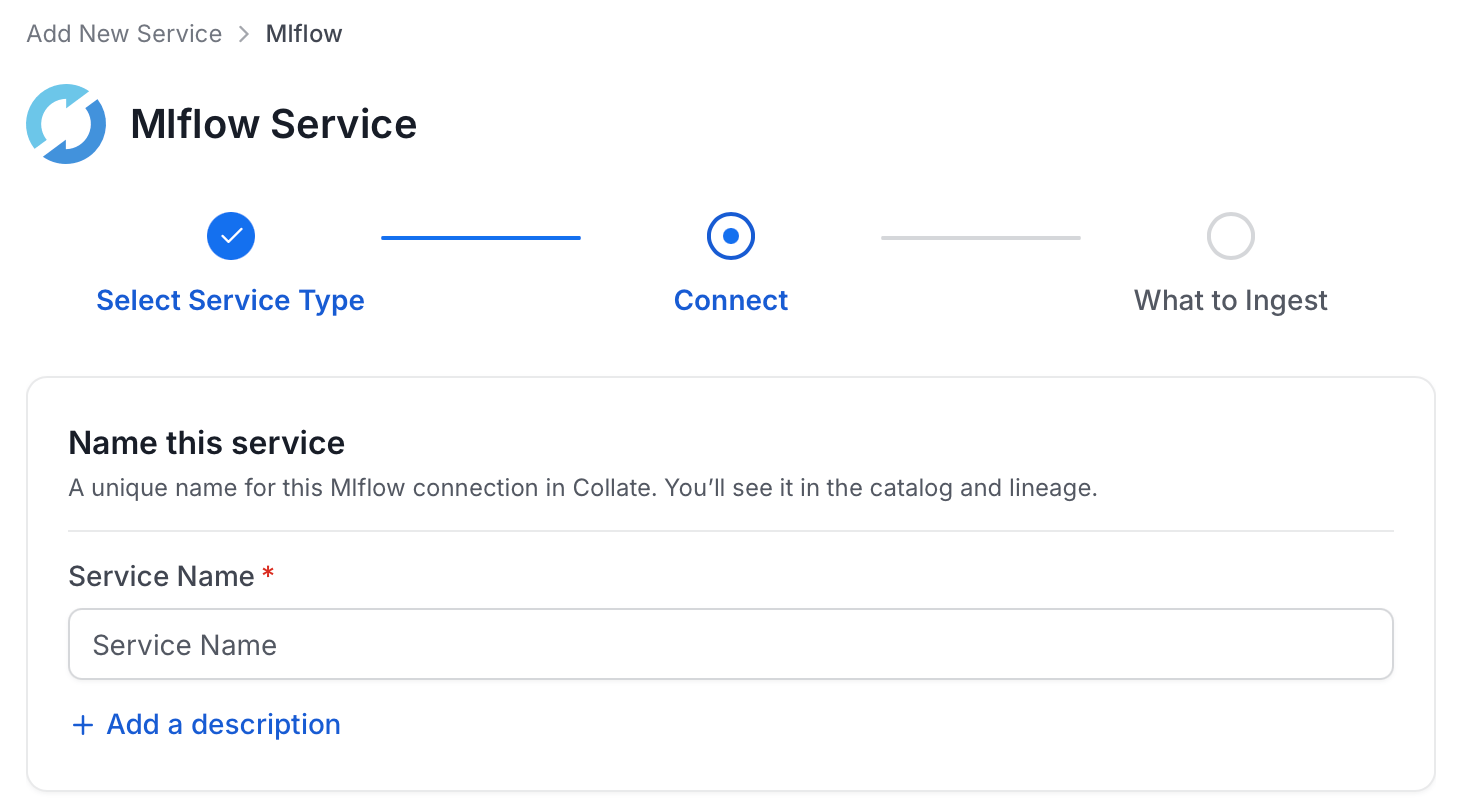
Note: The service name cannot be changed after it is set.
Step 4: Configure Connection Options
Specify where ingestion runs, provide your source credentials, and verify the connection.Select Ingestion Runner
Select an Ingestion Runner: the runner where the ingestion pipeline will execute.
Enter Connection Details
Enter the connection details for MLflow. The right-hand panel in the UI displays inline help for each field.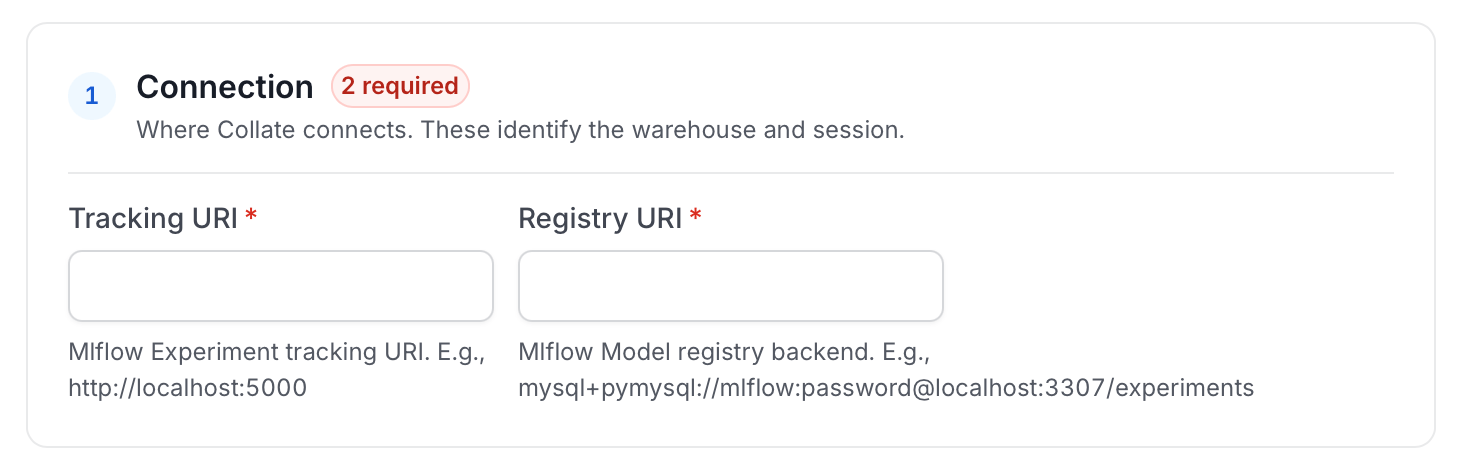
- trackingUri: Mlflow Experiment tracking URI. E.g.,
http://localhost:5000 - registryUri: Mlflow Model registry backend. E.g., mysql+pymysql://mlflow:password@localhost:3307/experiments
databricks as the trackingUri and databricks-uc as the registryUri. For the credentials this needs, see Databricks Unity Catalog.
Test Connection
Once the credentials have been added, click on Test Connection and Save the changes.
Step 5: Configure Ingestion Options
In the What to Ingest step, use filter patterns to control which assets Collate ingests from your ML model service. Filter patterns use regular expressions applied to model names.How Filter Patterns Work
- Include: Add one or more comma-separated regular expressions. Collate ingests only assets whose names match at least one expression. Leave blank to include all assets.
- Exclude: Add one or more comma-separated regular expressions. Collate skips any asset whose name matches an expression. Leave blank to exclude nothing.
- contains: matches any name containing the value. For example,
salesmatchesmy_sales_dataandsales_2024. - starts with: matches names beginning with the value. For example,
prod_matchesprod_dbandprod_schema. - ends with: matches names ending with the value. For example,
_rawmatchesevents_rawandlogs_raw. - is exactly: matches the exact name only. For example,
analyticsmatches onlyanalytics. - matches regex: matches names using a regular expression. For example,
^prod_.*_v\d+$matchesprod_events_v1.
- ML Model: Controls which ML models Collate ingests from the source.
- Scan Mode: You can choose between the following scan modes:
- Scan all: Ingests every asset of that type the connector can access. This is the default.
- Only specific: Enables include rules so only assets matching at least one rule are ingested.
- Exclude system toggle: Use this toggle to automatically filter out system-reserved names defined by the connector — for example, Exclude system databases for the Databases section.
- Always exclude: Add permanent exclusion rules (shown in red). Assets matching these rules are never ingested, regardless of include rules.
- Preview: Shows a real-time summary of what will be in scope based on your current rules.
- Include rules (available only in Only specific mode): Click + Add to define a rule. Added rules appear as chips; an asset is included if it matches any rule.
Step 6: Create & Deploy
Click Create & Deploy to deploy the agent and start the first metadata ingestion run. Collate saves the service configuration and immediately begins pulling metadata from the source. To monitor ingestion progress or view the service you just added, go to Connections in the left navigation and select your service.Configure Metadata Agent and Schedule Ingestion
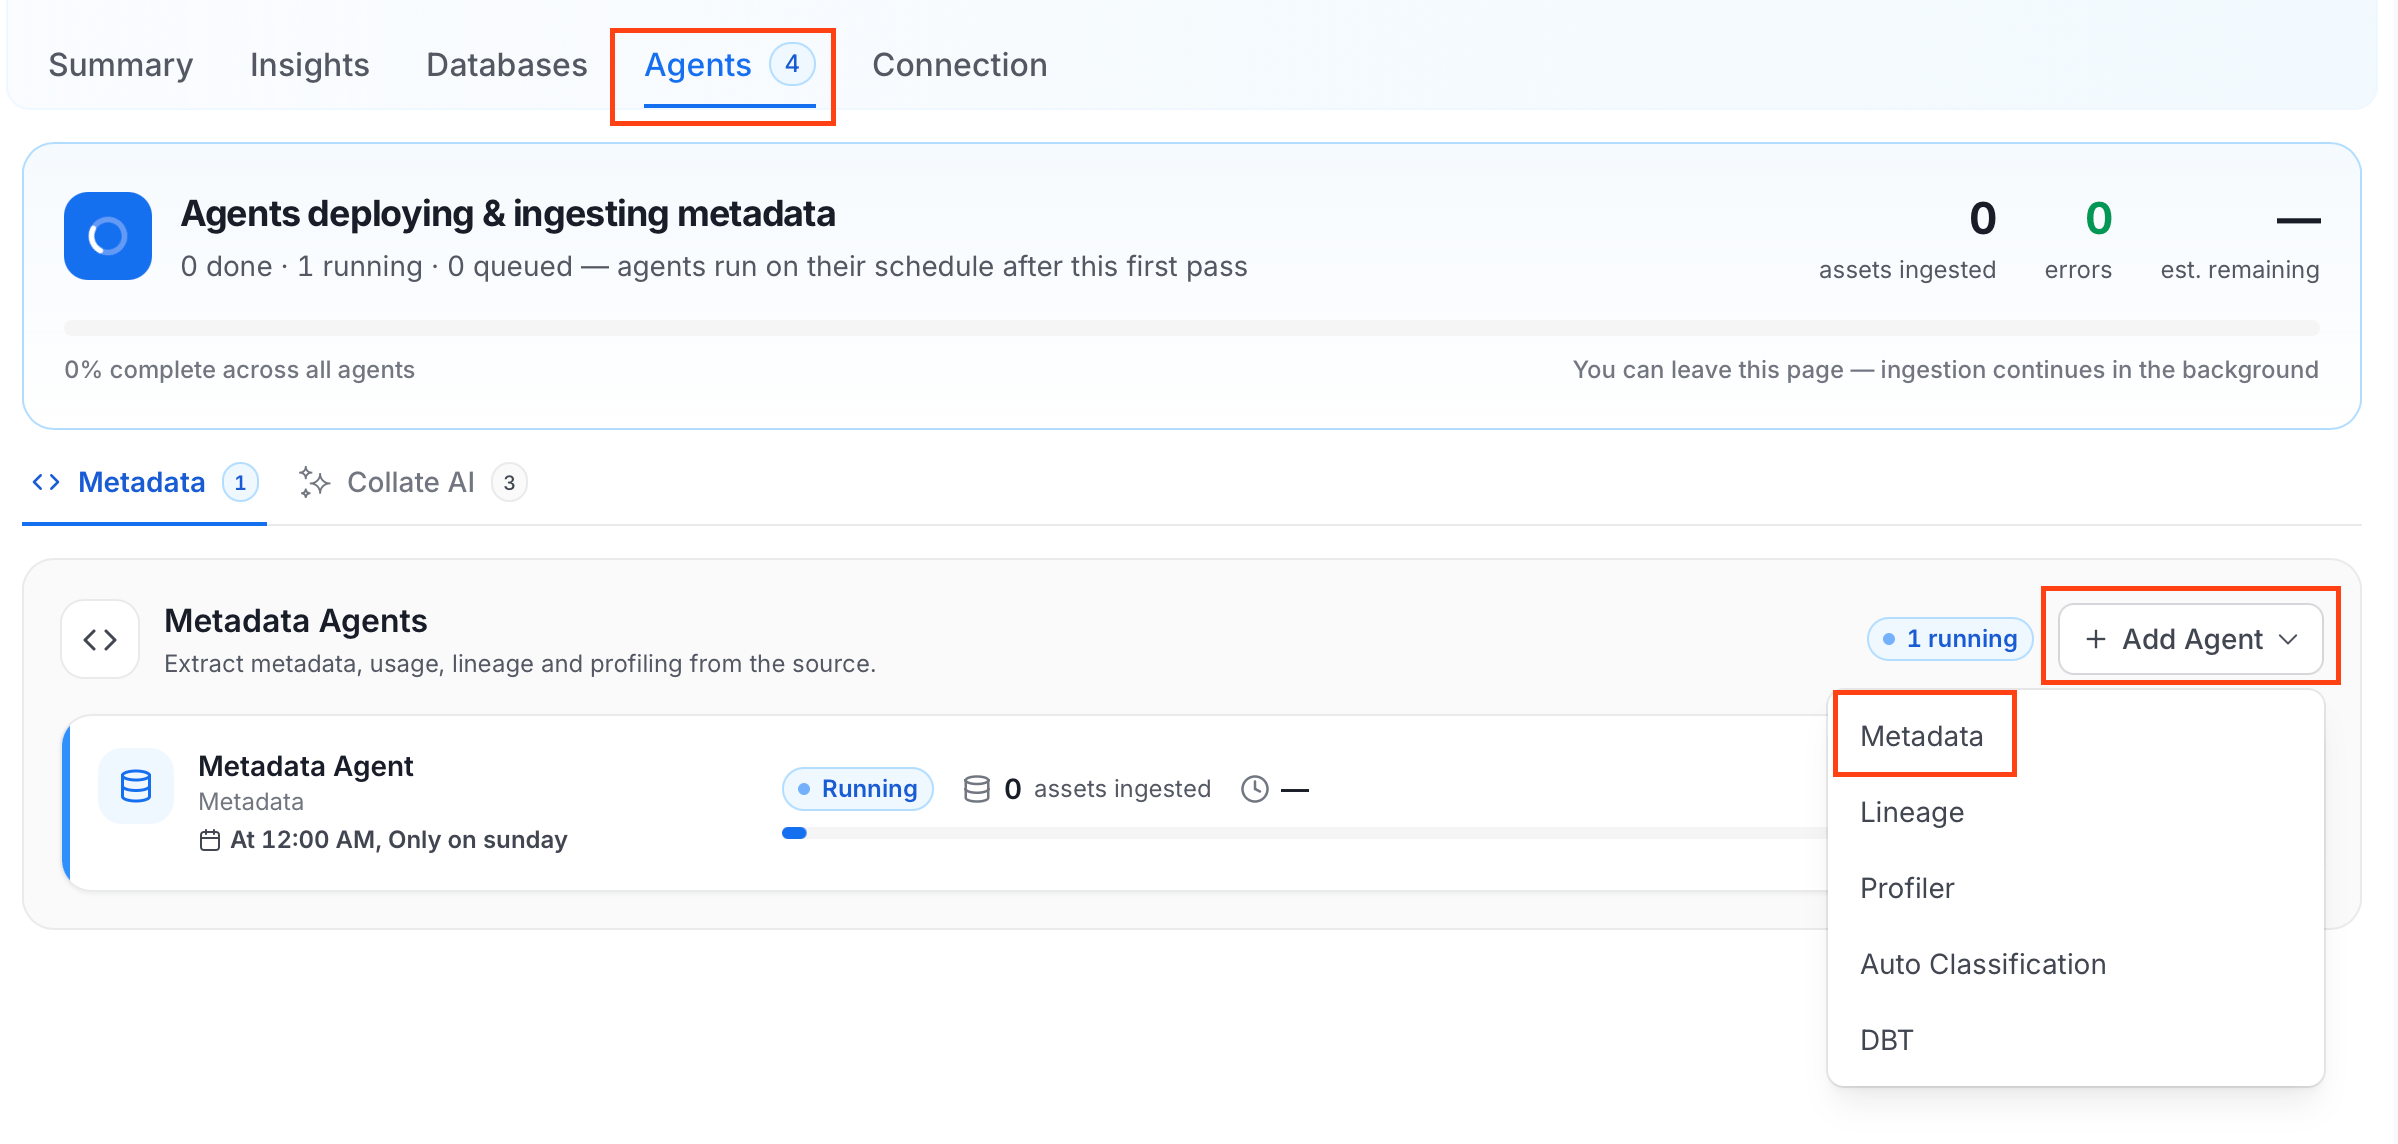
The Metadata Agent extracts ML models, features, and other structural metadata from your source and keeps your Collate catalog in sync. It powers discovery, lineage, and governance across your data assets. When you click Create & Deploy, Collate automatically deploys a Metadata Agent for this service and triggers the first ingestion run. View its status and run history from the Agents tab on the service detail page. To configure the additional Metadata Agent and schedule ingestion, follow these steps:- In the left navigation, click Connections and select your service.
- Click the Agents tab.
-
Click Add Agent and select Metadata from the dropdown.
-
On the Configure Ingestion page, do the following and click Next.
-
Name this Ingestion: Enter a unique recognizable name for this ingestion pipeline.

-
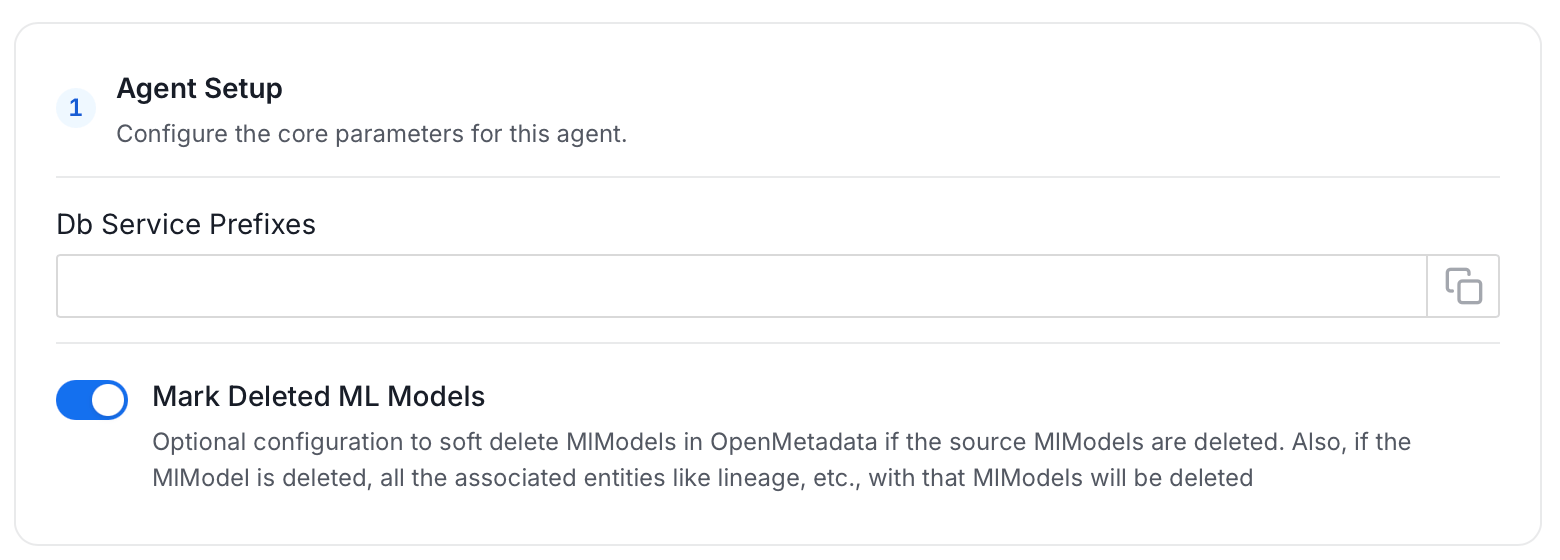
Agent Setup: Configure the core parameters for this agent. The following fields are available:
-
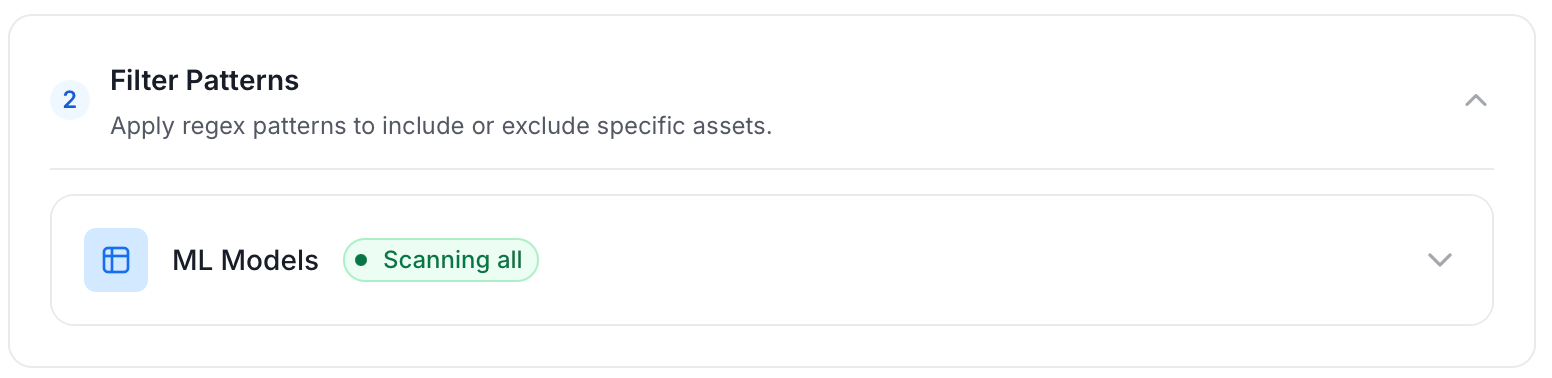
Filter Patterns: Apply include or exclude rules to scope which ML models this agent ingests. These follow the same filter options described in Step 5.
-
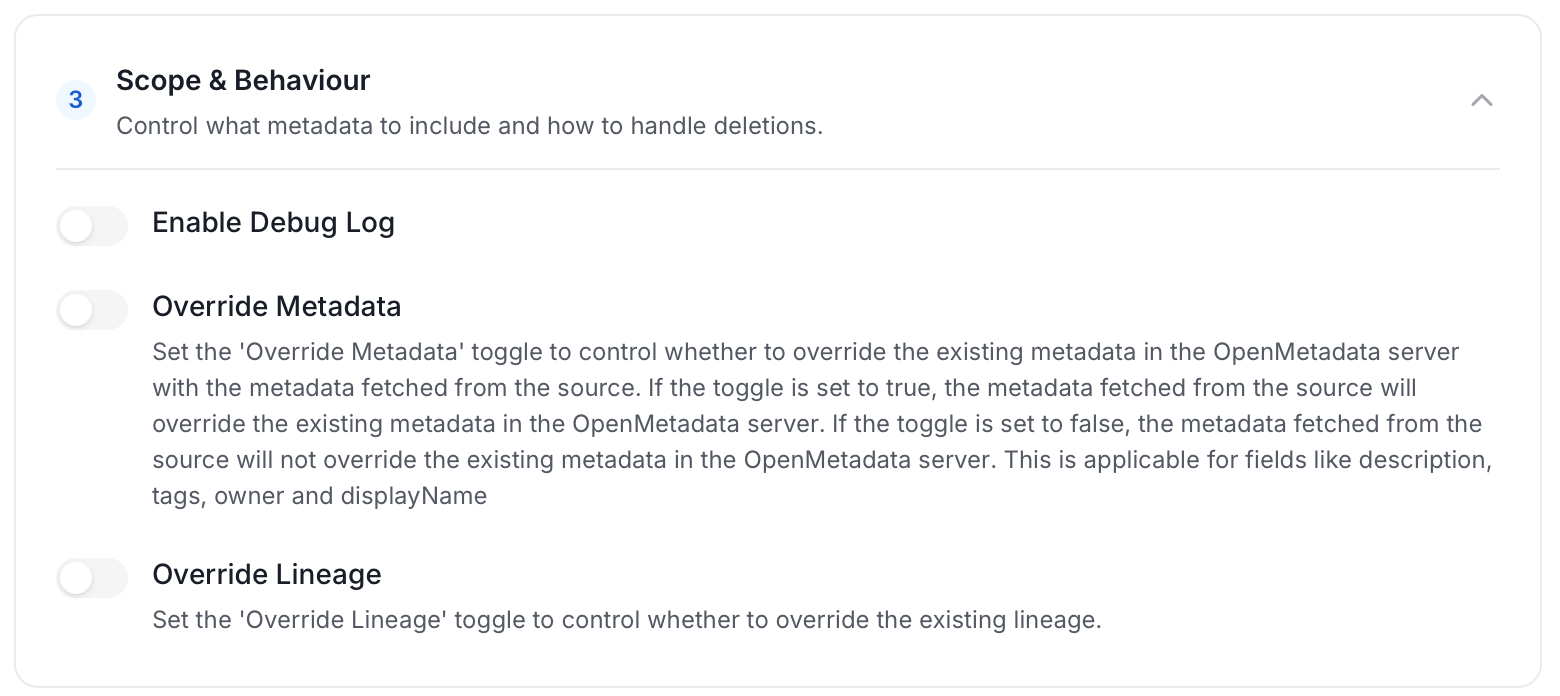
Scope & Behaviour: Control what metadata to include and how to handle deletions. Toggle each option on or off based on your needs:
-
Name this Ingestion: Enter a unique recognizable name for this ingestion pipeline.
-
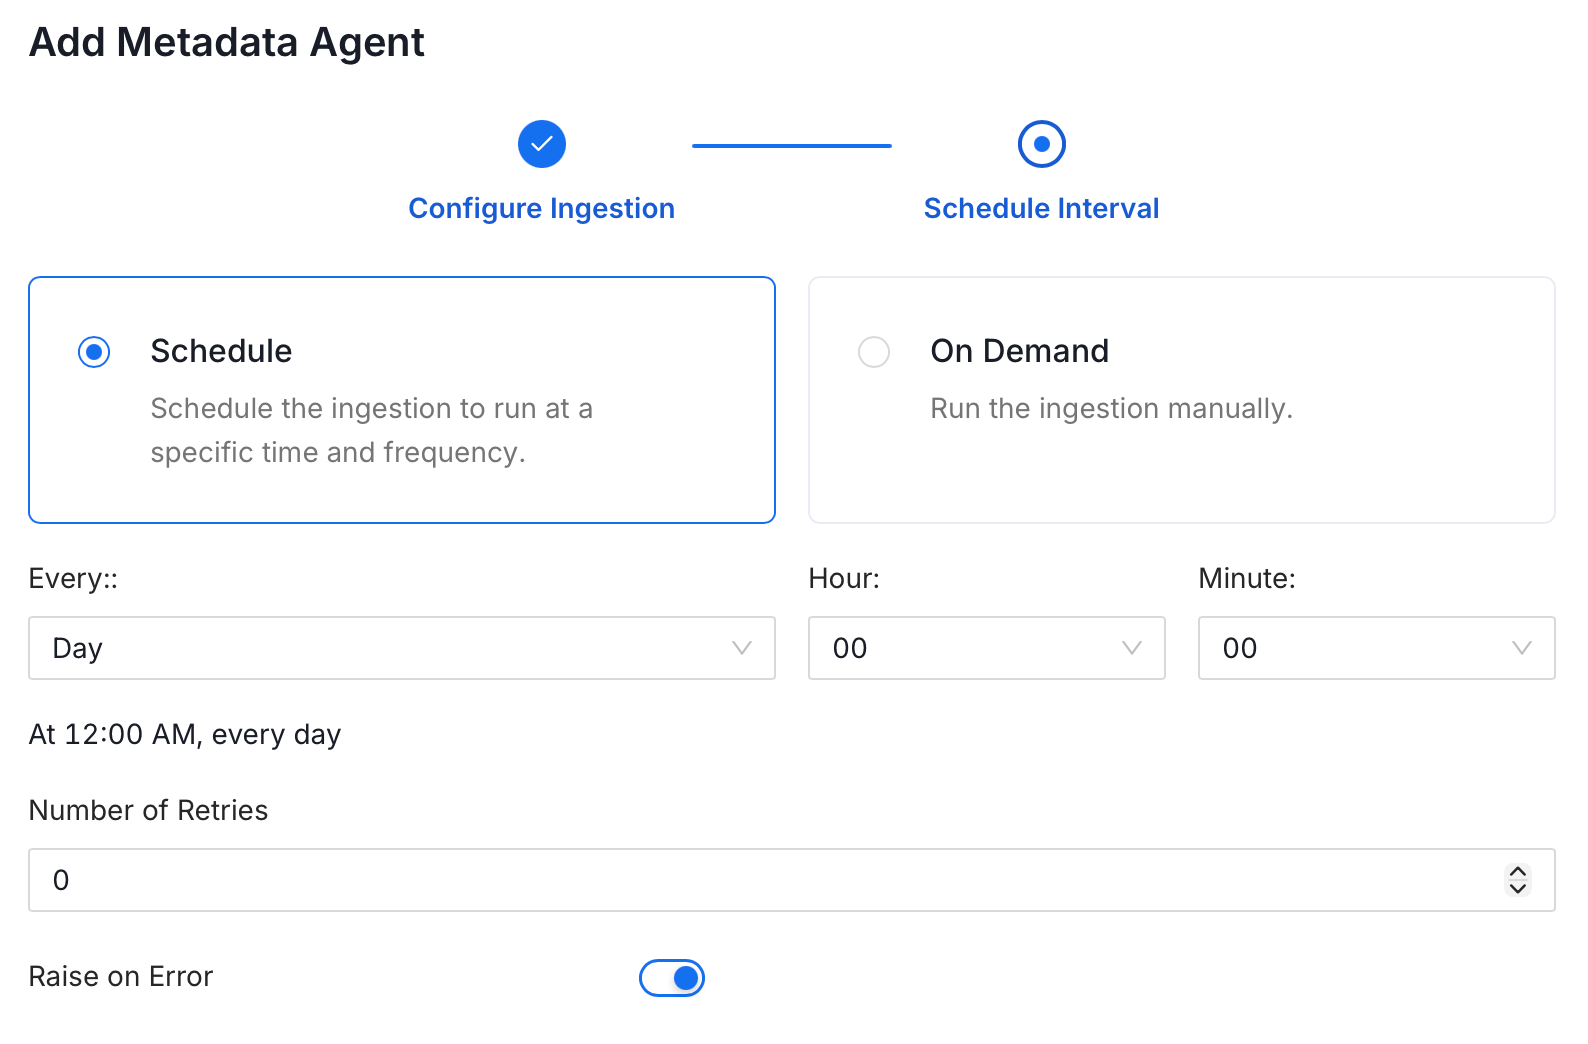
On the Schedule Interval page, set when the agent runs:
- Schedule: Choose a preset interval (Hourly, Daily, Weekly, Monthly) or enter a custom cron expression.
- On-Demand: No automatic schedule; trigger the agent manually when needed.
- Click Add to deploy the agent.
Troubleshooting
MLflow Troubleshooting
Learn more about how to troubleshoot common MLflow connector issues and resolve configuration or ingestion errors.