
Requirements
The connector communicates with the NATS JetStream API, so JetStream must be enabled on your NATS server. The connector reads metadata from the JetStream management subjects, for example$JS.API.STREAM.LIST, so the credentials you supply must be allowed to publish to and receive replies from the $JS.API.> subjects.
If you want schema ingestion, store your schemas in a JetStream KV bucket and configure the bucket with Schema KV Bucket. To read them, the credentials must also be able to access the underlying KV stream subjects.
The only mandatory connection field is NATS Servers. All authentication fields are optional. Leaving them empty connects anonymously.
Supported Authentication Types
NATS JetStream supports several ways to authenticate. Choose the one that matches your server configuration:- Anonymous: No credentials. Leave the authentication fields empty. Use this when your NATS server allows unauthenticated access.
- Username and Password: Basic authentication with a NATS user and password.
- Token: A single shared authentication token.
- NKey Seed: NKey-based authentication using the account’s seed, the private key that begins with
S.
Metadata Ingestion
To ingest metadata from NATS JetStream, you need to create a service connection. The service connects NATS JetStream with Collate. Once you create a service, Collate automatically starts ingesting metadata.Step 1: Add New Service
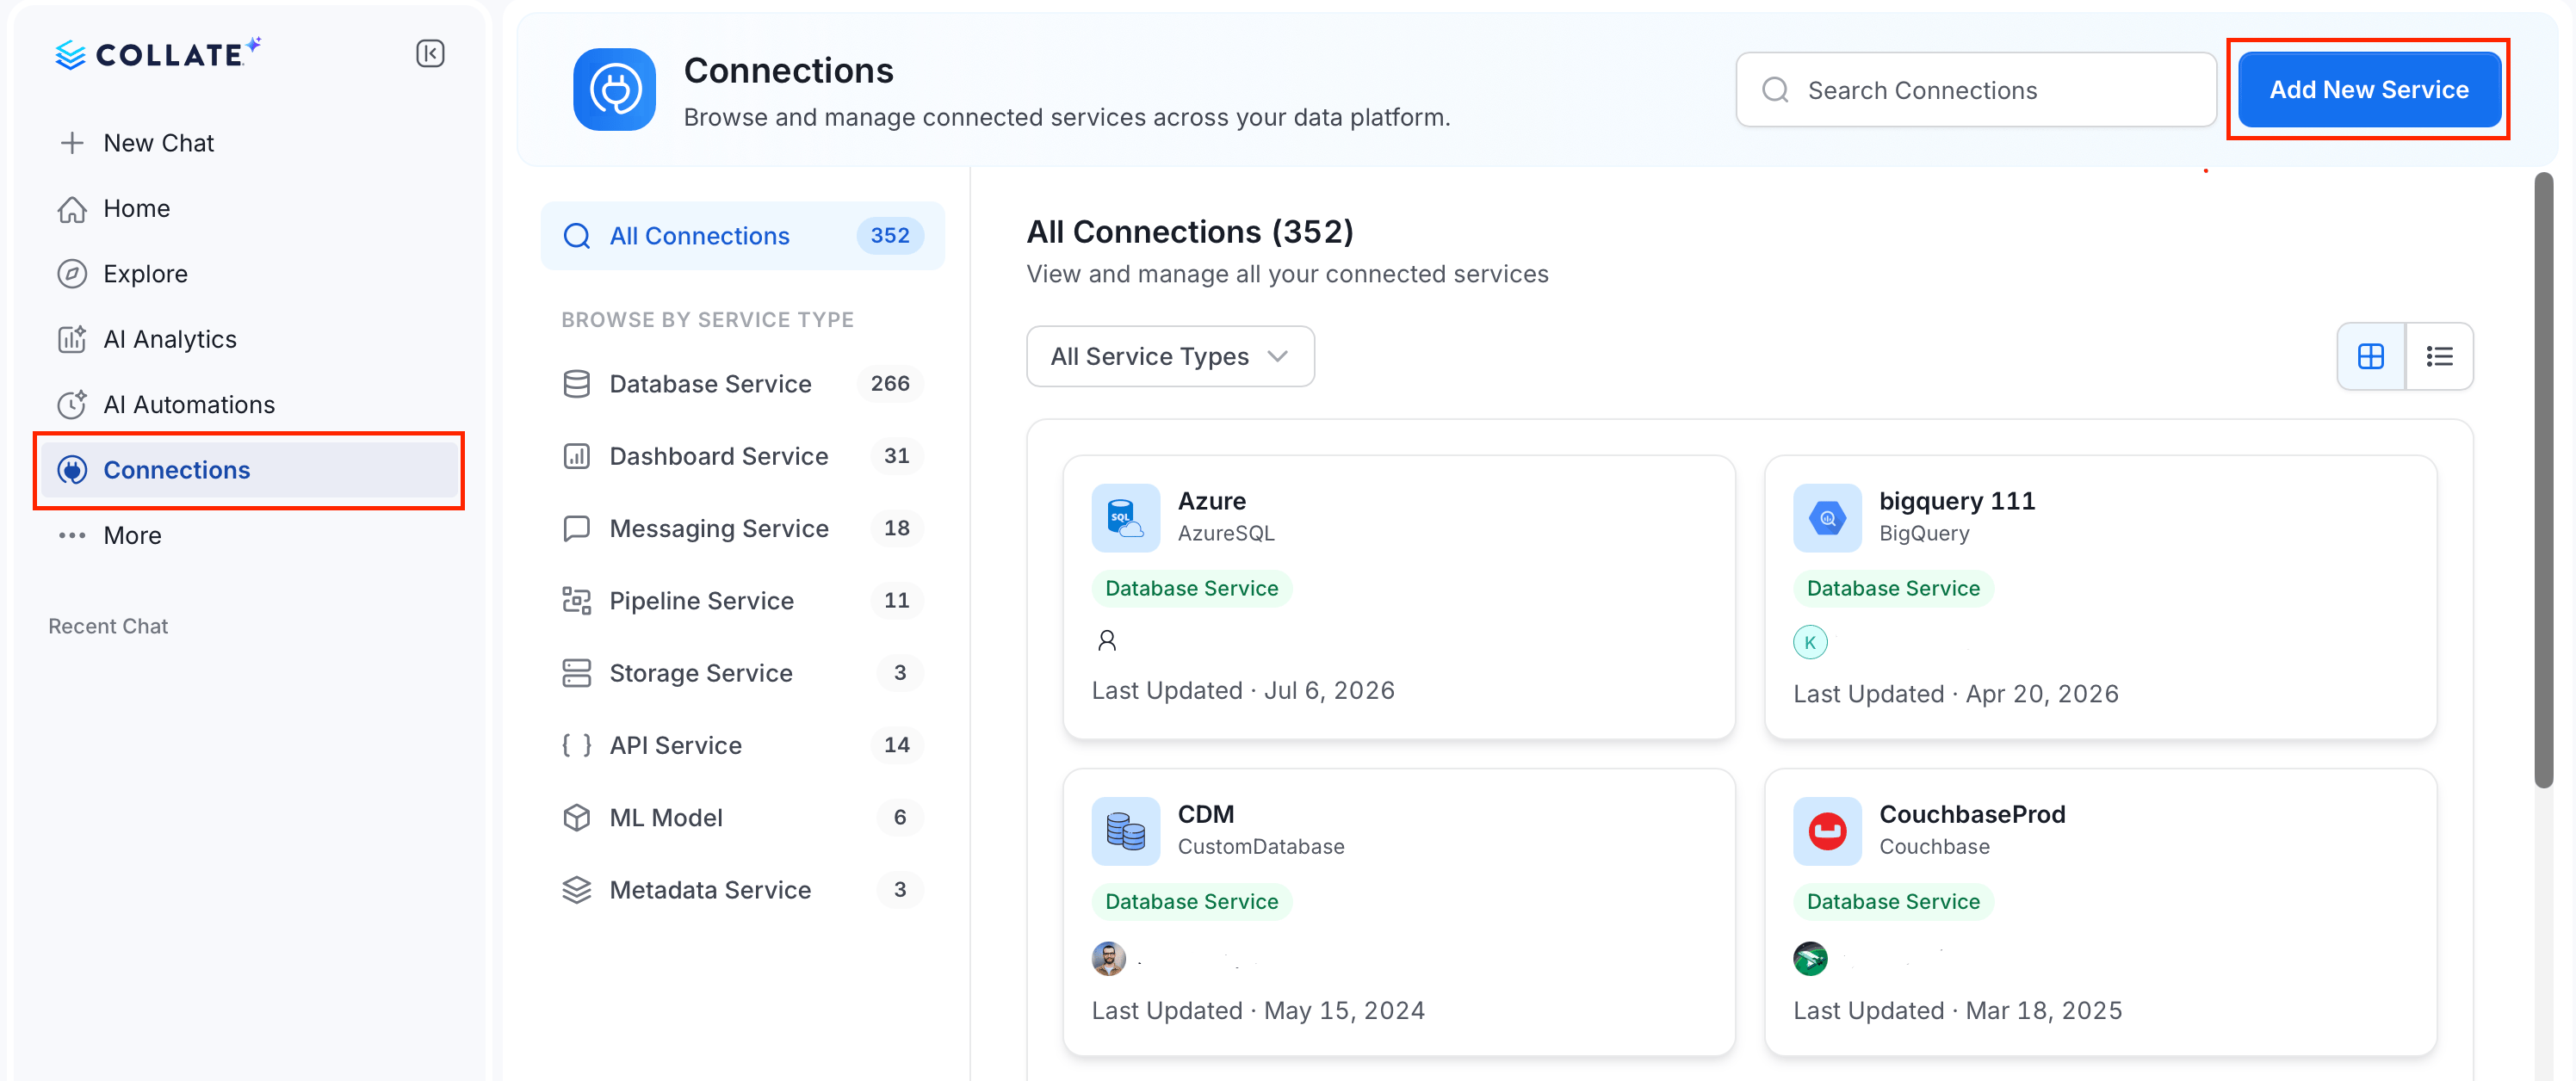
Create the service as follows:- In the left navigation, click Connections.
- On the Connections page, click Add New Service.
Step 2: Select a Service and Connector
From the service type dropdown, select Messaging Services, then click the NATS JetStream connector tile.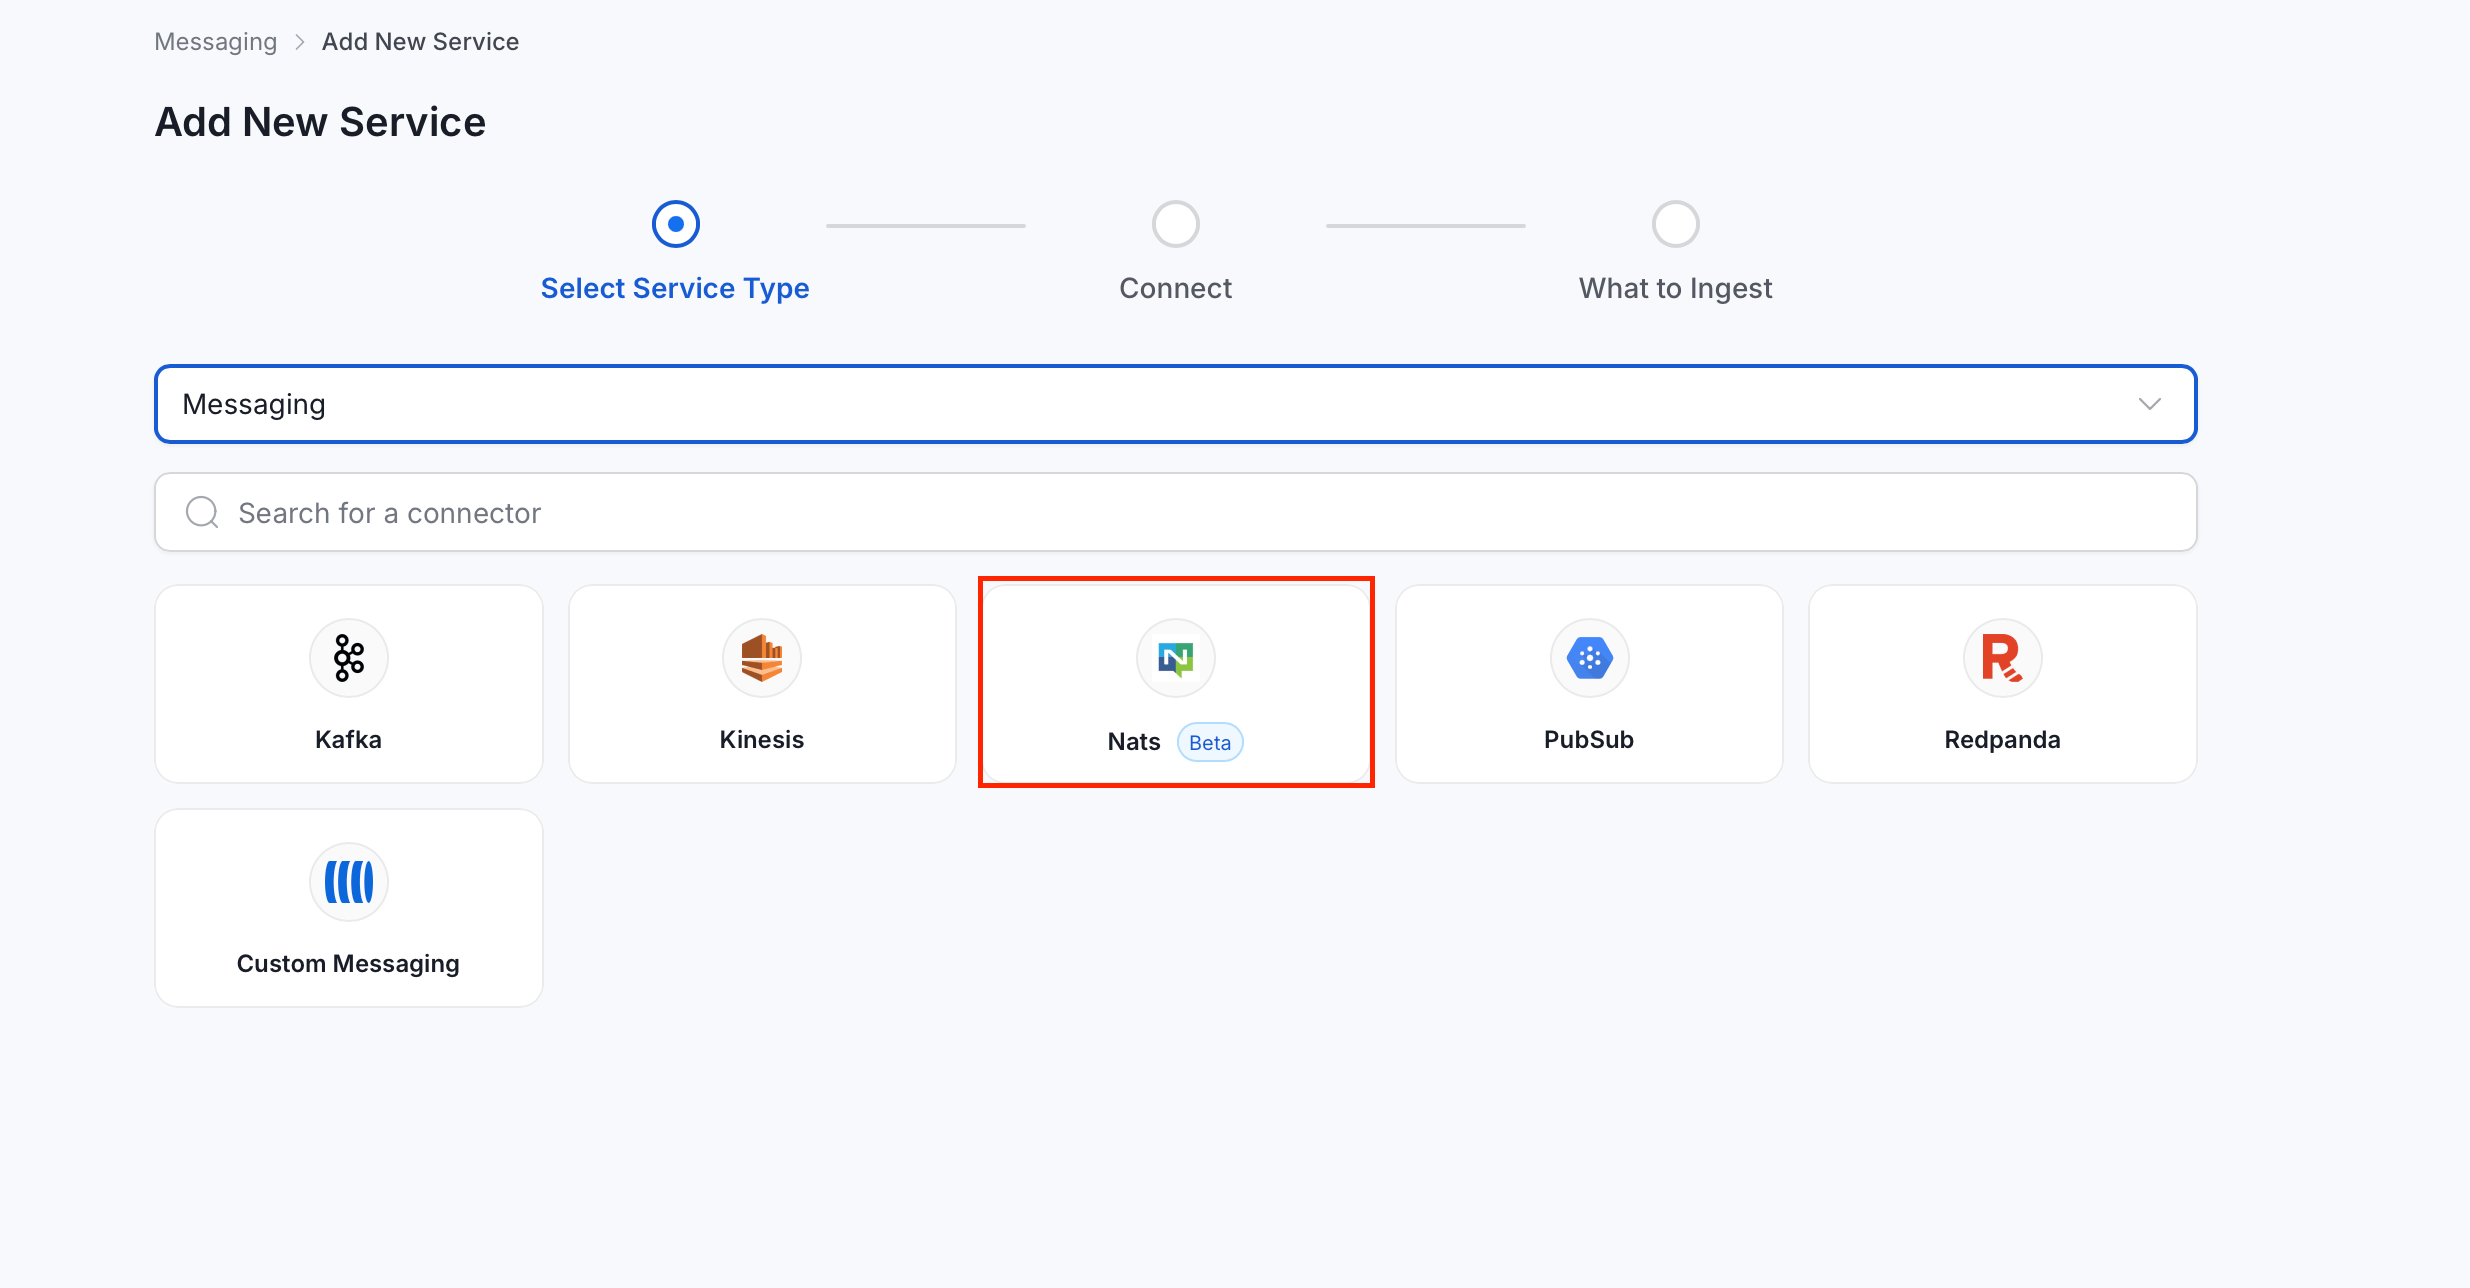
Step 3: Add Service Name and Description
- Enter a unique, descriptive Service Name. Collate identifies services by their service name. Enter a name that distinguishes this deployment from other NATS JetStream services you are ingesting metadata from.
- Optional: Enter a Description for the service.
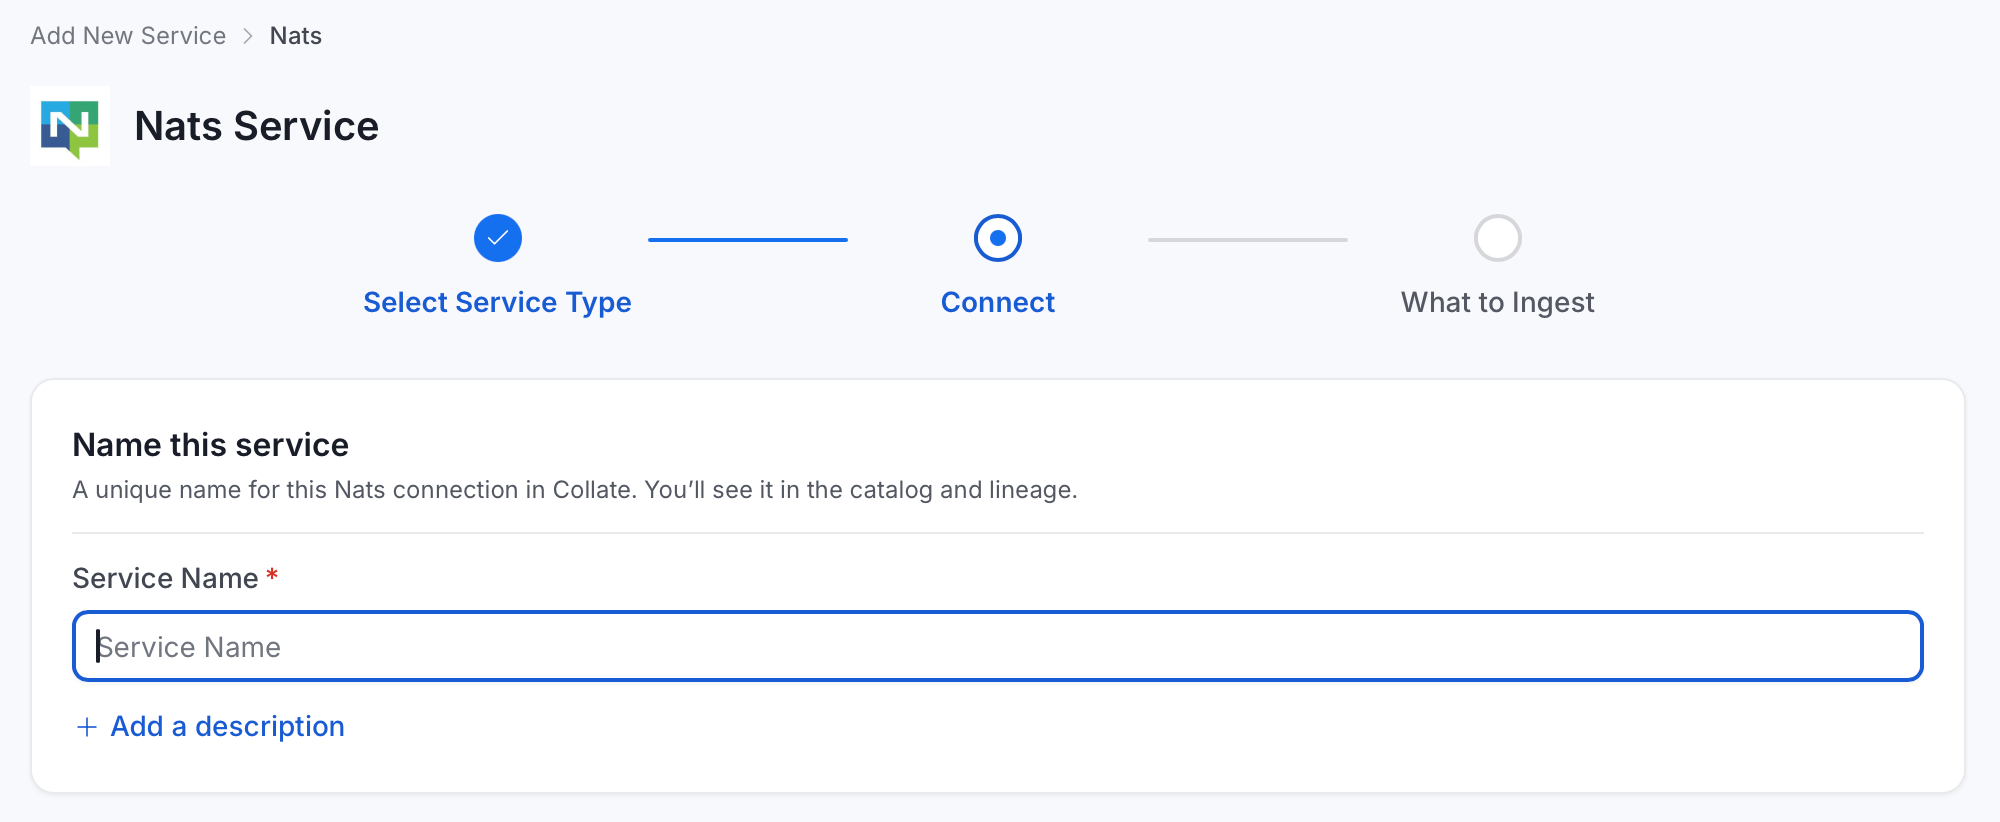
Note: The service name can’t be changed after you set it.
Step 4: Configure Connection Options
Specify where ingestion runs, provide your source credentials, and verify the connection.Select Ingestion Runner
Select an Ingestion Runner: the runner where the ingestion pipeline will execute.
Enter Connection Details
Enter the connection details for NATS JetStream. The right-hand panel in the UI displays inline help for each field.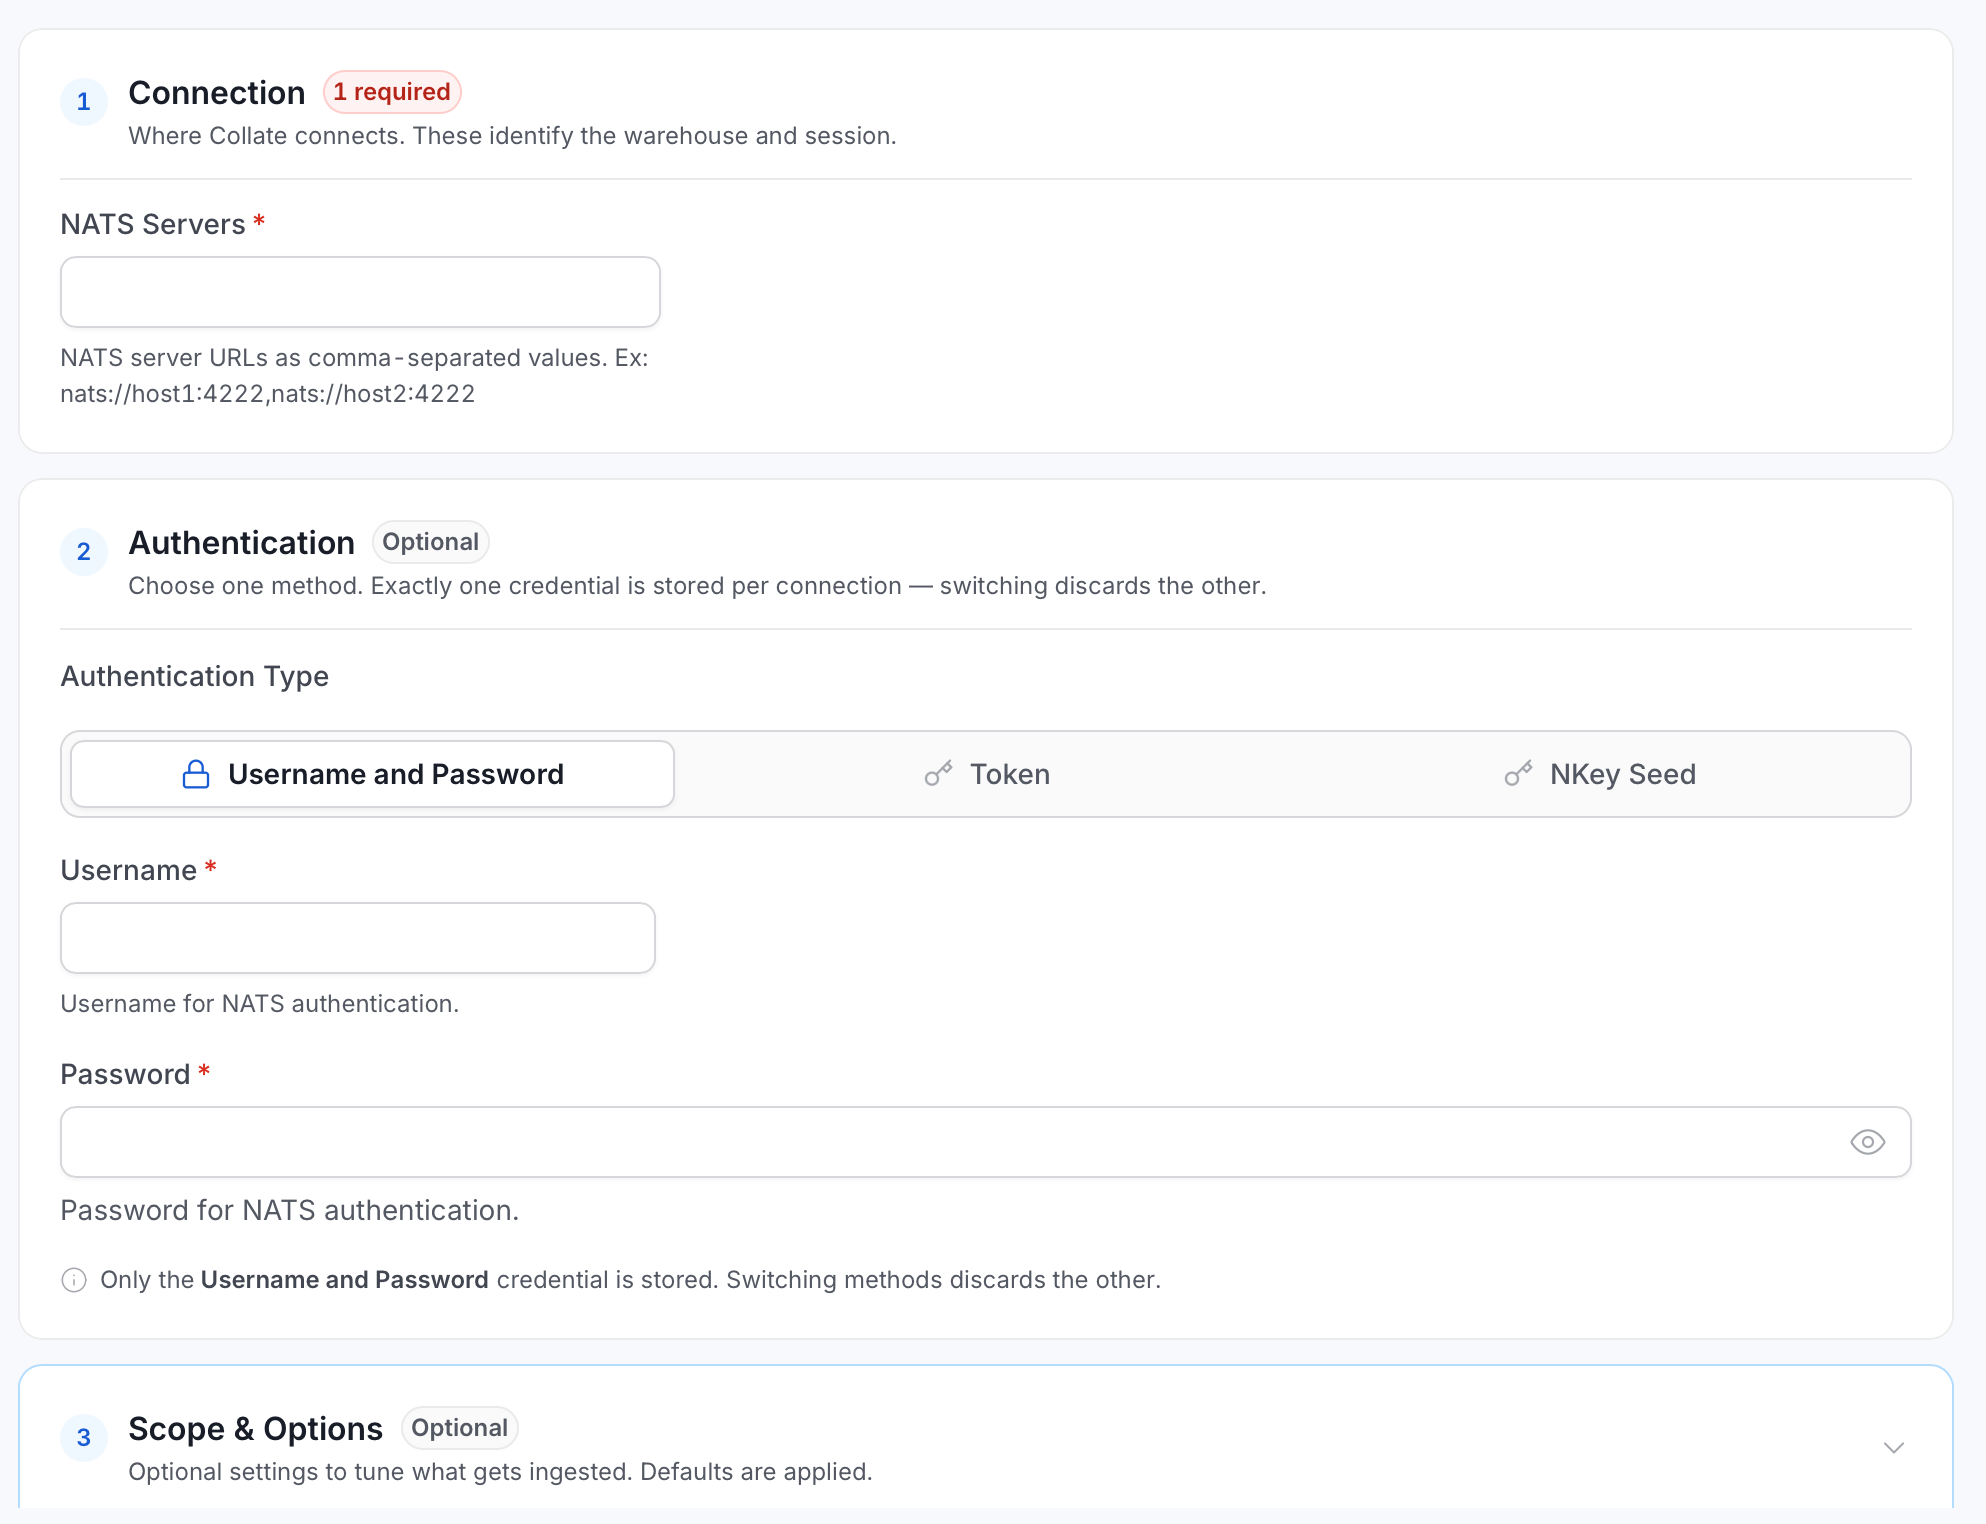
- NATS Servers: NATS server URLs as comma-separated values. Each entry uses the
nats://host:portform (the default NATS port is4222). Example:nats://host1:4222,nats://host2:4222. This is the only required field. - Authentication Type: The method used to authenticate to NATS. Leave empty for anonymous access, or choose one of the following:
- Username and Password: Provide a Username and Password for basic authentication.
- Token: Provide a single Token for token-based authentication.
- NKey Seed: Provide an NKey Seed (the private key seed beginning with
S) for NKey authentication.
- TLS Configuration (optional): TLS/SSL configuration for secure connections. Provide the CA Certificate used to validate the server. For mutual TLS, also provide the SSL Certificate (client certificate) and SSL Key (the private key for that certificate). Both must be supplied together. For more information, see TLS Configuration.
- Schema KV Bucket (optional): Name of the JetStream KV bucket where schemas are stored. Keys must match stream names and values should be Avro JSON, Protobuf (
.proto), or JSON Schema text. For more information, see Schema KV Bucket. - Additional NATS Config (optional): Additional NATS client configuration options passed through to the client. See the NATS Python client documentation. The following connection-managed keys are reserved and can’t be set here:
servers,user,password,token,nkeys_seed,nkeys_seed_str,tls,user_credentials,signature_cb, anduser_jwt_cb.
Test Connection
- Click Test Connection to verify the credentials.
- After the test succeeds, click Save.
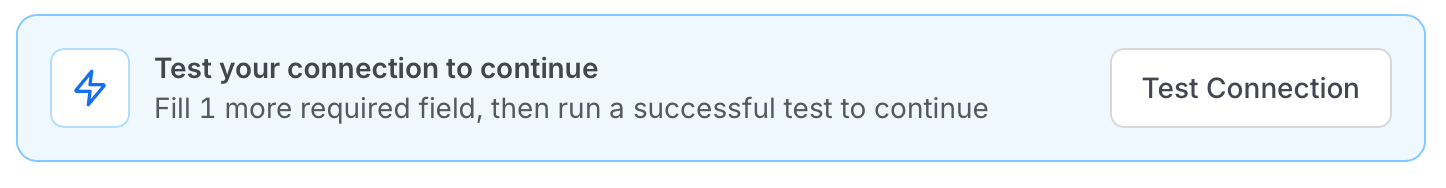
- GetTopics: Lists JetStream streams to confirm the connection and JetStream access.
- CheckSchemaKvBucket: Confirms the configured Schema KV bucket is reachable. This check is optional. When no Schema KV Bucket is set, it reports a failure that you can ignore. The overall test still passes.
Step 5: Configure Ingestion Options
In the What to Ingest step, use filter rules to control which topics (JetStream streams) Collate ingests from the source.How Filter Rules Work
Each rule matches topic names using one of five match types:- contains: matches any name containing the value. For example,
ordersmatchesprod_ordersandorders_2024. - starts with: matches names beginning with the value. For example,
prod_matchesprod_ordersandprod_events. - ends with: matches names ending with the value. For example,
_rawmatchesevents_rawandlogs_raw. - is exactly: matches the exact name only. For example,
ordersmatches onlyorders. - matches regex: matches names using a regular expression. For example,
^orders_.*_v\d+$matchesorders_eu_v1.
Filter Options
The Topic section controls which NATS JetStream streams Collate ingests. It provides the following controls:- Scan Mode: Choose between the following scan modes:
- Scan all: Ingests every topic the connector can access. This is the default.
- Only specific: Enables include rules so only topics matching at least one rule are ingested.
- Always exclude: Add permanent exclusion rules (shown in red). Topics matching these rules are never ingested, regardless of include rules.
- Preview: Shows a real-time summary of what will be in scope based on your current rules.
- Include rules: In Only specific mode, click + Add to define a rule. Added rules appear as chips. A topic is included if it matches any rule.
Step 6: Create & Deploy
Click Create & Deploy to deploy the agent and start the first metadata ingestion run. Collate saves the service configuration and immediately begins pulling metadata from the source. To monitor ingestion progress or view the service you just added, go to Connections in the left navigation and select your service.Configure Metadata Agent and Schedule Ingestion
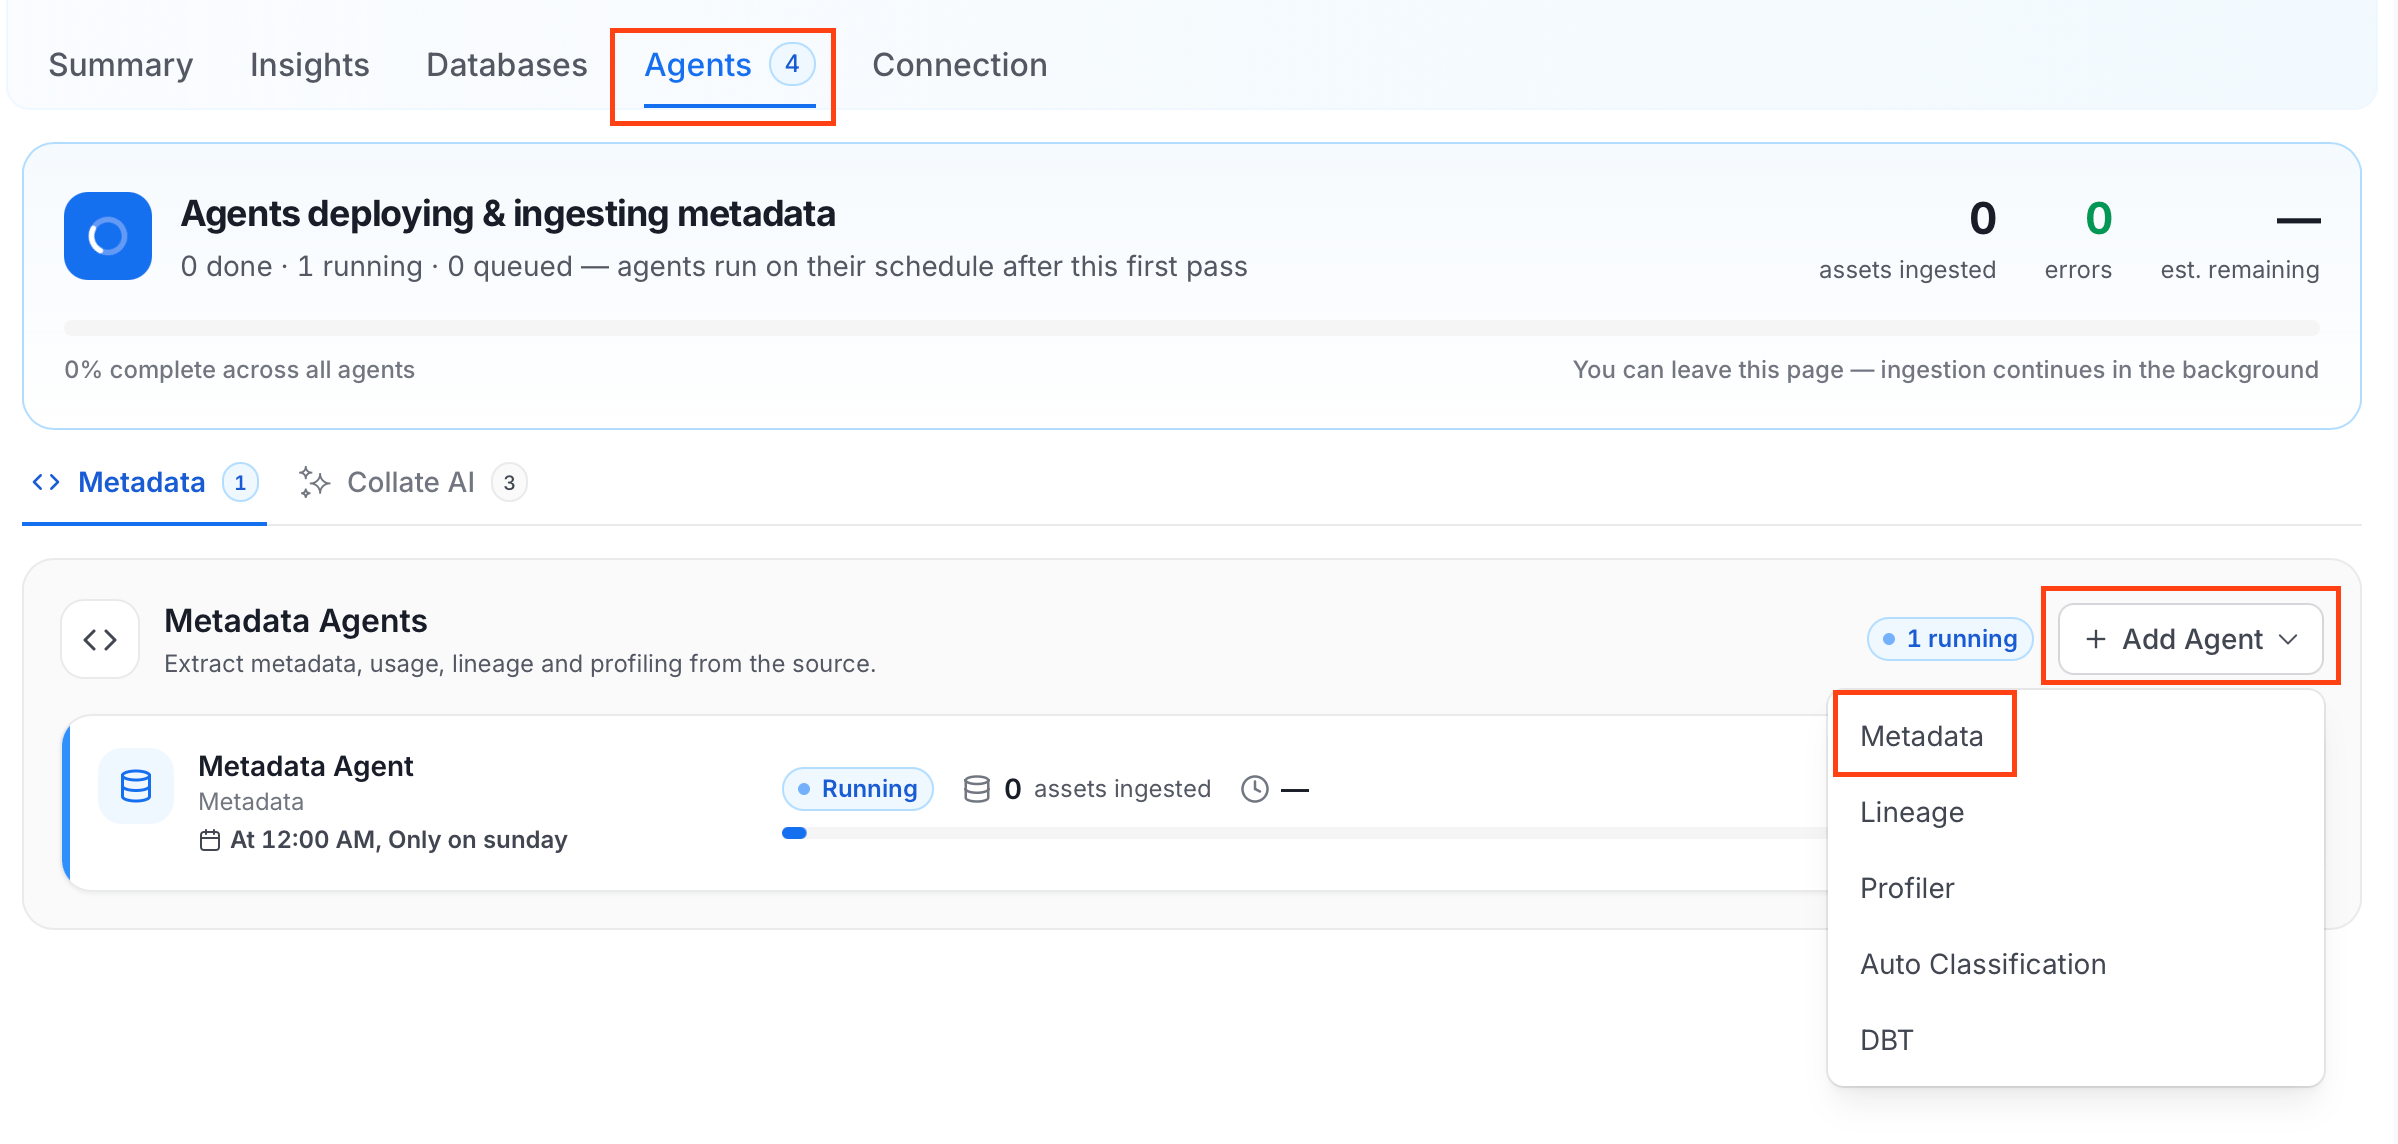
The Metadata Agent extracts topics, schemas, and other structural metadata from your source and keeps your Collate catalog in sync. It powers discovery, lineage, and governance across your data assets. When you click Create & Deploy, Collate automatically deploys a Metadata Agent for this service and triggers the first ingestion run. View its status and run history from the Agents tab on the service detail page. To configure the additional Metadata Agent and schedule ingestion, follow these steps:- In the left navigation, click Connections and select your service.
- Click the Agents tab.
-
Click Add Agent and select Metadata from the dropdown.
-
On the Configure Ingestion page, do the following and click Next.
-
Name this Ingestion: Enter a unique, recognizable name for this ingestion pipeline.

-
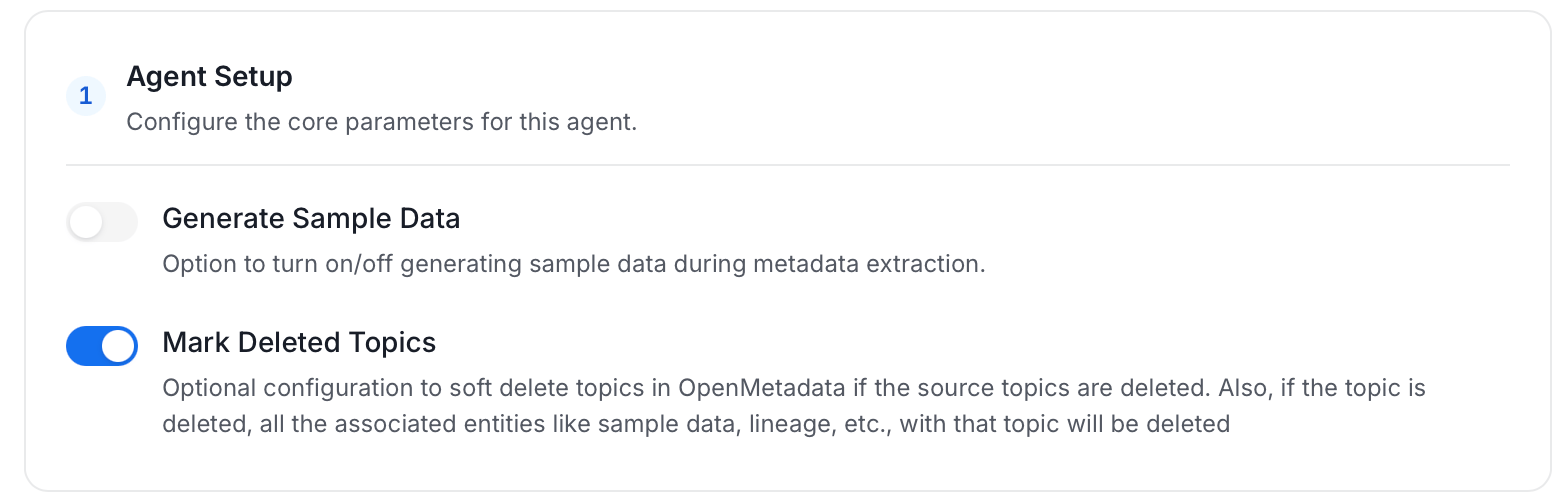
Agent Setup: Configure the core parameters for this agent. The following fields are available:
-
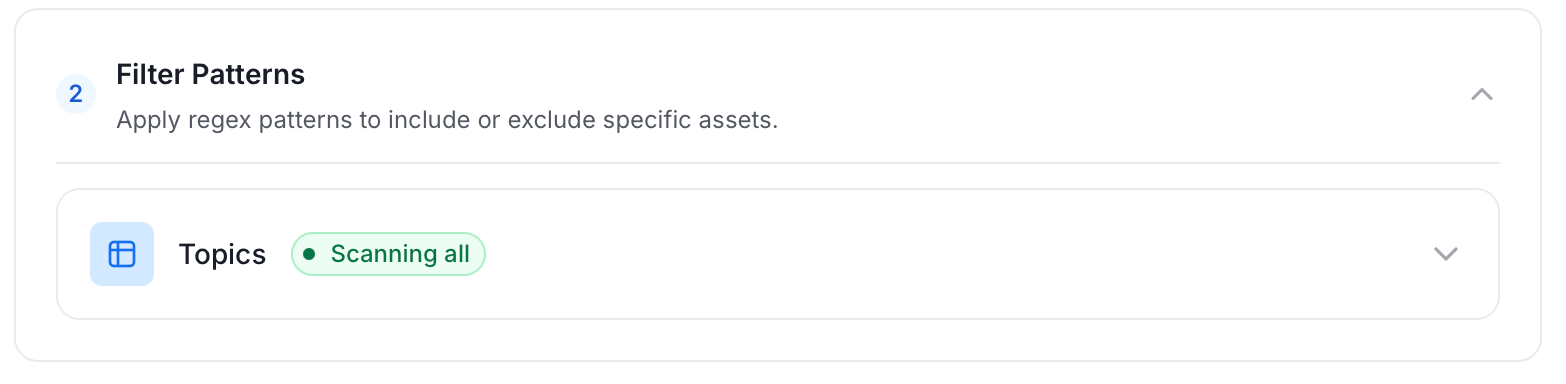
Filter Patterns: Apply include or exclude rules to scope which topics this agent ingests. These follow the same filter options described in Step 5.
-
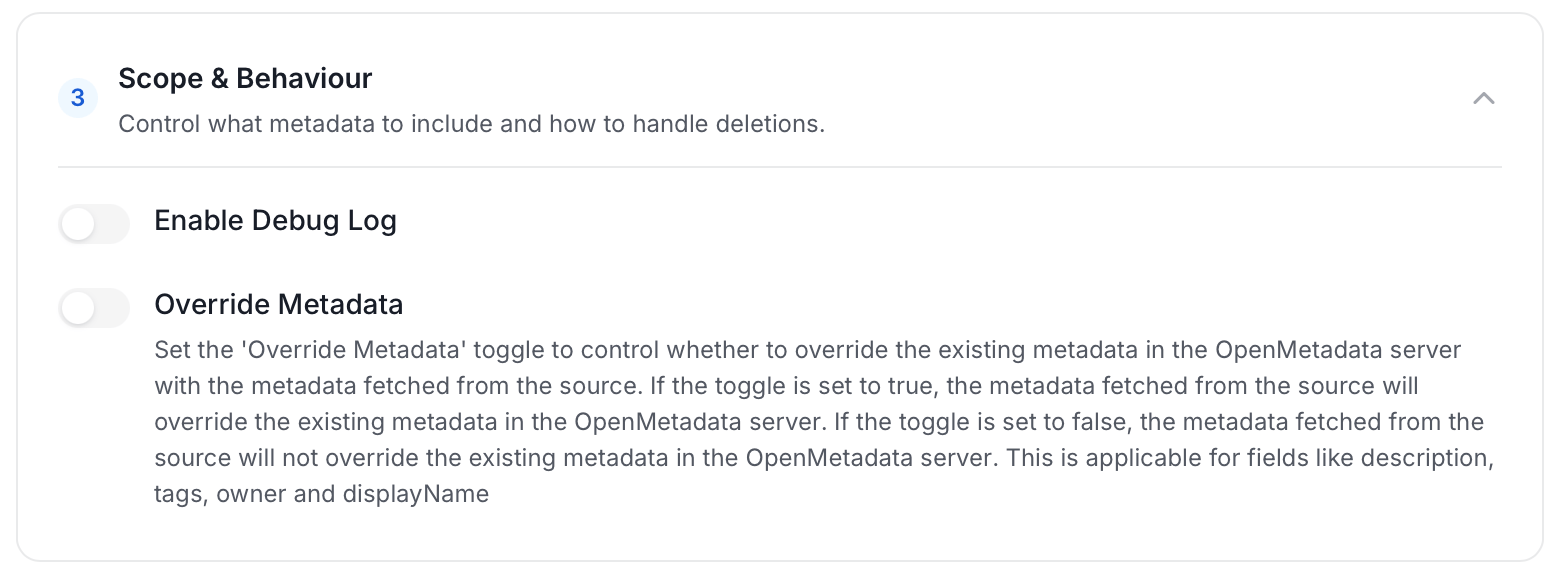
Scope & Behaviour: Control what metadata to include and how to handle deletions. Toggle each option on or off based on your needs:
-
Name this Ingestion: Enter a unique, recognizable name for this ingestion pipeline.
-
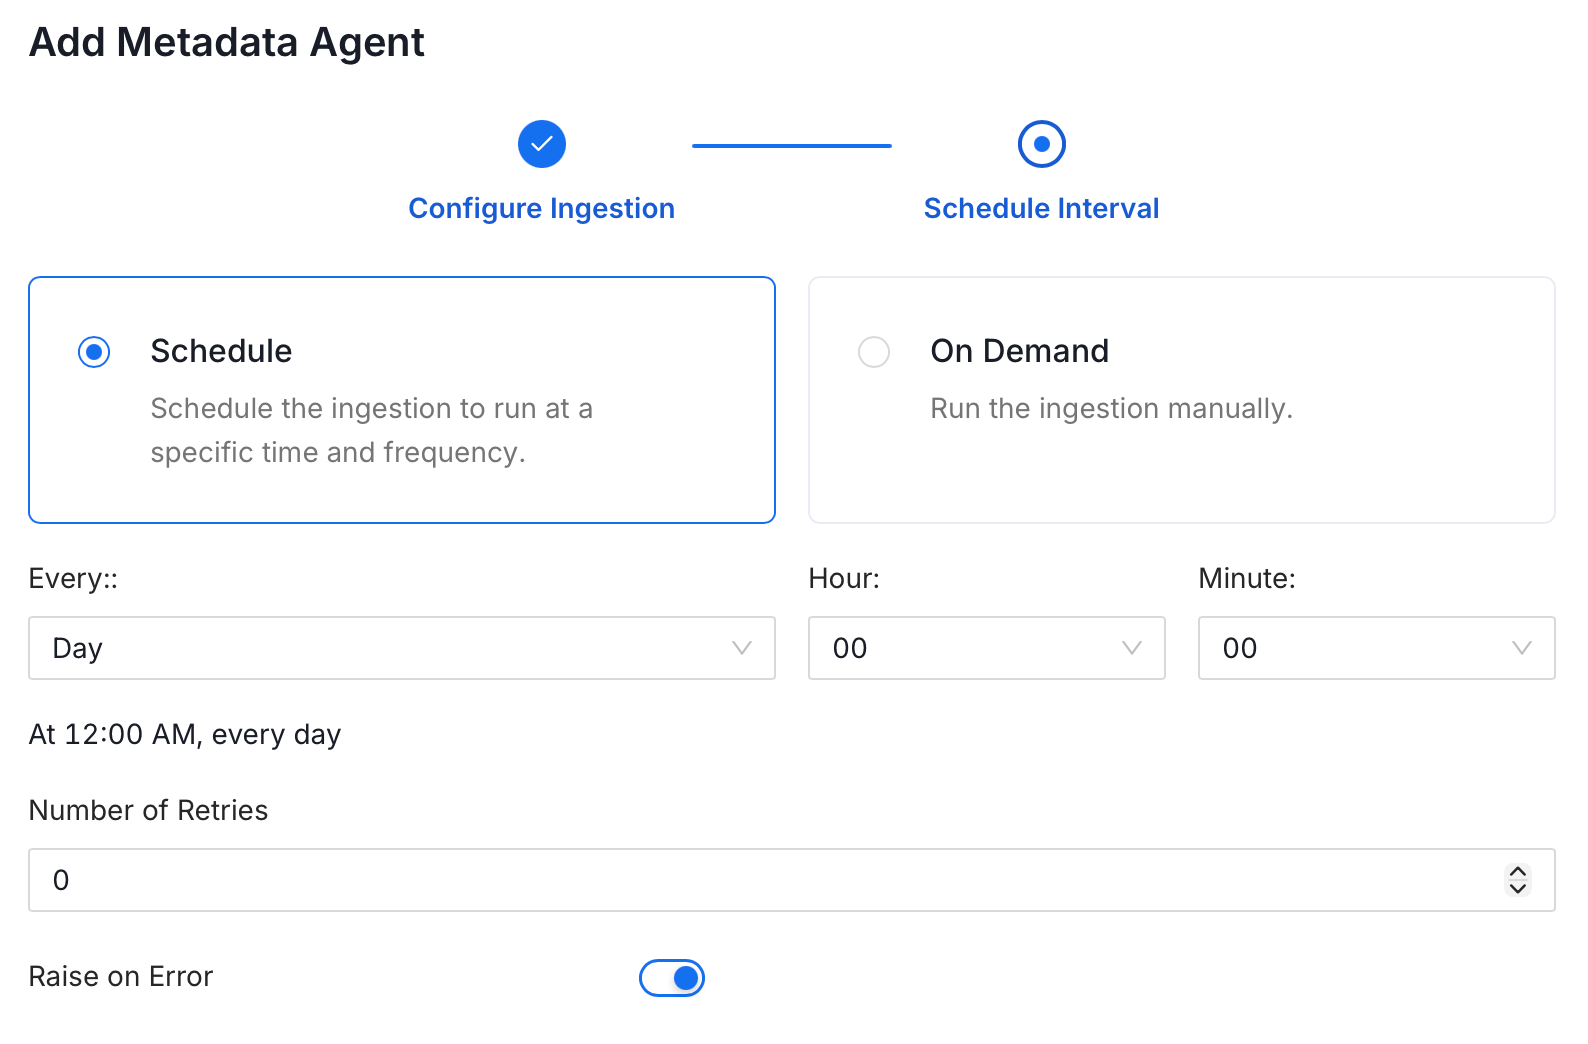
On the Schedule Interval page, set when the agent runs:
- Schedule: Choose a preset interval (Hourly, Daily, Weekly, Monthly) or enter a custom cron expression.
- On-Demand: No automatic schedule; trigger the agent manually when needed.
- Click Add to deploy the agent.
TLS Configuration
To establish secure connections between Collate and NATS, configure the TLS Configuration option. Provide the CA Certificate used to validate the NATS server’s certificate. If your server requires mutual TLS (mTLS), also provide the SSL Certificate (the client certificate) and the SSL Key (the private key associated with that certificate). The client certificate and key must always be supplied together. Configuring only one of them results in a connection error.Schema KV Bucket
NATS JetStream does not have a built-in schema registry. To ingest topic schemas, store them in a JetStream KV bucket and set the Schema KV Bucket option to that bucket’s name.- Each key in the bucket must match a stream (topic) name.
- Each value should be schema text in Avro JSON, Protobuf (
.proto), or JSON Schema format.
Sample Data
When Generate Sample Data is enabled in the ingestion configuration, Collate fetches up to 10 messages from the last 100 sequences of each stream. The total sample is capped at 1 MB. Only UTF-8 text messages are included. Binary payloads are skipped. Sample data collection also respects the global sample-data storage setting. If sample data storage is disabled server-wide, no sample messages are collected.Troubleshooting
NATS JetStream Troubleshooting
Learn more about how to troubleshoot common NATS JetStream connector issues and resolve configuration or ingestion errors.