
Requirements
Collate connects to ClickZetta with a SQLAlchemy driver, using a username and password and a virtual cluster to run its read-only queries. The connecting user needs to be able to use that virtual cluster and to read the catalog, the tables you want to ingest, and the query-history view. Grant the following to the role your ingestion user connects with:Profiler and Data Quality
Running the profiler workflow, data quality tests, or data diff requiresSELECT on the tables and schemas being profiled or tested. The profiler uses ClickZetta’s native sampling to keep profiling efficient. For more information, see Profiler Workflow and Data Quality.
Usage and Lineage
Query Usage and query-based lineage read from a ClickZetta query-history source. GrantSELECT on the query-history view you configure:
Metadata Ingestion
To ingest metadata from ClickZetta, you need to create a service connection. The service connects ClickZetta with Collate. Once you create a service, Collate automatically starts ingesting metadata.Step 1: Add New Service
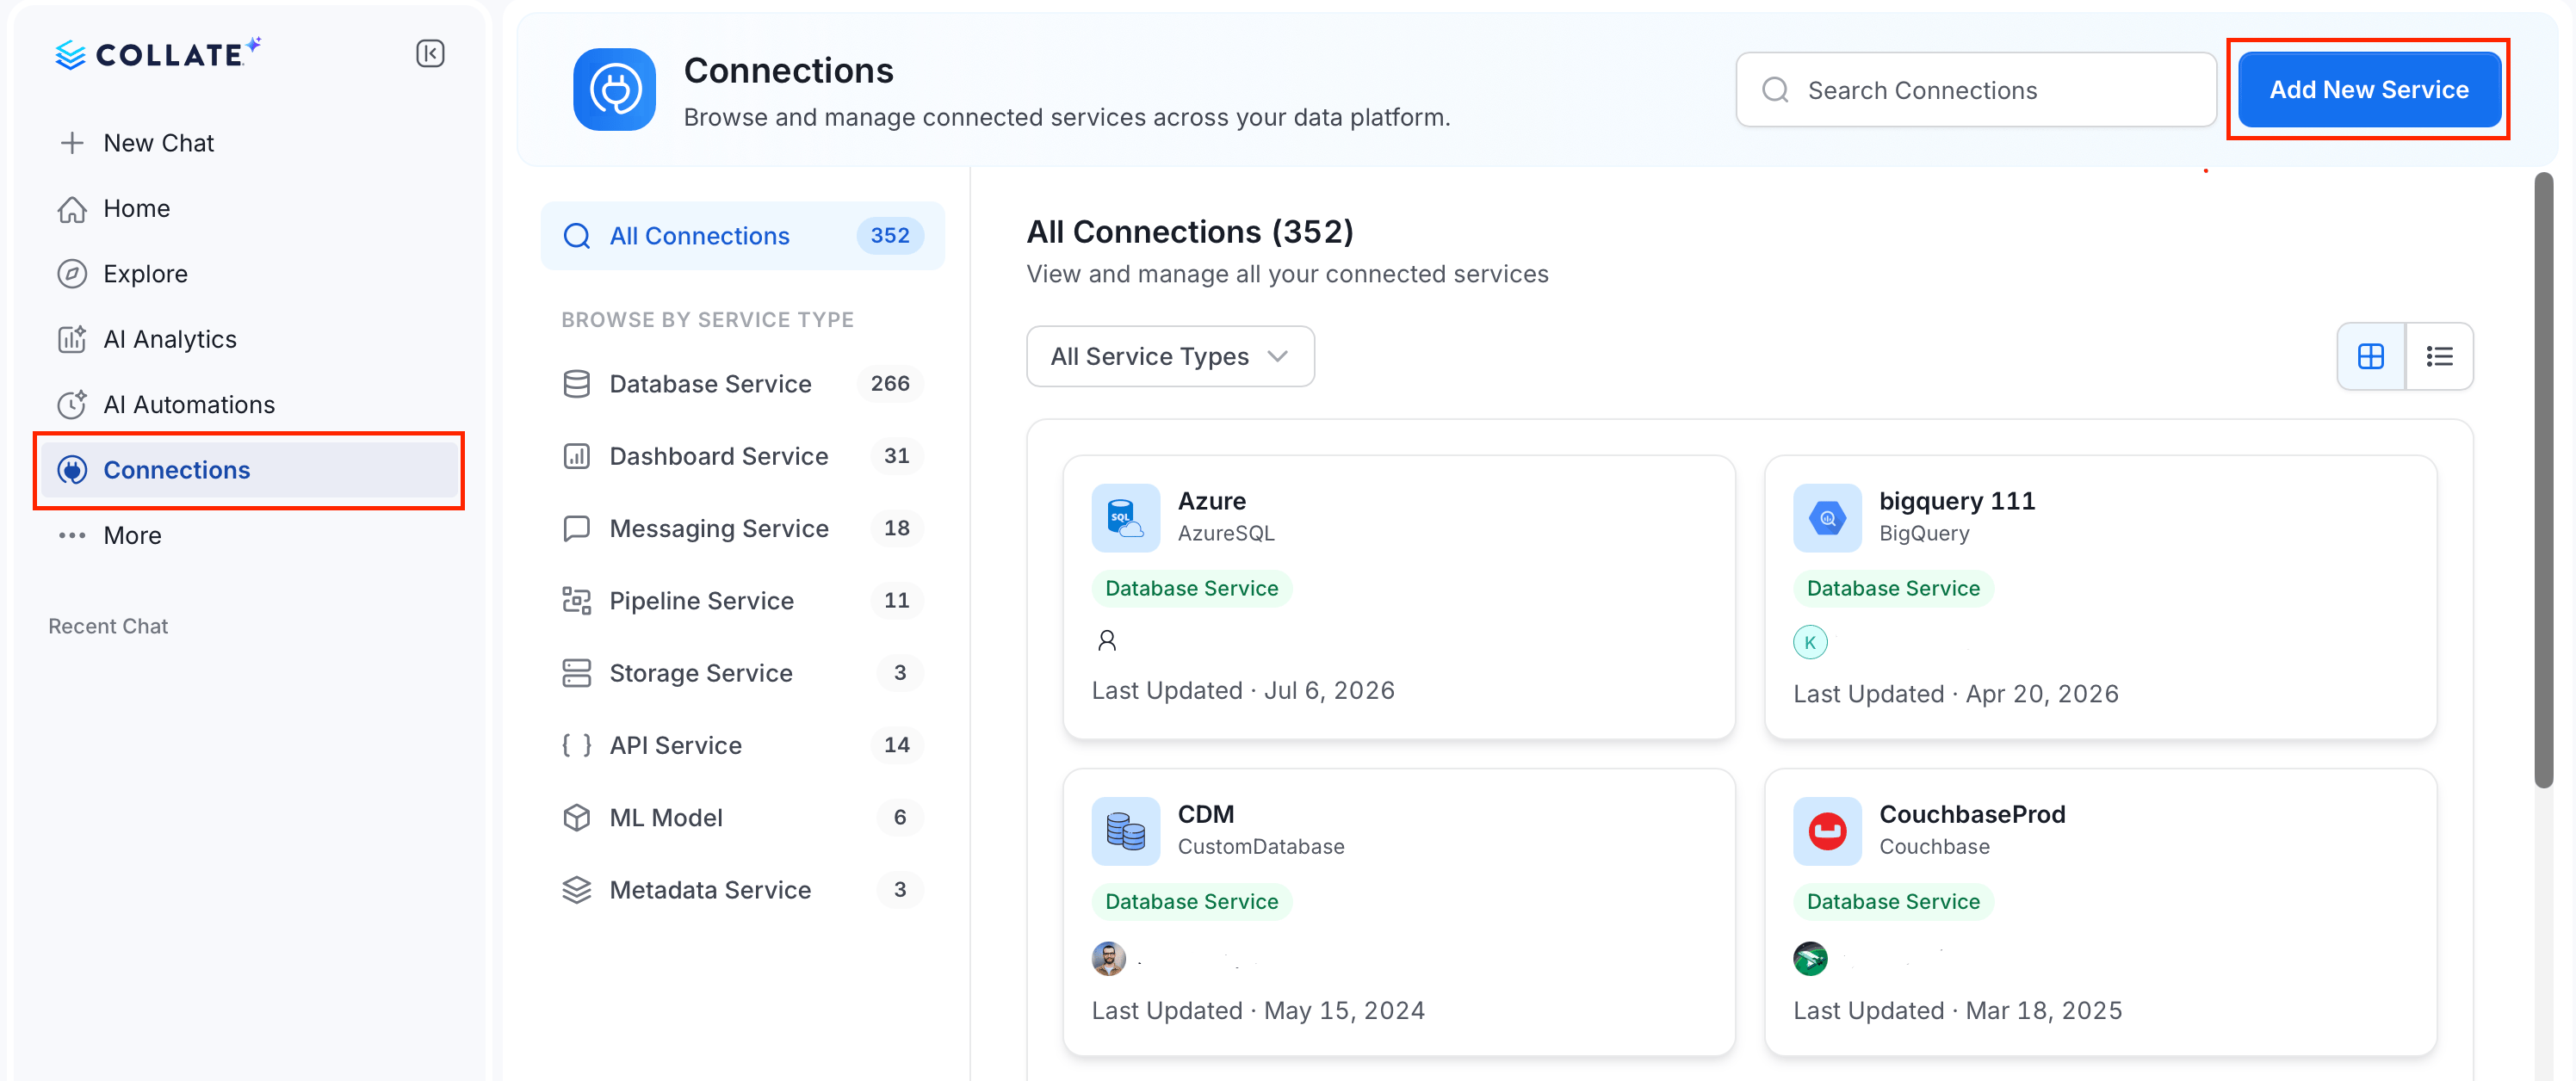
Create the service as follows:- In the left navigation, click Connections.
- On the Connections page, click Add New Service.
Step 2: Select a Service and Connector
From the service type dropdown, select Database Services, then click the ClickZetta connector tile.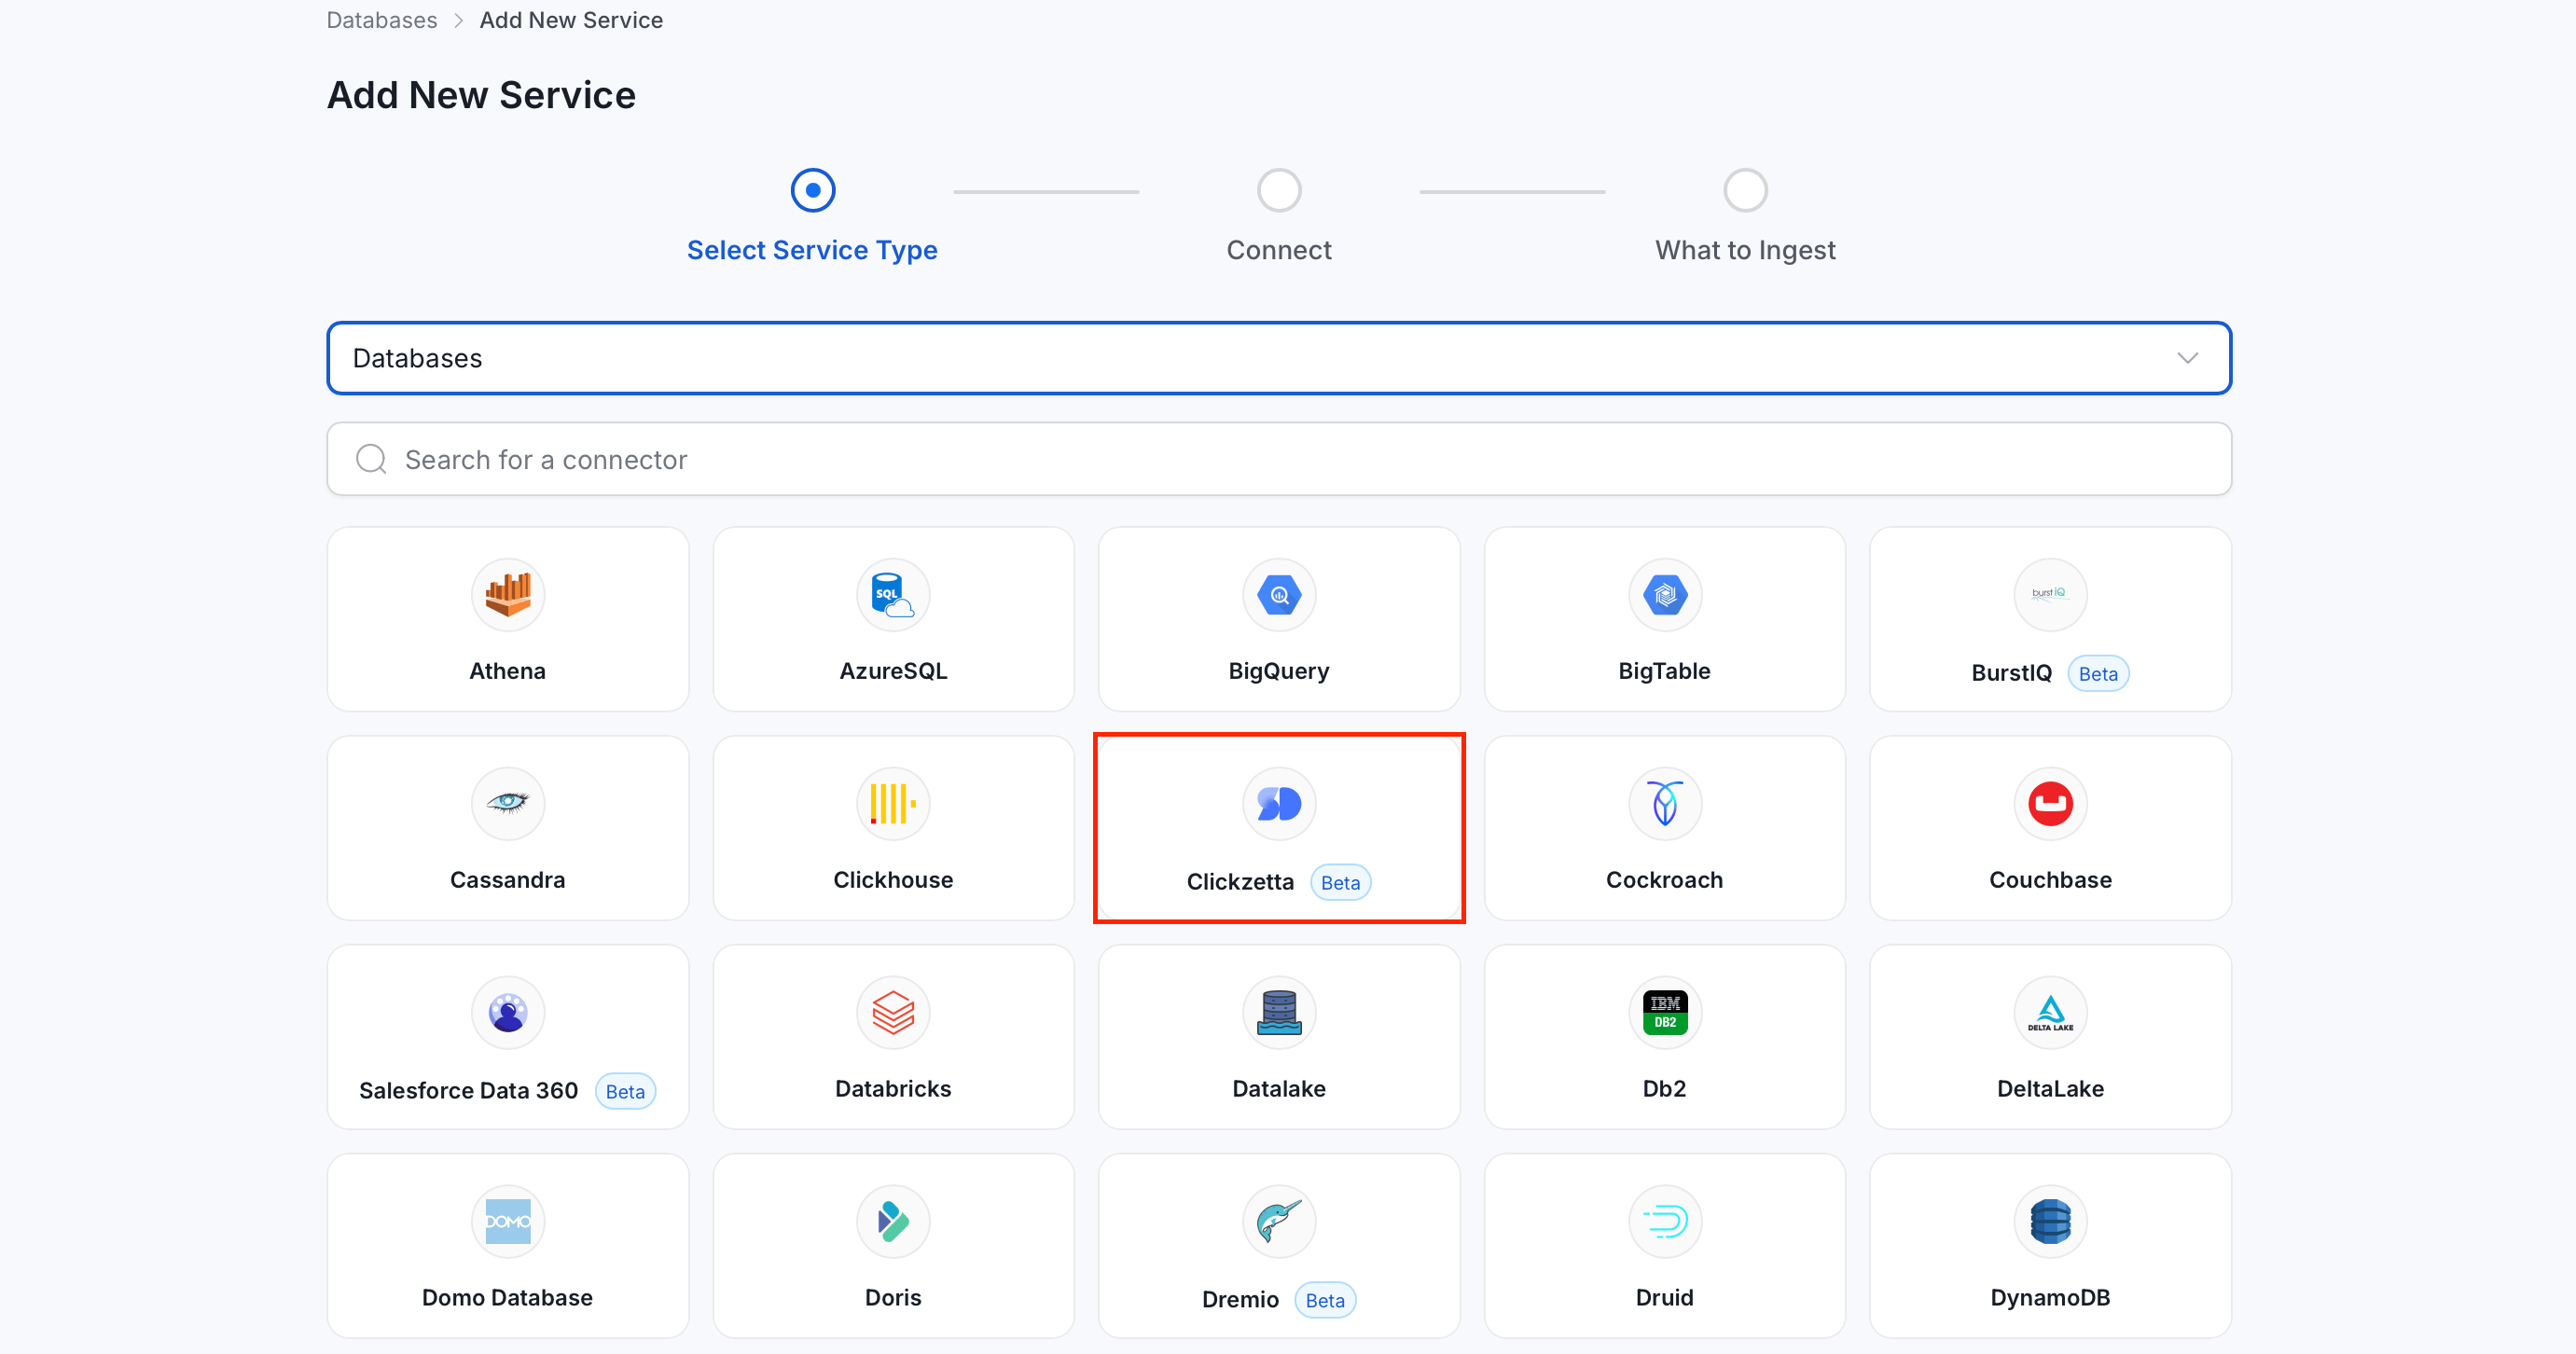
Step 3: Add Service Name and Description
- Enter a unique, descriptive Service Name. Collate identifies services by their service name. Enter a name that distinguishes this deployment from other ClickZetta services you are ingesting metadata from.
- Optional: Enter a Description for the service.
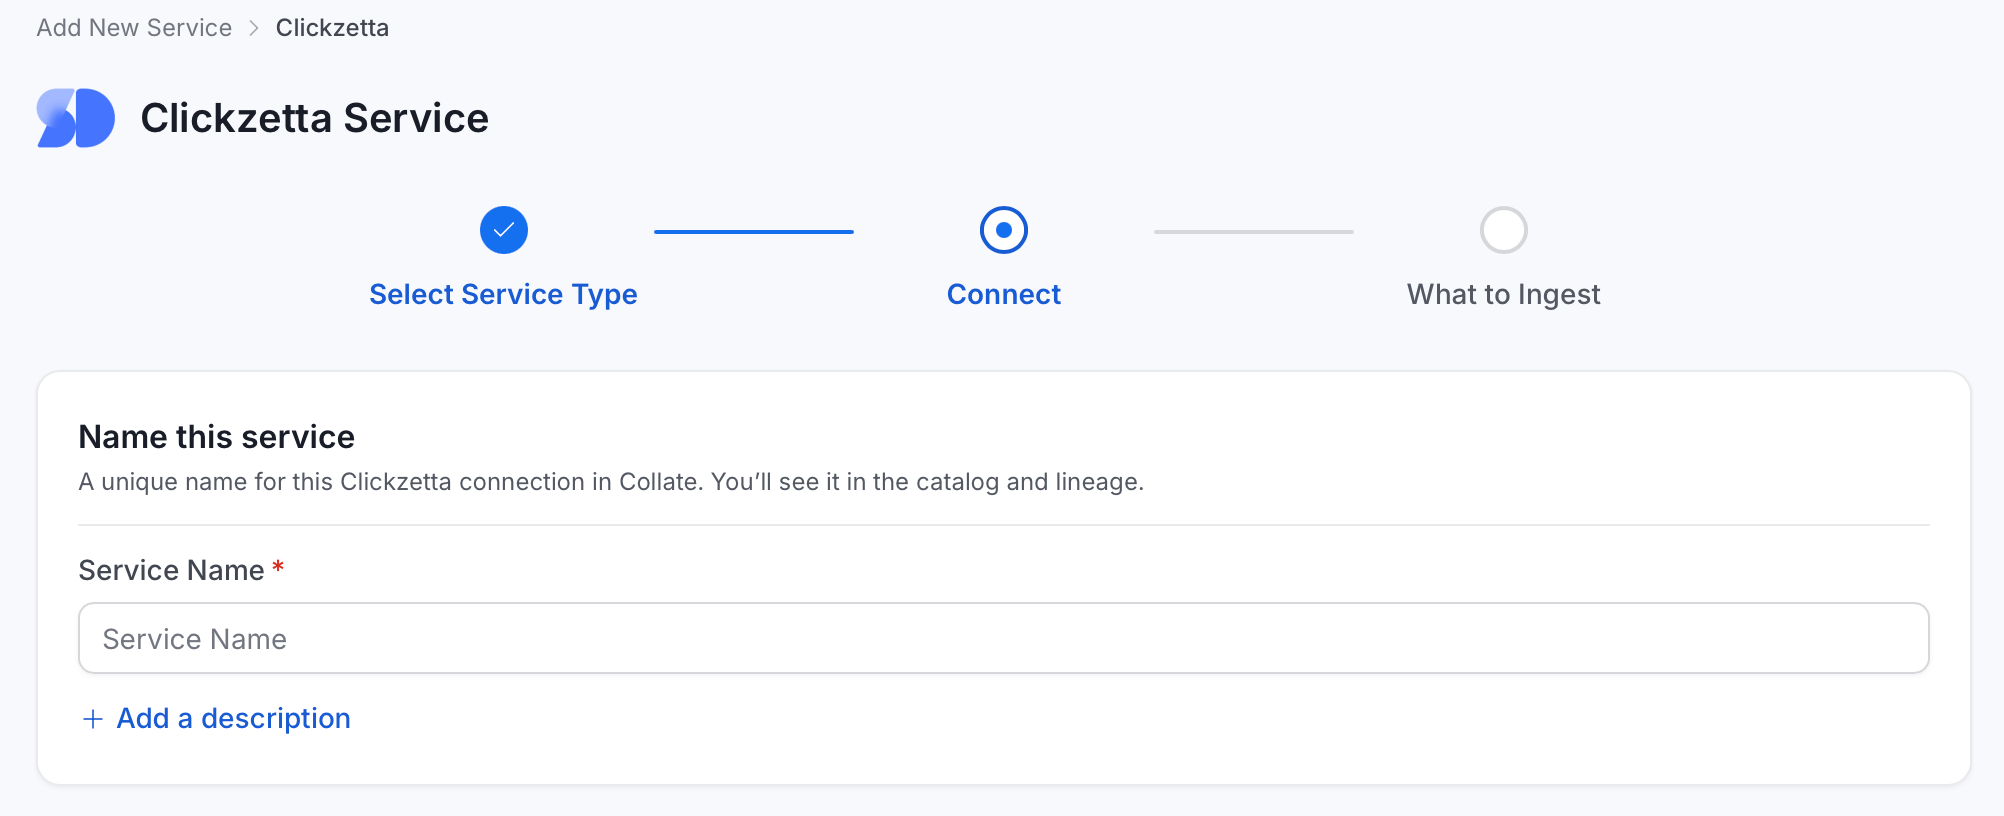
Note: The service name can’t be changed after you set it.
Step 4: Configure Connection Options
Specify where ingestion runs, provide your source credentials, and verify the connection.Select Ingestion Runner
Select an Ingestion Runner: the runner where the ingestion pipeline will execute.
Enter Connection Details
Enter the connection details for ClickZetta. The right-hand panel in the UI displays inline help for each field.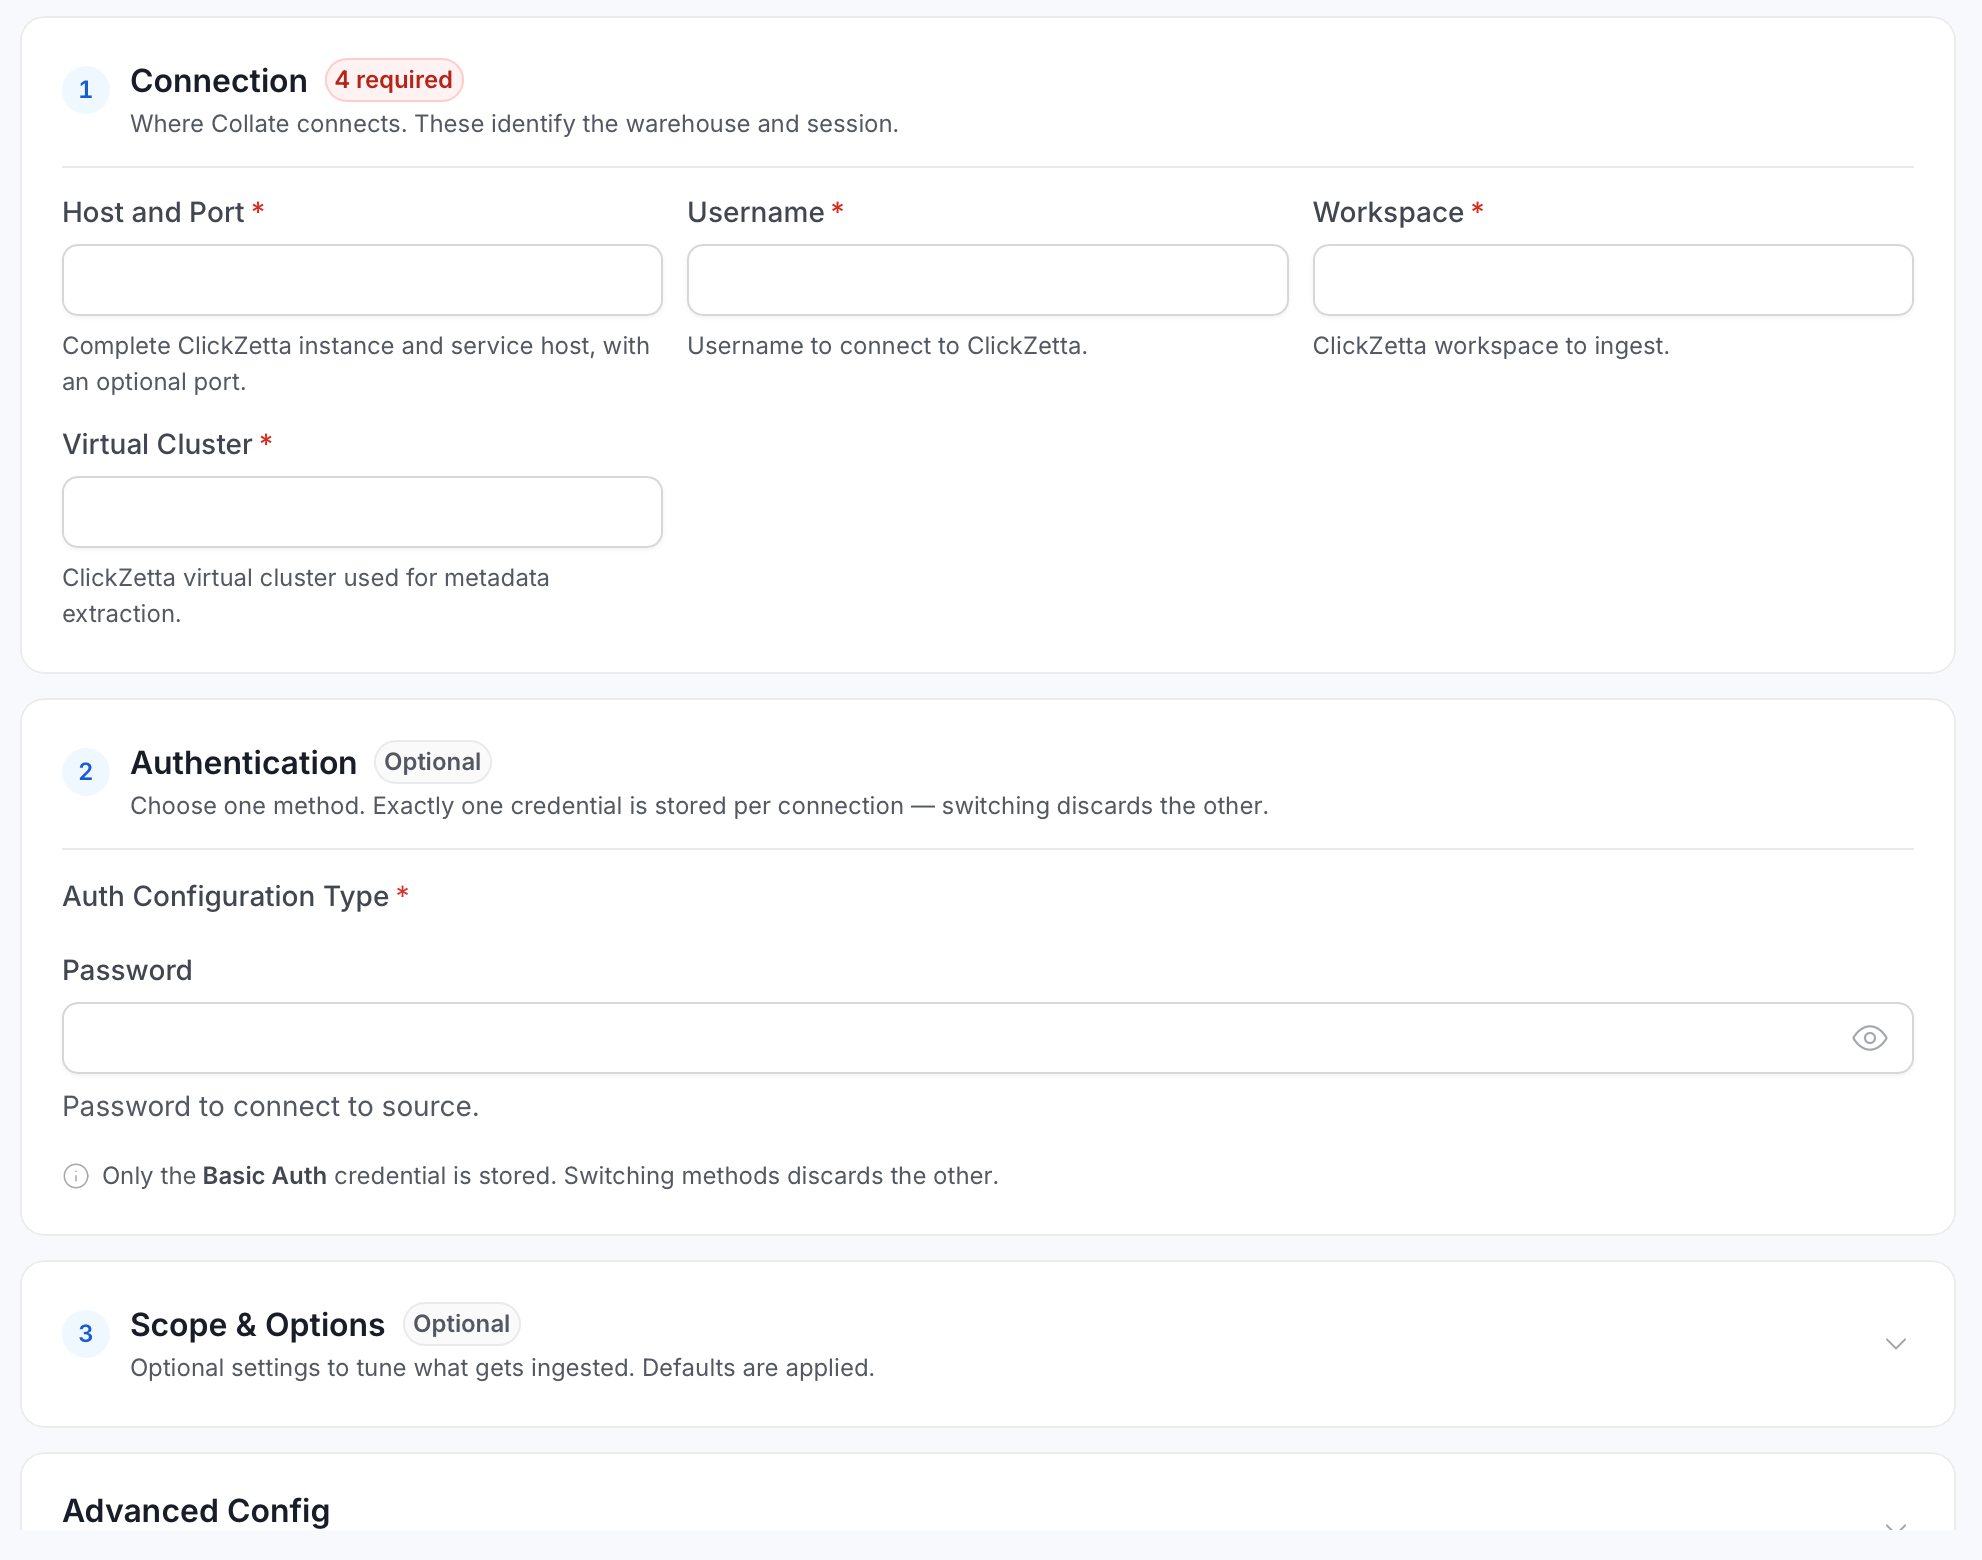
- Host and Port: Complete ClickZetta instance and service host, with an optional port, for example
your-instance.clickzetta.comoryour-instance.clickzetta.com:8443. - Username: Username to connect to ClickZetta. It should have enough privileges to read all the metadata.
- Workspace: The ClickZetta workspace to ingest.
- Virtual Cluster: The ClickZetta virtual cluster used to run the metadata extraction queries.
- Password: Password to connect to ClickZetta.
- Database Schema (optional): Schema restriction. When left blank, Collate attempts to scan all schemas.
- Query History Table: ClickZetta table or view used for usage and query-lineage extraction. It is required for the Query Usage and Lineage agents, which fail if it is unset. Set this to
information_schema.job_historyfor workspace-local native history. Usesys.information_schema.job_historyfor cross-workspace native history. The connector maps the native columns from either source and scopes them to the configured workspace and schema. Custom tables or views must expose the following columns:- Query columns:
query_text,query_type,user_name - Scope and timing columns:
database_name,schema_name,start_time,end_time,duration,aborted,cost
- Query columns:
- Protocol: Protocol used to connect to ClickZetta. Choose
https(default) orhttp.
Test Connection
- Click Test Connection to verify the credentials.
- After the test succeeds, click Save.
Step 5: Configure Ingestion Options
In the What to Ingest step, use filter rules to control which databases, schemas, and tables Collate ingests from the source.How Filter Rules Work
Each rule matches asset names using one of five match types:- contains: matches any name containing the value. For example,
salesmatchesmy_sales_dataandsales_2024. - starts with: matches names beginning with the value. For example,
prod_matchesprod_dbandprod_schema. - ends with: matches names ending with the value. For example,
_rawmatchesevents_rawandlogs_raw. - is exactly: matches the exact name only. For example,
analyticsmatches onlyanalytics. - matches regex: matches names using a regular expression. For example,
^prod_.*_v\d+$matchesprod_events_v1.
Filter Options
The Database, Schema, and Table sections control ingestion for the corresponding asset type. Each section provides the following controls:- Scan Mode: Choose between the following scan modes:
- Scan all: Ingests every asset of that type the connector can access. This is the default.
- Only specific: Enables include rules so only assets matching at least one rule are ingested.
- Exclude system toggle: Use this toggle to filter out system-reserved names defined by the connector for that asset type.
- Always exclude: Add permanent exclusion rules (shown in red). Assets matching these rules are never ingested, regardless of include rules.
- Preview: Shows a real-time summary of what will be in scope based on your current rules.
- Include rules: In Only specific mode, click + Add to define a rule. Added rules appear as chips. An asset is included if it matches any rule.
Step 6: Create & Deploy
Click Create & Deploy to deploy the agent and start the first metadata ingestion run. Collate saves the service configuration and immediately begins pulling metadata from the source. To monitor ingestion progress or view the service you just added, go to Connections in the left navigation and select your service.Configure Metadata Agent and Schedule Ingestion
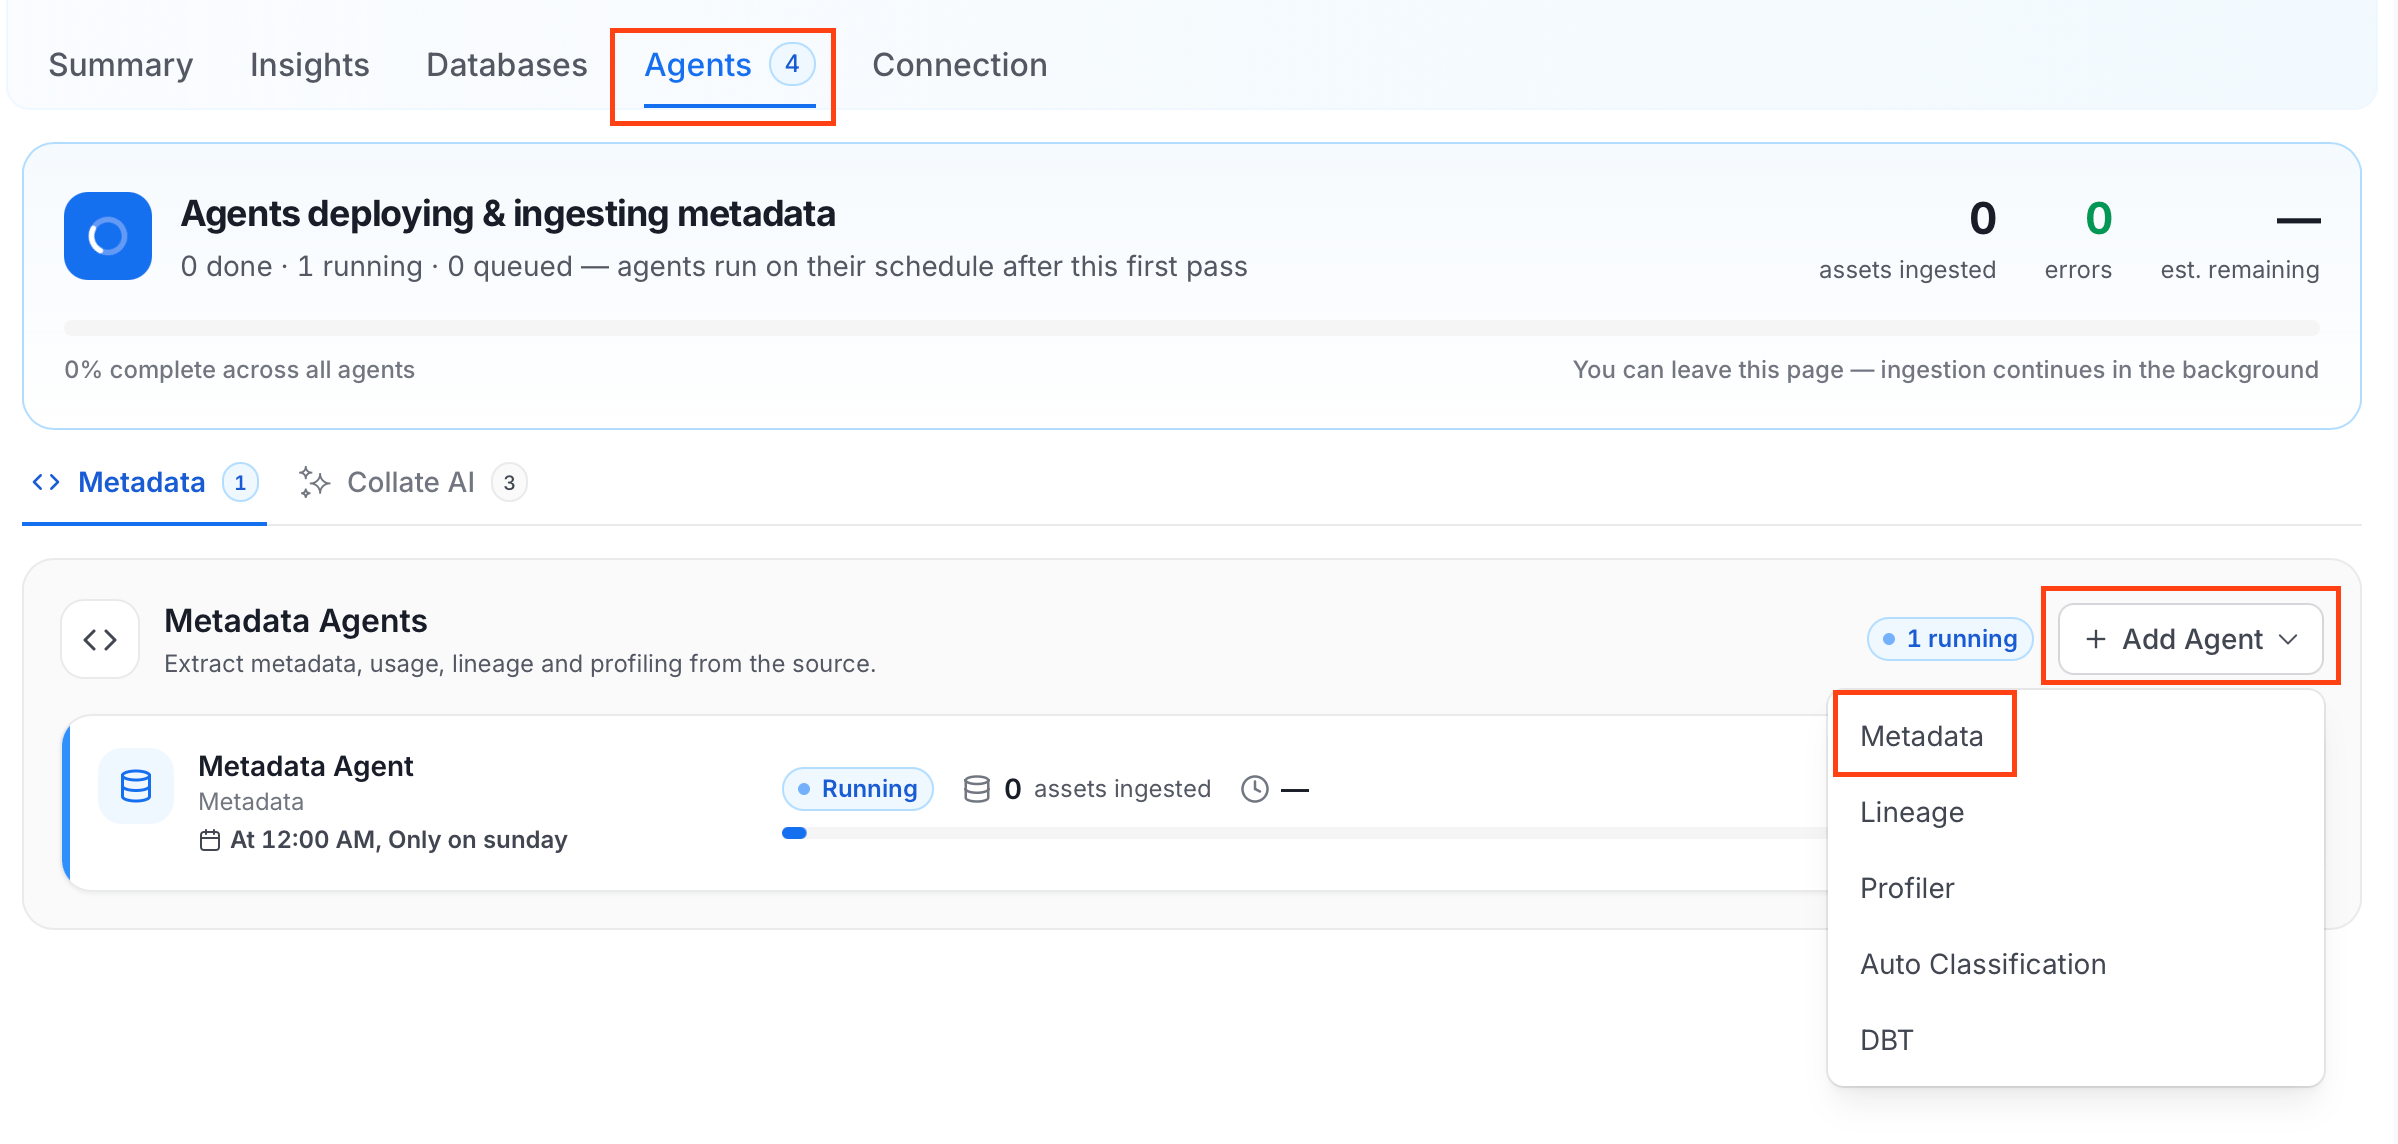
The Metadata Agent extracts schemas, tables, columns, and other structural metadata from your source and keeps your Collate catalog in sync. It powers discovery, lineage, and governance across your data assets. When you click Create & Deploy, Collate automatically deploys a Metadata Agent for this service and triggers the first ingestion run. View its status and run history from the Agents tab on the service detail page. To configure the additional Metadata Agent and schedule ingestion, follow these steps:- In the left navigation, click Connections and select your service.
- Click the Agents tab.
-
Click Add Agent and select Metadata from the dropdown.
-
On the Configure Ingestion page, do the following and click Next.
-
Name this Ingestion: Enter a unique, recognizable name for this ingestion pipeline.

-
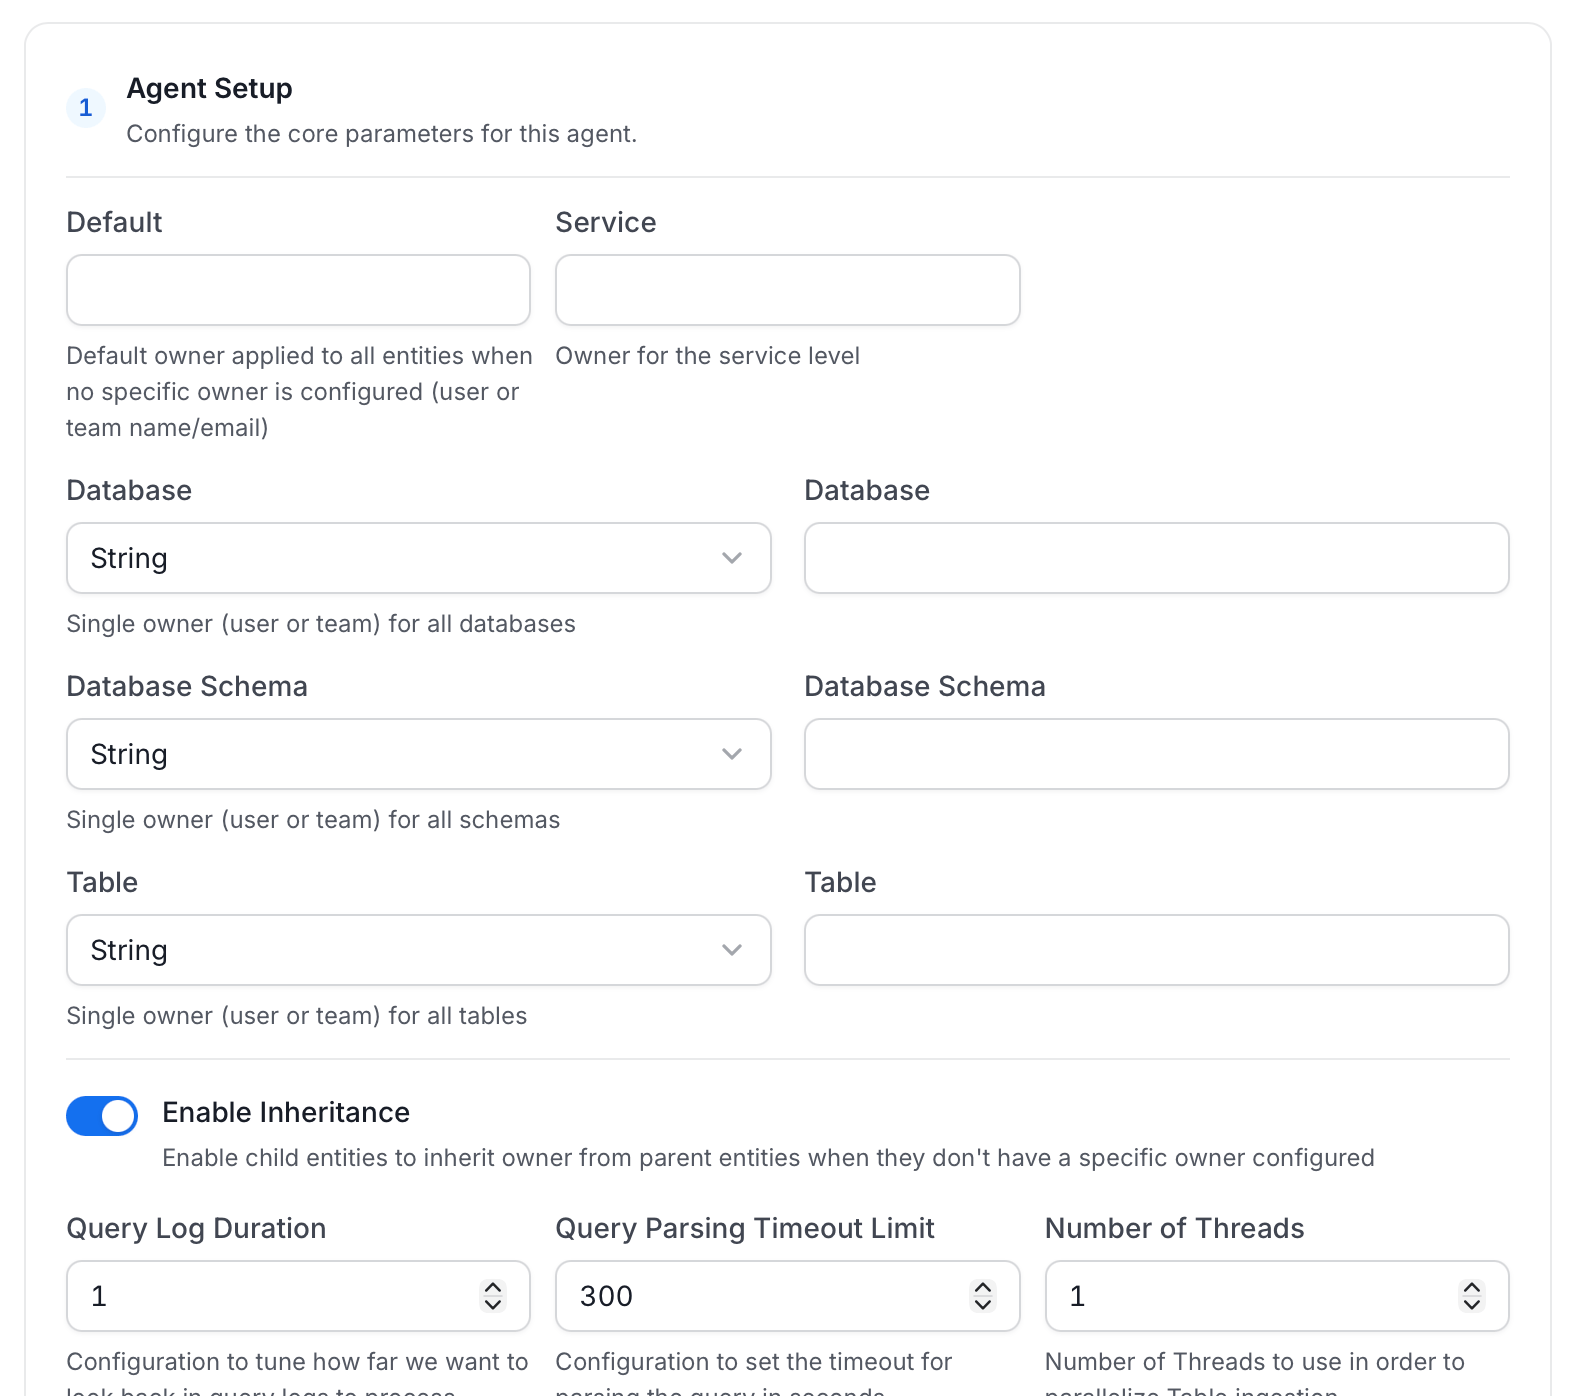
Agent Setup: Configure core parameters for metadata extraction. The following fields are available:
For more information, see Hierarchical Owner Configuration.
-
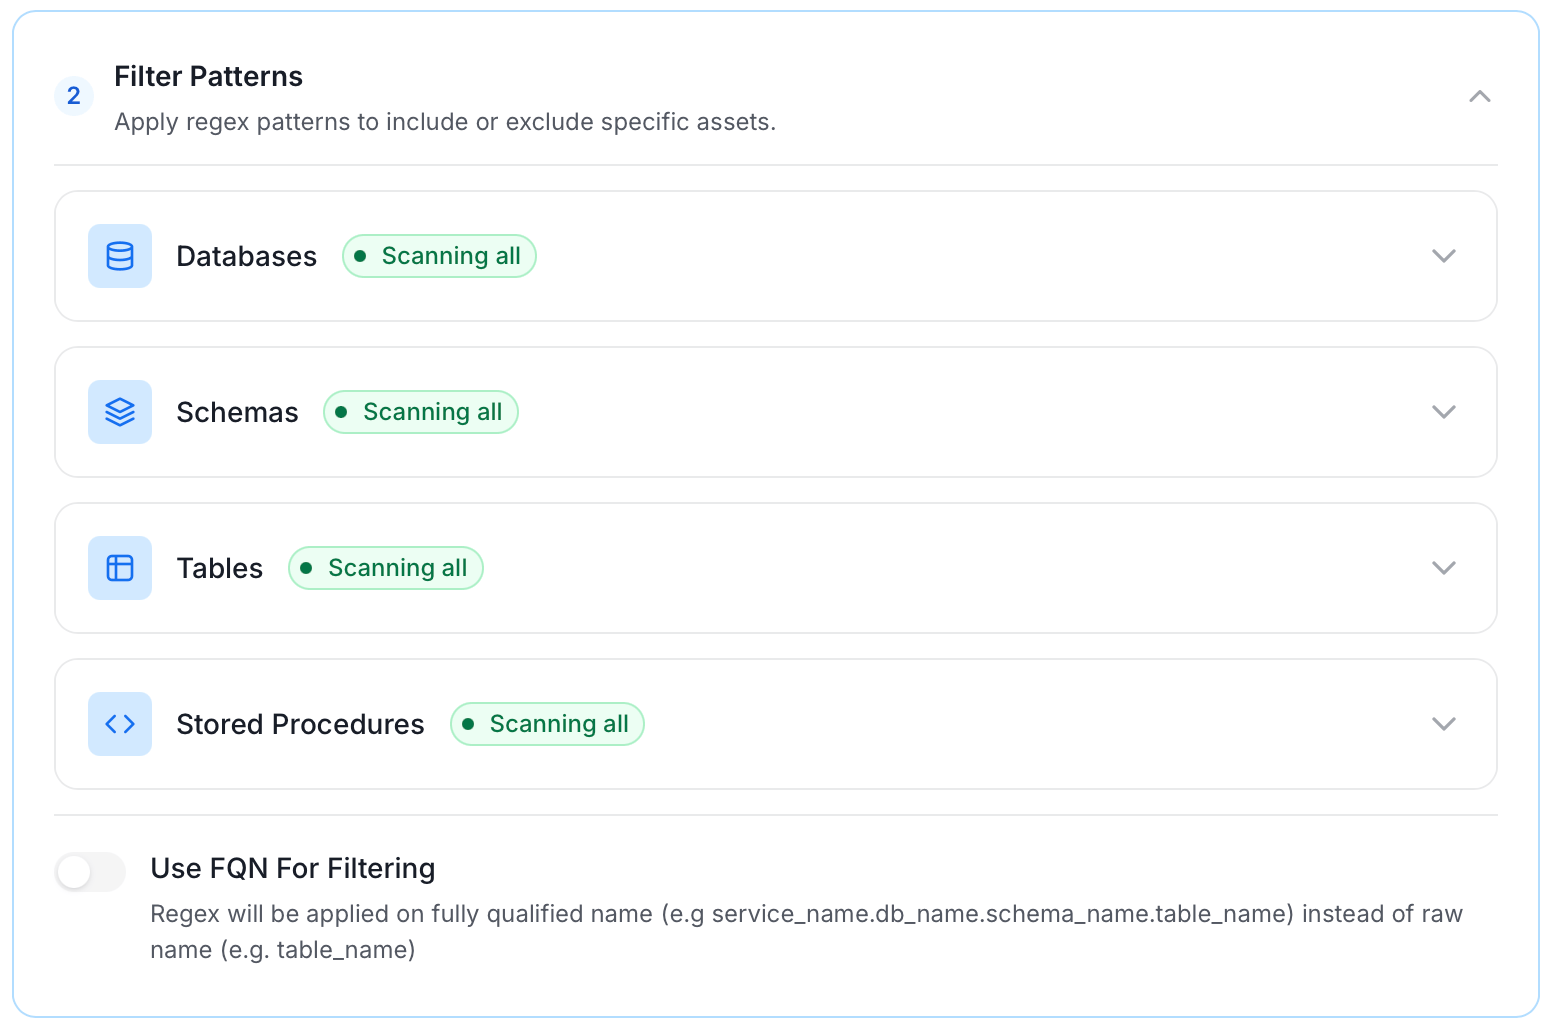
Filter Patterns: Apply include or exclude rules to scope which databases, schemas, tables, and stored procedures this agent ingests. These follow the same filter options described in Step 5.
-
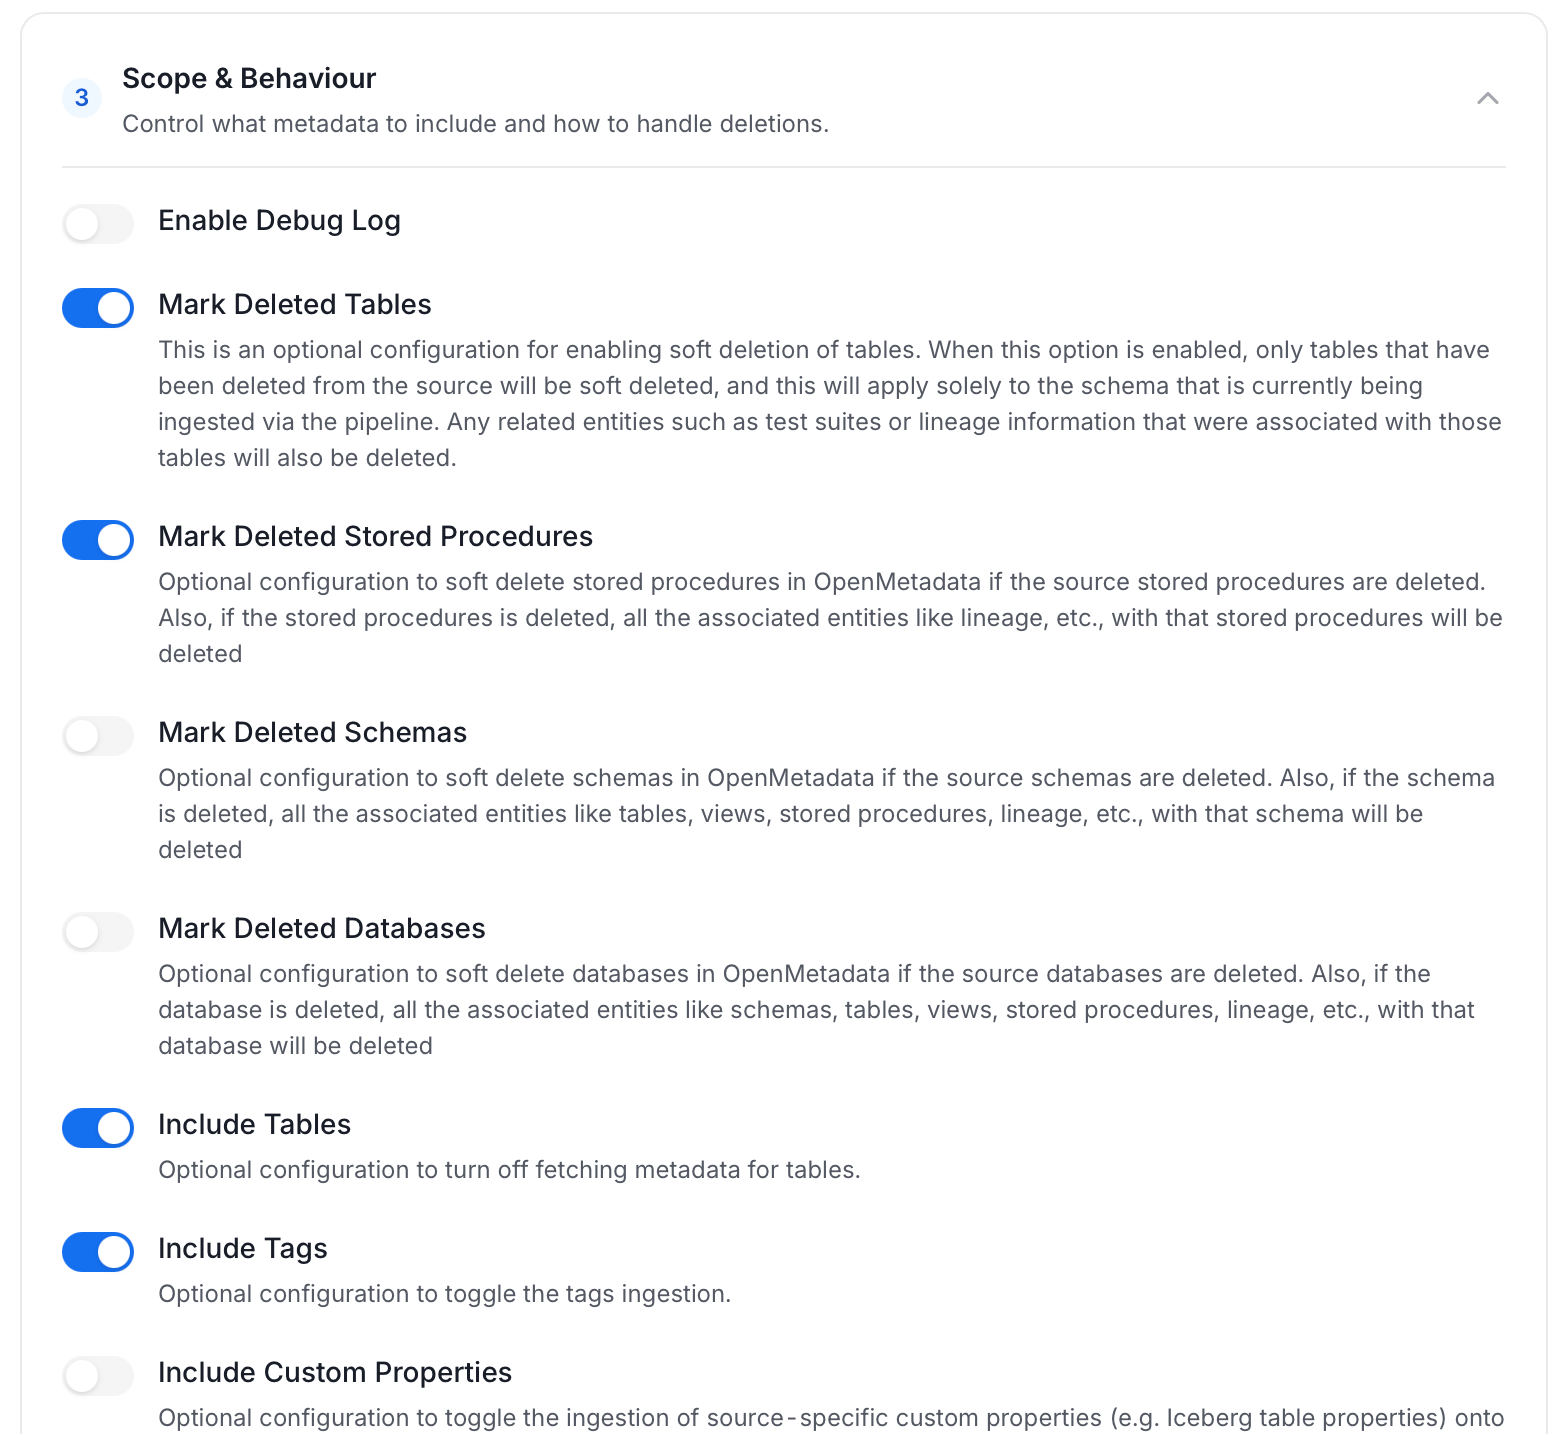
Scope & Behaviour: Control how the agent handles metadata during ingestion. Toggle each option on or off based on your needs:
Note: Available toggles vary by connector. Stored procedure options only appear for connectors that support stored procedures.
-
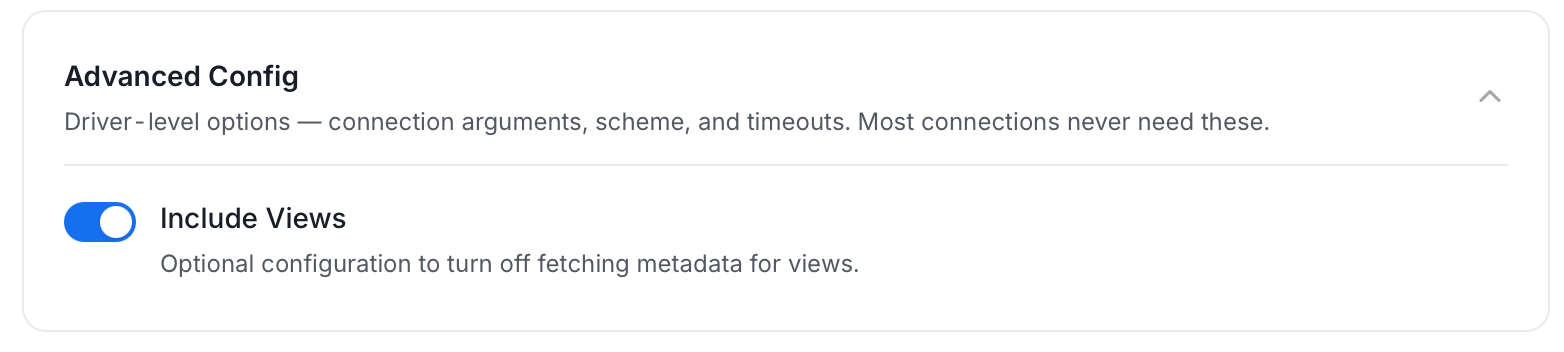
Advanced Config: Driver-level options (connection arguments, scheme, and timeouts). Most connections never need these, and they vary by connector. This section also has one ingestion-scope toggle:
-
Name this Ingestion: Enter a unique, recognizable name for this ingestion pipeline.
-
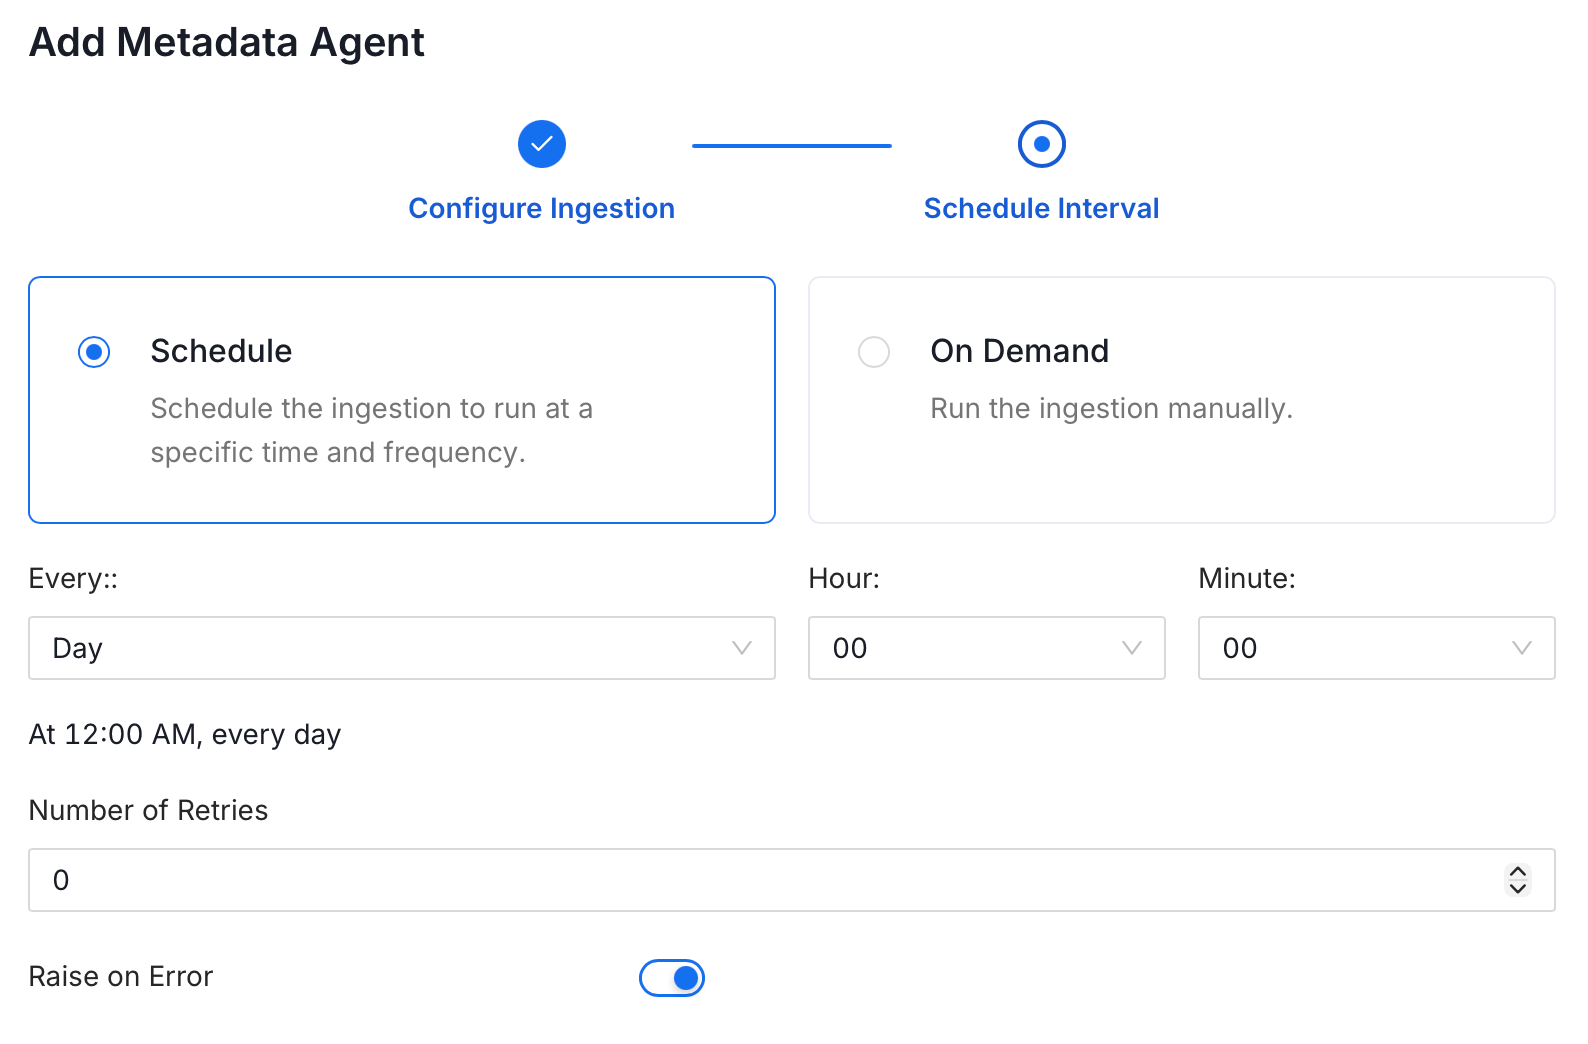
On the Schedule Interval page, set when the agent runs:
- Schedule: Choose a preset interval (Hourly, Daily, Weekly, Monthly) or enter a custom cron expression.
- On-Demand: No automatic schedule. Trigger the agent manually when needed.
- Click Add to deploy the agent.
Troubleshooting
ClickZetta Troubleshooting
Learn more about how to troubleshoot common ClickZetta connector issues and resolve configuration or ingestion errors.