
This section provides guides and references to use the Superset connector.
Configure and schedule Superset metadata and profiler workflows from the Collate UI:
Requirements
The ingestion also works with Superset 2.0.0. API Connection: To extract metadata from Superset via API, the user must have at leastcan read on Chart and can read on Dashboard permissions.
Database Connection: To extract metadata from Superset via MySQL or Postgres database, the database user must have at least SELECT privilege on the dashboards, tables, and slices tables within the Superset schema.
Metadata Ingestion
To ingest metadata from Superset, you need to create a service connection. The service connects Superset with Collate. Once you create a service, Collate automatically starts ingesting metadata.Step 1: Add New Service
Open the Services page and start a new service.-
Navigate to Settings > Services and select Dashboard Services.
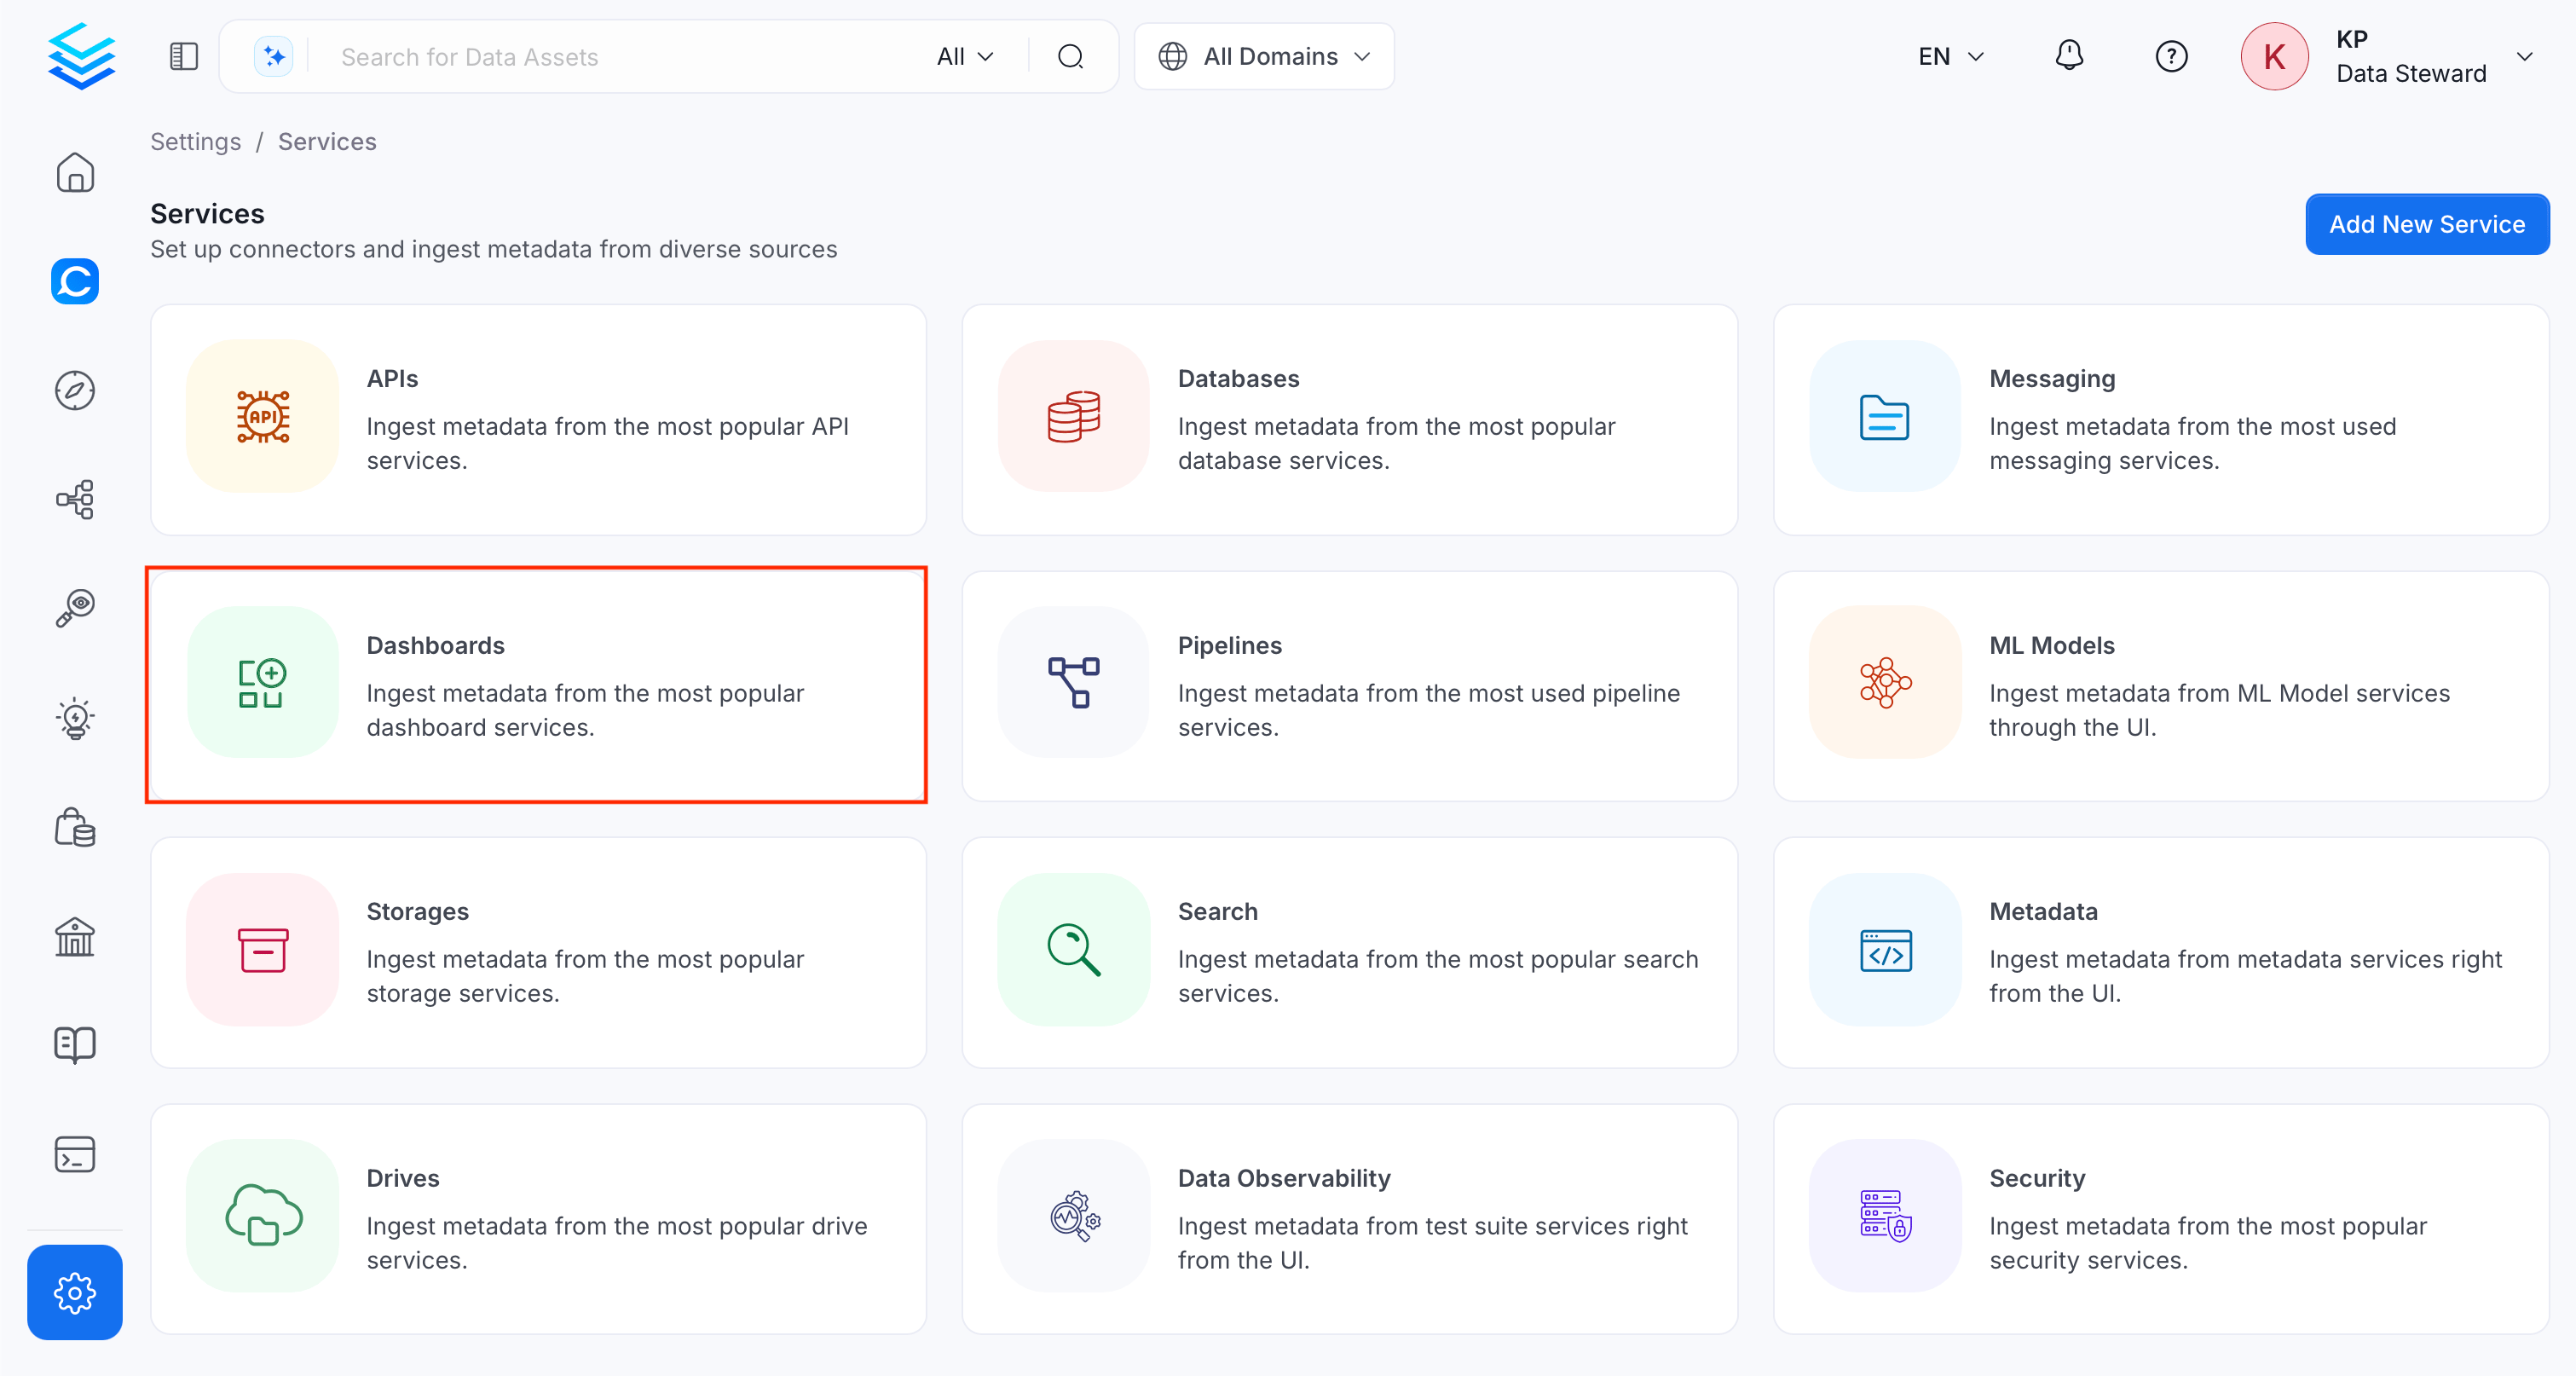
-
Click Add New Service.
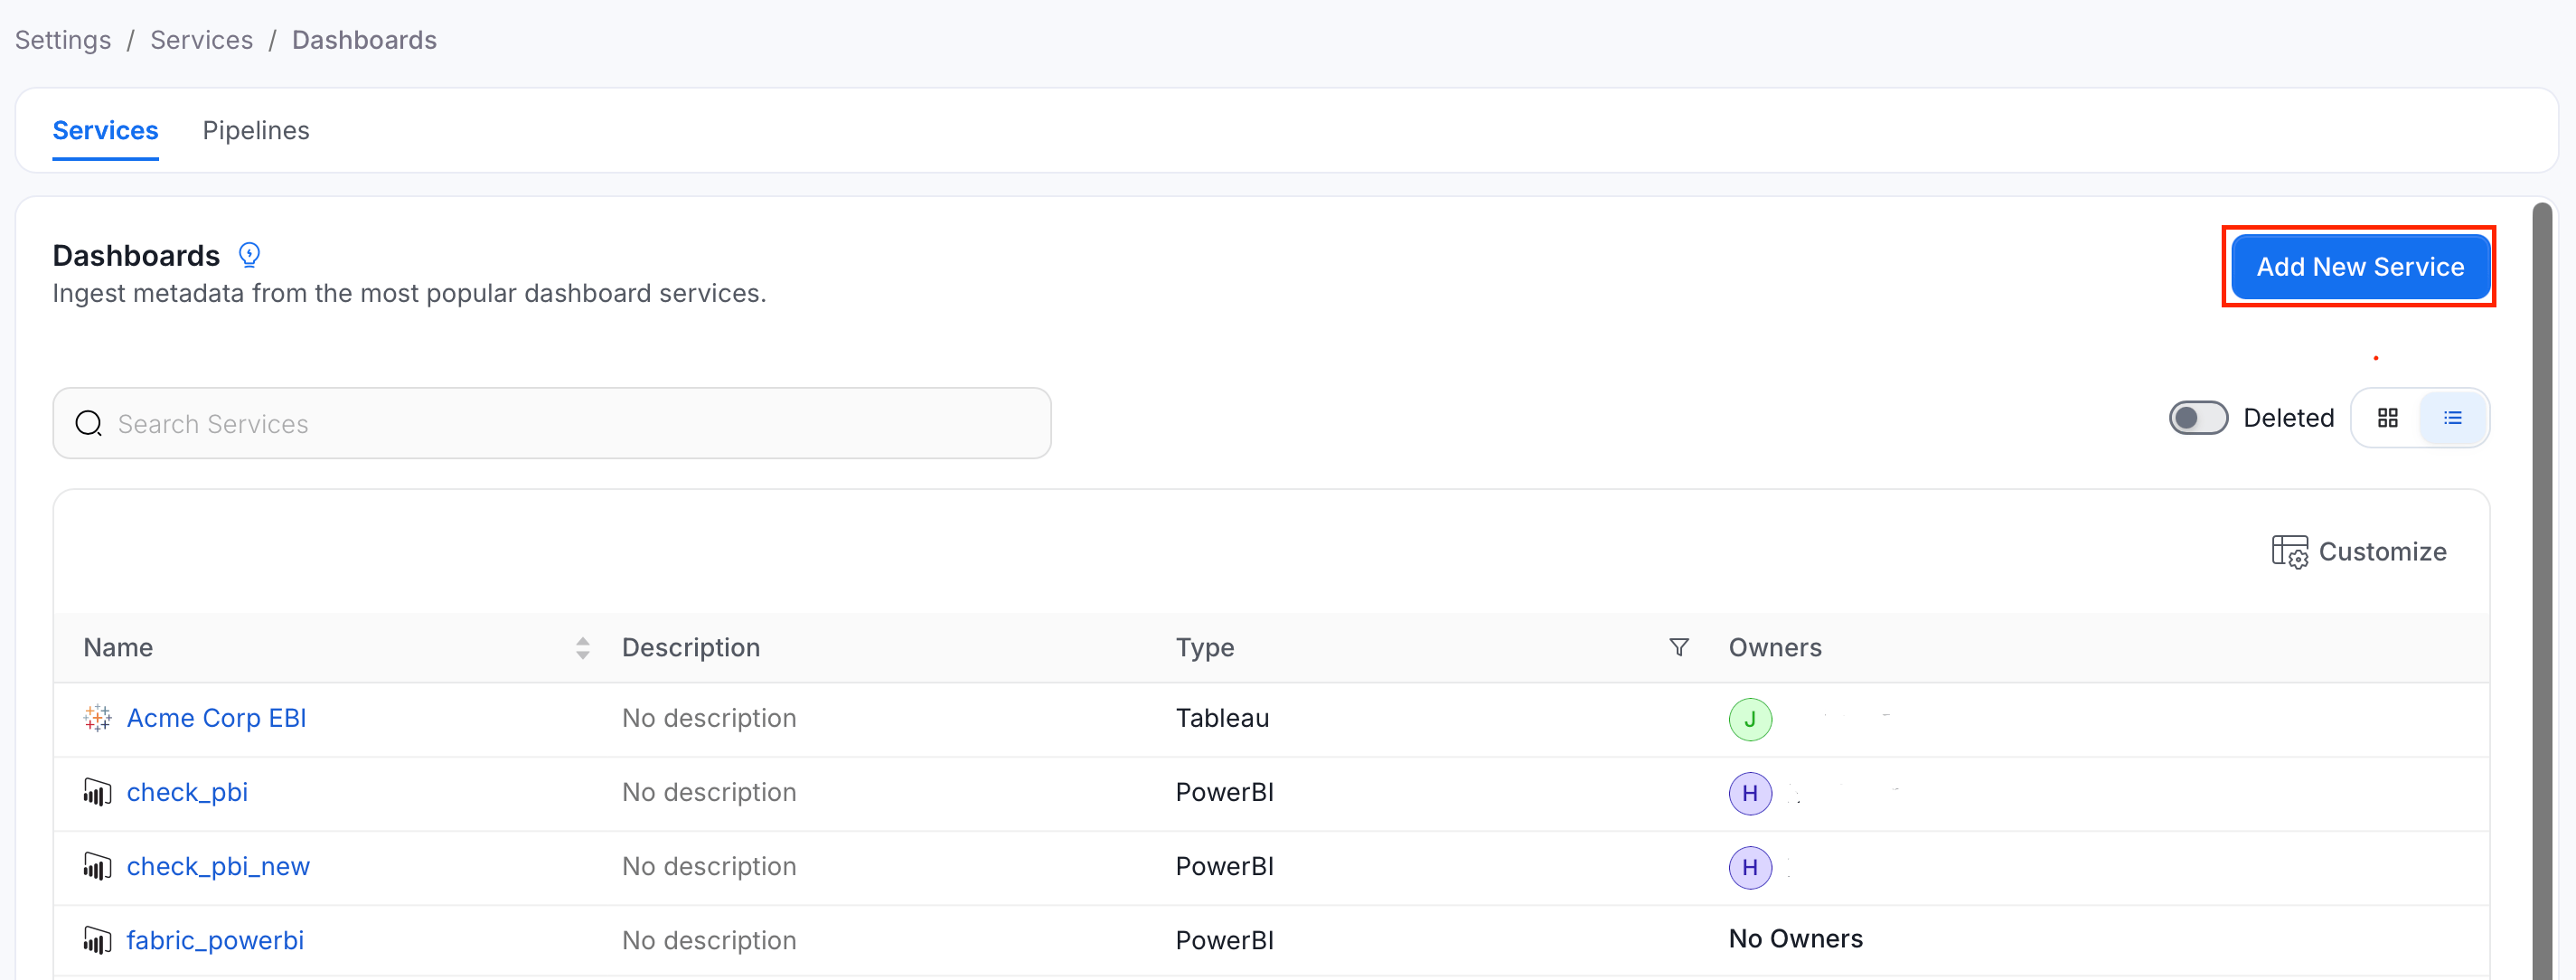
Step 2: Select a Service and Connector
From the service type dropdown, select Dashboard Services, then click the Superset connector tile.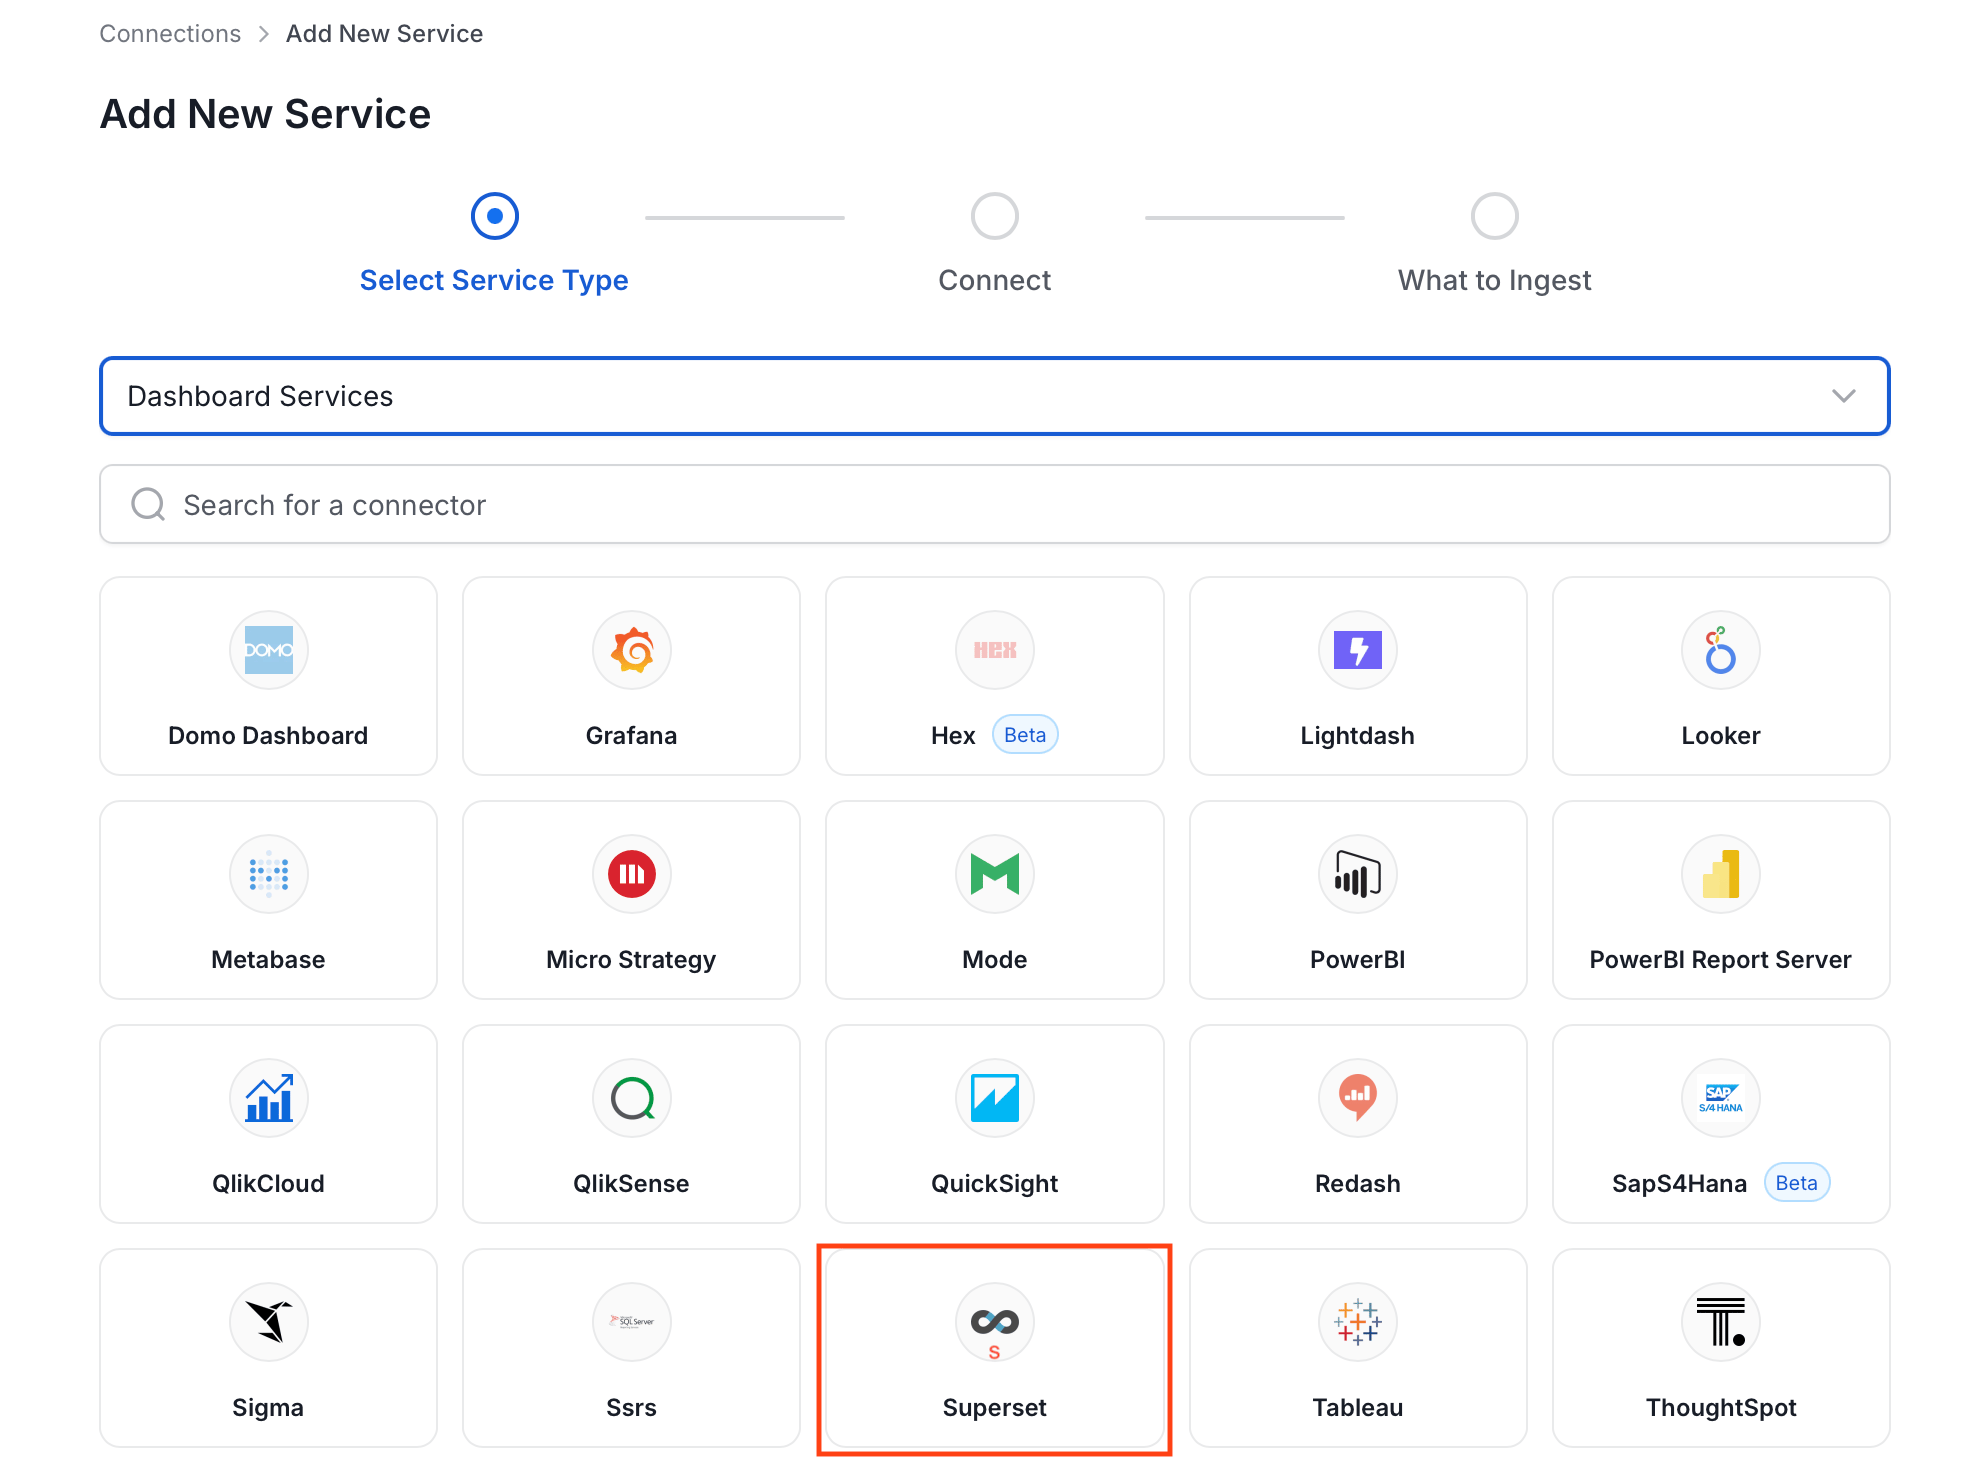
Step 3: Add Service Name and Description
- Enter a unique, descriptive Service Name. Collate identifies services by their service name. Enter a name that distinguishes this deployment from other Superset services you are ingesting metadata from.
- Optional: Enter a Description for the service.
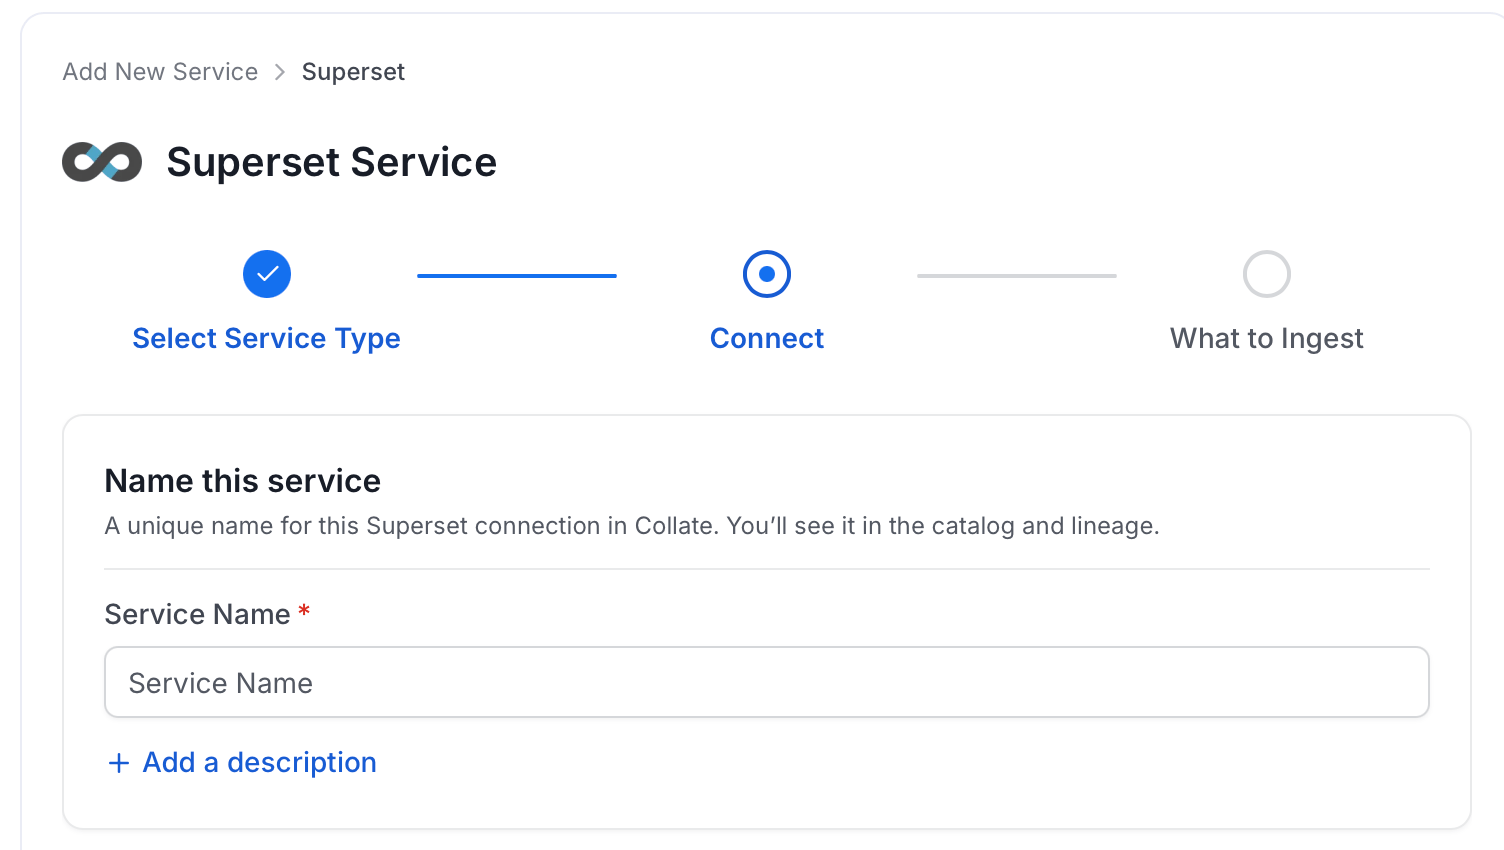
Note: The service name can’t be changed after you set it.
Step 4: Configure Connection Options
Specify where ingestion runs, provide your source credentials, and verify the connection.Select Ingestion Runner
Select an Ingestion Runner: the runner where the ingestion pipeline will execute.
Enter Connection Details
Enter the connection details for Superset. The right-hand panel in the UI displays inline help for each field.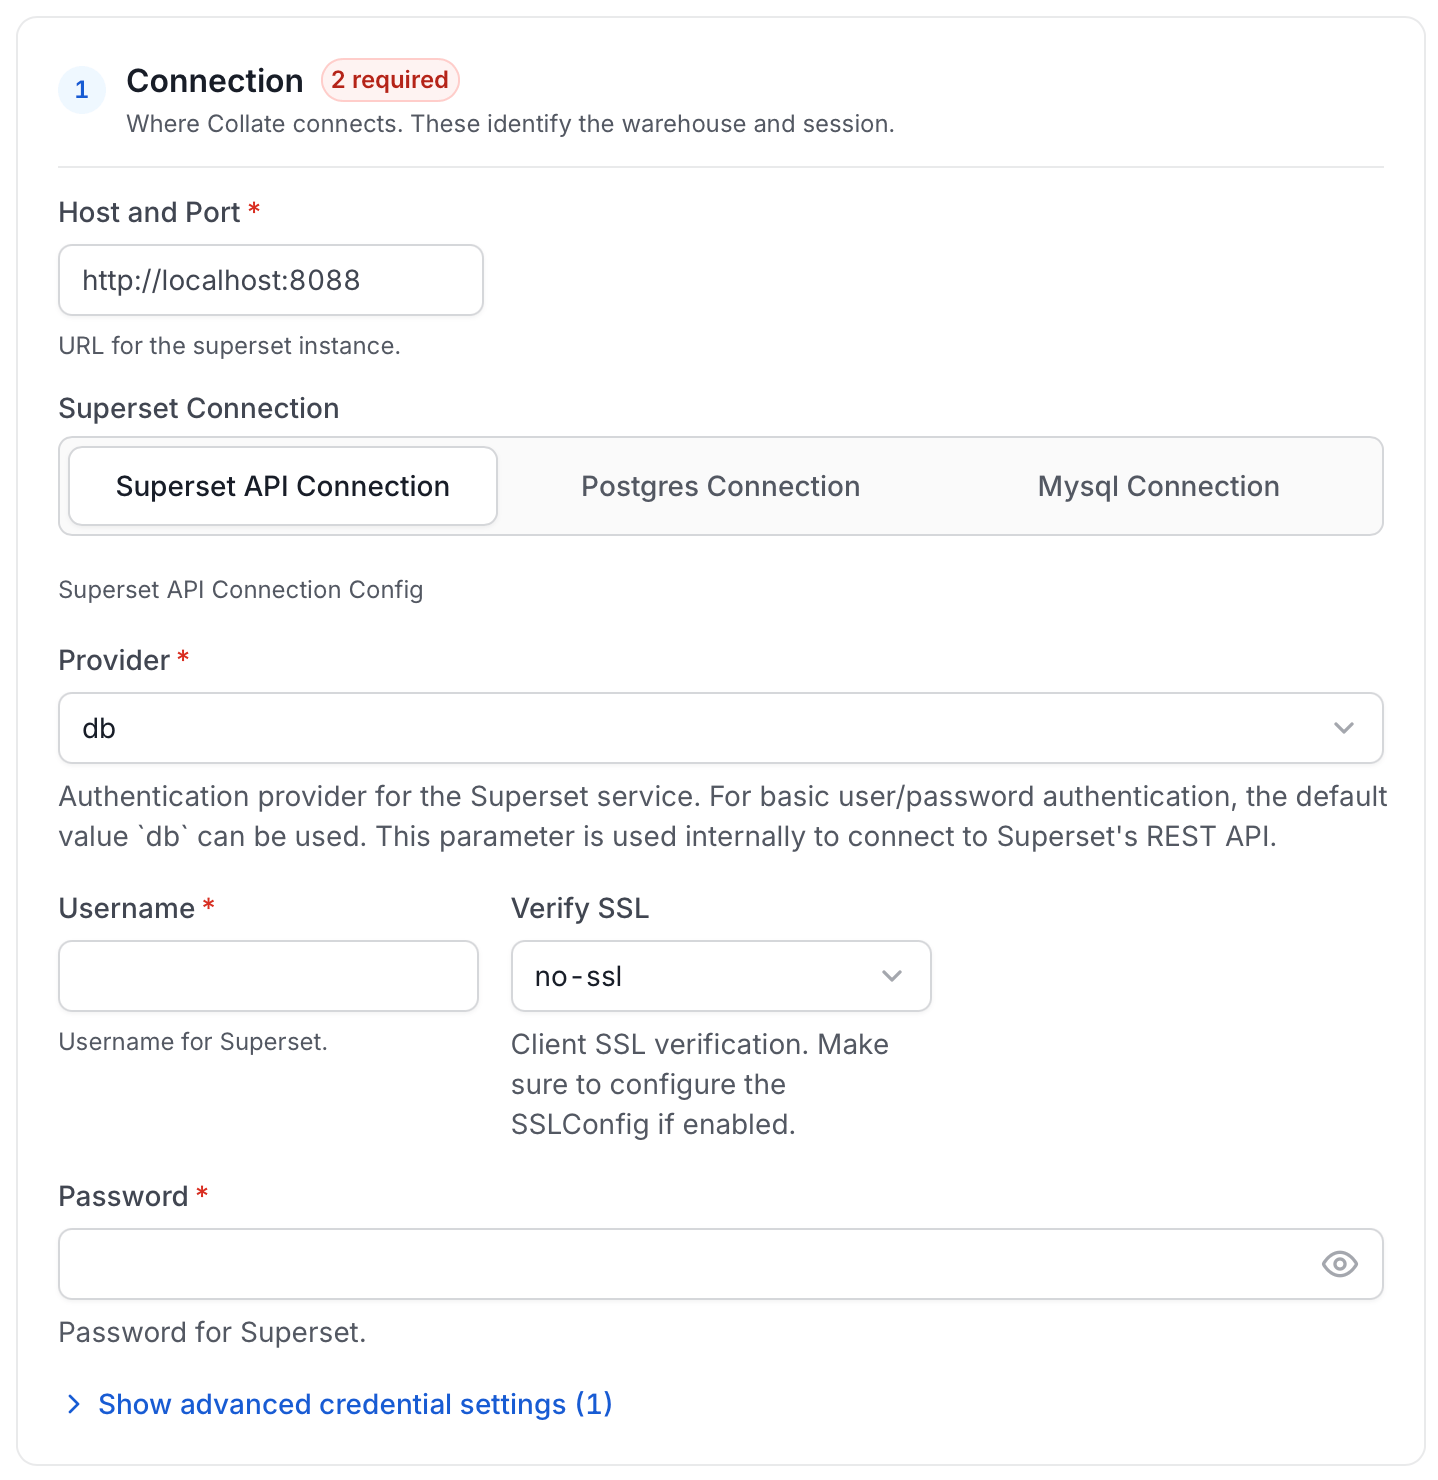
- Host and Port: The
Host and Portparameter is common to all three authentication modes and specifies the host and port of the Superset instance. This should be specified as a string in the formathttp://hostname:portorhttps://hostname:port. For example, you might set the hostPort parameter tohttps://org.superset.com:8088. - Superset Connection: Add the connection details to fetch metadata from Superset either through APIs or a database.
For Superset API Connection
Superset API connection is the default authentication mode. It fetches metadata using the Superset APIs.- Username: Username to connect to Superset, for ex.
user@organization.com. This user should have access to relevant dashboards and charts in Superset to fetch the metadata. - Password: Password of the user account to connect with Superset.
- Provider: Choose between
db(default) orldapmode of Authentication provider for the Superset service. This parameter is used internally to connect to Superset’s REST API. - Verify SSL:
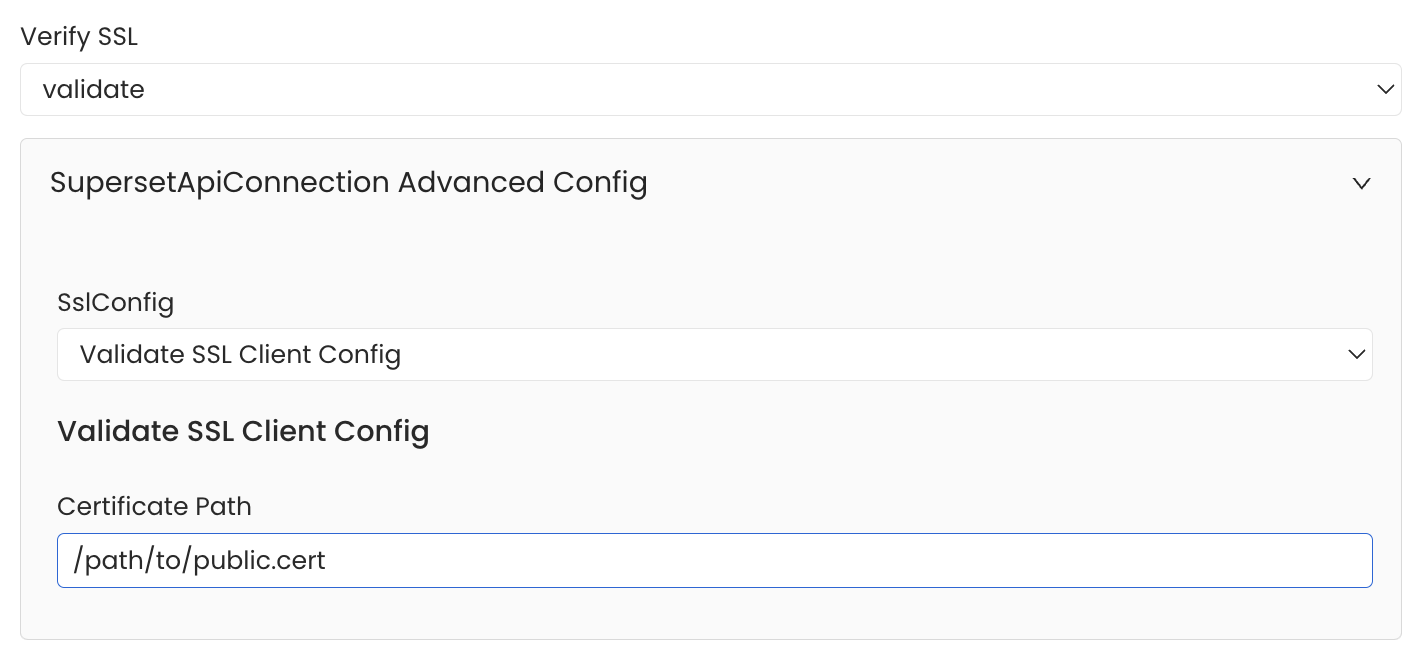
Client SSL verification. Make sure to configure the SSLConfig if enabled.
Possible values:
validate: Validate the certificate using the public certificate (recommended).ignore: Ignore the certification validation (not recommended for production).no-ssl: SSL validation is not needed.
- SSL Config: Client SSL configuration in case you are connecting to a host with SSL enabled.
- Certificate Path: CA certificate path in the instance where the ingestion run. E.g.,
/path/to/public.cert. Will be used if Verify SSL is set tovalidate.
For MySQL Connection
Use a MySQL connection when you have SSO enabled and your Superset instance is backed by a MySQL database.- Username: Specify the user to connect to MySQL. It should have enough privileges to read all the metadata. Make sure the user has select privileges on the
dashboards,tables, andslicestables of the Superset schema. - Password: Password to connect to MySQL.
- Host and Port: Enter the fully qualified hostname and port number for your MySQL deployment in the Host and Port field.
- databaseSchema: Enter the database schema which is associated with the Superset instance.
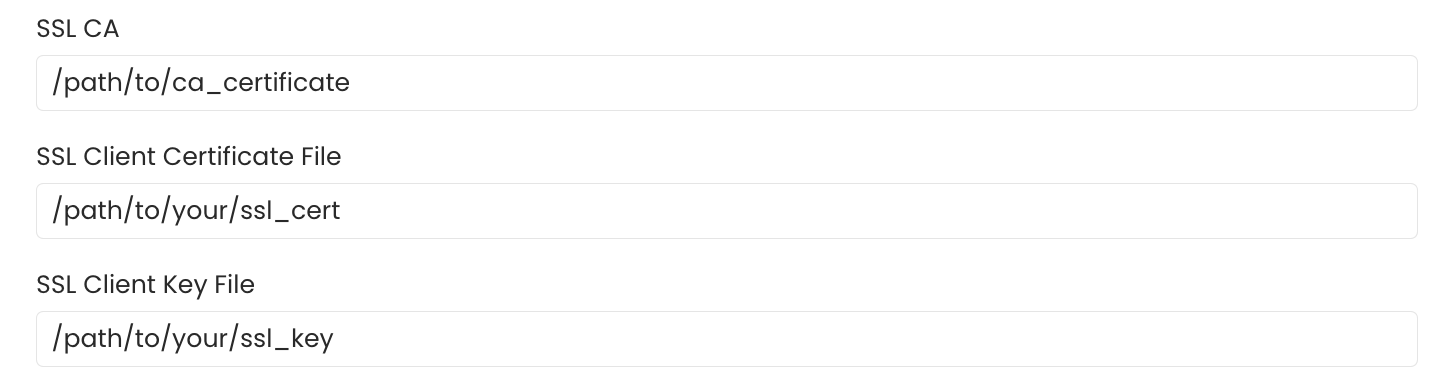
- caCertificate: Provide the path to ssl ca file.
- sslCertificate: Provide the path to ssl client certificate file (ssl_cert).
- sslKey: Provide the path to ssl client certificate file (ssl_key).
For Postgres Connection
Use a Postgres connection when you have SSO enabled and your Superset instance is backed by a Postgres database.- Username: Specify the user to connect to Postgres. Make sure the user has select privileges on the
dashboards,tables, andslicestables of the Superset schema. - Password: Password to connect to Postgres.
- Host and Port: Enter the fully qualified hostname and port number for your Postgres deployment in the Host and Port field.
- Database: Initial Postgres database to connect to. Specify the name of the database associated with the Superset instance.
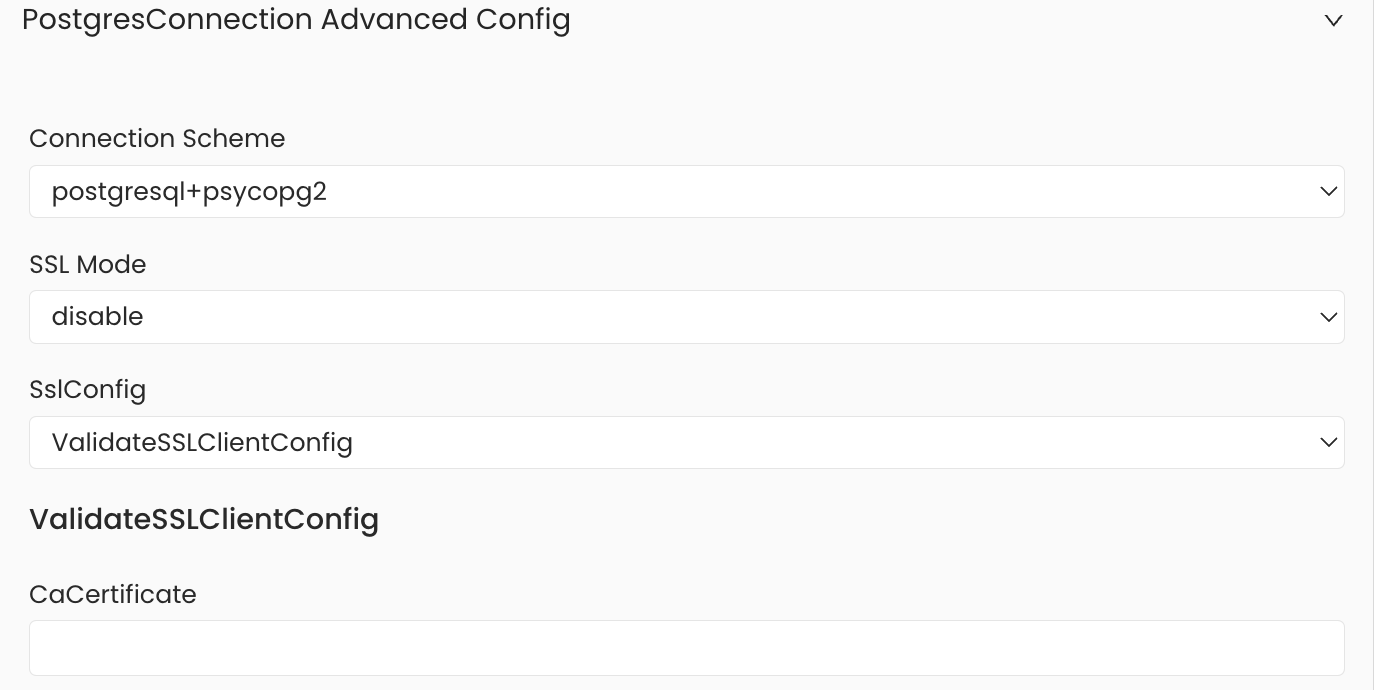
- caCertificate: Provide the path to the SSL CA file.
Advanced Configuration
Database Services include an Advanced Configuration section for passing extra arguments to the connector and, if needed, changing the connection scheme. This is only needed for advanced connectivity scenarios or customizations.- Connection Options (Optional): Enter the details for any additional connection options that can be sent to the database during the connection. These details must be added as key-value pairs.
- Connection Arguments (Optional): Enter the details for any additional connection arguments such as security or protocol configs that can be sent during the connection. These details must be added as key-value pairs.
Test Connection
- Click Test Connection to verify the credentials.
- After the test succeeds, click Save.
Step 5: Configure Ingestion Options
In the What to Ingest step, use filter patterns to control which assets Collate ingests from your dashboard service. Filter rules match asset names using the following match types.How Filter Patterns Work
- Include: Add one or more comma-separated values. Each value uses one of the following match types. Collate ingests only assets whose names match at least one rule. Leave blank to include all assets.
- Exclude: Add one or more comma-separated values. Each value uses one of the following match types. Collate skips any asset whose name matches a rule. Leave blank to exclude nothing.
- contains: matches any name containing the value. For example,
salesmatchesmy_sales_dataandsales_2024. - starts with: matches names beginning with the value. For example,
prod_matchesprod_dbandprod_schema. - ends with: matches names ending with the value. For example,
_rawmatchesevents_rawandlogs_raw. - is exactly: matches the exact name only. For example,
analyticsmatches onlyanalytics. - matches regex: matches names using a regular expression. For example,
^prod_.*_v\d+$matchesprod_events_v1.
Filter Options
The Dashboard and Chart sections each include the following filter options:- Dashboard: Controls which dashboards Collate ingests from the source.
- Chart: Controls which charts within the ingested dashboards are included.
- Scan Mode: Choose between the following scan modes:
- Scan all: Ingests every asset of that type the connector can access. This is the default.
- Only specific: Enables include rules so only assets matching at least one rule are ingested.
- Exclude system toggle: Use this toggle to filter out system-reserved names defined by the connector for that asset type.
- Always exclude: Add permanent exclusion rules (shown in red). Assets matching these rules are never ingested, regardless of include rules.
- Preview: Shows a real-time summary of what will be in scope based on your current rules.
- Include rules: In Only specific mode, click + Add to define a rule. Added rules appear as chips. An asset is included if it matches any rule.
Step 6: Create & Deploy
Click Create & Deploy to deploy the agent and start the first metadata ingestion run. Collate saves the service configuration and immediately begins pulling metadata from the source. To monitor ingestion progress or view the service you just added, go to Settings > Services and select your service.Configure Metadata Agent and Schedule Ingestion
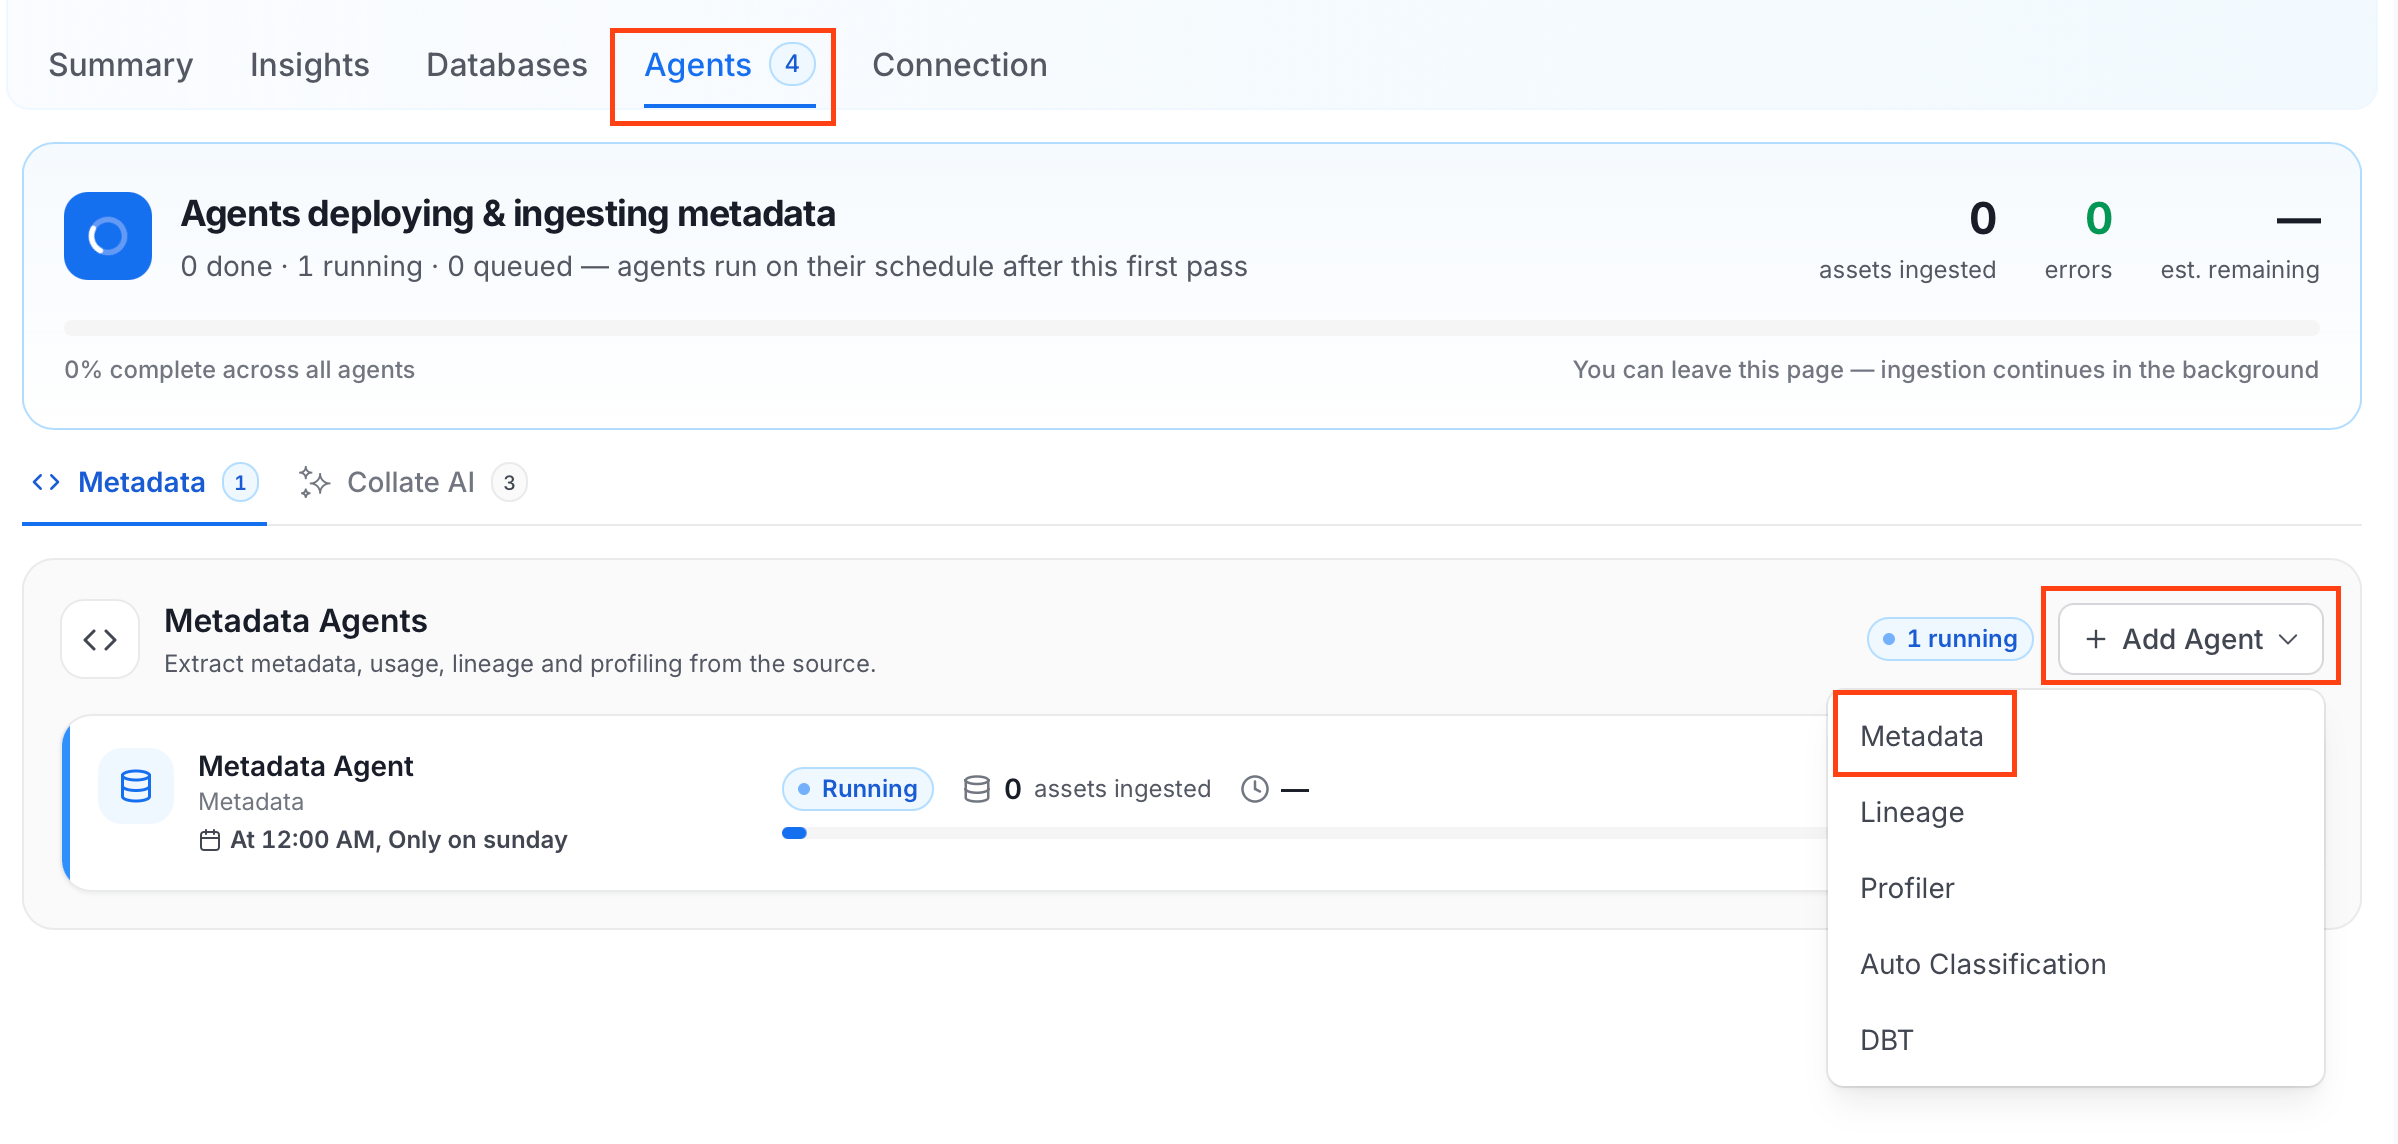
The Metadata Agent extracts dashboards, charts, data models, and other structural metadata from your source and keeps your Collate catalog in sync. It powers discovery, lineage, and governance across your data assets. When you click Create & Deploy, Collate automatically deploys a Metadata Agent for this service and triggers the first ingestion run. View its status and run history from the Agents tab on the service detail page. To configure the additional Metadata Agent and schedule ingestion, follow these steps:- Navigate to Settings > Services and select the Dashboards service.
- Select your service and click the Agents tab.
-
Click Add Agent and select Metadata from the dropdown.
-
On the Configure Ingestion page, do the following and click Next.
-
Name this Ingestion: Enter a unique, recognizable name for this ingestion pipeline.

-
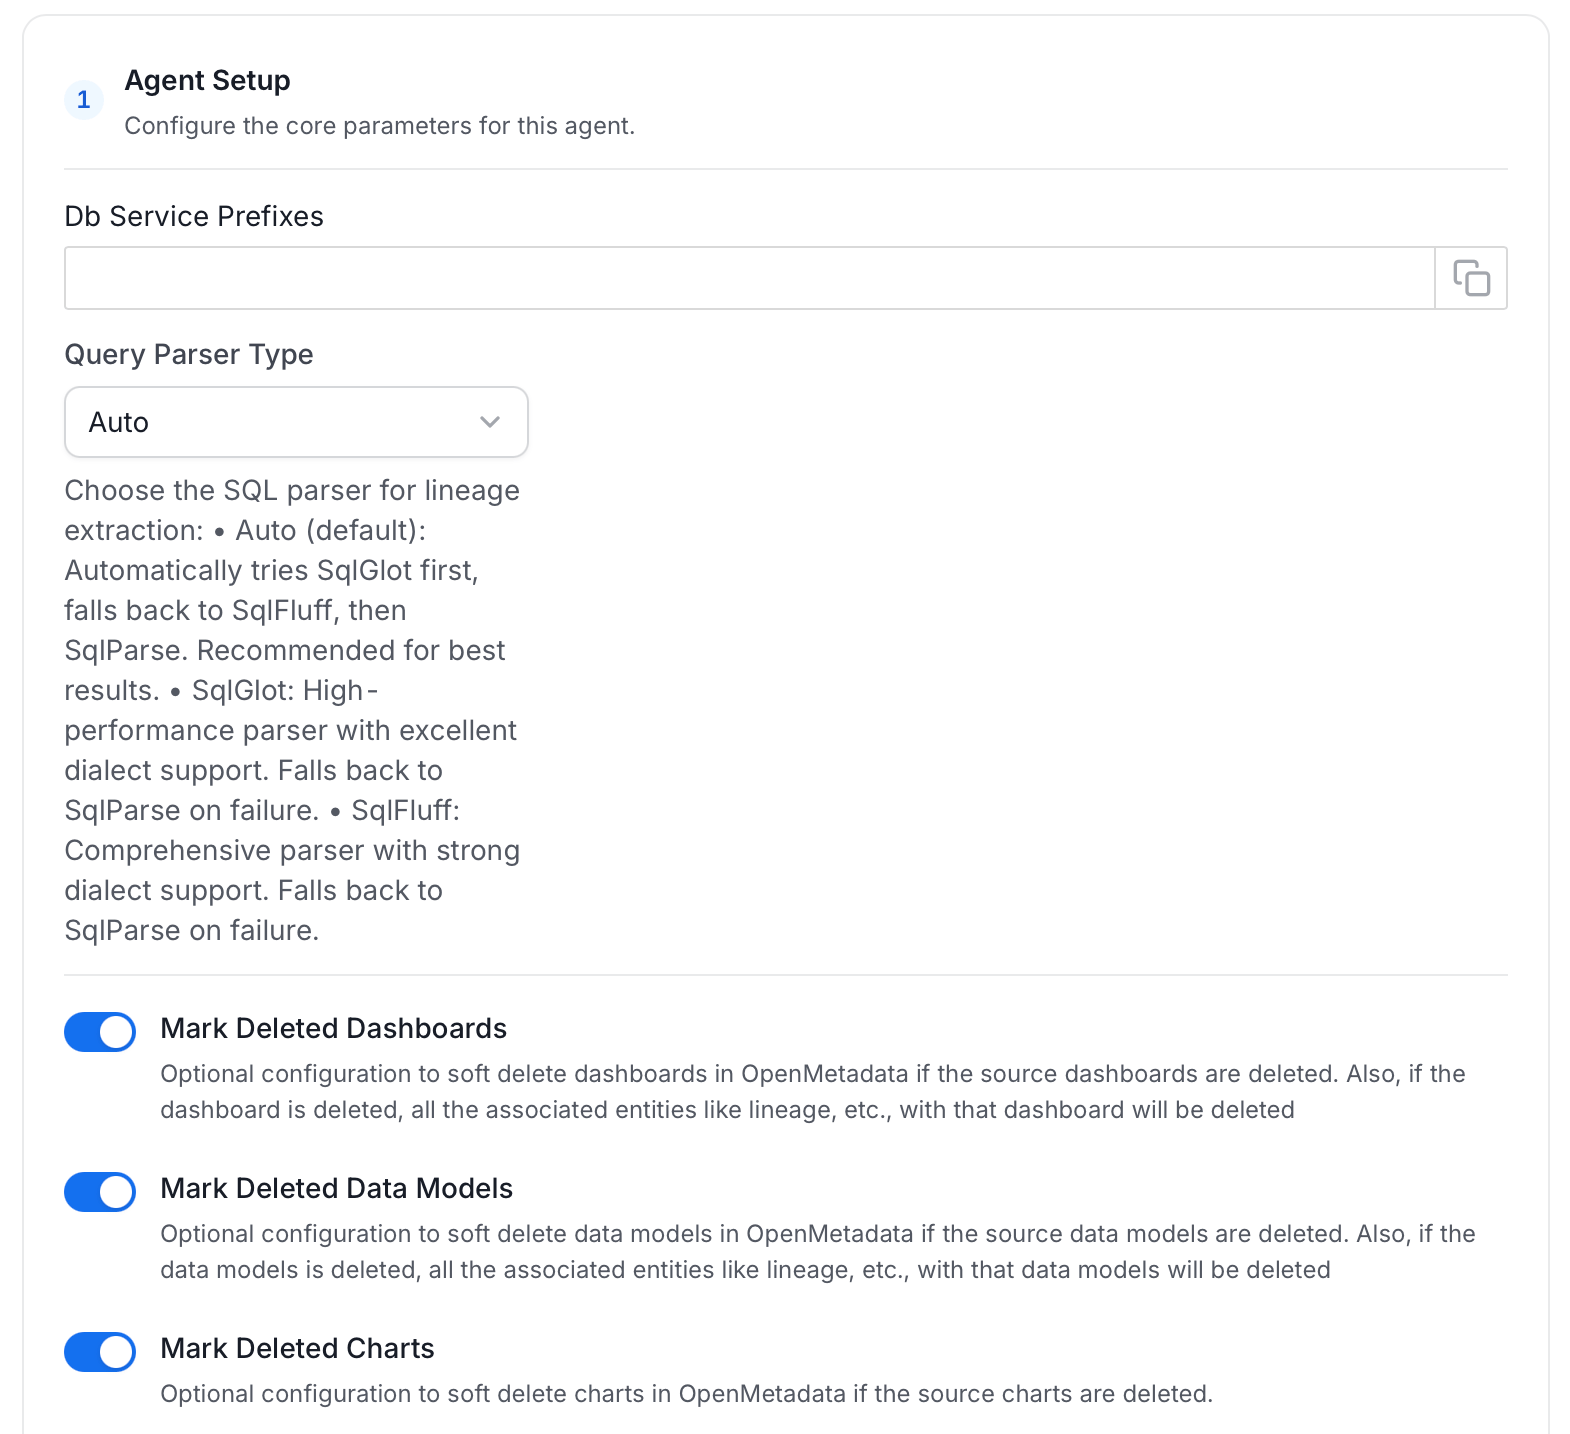
Agent Setup: Configure ingestion parameters. The following fields are available:
-
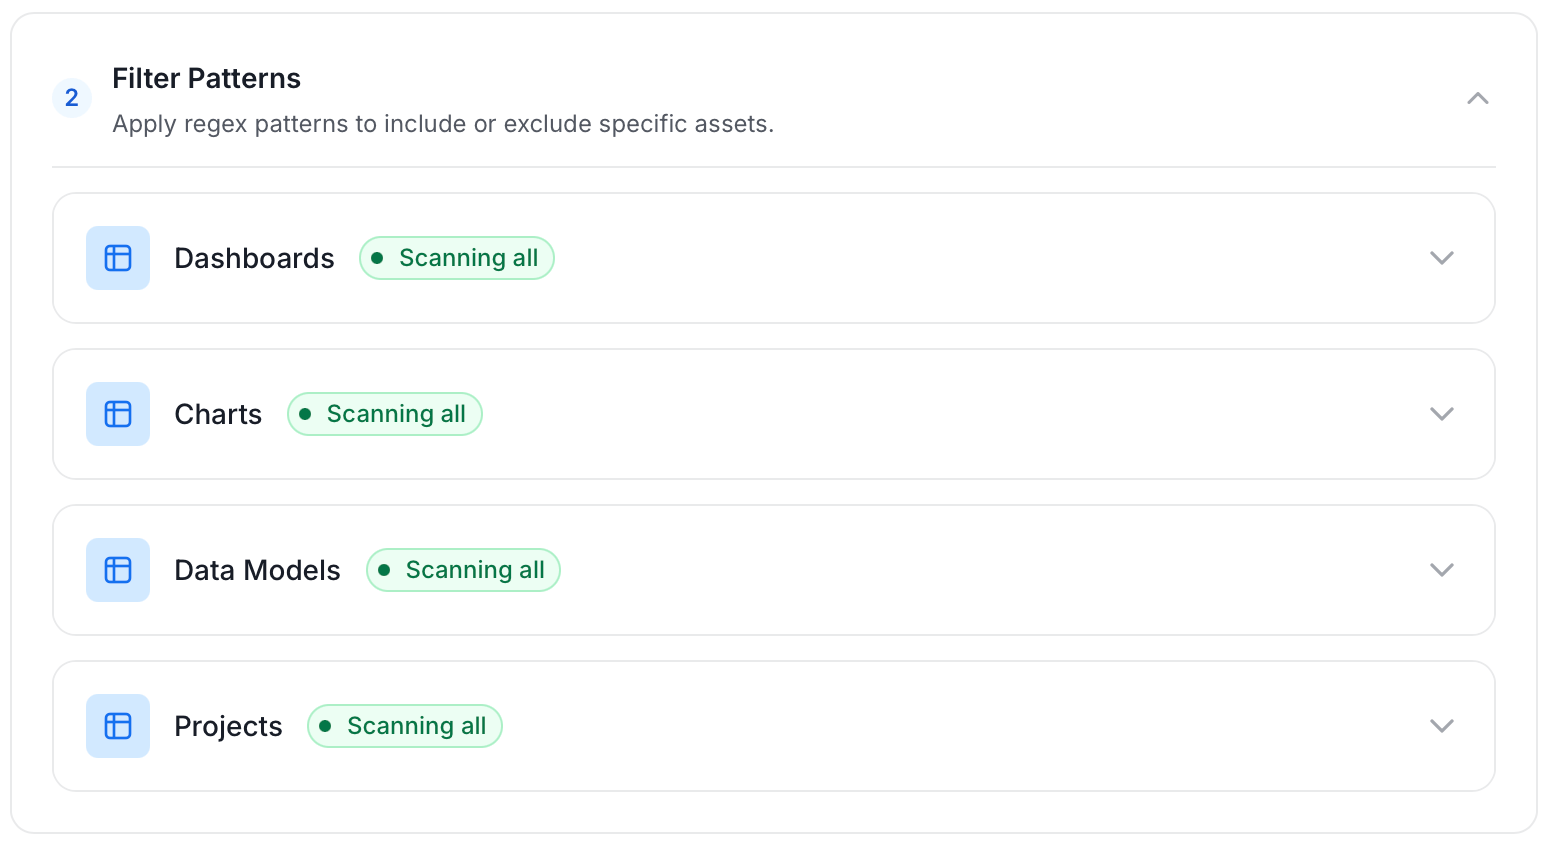
Filter Patterns: Apply include or exclude rules to scope which dashboards, charts, data models, and projects this agent ingests. These follow the same filter options described in Step 5.
-
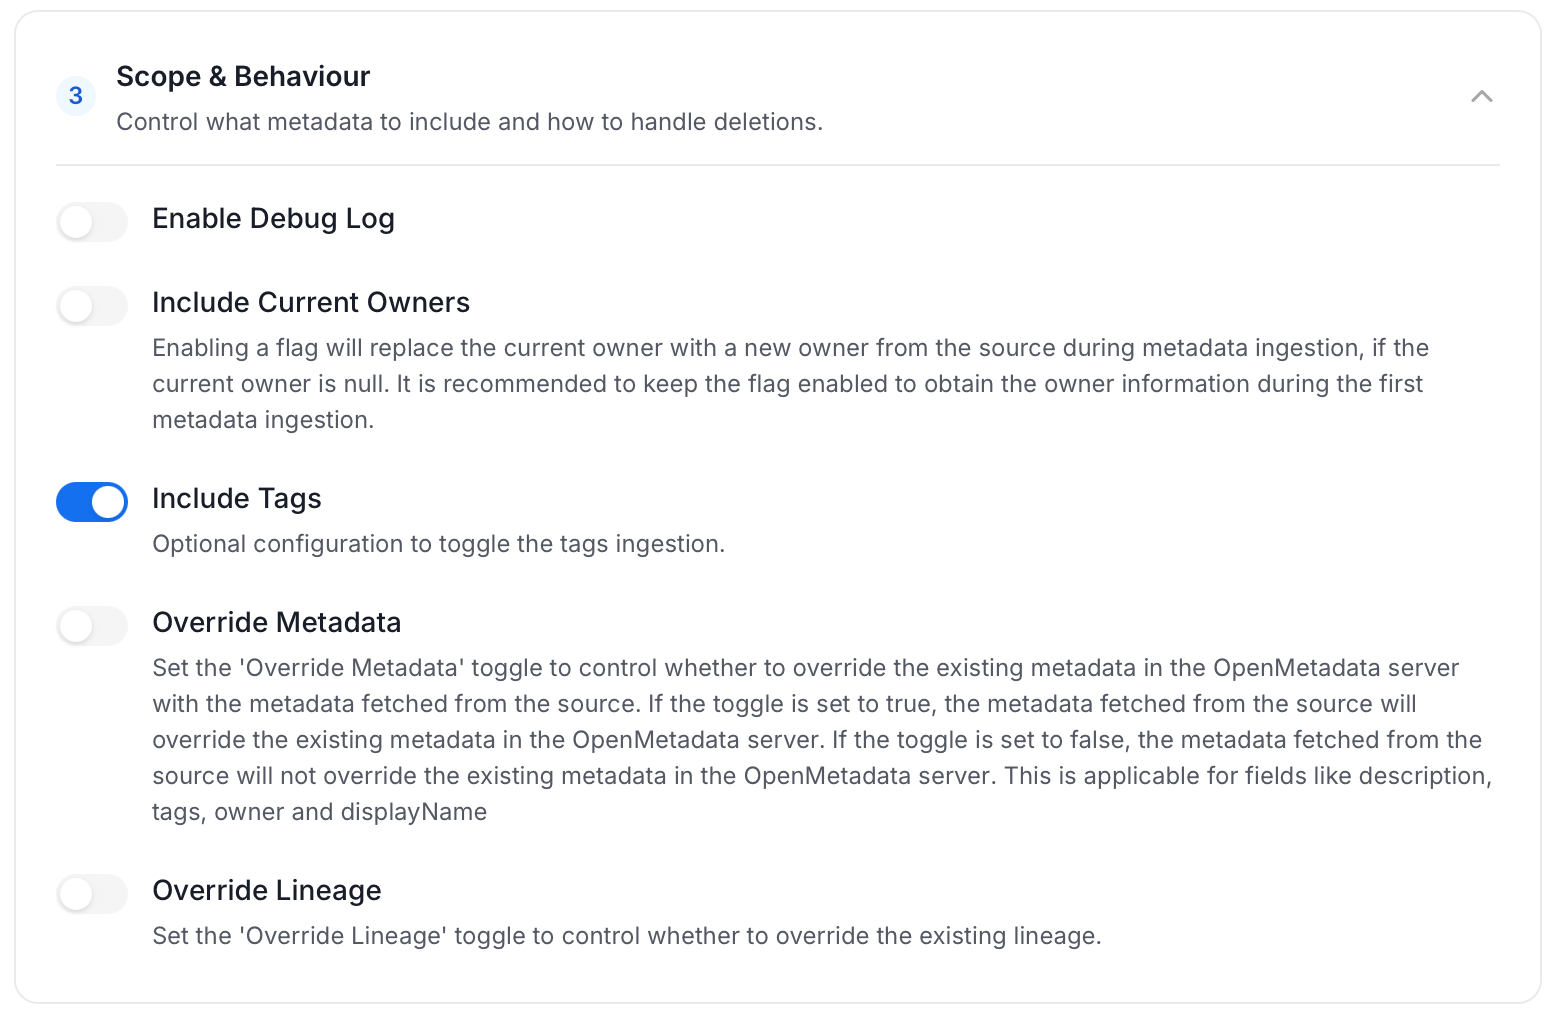
Scope & Behaviour: Control what metadata to include and how to handle deletions. Toggle each option on or off based on your needs:
-
Name this Ingestion: Enter a unique, recognizable name for this ingestion pipeline.
-
On the Schedule Interval page, set when the agent runs:
- Schedule: Choose a preset interval (Hourly, Daily, Weekly, Monthly) or enter a custom cron expression.
- On-Demand: No automatic schedule. Trigger the agent manually when needed.
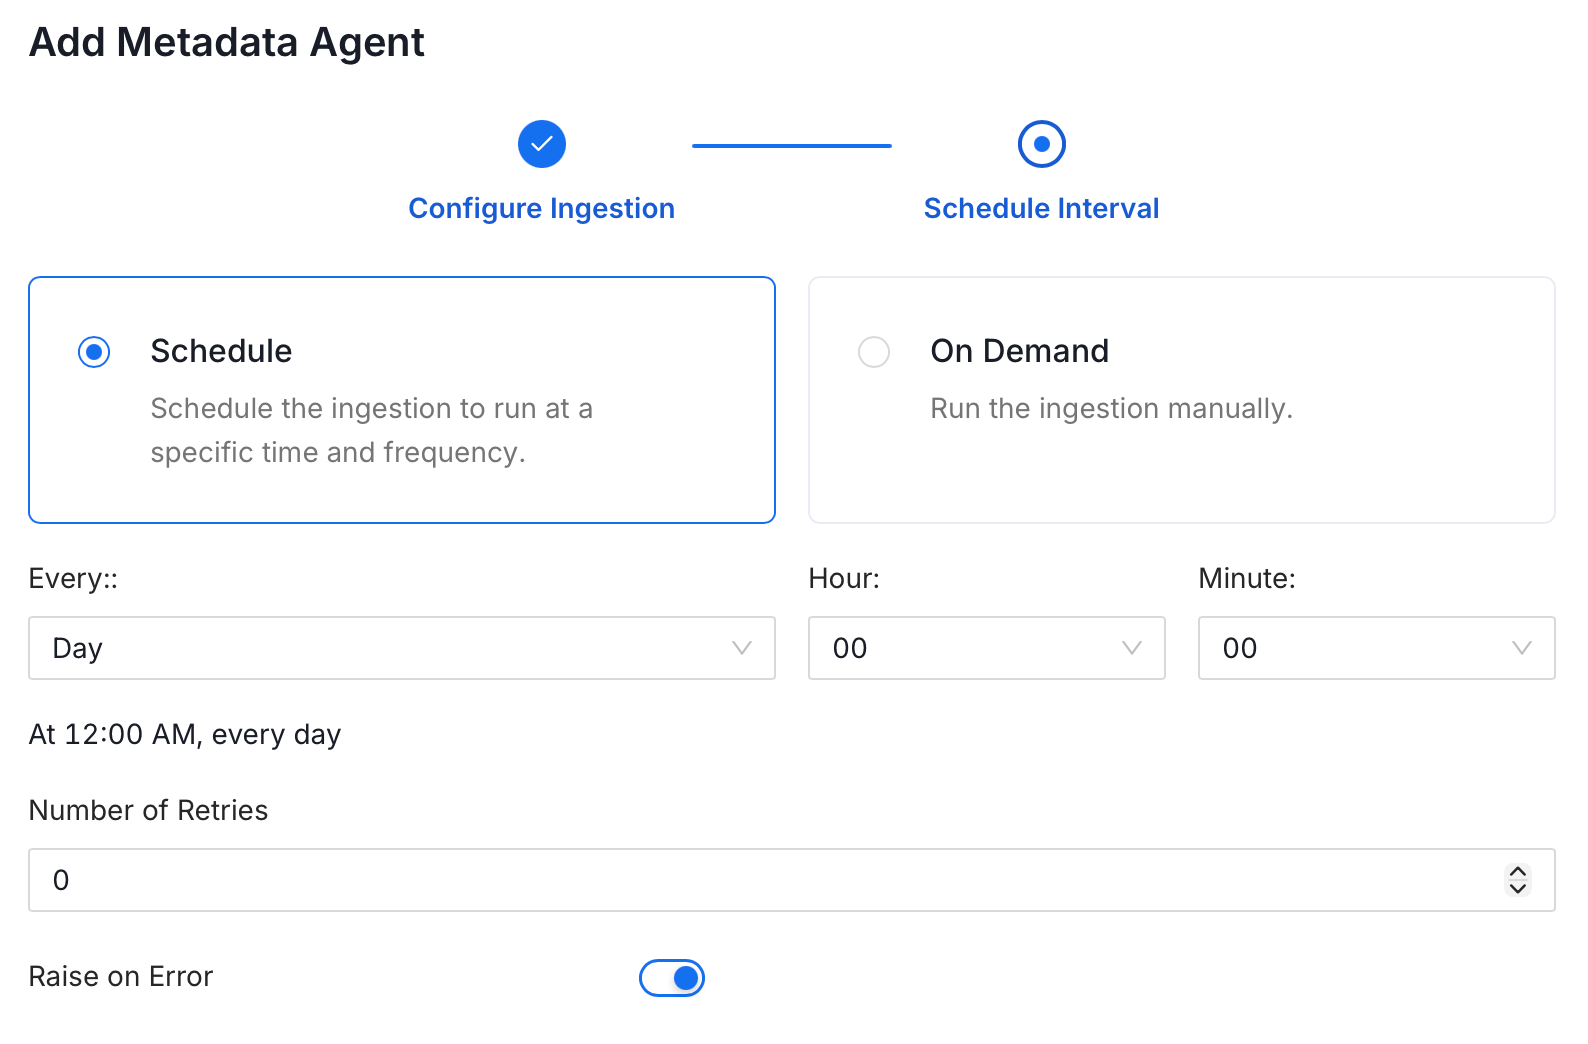
- Click Add to deploy the agent.
Lineage
Lineage
Lineage in Collate shows you which database tables power each dashboard. When lineage is set up, you can trace any dashboard back to the exact source tables in your database. There is no separate lineage agent or lineage pipeline—lineage is collected as part of the same metadata ingestion workflow. Configuring the Db Service Prefixes field (covered below) is optional but recommended — it restricts table matching to specific database services. If left blank, Collate attempts to match source tables across all ingested database services.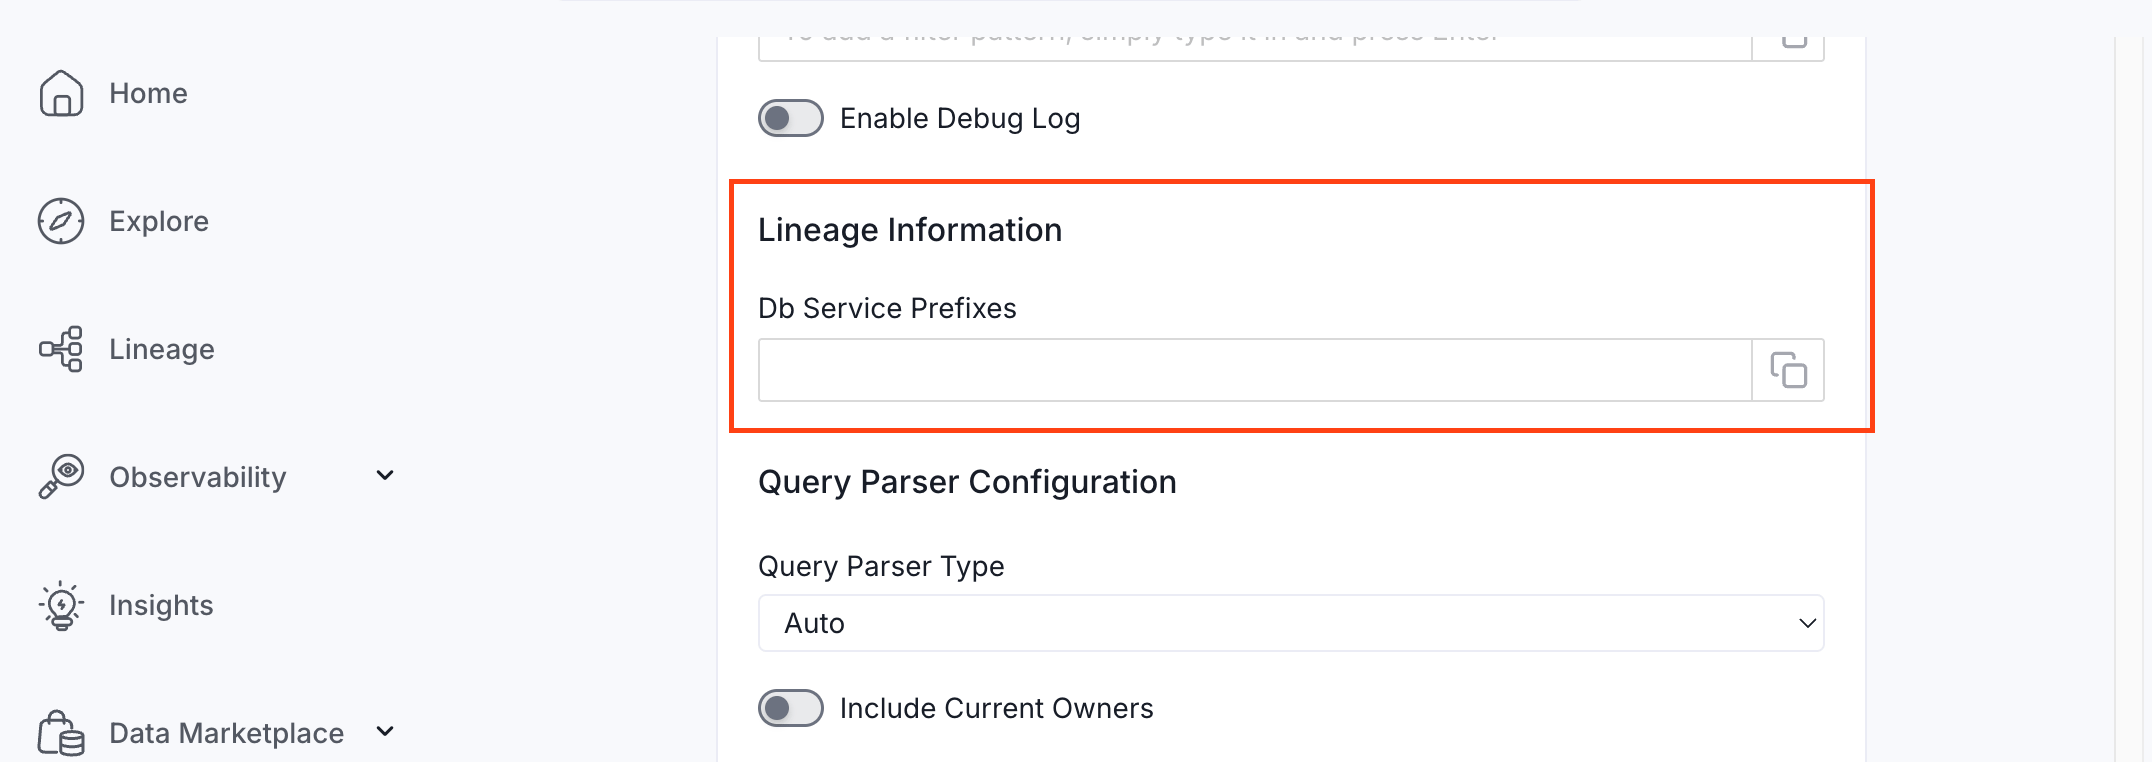
How to Set Up Lineage
- Go to Settings > Services > Dashboards.
- Click the dashboard service you’ve added.
- Go to the Agents tab, then select Add Agent > Add Metadata Agent. If a metadata agent already exists, select the three-dot context menu (⋮) next to it and select Edit.
- In the Configure Ingestion step, scroll down to the Lineage Information section.
- Optionally enter one or more database service names in the Db Service Prefixes field to restrict table matching to specific services. If left blank, Collate searches across all ingested database services.
Securing Superset Connection with SSL in Collate
- To establish secure connections between Collate and Superset, navigate to the
Advanced Configsection. Update theCertificate Pathand ensure that the certificates are accessible from the Airflow Server.
- To establish secure connections between Collate and Superset’s MySQL database, configure SSL certificates appropriately. If you only require SSL validation, specify the
caCertificateto use the CA certificate for validating the server’s certificate. For mutual authentication, where both client and server need to authenticate each other, provide all three parameters:ssl_keyfor the client’s private key,ssl_certfor the client’s SSL certificate, andssl_cafor the CA certificate to validate the server’s certificate.
- To establish secure connections between Collate and Superset’s PostgreSQL database, configure SSL using different SSL modes provided by PostgreSQL, each offering varying levels of security. Under
PostgresConnection Advanced Config, specify the SSL mode appropriate for your connection, such asprefer,verify-ca,allow, and others. After selecting the SSL mode, provide the CA certificate used for SSL validation (caCertificate). PostgreSQL requires only the CA certificate for SSL validation.
Troubleshooting
Superset Troubleshooting
Learn more about how to troubleshoot common Superset connector issues and resolve configuration or ingestion errors.