
Requirements
The Rill connector reads metadata from a Rill runtime over its REST API. It works with both deployment styles:- Rill Developer: A local or self-hosted Rill runtime. Point Host and Port at the runtime URL, for example
http://localhost:9009. An API token is optional. - Rill Cloud: A hosted project. Point Host and Port at the project endpoint, for example
https://api.rilldata.com/v1/orgs/<org>/projects/<project>. An API Token is required.
/branch/<name> segment, remove it before configuring the connection.
The token must have read access to the project’s resources. Collate uses that access to list the following:
- Dashboards, including Explore and Canvas dashboards
- Charts, including Canvas components
- Data models, including SQL models and metrics views
- Relationships between these assets
Metadata Ingestion
To ingest metadata from Rill, you need to create a service connection. The service connects Rill with Collate. Once you create a service, Collate automatically starts ingesting metadata.Step 1: Add New Service
Open the Services page and start a new service.-
Navigate to Settings > Services and select Dashboard Services.
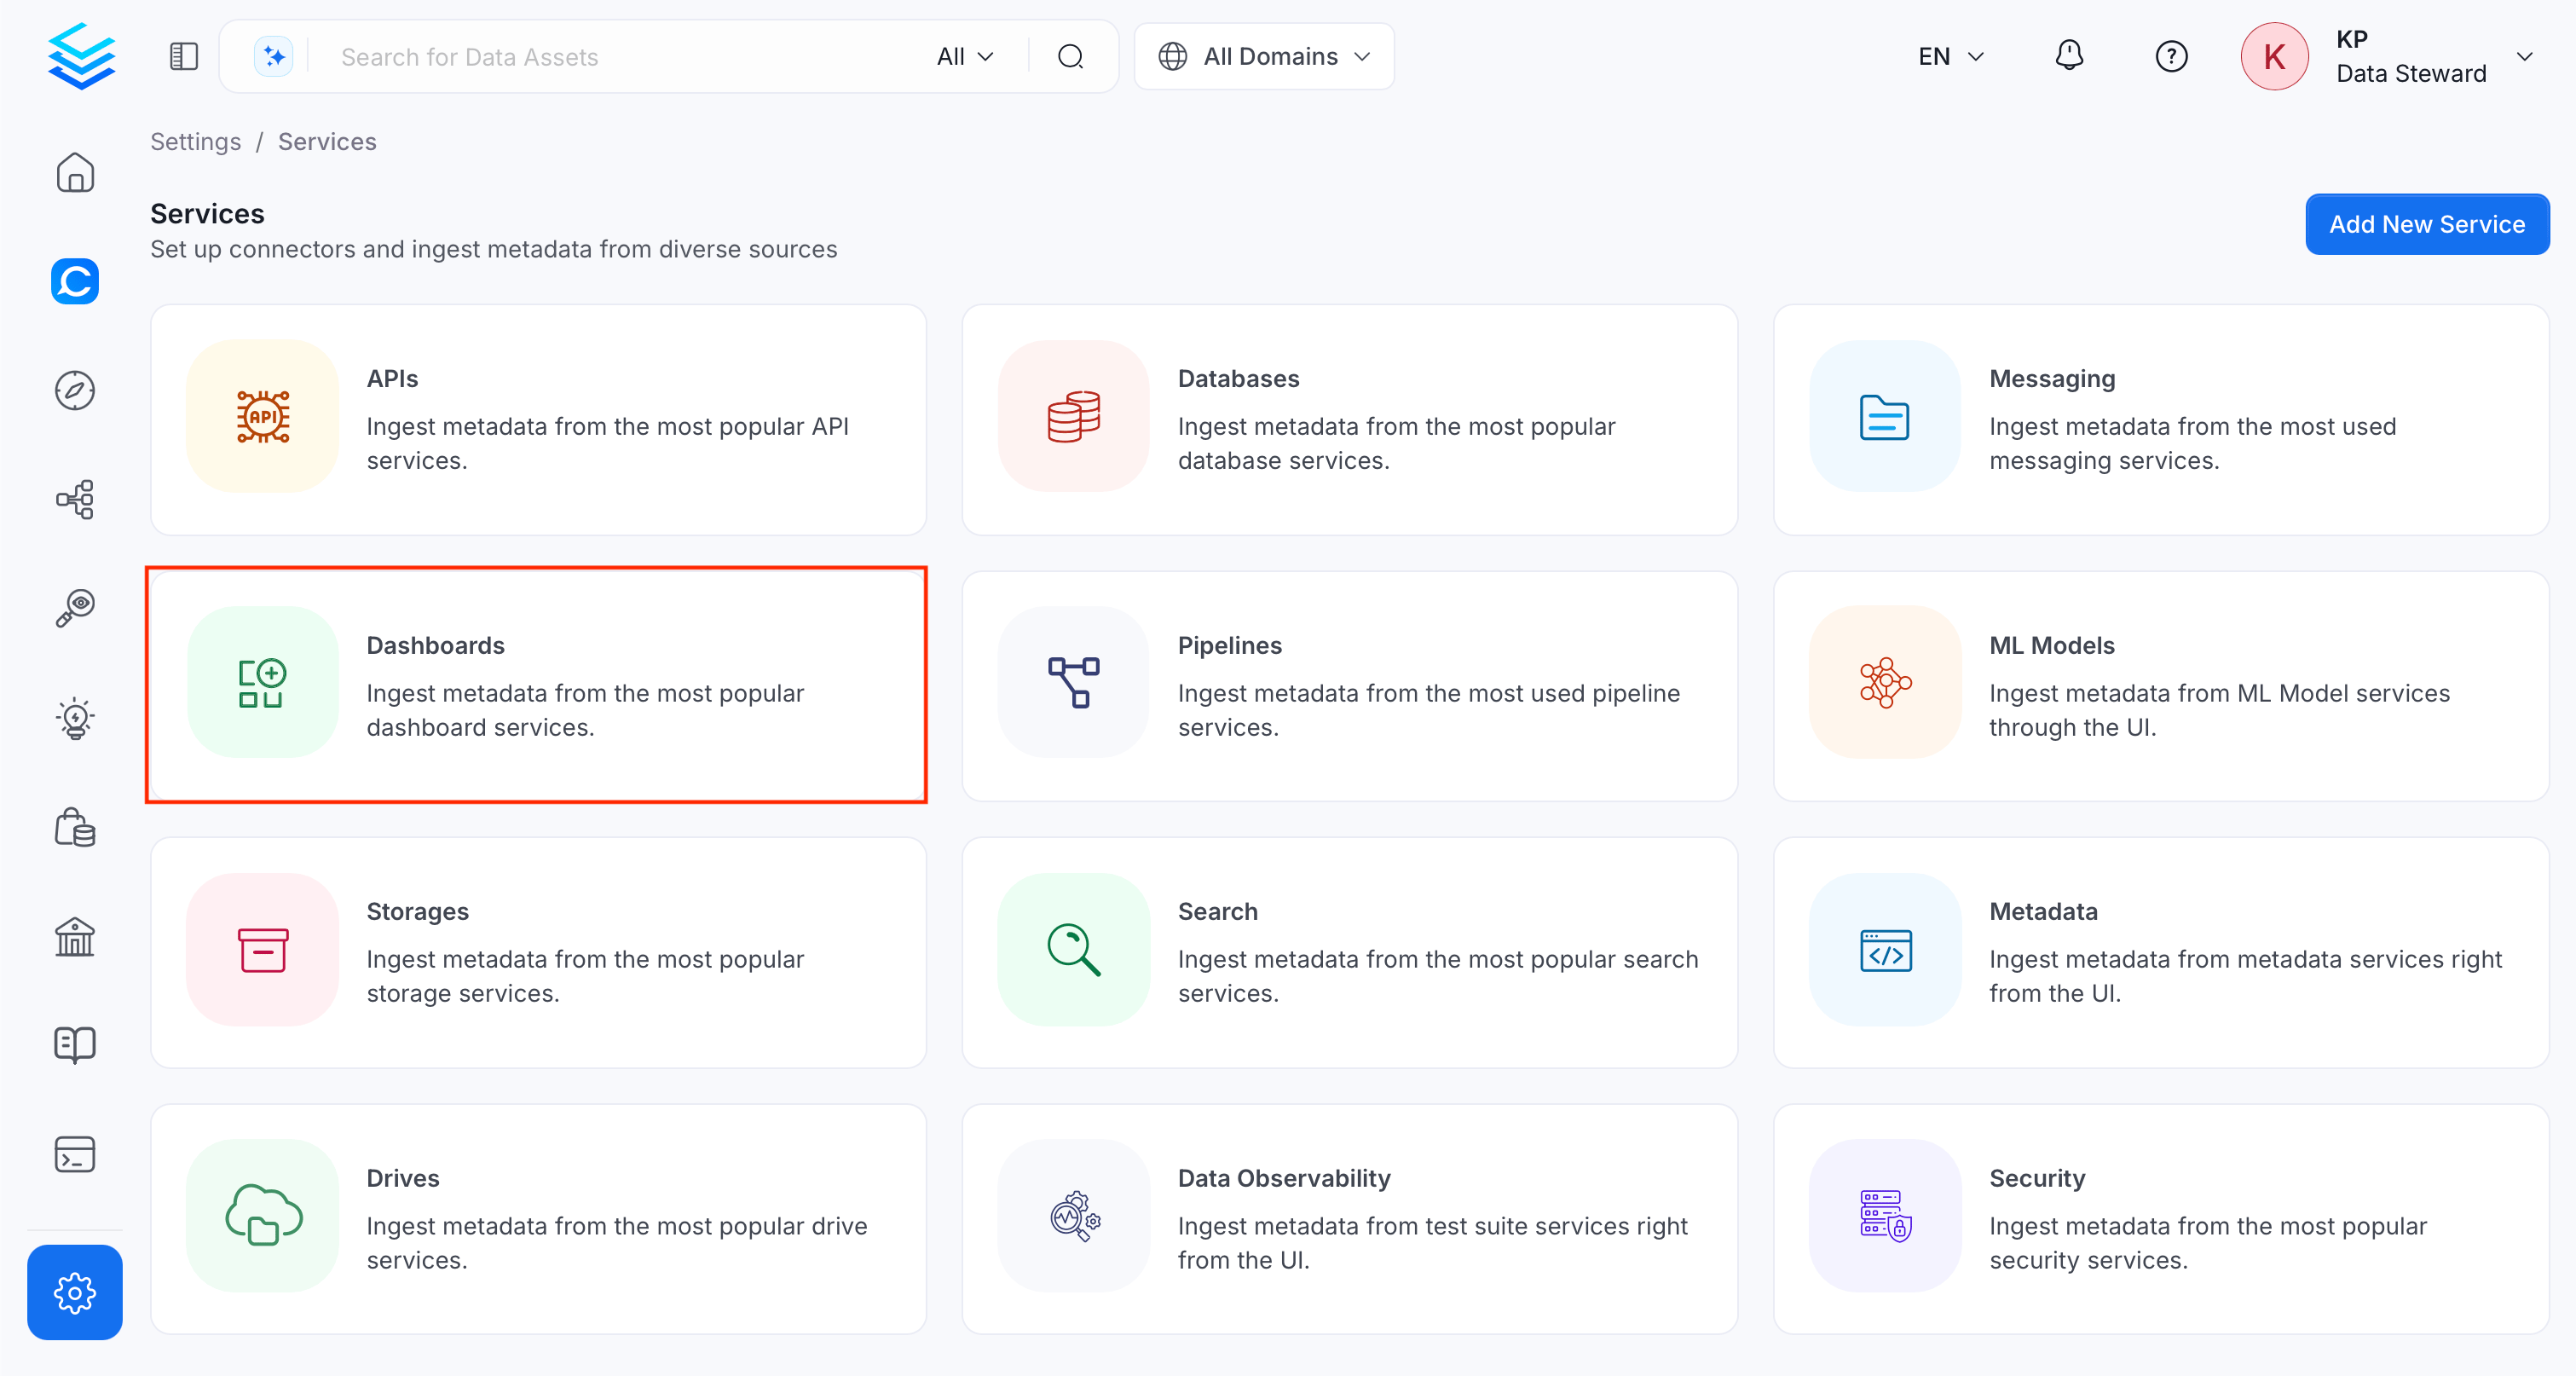
-
Click Add New Service.
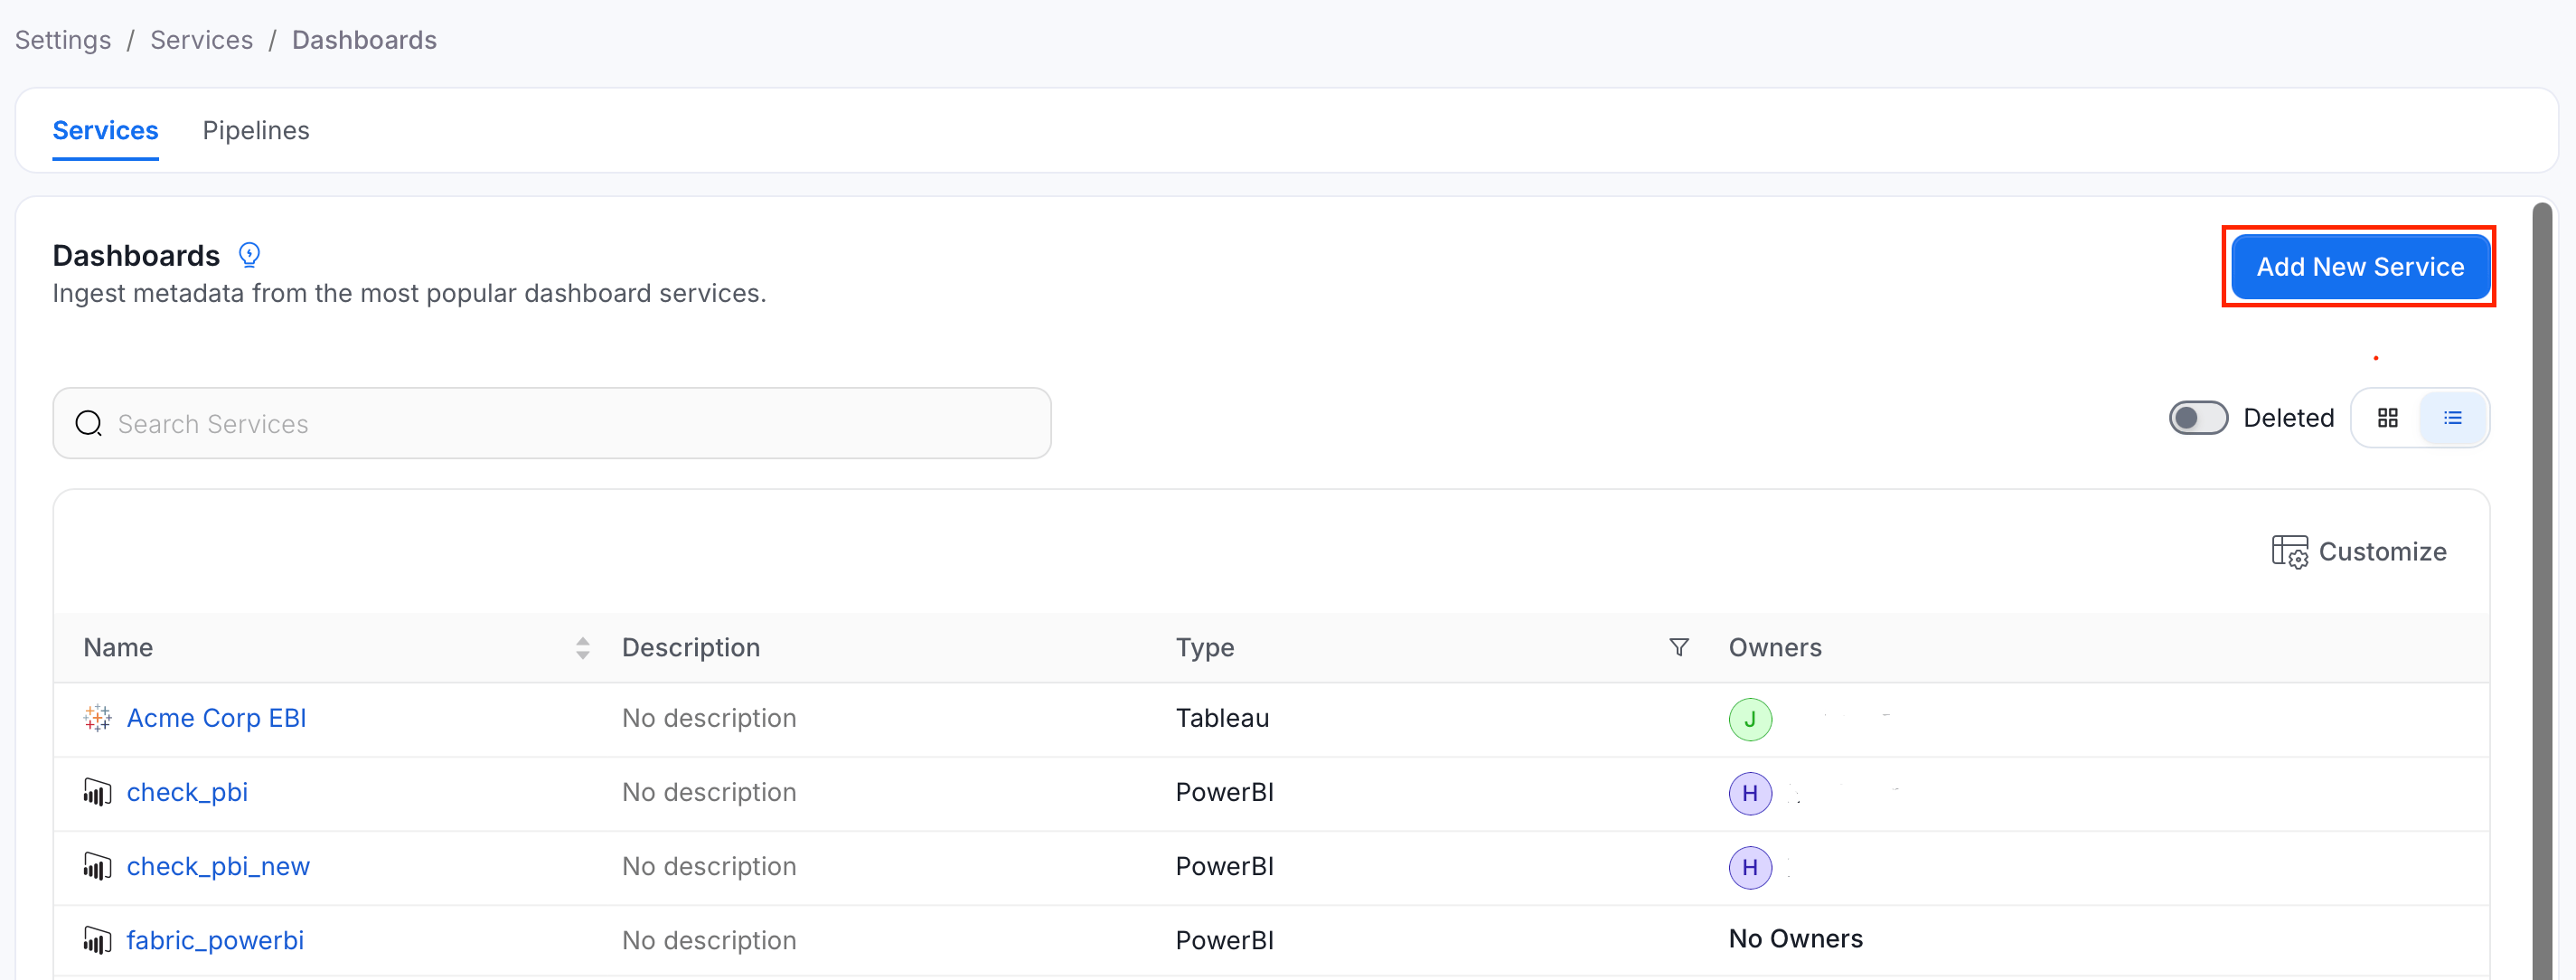
Step 2: Select a Service and Connector
From the service type dropdown, select Dashboard Services, then click the Rill connector tile.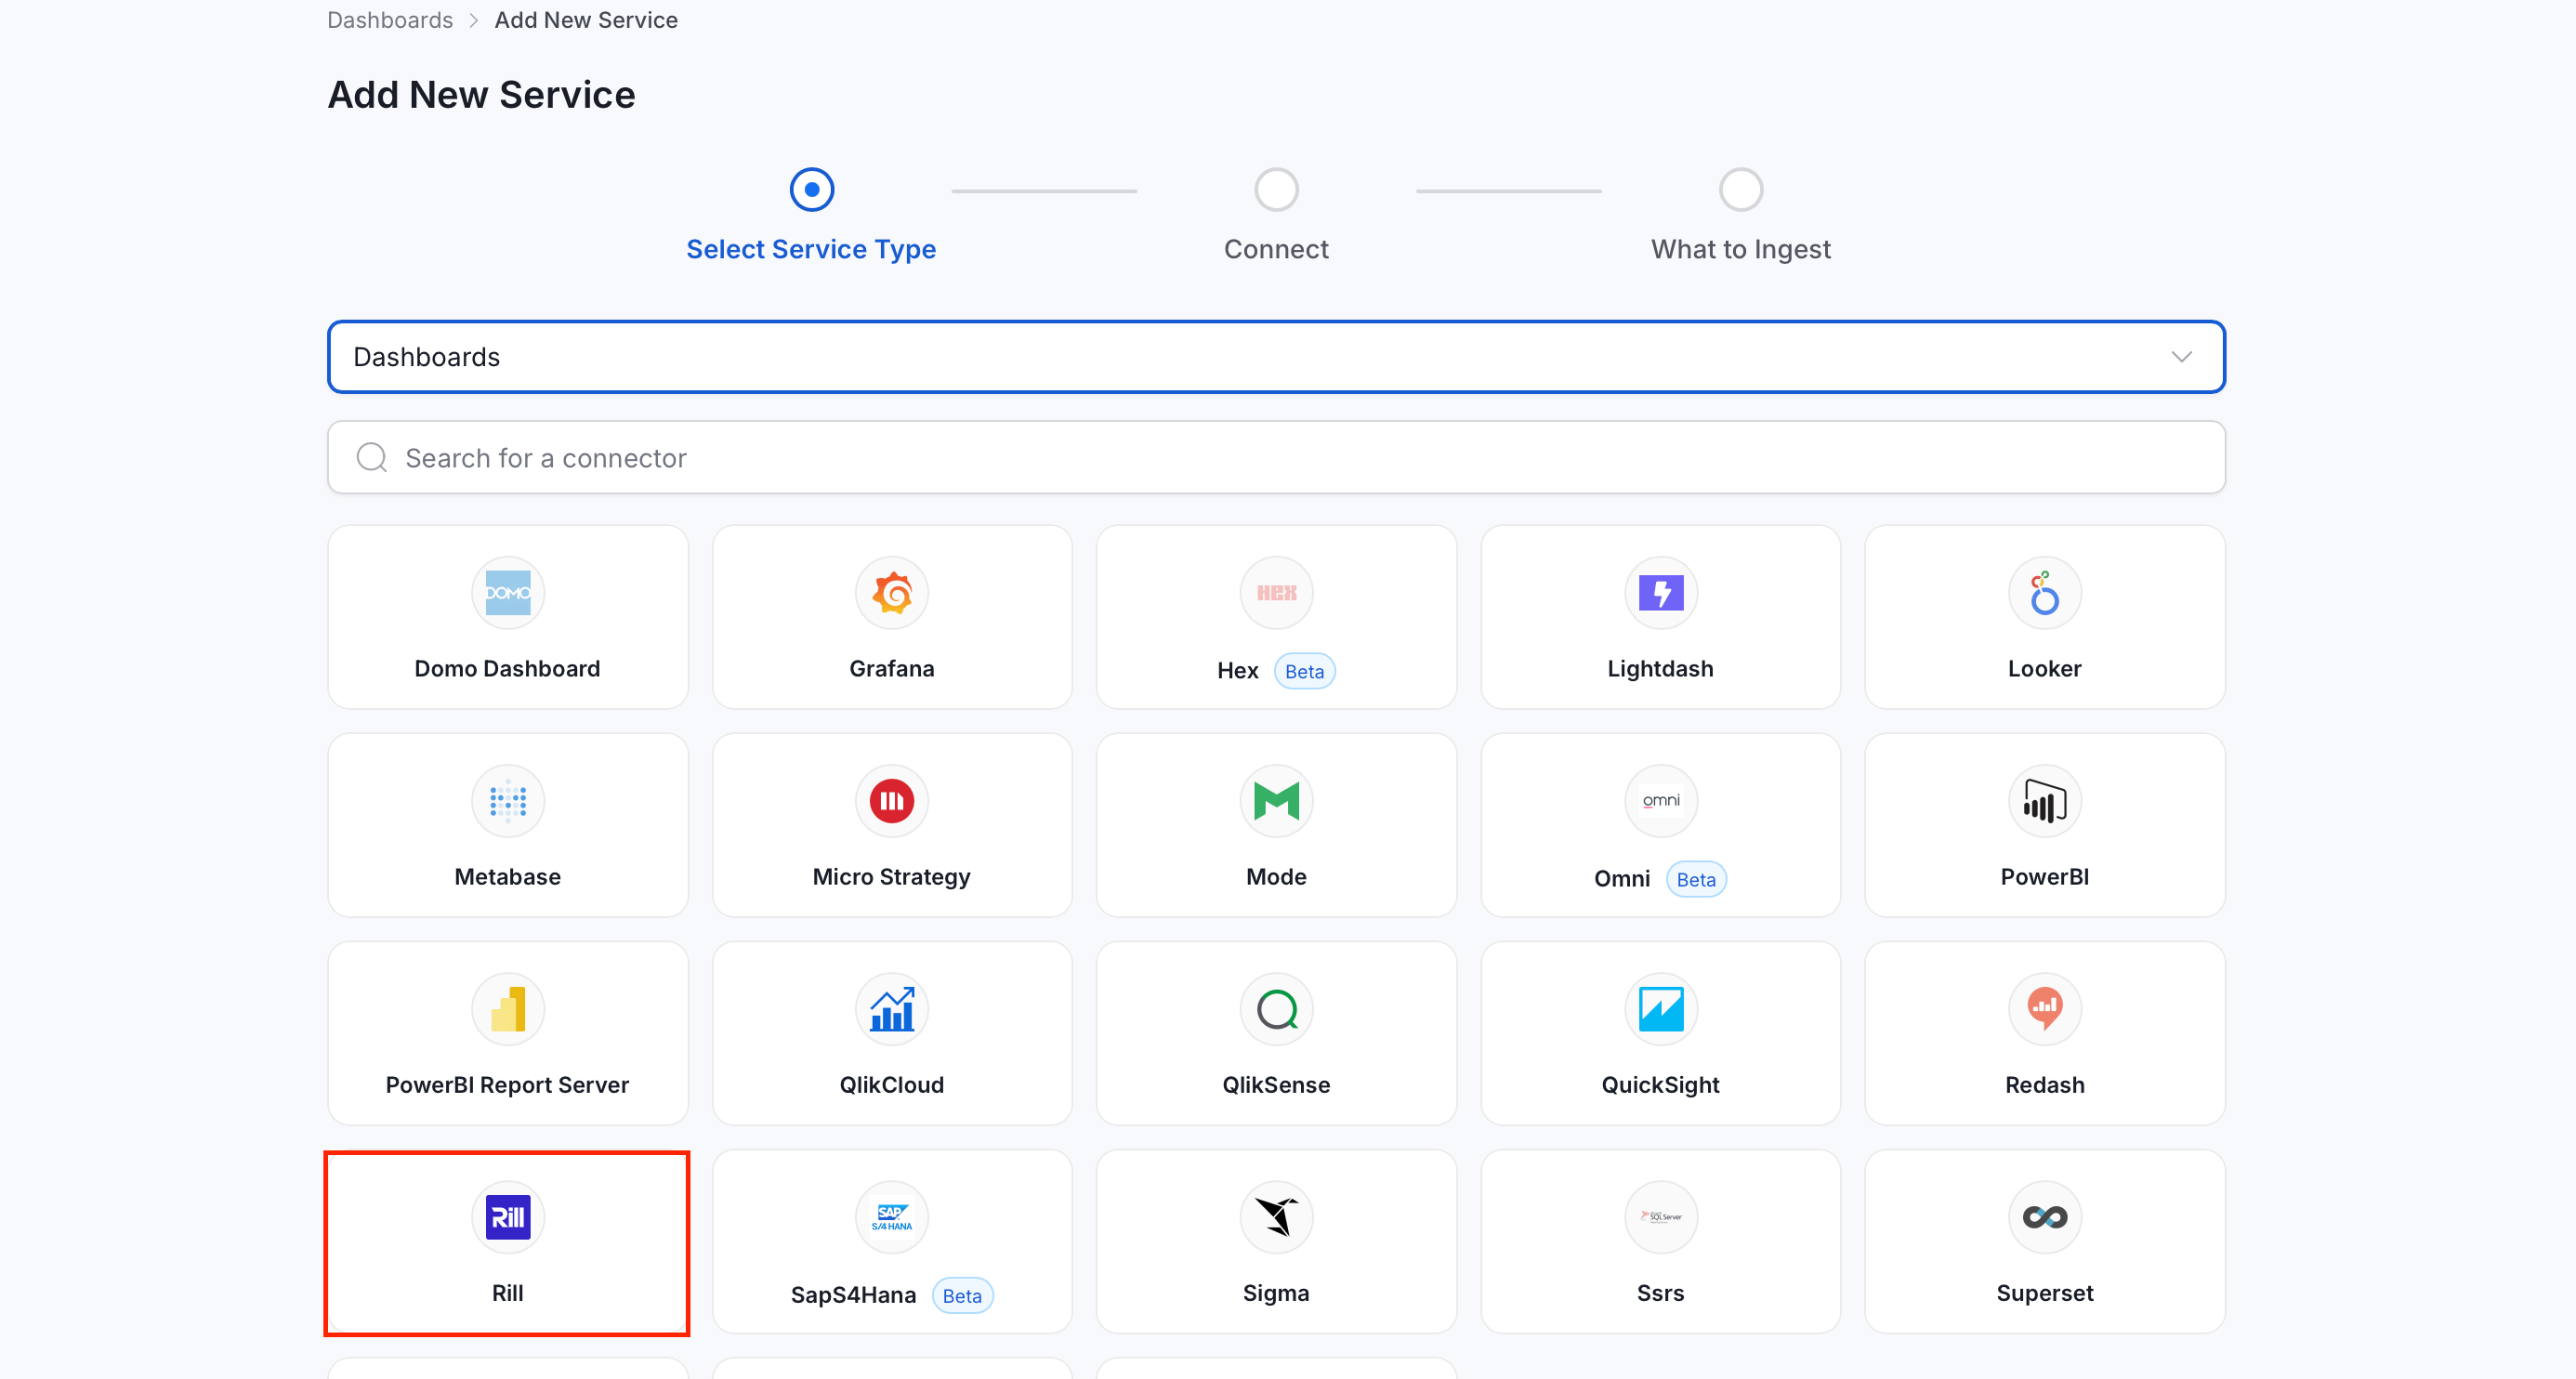
Step 3: Add Service Name and Description
- Enter a unique, descriptive Service Name. Collate identifies services by their service name. Enter a name that distinguishes this deployment from other Rill services you are ingesting metadata from.
- Optional: Enter a Description for the service.
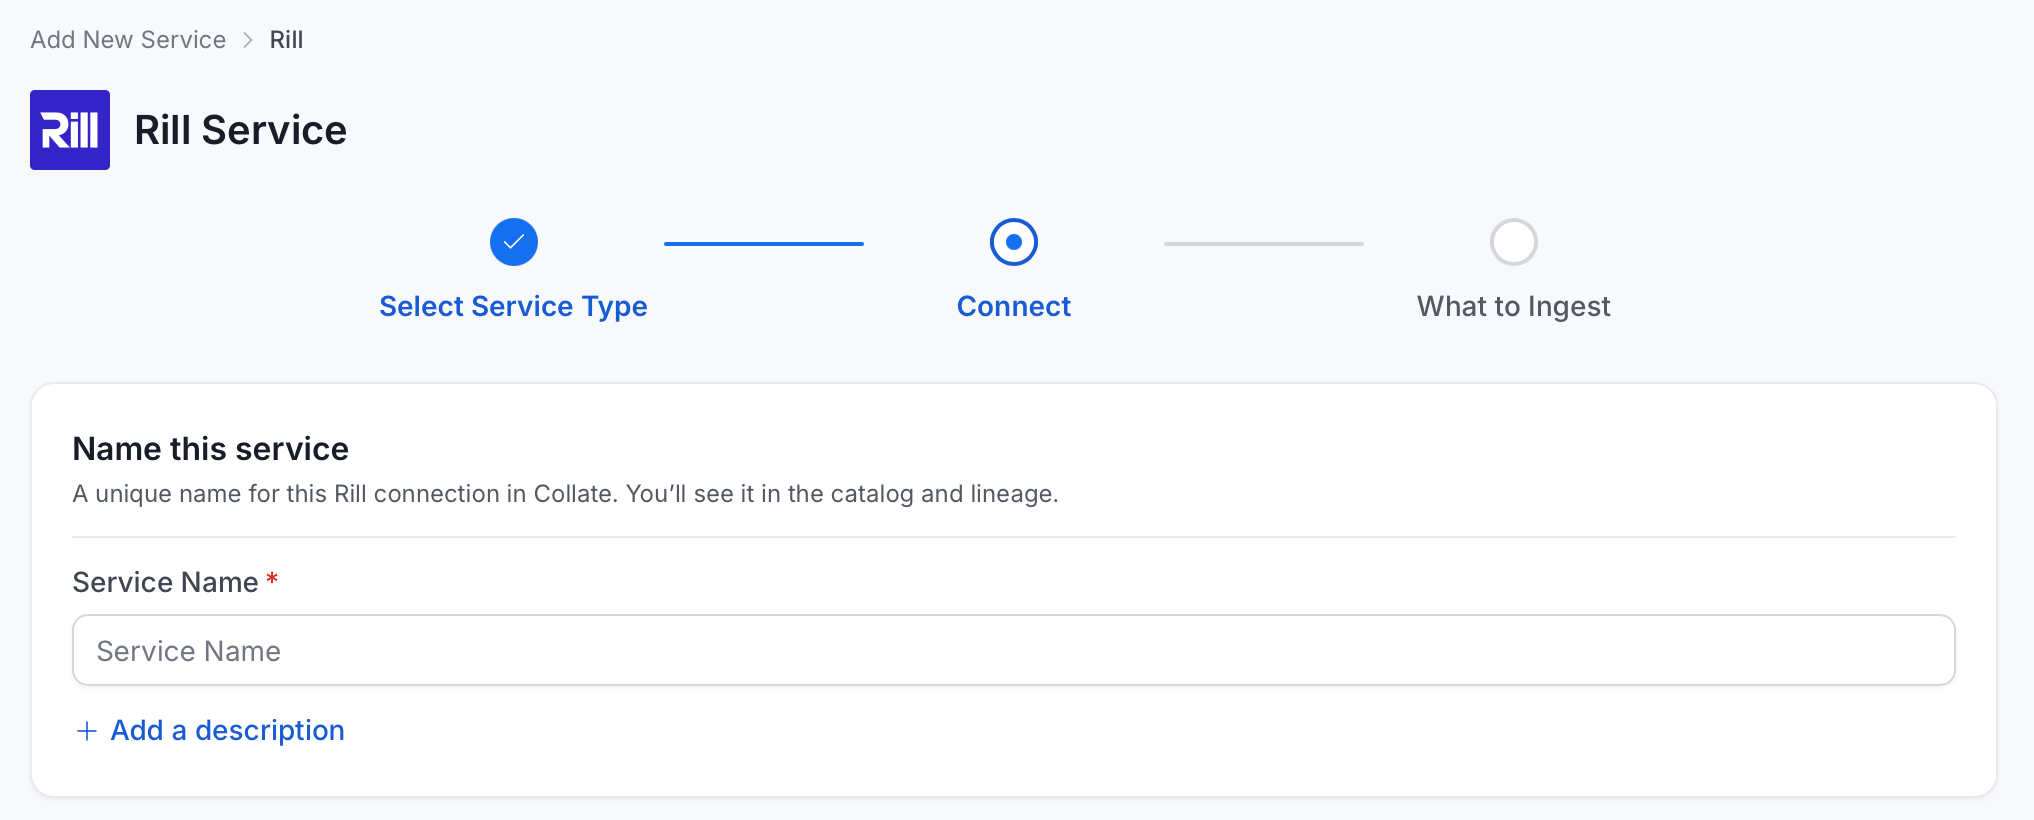
Note: The service name can’t be changed after you set it.
Step 4: Configure Connection Options
Specify where ingestion runs, provide your source credentials, and verify the connection.Select Ingestion Runner
Select an Ingestion Runner: the runner where the ingestion pipeline will execute.
Enter Connection Details
Enter the connection details for Rill. The right-hand panel in the UI displays inline help for each field.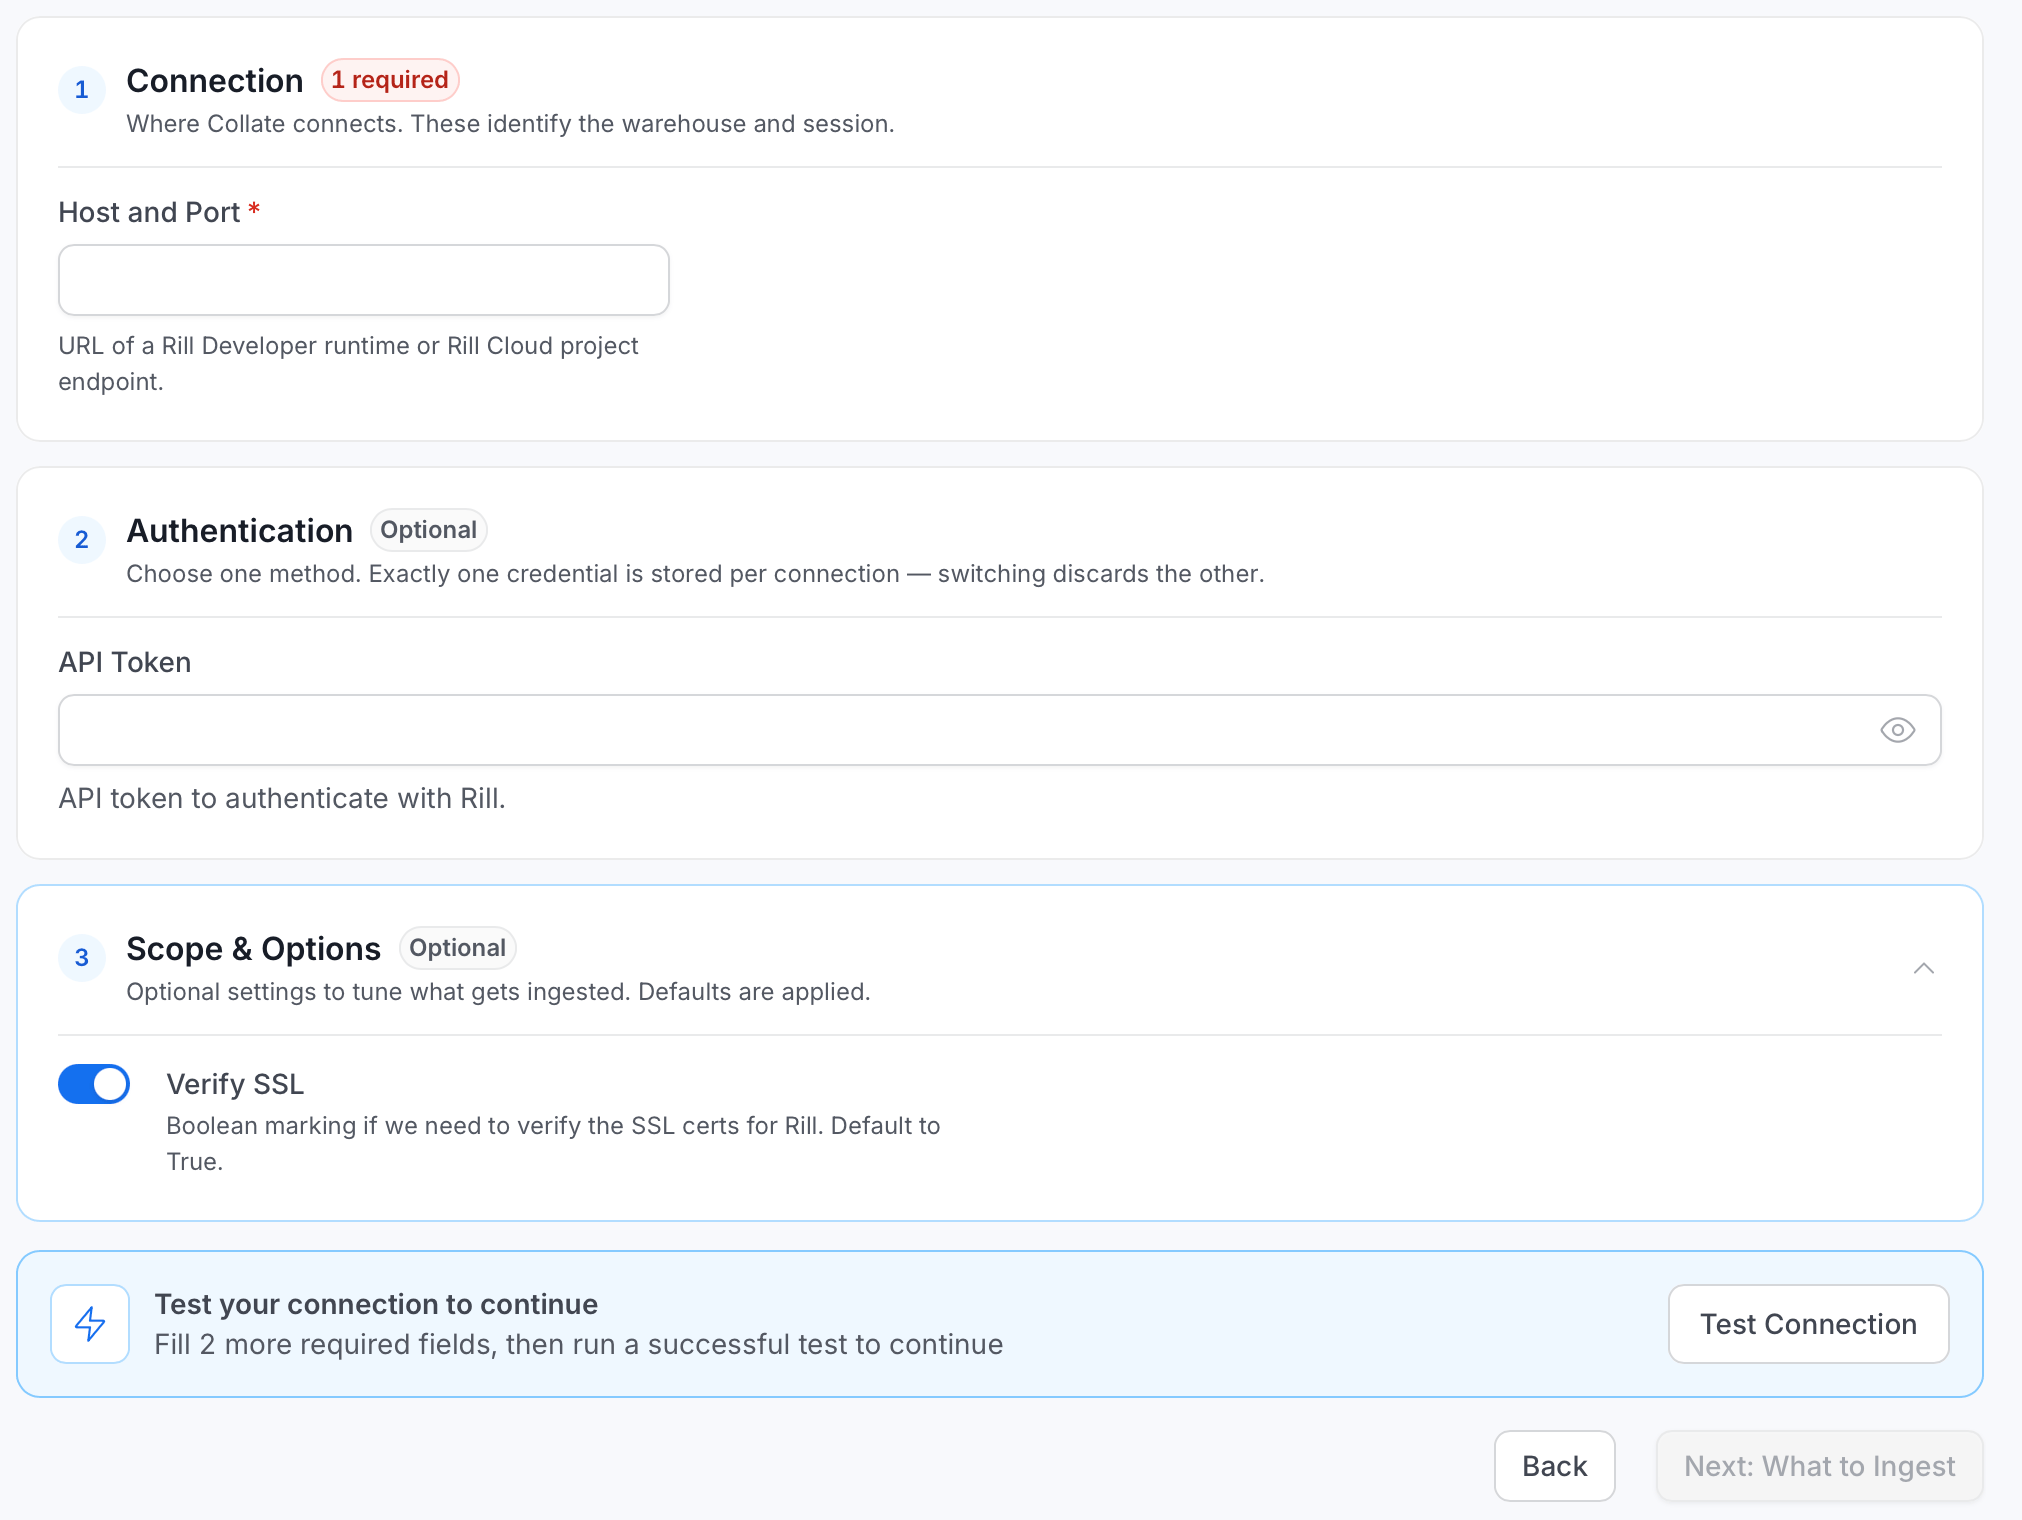
-
Host and Port: URL of a Rill Developer runtime or a Rill Cloud project endpoint. For a local Rill Developer runtime, use something like
http://localhost:9009. For Rill Cloud, use the project endpoint, for examplehttps://api.rilldata.com/v1/orgs/<org>/projects/<project>. - API Token (optional): API token used to authenticate with Rill. Required for Rill Cloud. Optional for a Rill Developer runtime that does not require authentication.
-
Verify SSL (optional): Whether to verify SSL certificates when connecting to Rill. Defaults to
true.
Test Connection
- Click Test Connection to verify the credentials.
- After the test succeeds, click Save.
Step 5: Configure Ingestion Options
In the What to Ingest step, use filter rules to control which dashboards, charts, and data models Collate ingests from the source.How Filter Rules Work
Each rule matches asset names using one of five match types:- contains: matches any name containing the value. For example,
salesmatchesmy_sales_dataandsales_2024. - starts with: matches names beginning with the value. For example,
prod_matchesprod_dbandprod_schema. - ends with: matches names ending with the value. For example,
_rawmatchesevents_rawandlogs_raw. - is exactly: matches the exact name only. For example,
analyticsmatches onlyanalytics. - matches regex: matches names using a regular expression. For example,
^prod_.*_v\d+$matchesprod_events_v1.
Filter Options
The Dashboard, Chart, and Data Model sections control ingestion for the corresponding asset type. Each section provides the following controls:- Scan Mode: Choose between the following scan modes:
- Scan all: Ingests every asset of that type the connector can access. This is the default.
- Only specific: Enables include rules so only assets matching at least one rule are ingested.
- Always exclude: Add permanent exclusion rules (shown in red). Assets matching these rules are never ingested, regardless of include rules.
- Preview: Shows a real-time summary of what will be in scope based on your current rules.
- Include rules: In Only specific mode, click + Add to define a rule. Added rules appear as chips. An asset is included if it matches any rule.
Step 6: Create & Deploy
Click Create & Deploy to deploy the agent and start the first metadata ingestion run. Collate saves the service configuration and immediately begins pulling metadata from the source. To monitor ingestion progress or view the service you just added, go to Settings > Services and select your service.Configure Metadata Agent and Schedule Ingestion
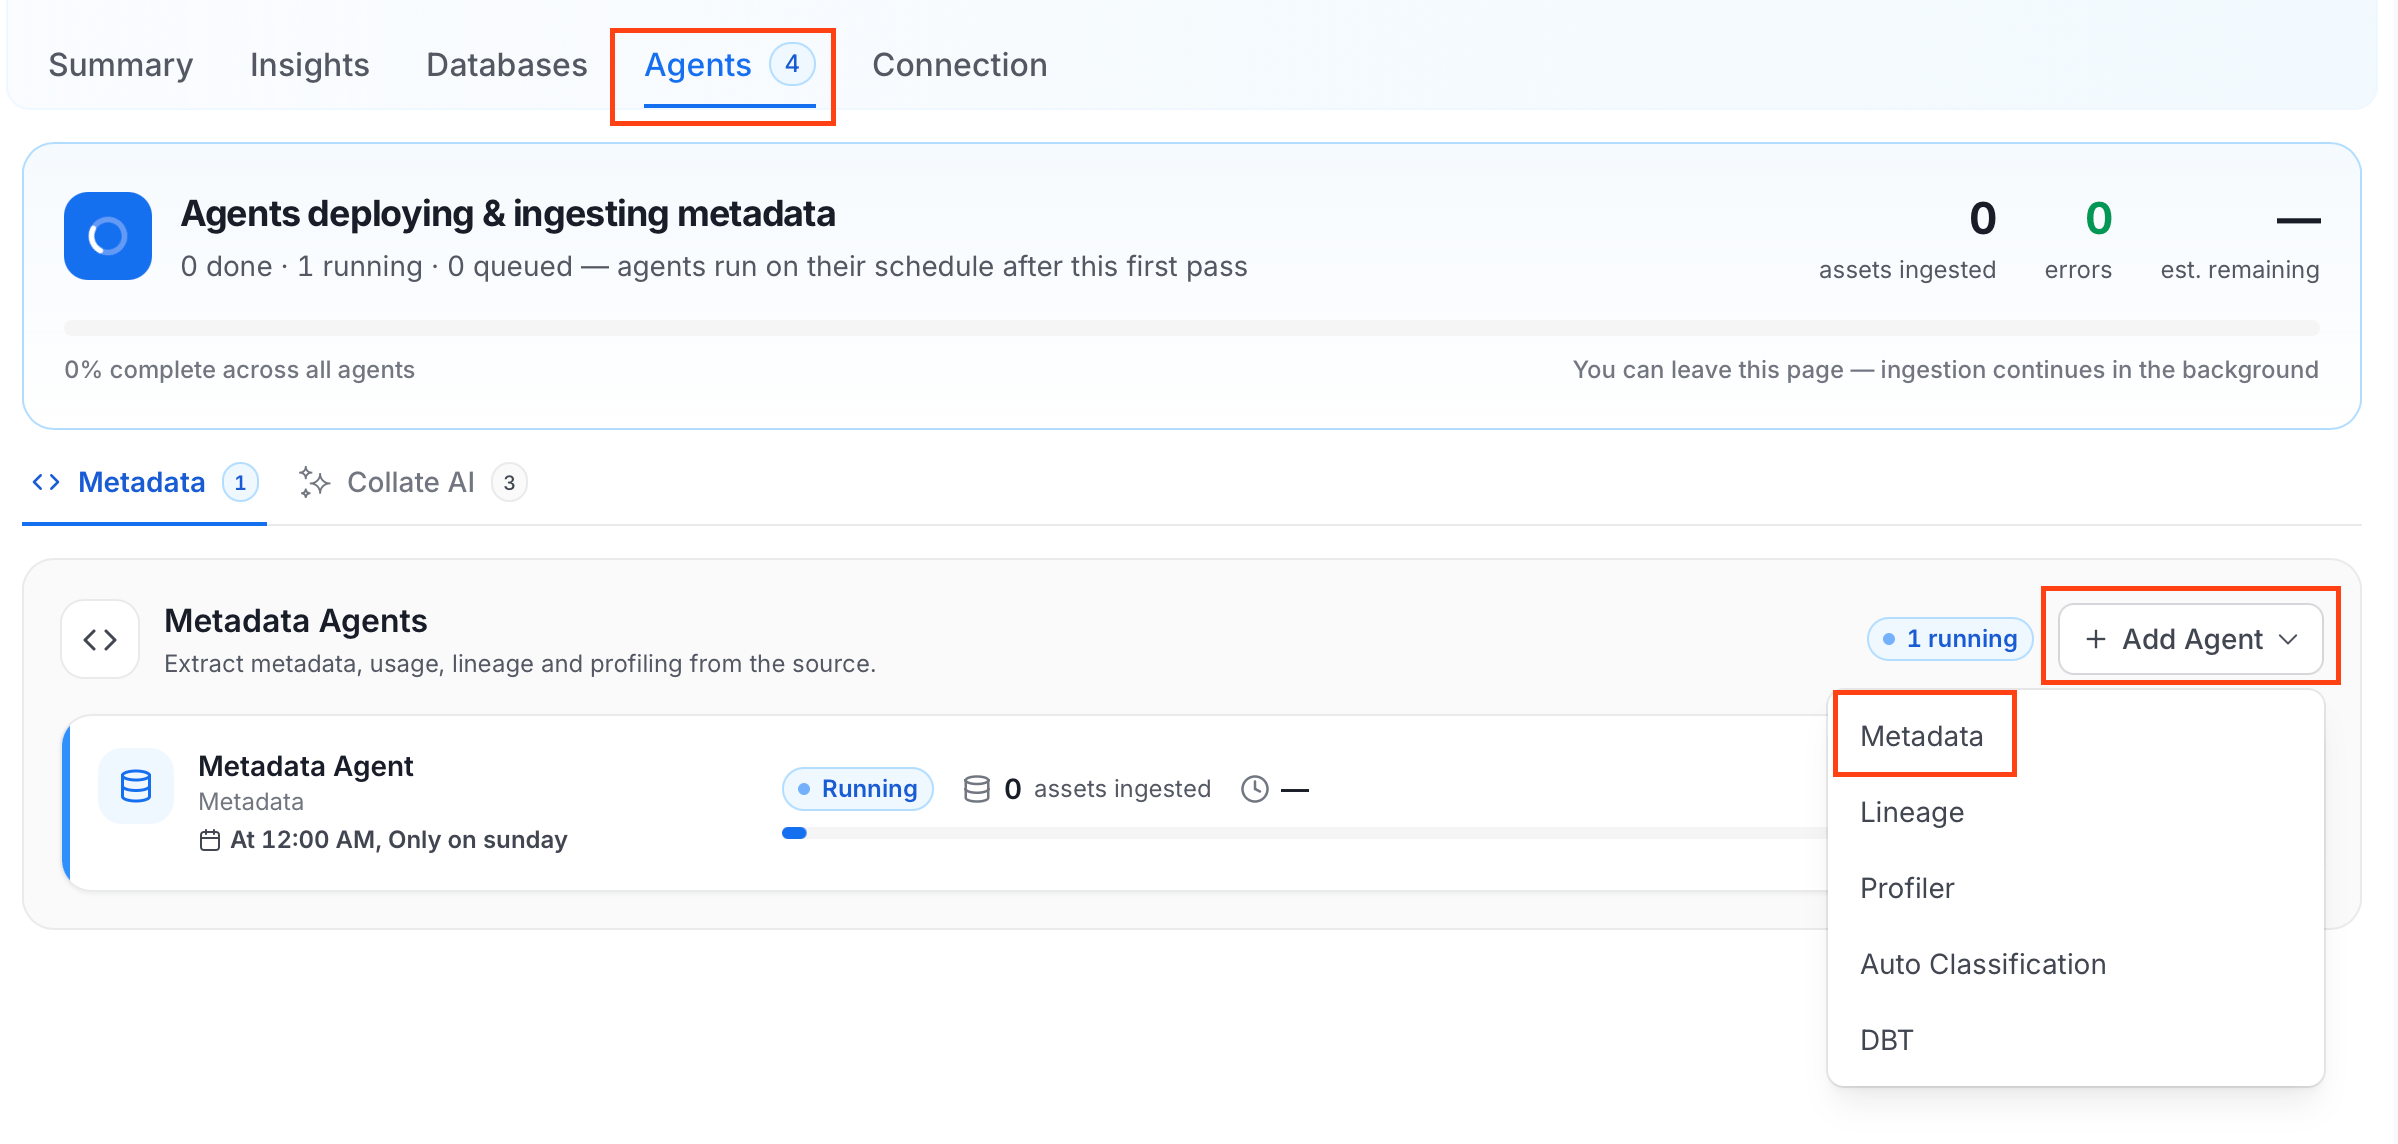
The Metadata Agent extracts dashboards, charts, data models, and other structural metadata from your source and keeps your Collate catalog in sync. It powers discovery, lineage, and governance across your data assets. When you click Create & Deploy, Collate automatically deploys a Metadata Agent for this service and triggers the first ingestion run. View its status and run history from the Agents tab on the service detail page. To configure the additional Metadata Agent and schedule ingestion, follow these steps:- Navigate to Settings > Services and select the Dashboards service.
- Select your service and click the Agents tab.
-
Click Add Agent and select Metadata from the dropdown.
-
On the Configure Ingestion page, do the following and click Next.
-
Name this Ingestion: Enter a unique, recognizable name for this ingestion pipeline.

-
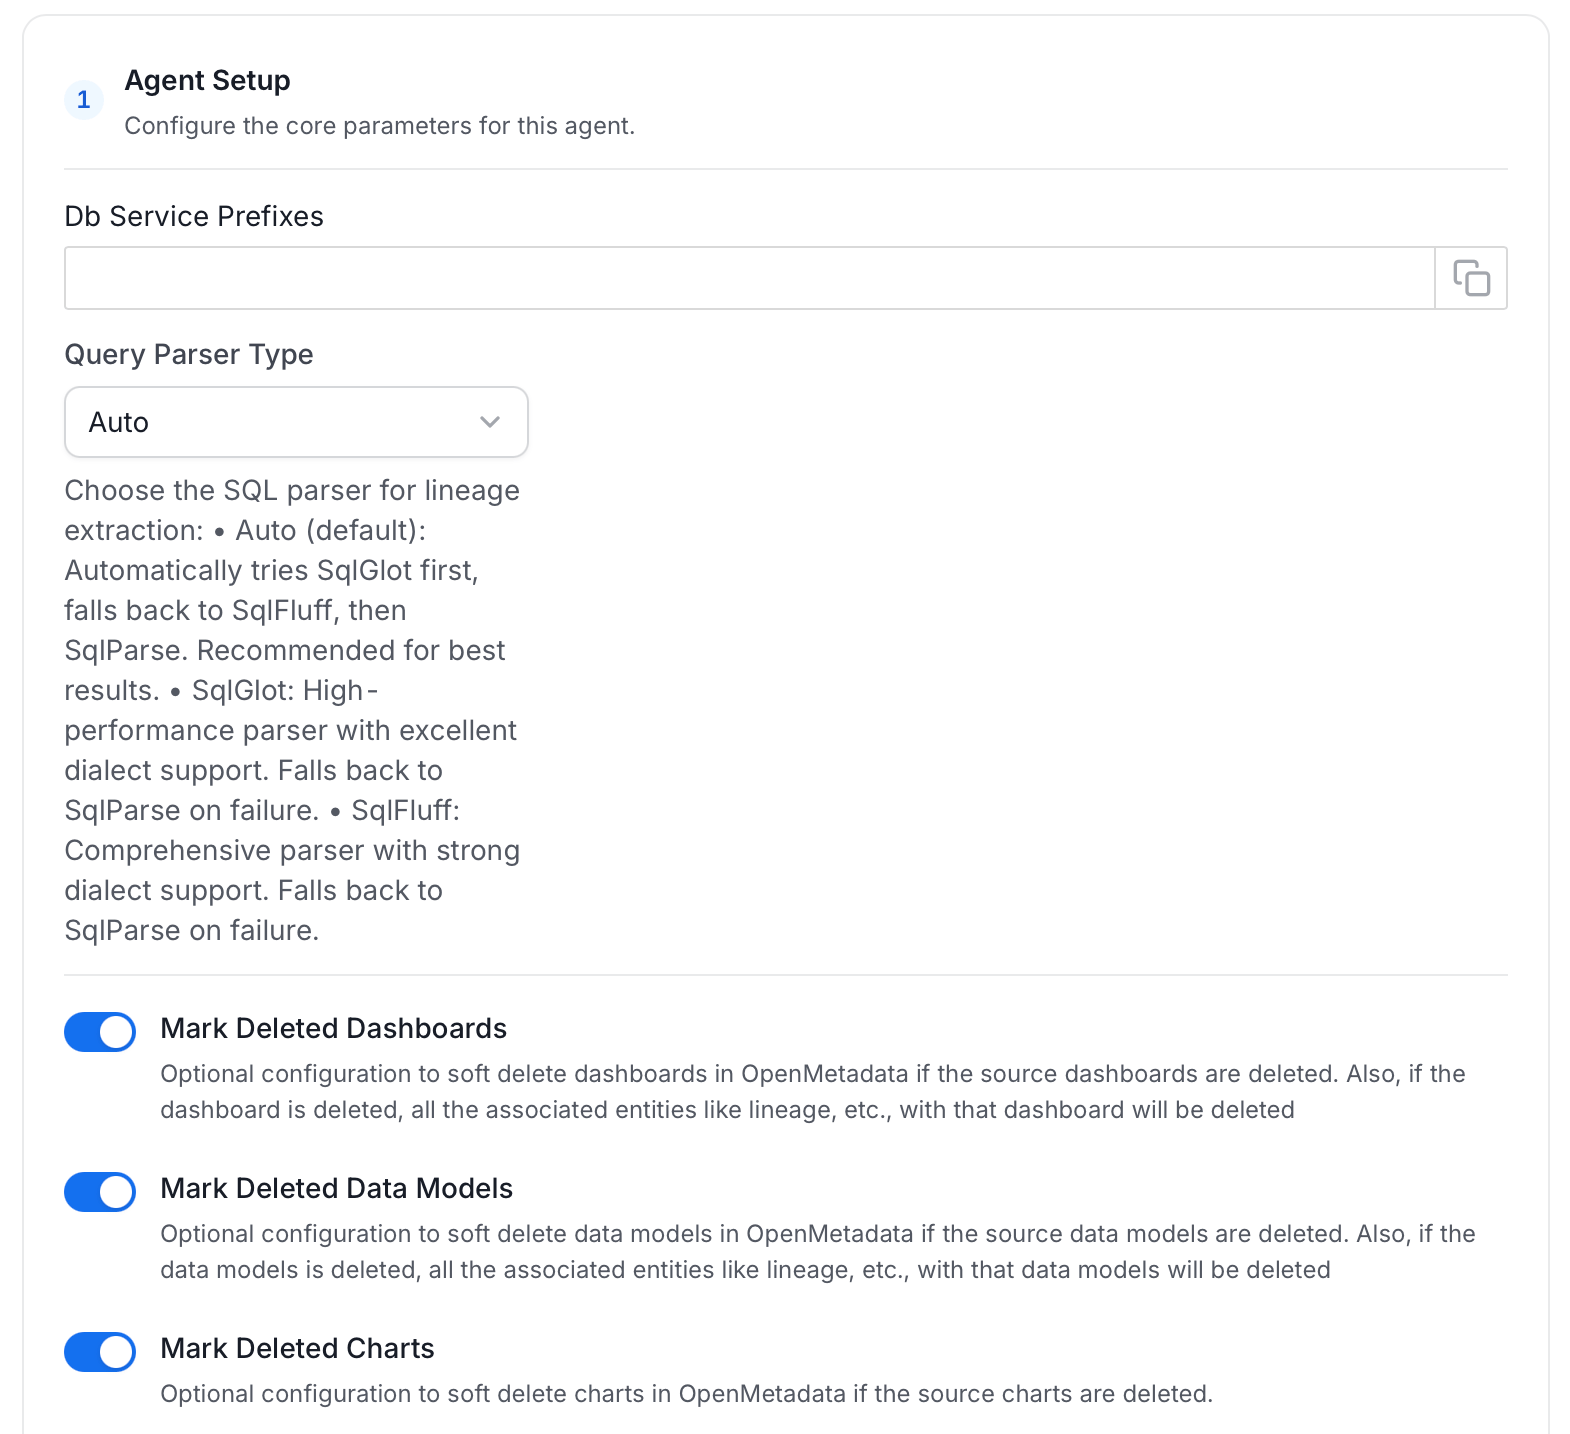
Agent Setup: Configure ingestion parameters. The following fields are available:
-
Filter Patterns: Apply include or exclude rules to scope which dashboards, charts, data models, and projects this agent ingests. These follow the same filter options described in Step 5.
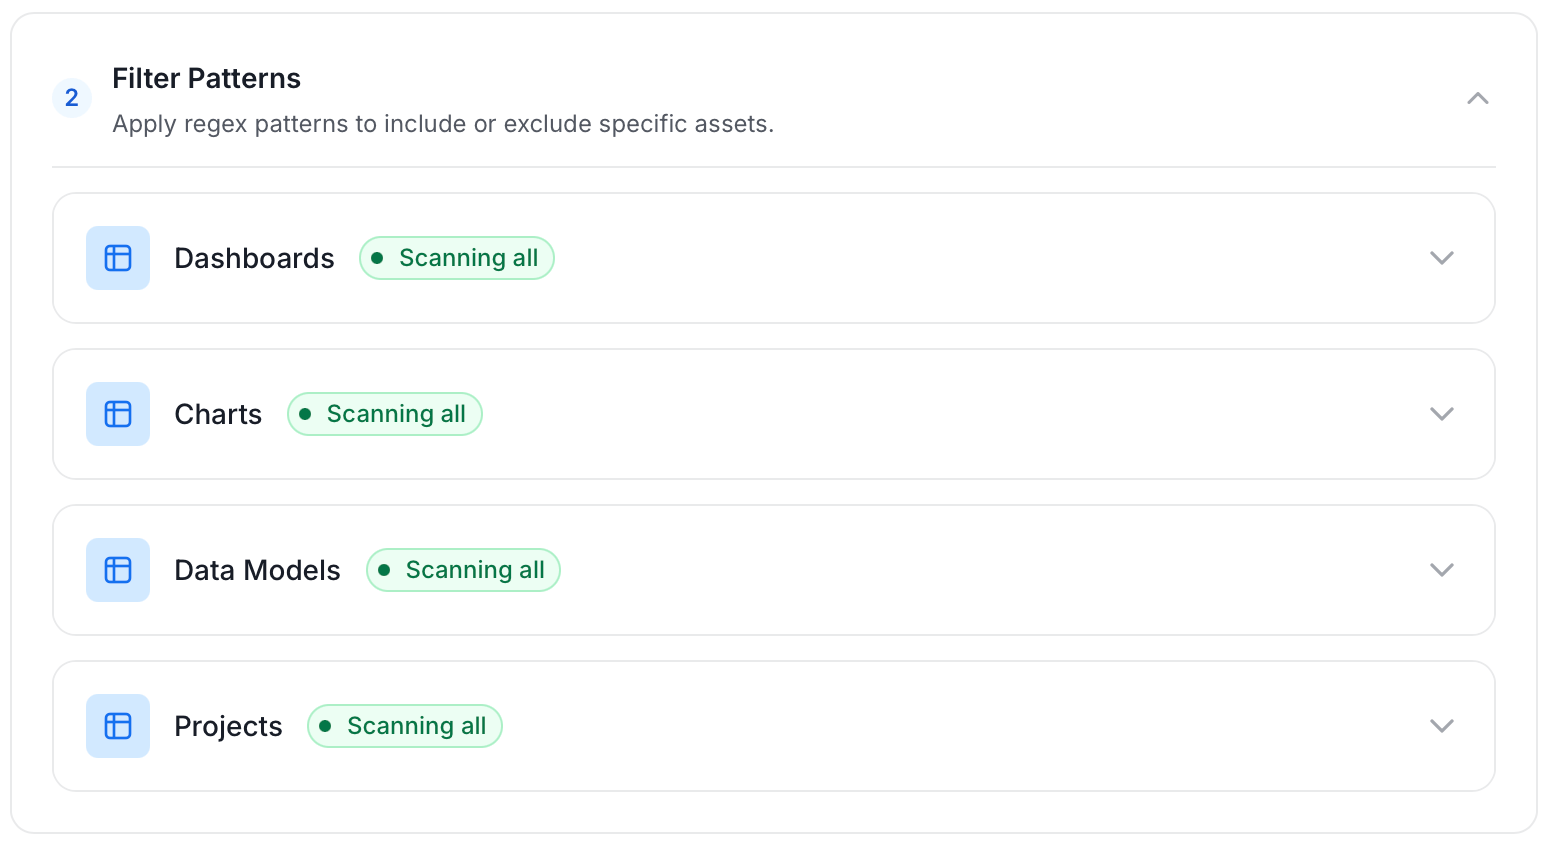
-
Scope & Behaviour: Control what metadata to include and how to handle deletions. Toggle each option on or off based on your needs:
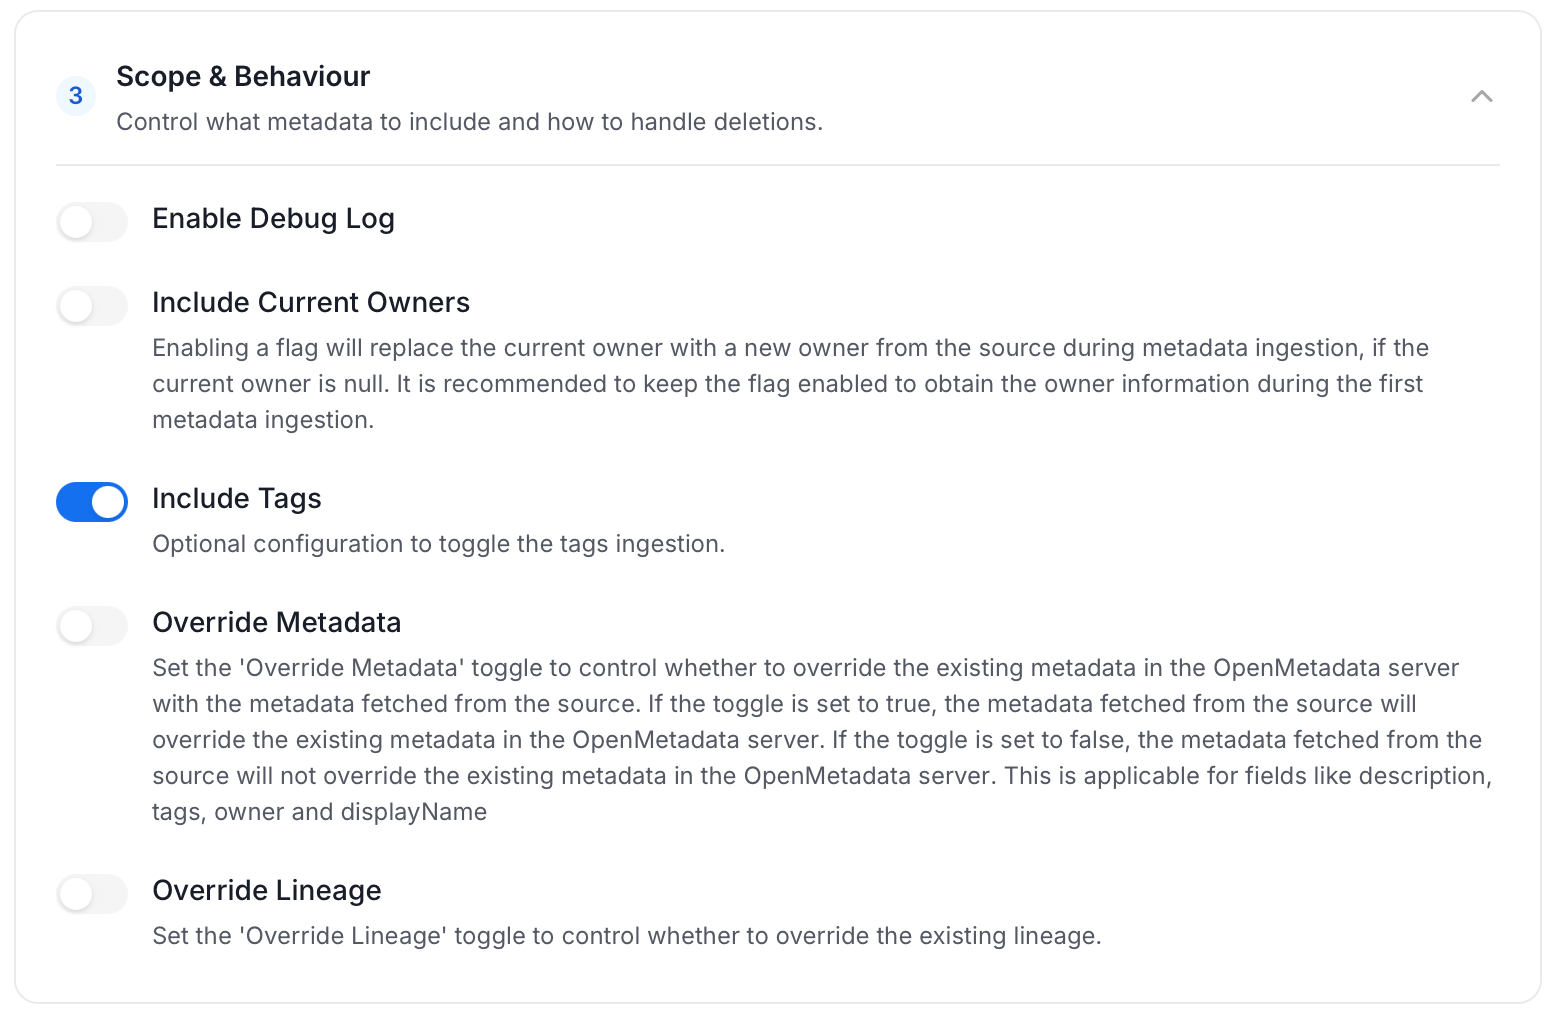
-
Name this Ingestion: Enter a unique, recognizable name for this ingestion pipeline.
-
On the Schedule Interval page, set when the agent runs:
- Schedule: Choose a preset interval (Hourly, Daily, Weekly, Monthly) or enter a custom cron expression.
- On-Demand: No automatic schedule. Trigger the agent manually when needed.
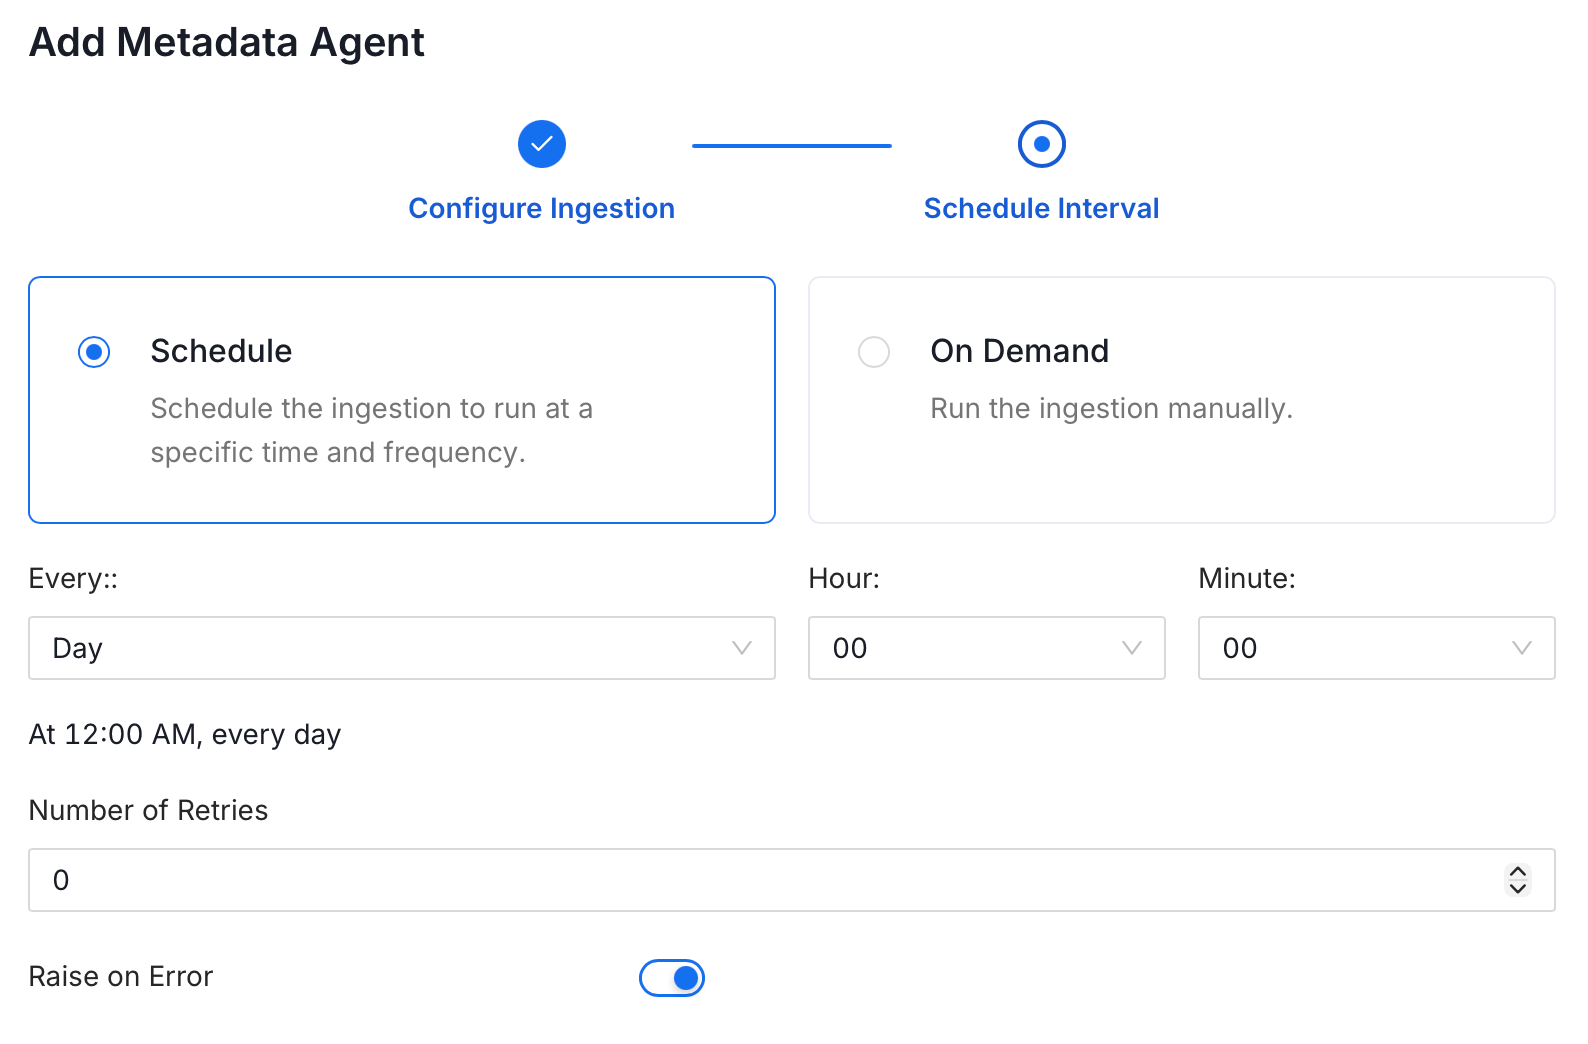
- Click Add to deploy the agent.
Troubleshooting
Rill Troubleshooting
Learn more about how to troubleshoot common Rill connector issues and resolve configuration or ingestion errors.