
Requirements
To execute metadata extraction and usage workflow successfully the IAM User should have enough access to fetch required data. The following table describes the minimum required permissions:- Navigate to the IAM console in the AWS Management Console.
- Choose the IAM user or group to attach the policy to.
- Click the “Permissions” tab.
- Click the “Add permissions” button and select “Attach existing policies directly”.
- Search for the policy by name or by filtering the available policies, and select the one you want to attach.
- Review the policy and click “Add permissions” to complete the process.
Metadata Ingestion
To ingest metadata from QuickSight, you need to create a service connection. The service connects QuickSight with Collate. Once you create a service, Collate automatically starts ingesting metadata.Step 1: Add New Service
Open the Services page and start a new service.-
Navigate to Settings > Services and select Dashboard Services.
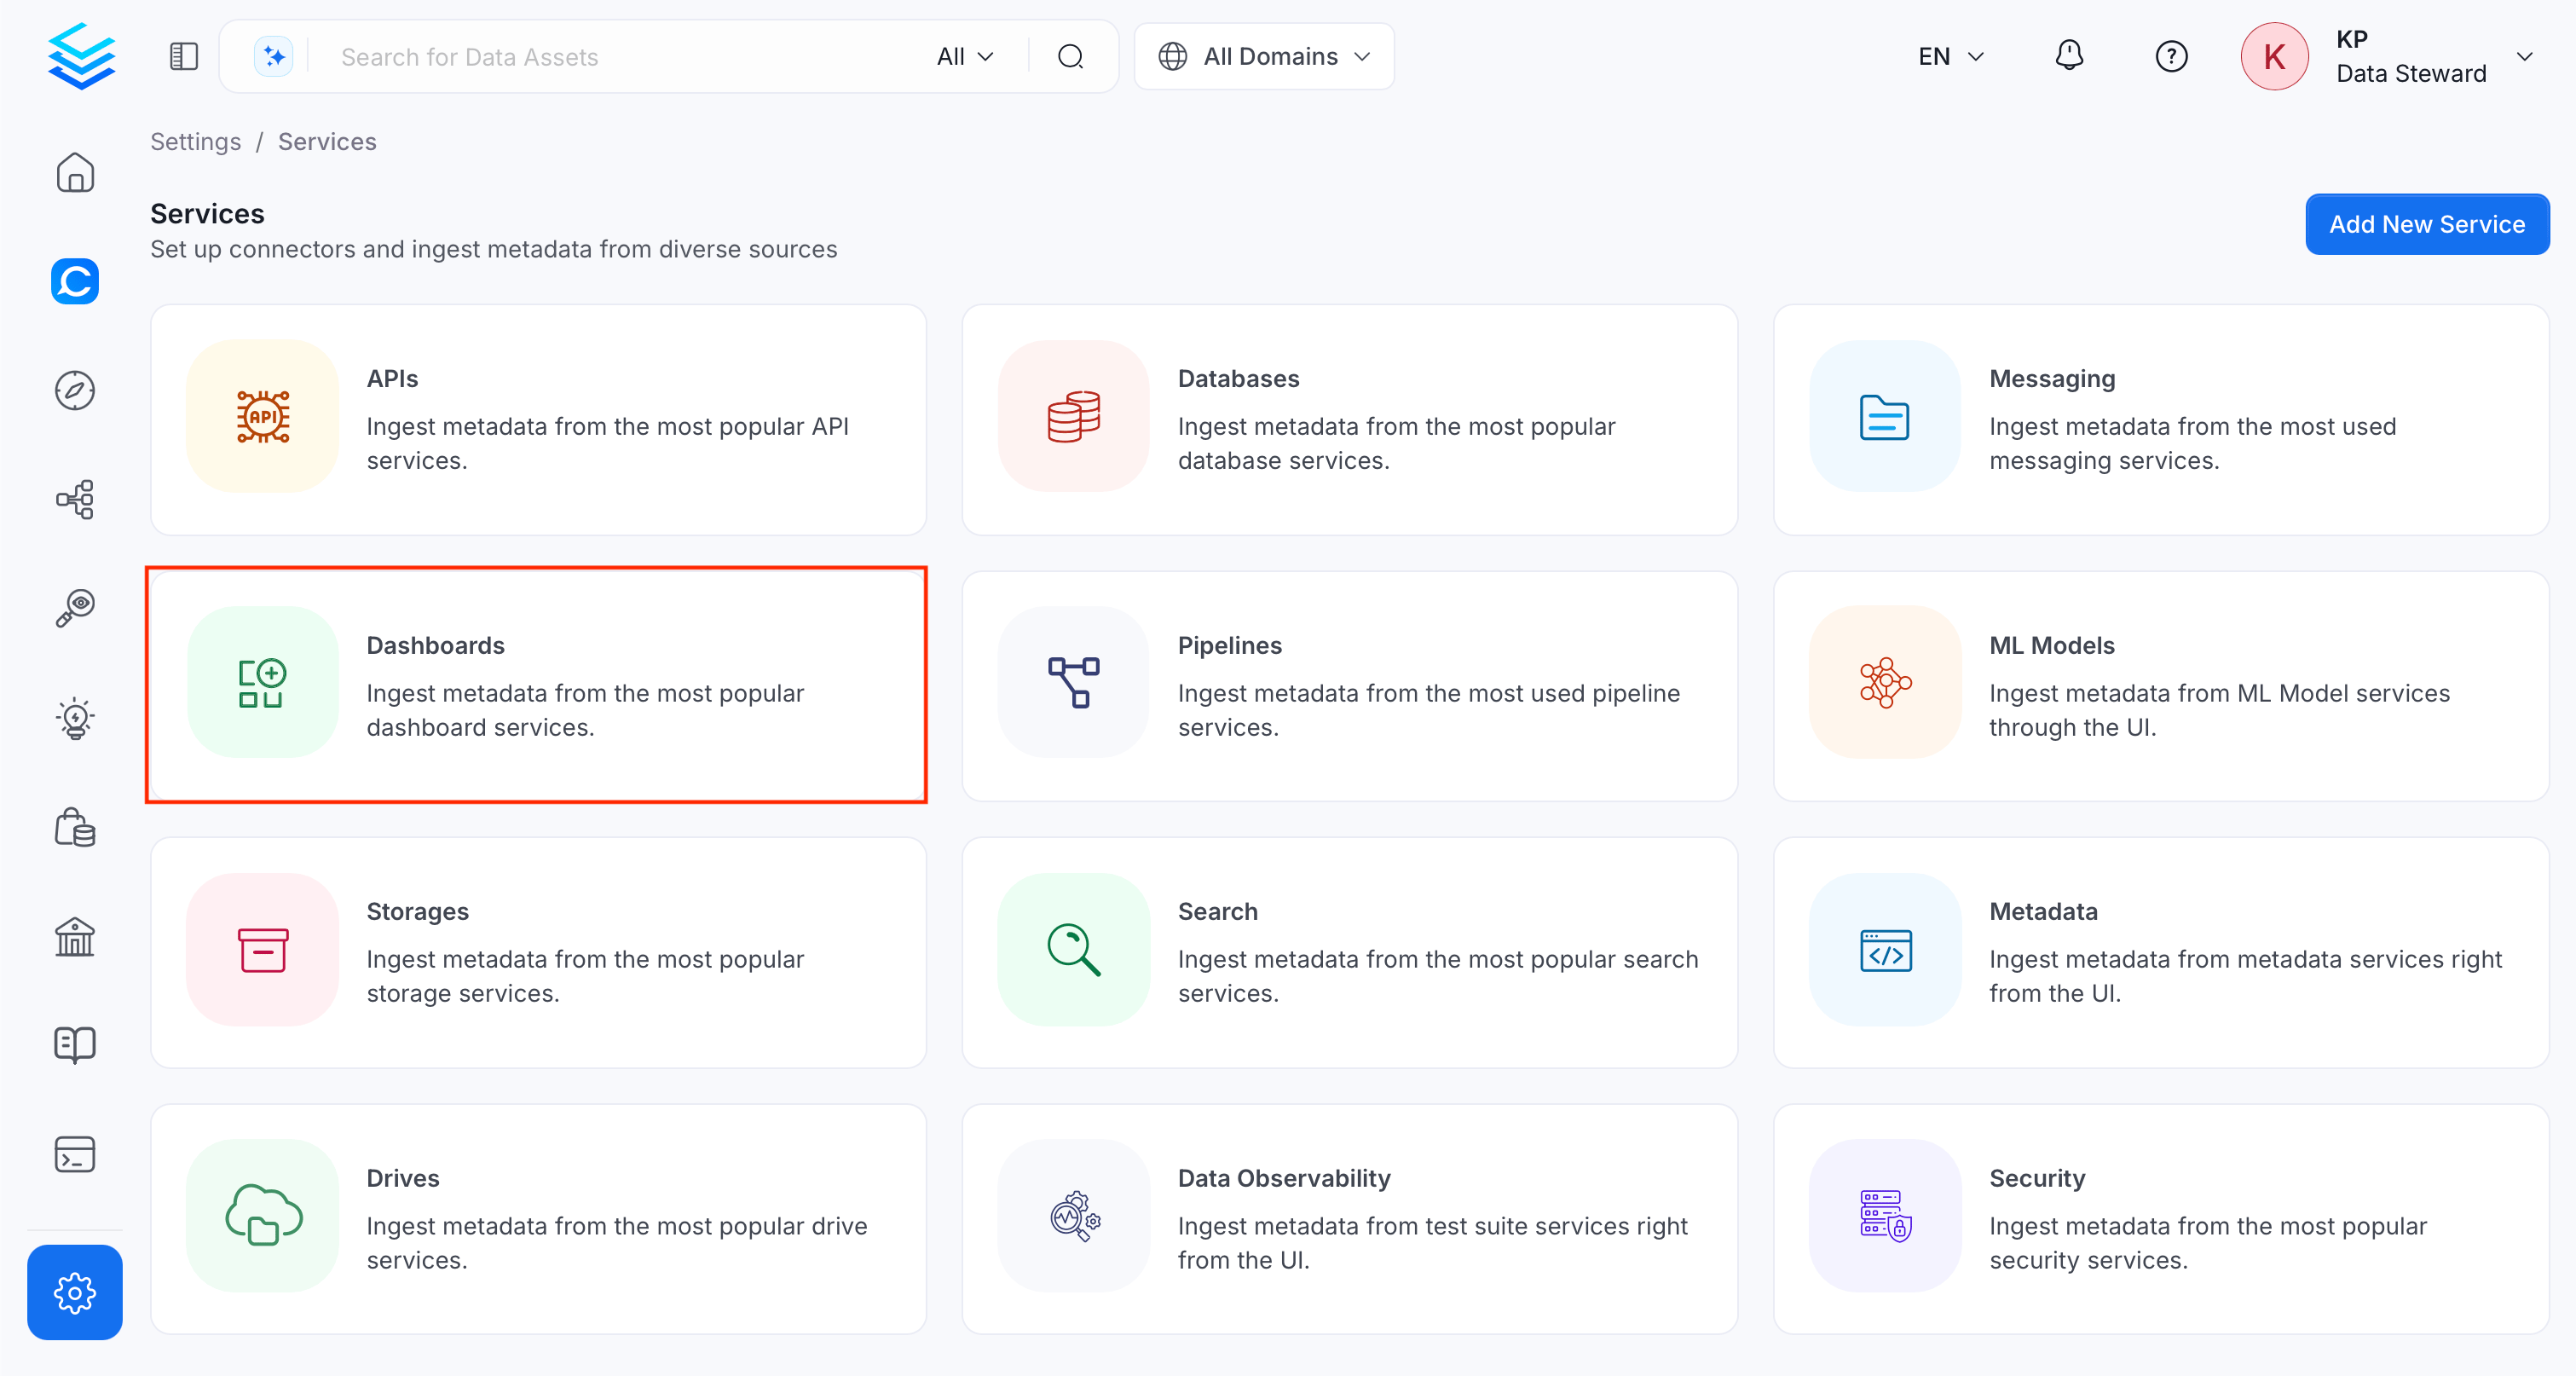
-
Click Add New Service.
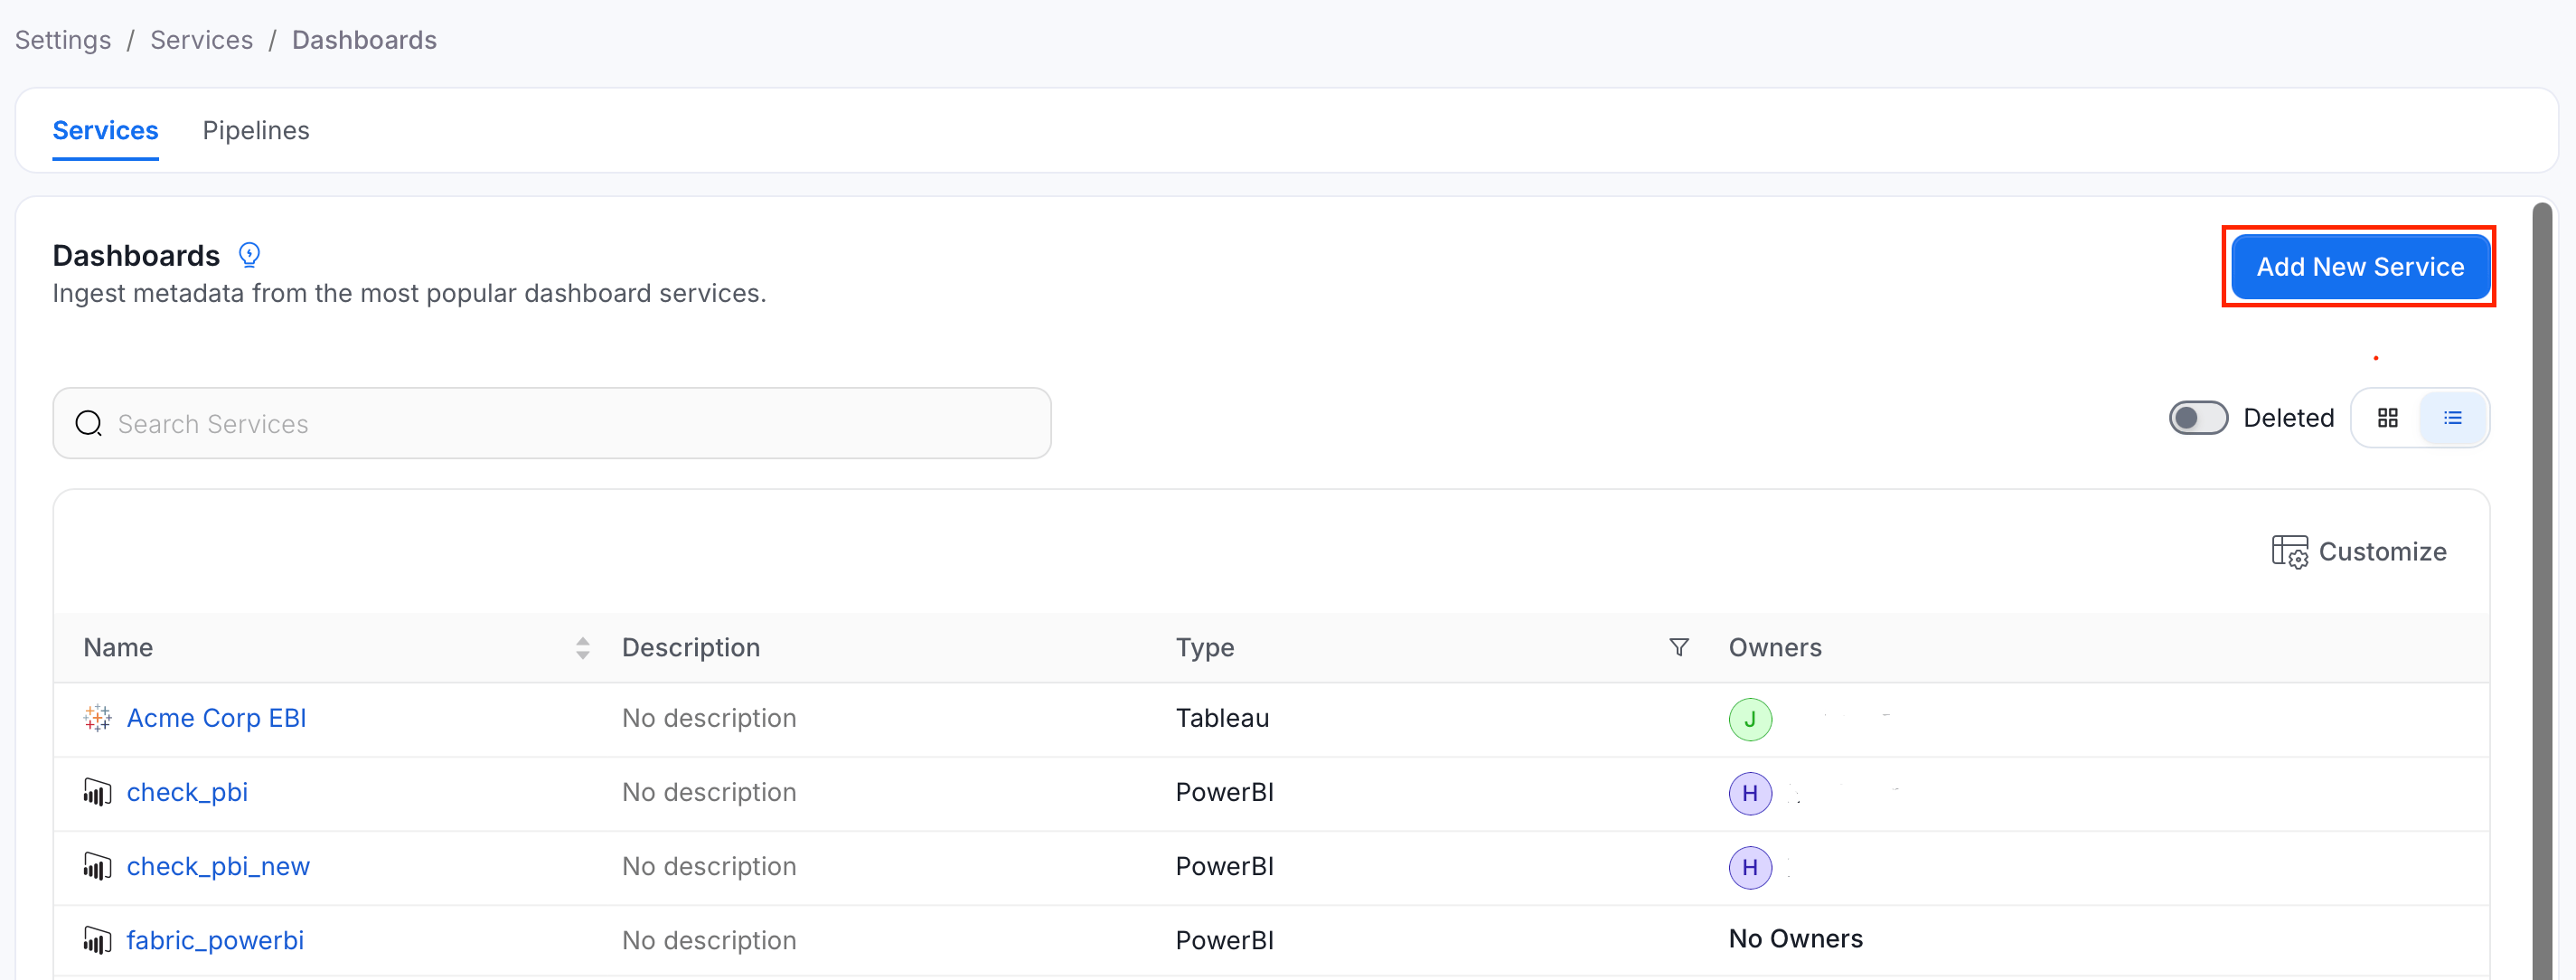
Step 2: Select a Service and Connector
From the service type dropdown, select Dashboard Services, then click the QuickSight connector tile.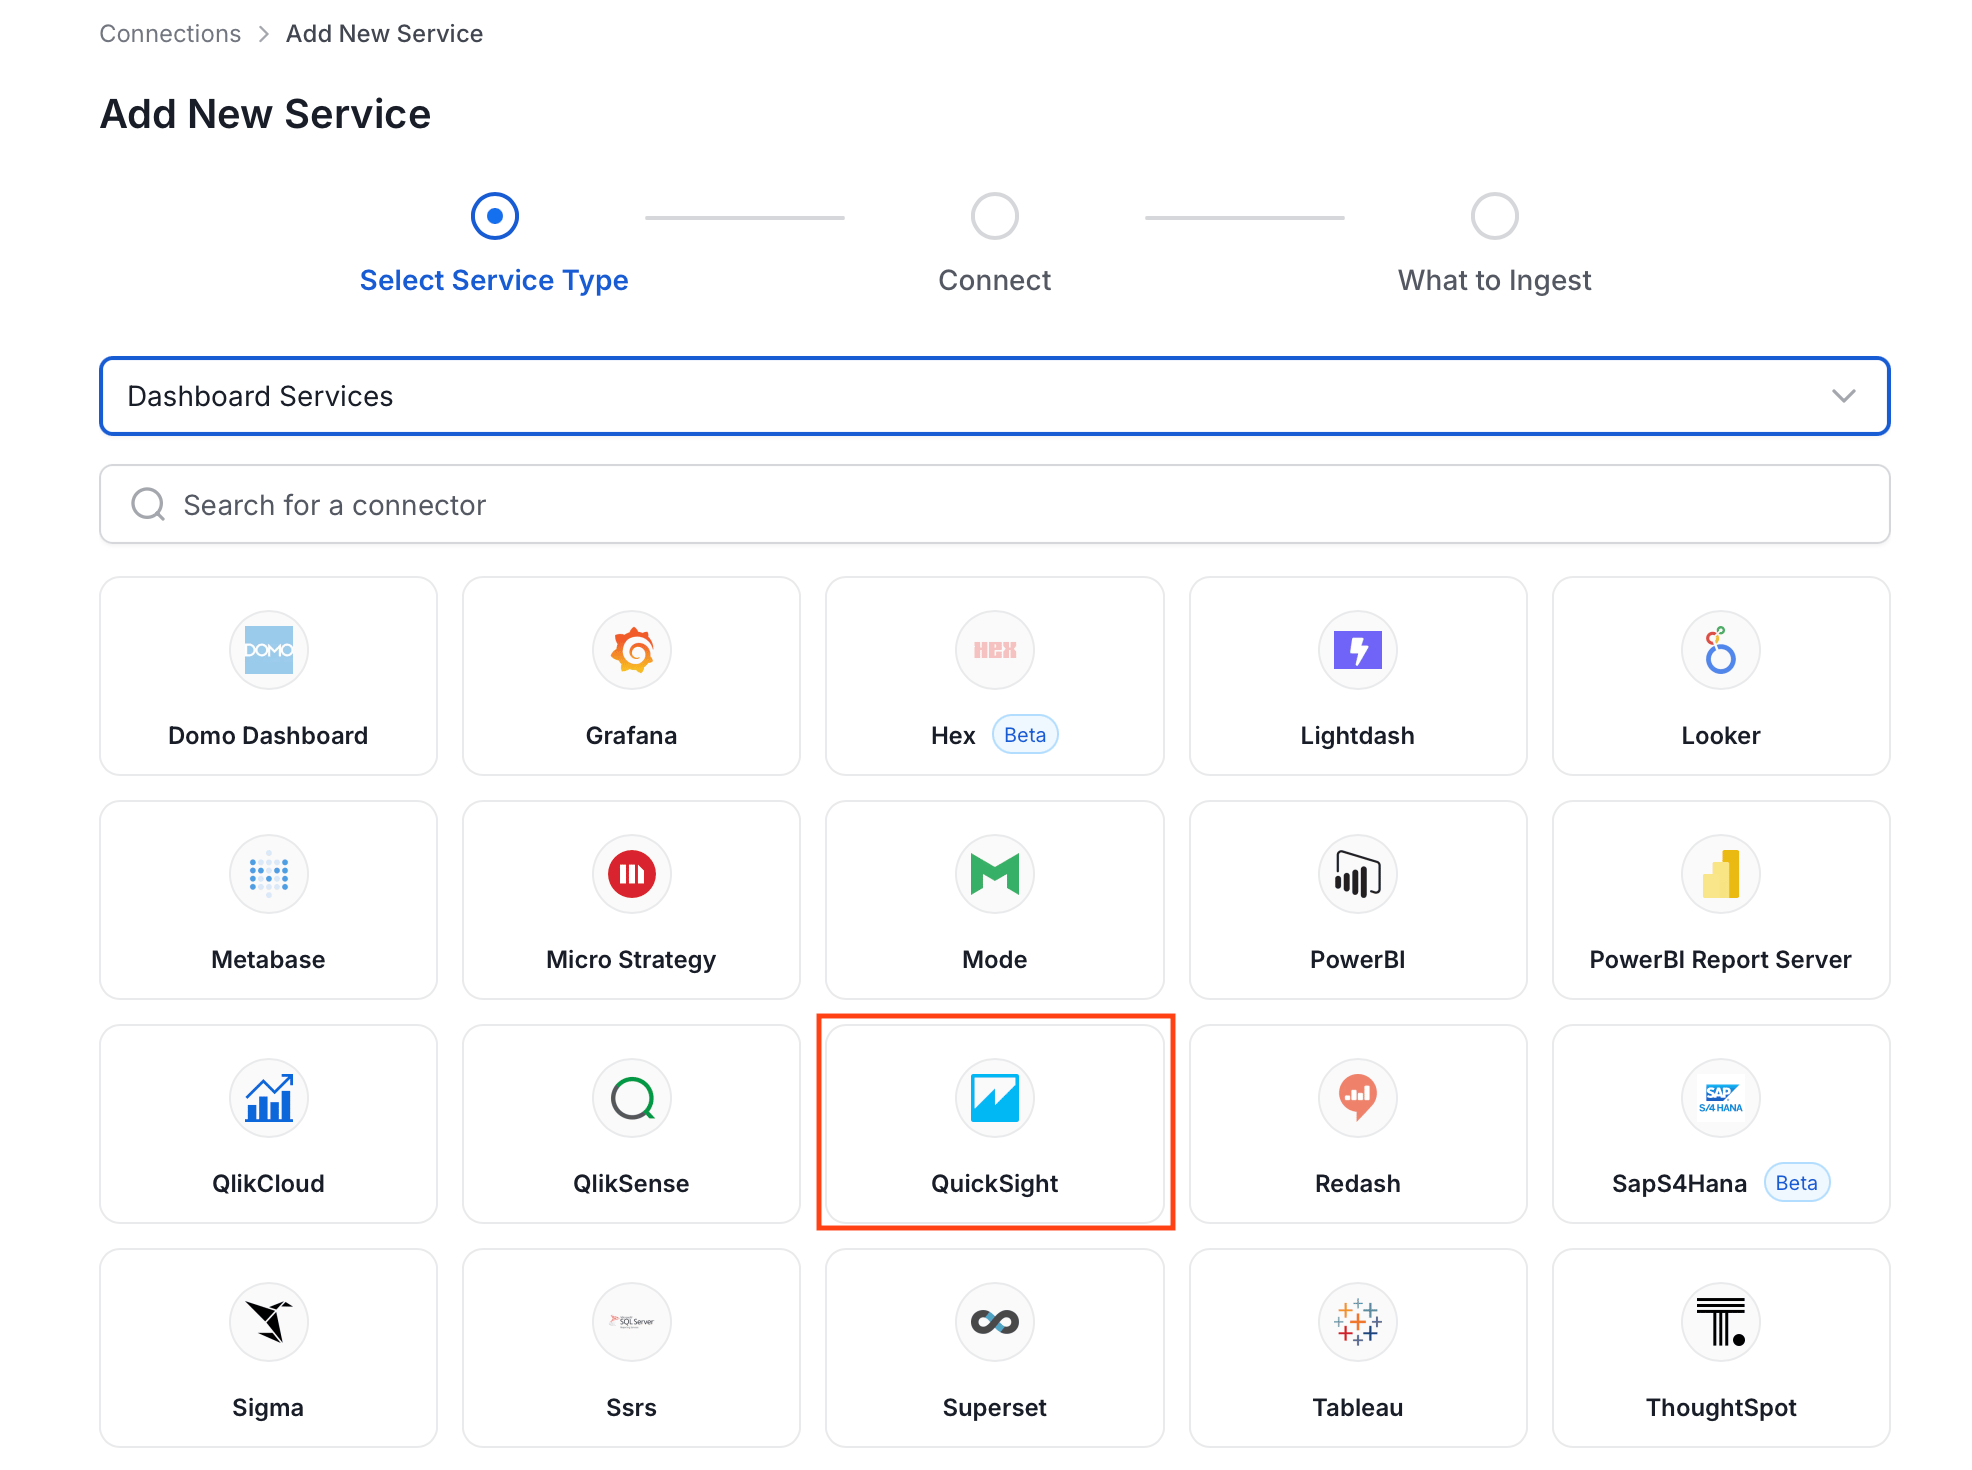
Step 3: Add Service Name and Description
- Enter a unique, descriptive Service Name. Collate identifies services by their service name. Enter a name that distinguishes this deployment from other QuickSight services you are ingesting metadata from.
- Optional: Enter a Description for the service.

Note: The service name can’t be changed after you set it.
Step 4: Configure Connection Options
Specify where ingestion runs, provide your source credentials, and verify the connection.Select Ingestion Runner
Select an Ingestion Runner: the runner where the ingestion pipeline will execute.
Enter Connection Details
Enter the connection details for QuickSight. The right-hand panel in the UI displays inline help for each field.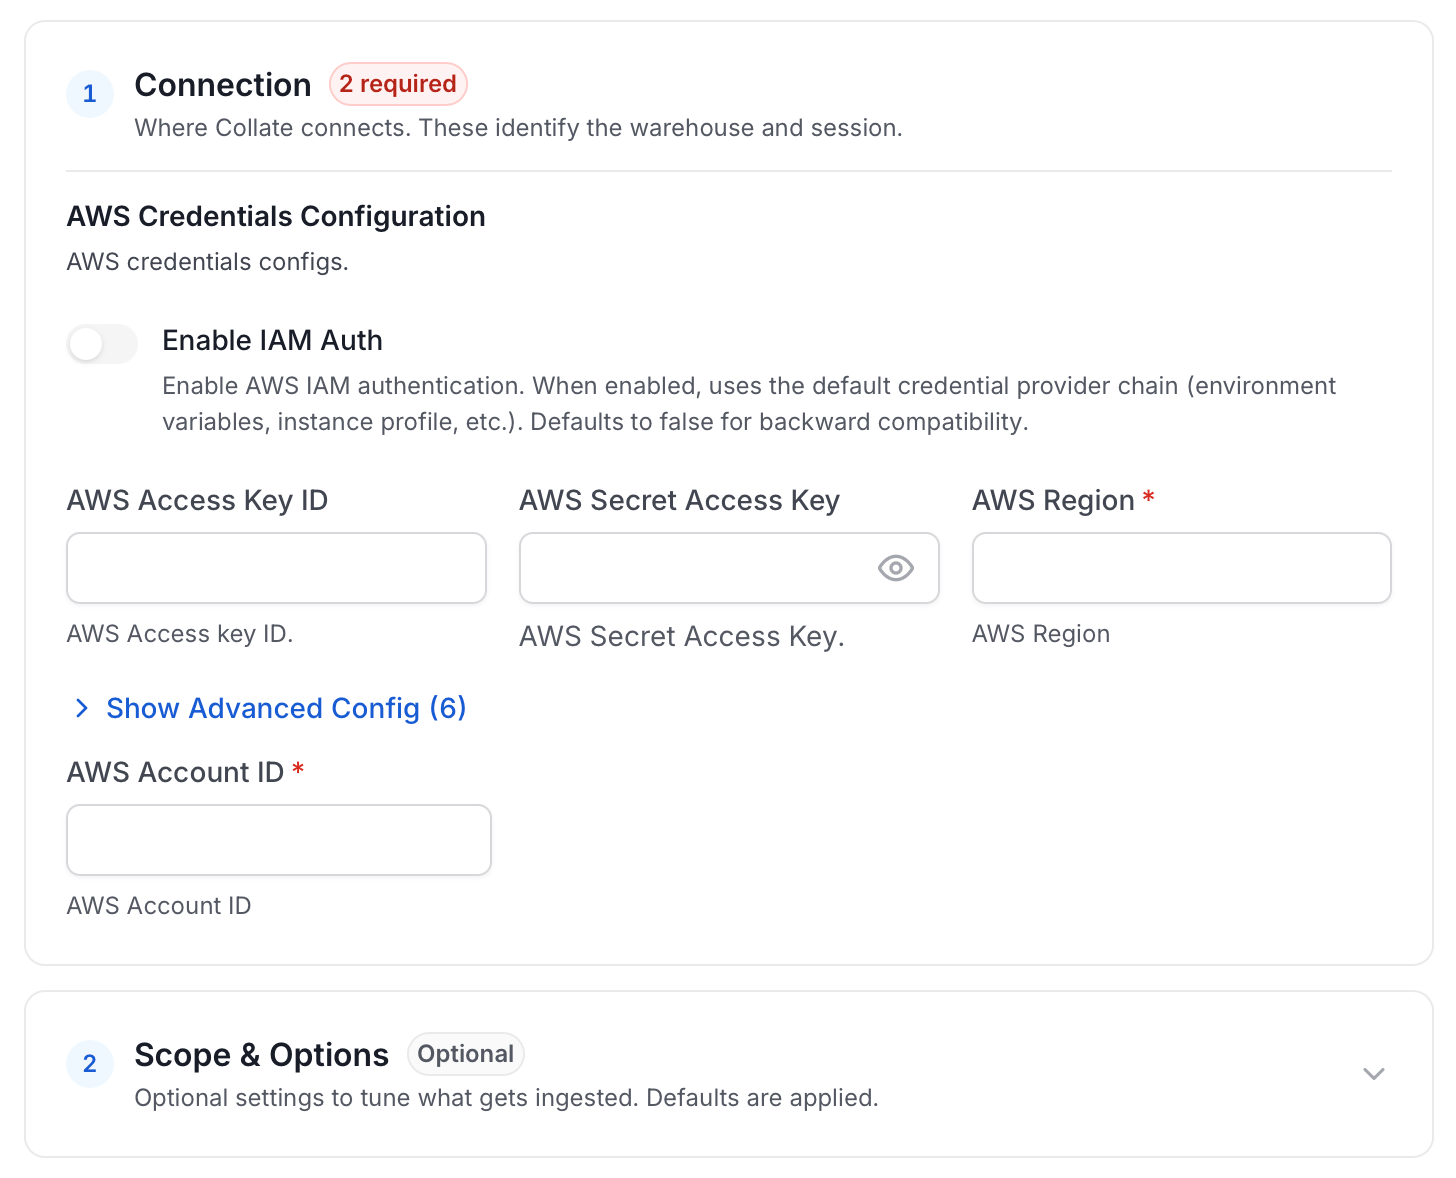
- AWS Access Key ID and AWS Secret Access Key: When you interact with AWS, you specify your AWS security credentials to verify who you are and whether you have
permission to access the resources that you are requesting. AWS uses the security credentials to authenticate and
authorize your requests (docs).
Access keys consist of two parts: An access key ID (for example,
AKIAIOSFODNN7EXAMPLE), and a secret access key (for example,wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY). You must use both the access key ID and secret access key together to authenticate your requests. For more information, see how to manage your access keys. - AWS Region: Each AWS Region is a separate geographic area in which AWS clusters data centers (docs). As AWS can have instances in multiple regions, Collate needs to know the region of the service you want to reach. The AWS Region is the only required parameter when configuring a connection. When connecting to services programmatically, Collate can extract and use the rest of the AWS configuration in different ways. For more information, see configuring your credentials.
- AWS Session Token (optional): If you are using temporary credentials to access your services, provide the AWS Access Key ID and AWS Secret Access Key. Temporary credentials also include an AWS Session Token. For more information, see Using temporary credentials with AWS resources.
- Endpoint URL (optional): To connect programmatically to an AWS service, you use an endpoint. An endpoint is the URL of the entry point for an AWS web service. The AWS SDKs and the AWS Command Line Interface (AWS CLI) automatically use the default endpoint for each service in an AWS Region. But you can specify an alternate endpoint for your API requests. Find more information on AWS service endpoints.
- Profile Name: A named profile is a collection of settings and credentials that you can apply to an AWS CLI command.
When you specify a profile to run a command, the settings and credentials are used to run that command.
Multiple named profiles can be stored in the config and credentials files.
You can inform this field if you’d like to use a profile other than
default. Find more information about Named profiles for the AWS CLI. - Assume Role Arn: Typically, you use
AssumeRolewithin your account or for cross-account access. In this field you’ll set theARN(Amazon Resource Name) of the policy of the other account. A user who wants to access a role in a different account must also have permissions that are delegated from the account administrator. The administrator must attach a policy that allows the user to callAssumeRolefor theARNof the role in the other account. This is a required field if you’d like toAssumeRole. Find more information on AssumeRole.
- Assume Role Session Name: An identifier for the assumed role session. Use the role session name to uniquely identify a session when the same role
is assumed by different principals or for different reasons.
By default, Collate uses the name
OpenMetadataSession. For more information, see the Role Session Name. - Assume Role Source Identity: The source identity specified by the principal that is calling the
AssumeRoleoperation. You can use source identity information in AWS CloudTrail logs to determine who took actions with a role. Find more information about Source Identity. - identityType: The authentication method you use to sign in.
- awsAccountId: QuickSight account ID is required to manage QuickSight users, data sources, and reports.
- namespace: The Amazon QuickSight namespace that contains the dashboard IDs in this request. Provide this when identityType is
ANONYMOUS.
Test Connection
- Click Test Connection to verify the credentials.
- After the test succeeds, click Save.
Step 5: Configure Ingestion Options
In the What to Ingest step, use filter patterns to control which assets Collate ingests from your dashboard service. Filter rules match asset names using the following match types.How Filter Patterns Work
- Include: Add one or more comma-separated values. Each value uses one of the following match types. Collate ingests only assets whose names match at least one rule. Leave blank to include all assets.
- Exclude: Add one or more comma-separated values. Each value uses one of the following match types. Collate skips any asset whose name matches a rule. Leave blank to exclude nothing.
- contains: matches any name containing the value. For example,
salesmatchesmy_sales_dataandsales_2024. - starts with: matches names beginning with the value. For example,
prod_matchesprod_dbandprod_schema. - ends with: matches names ending with the value. For example,
_rawmatchesevents_rawandlogs_raw. - is exactly: matches the exact name only. For example,
analyticsmatches onlyanalytics. - matches regex: matches names using a regular expression. For example,
^prod_.*_v\d+$matchesprod_events_v1.
Filter Options
The Dashboard and Chart sections each include the following filter options:- Dashboard: Controls which dashboards Collate ingests from the source.
- Chart: Controls which charts within the ingested dashboards are included.
- Scan Mode: Choose between the following scan modes:
- Scan all: Ingests every asset of that type the connector can access. This is the default.
- Only specific: Enables include rules so only assets matching at least one rule are ingested.
- Exclude system toggle: Use this toggle to filter out system-reserved names defined by the connector for that asset type.
- Always exclude: Add permanent exclusion rules (shown in red). Assets matching these rules are never ingested, regardless of include rules.
- Preview: Shows a real-time summary of what will be in scope based on your current rules.
- Include rules: In Only specific mode, click + Add to define a rule. Added rules appear as chips. An asset is included if it matches any rule.
Step 6: Create & Deploy
Click Create & Deploy to deploy the agent and start the first metadata ingestion run. Collate saves the service configuration and immediately begins pulling metadata from the source. To monitor ingestion progress or view the service you just added, go to Settings > Services and select your service.Configure Metadata Agent and Schedule Ingestion
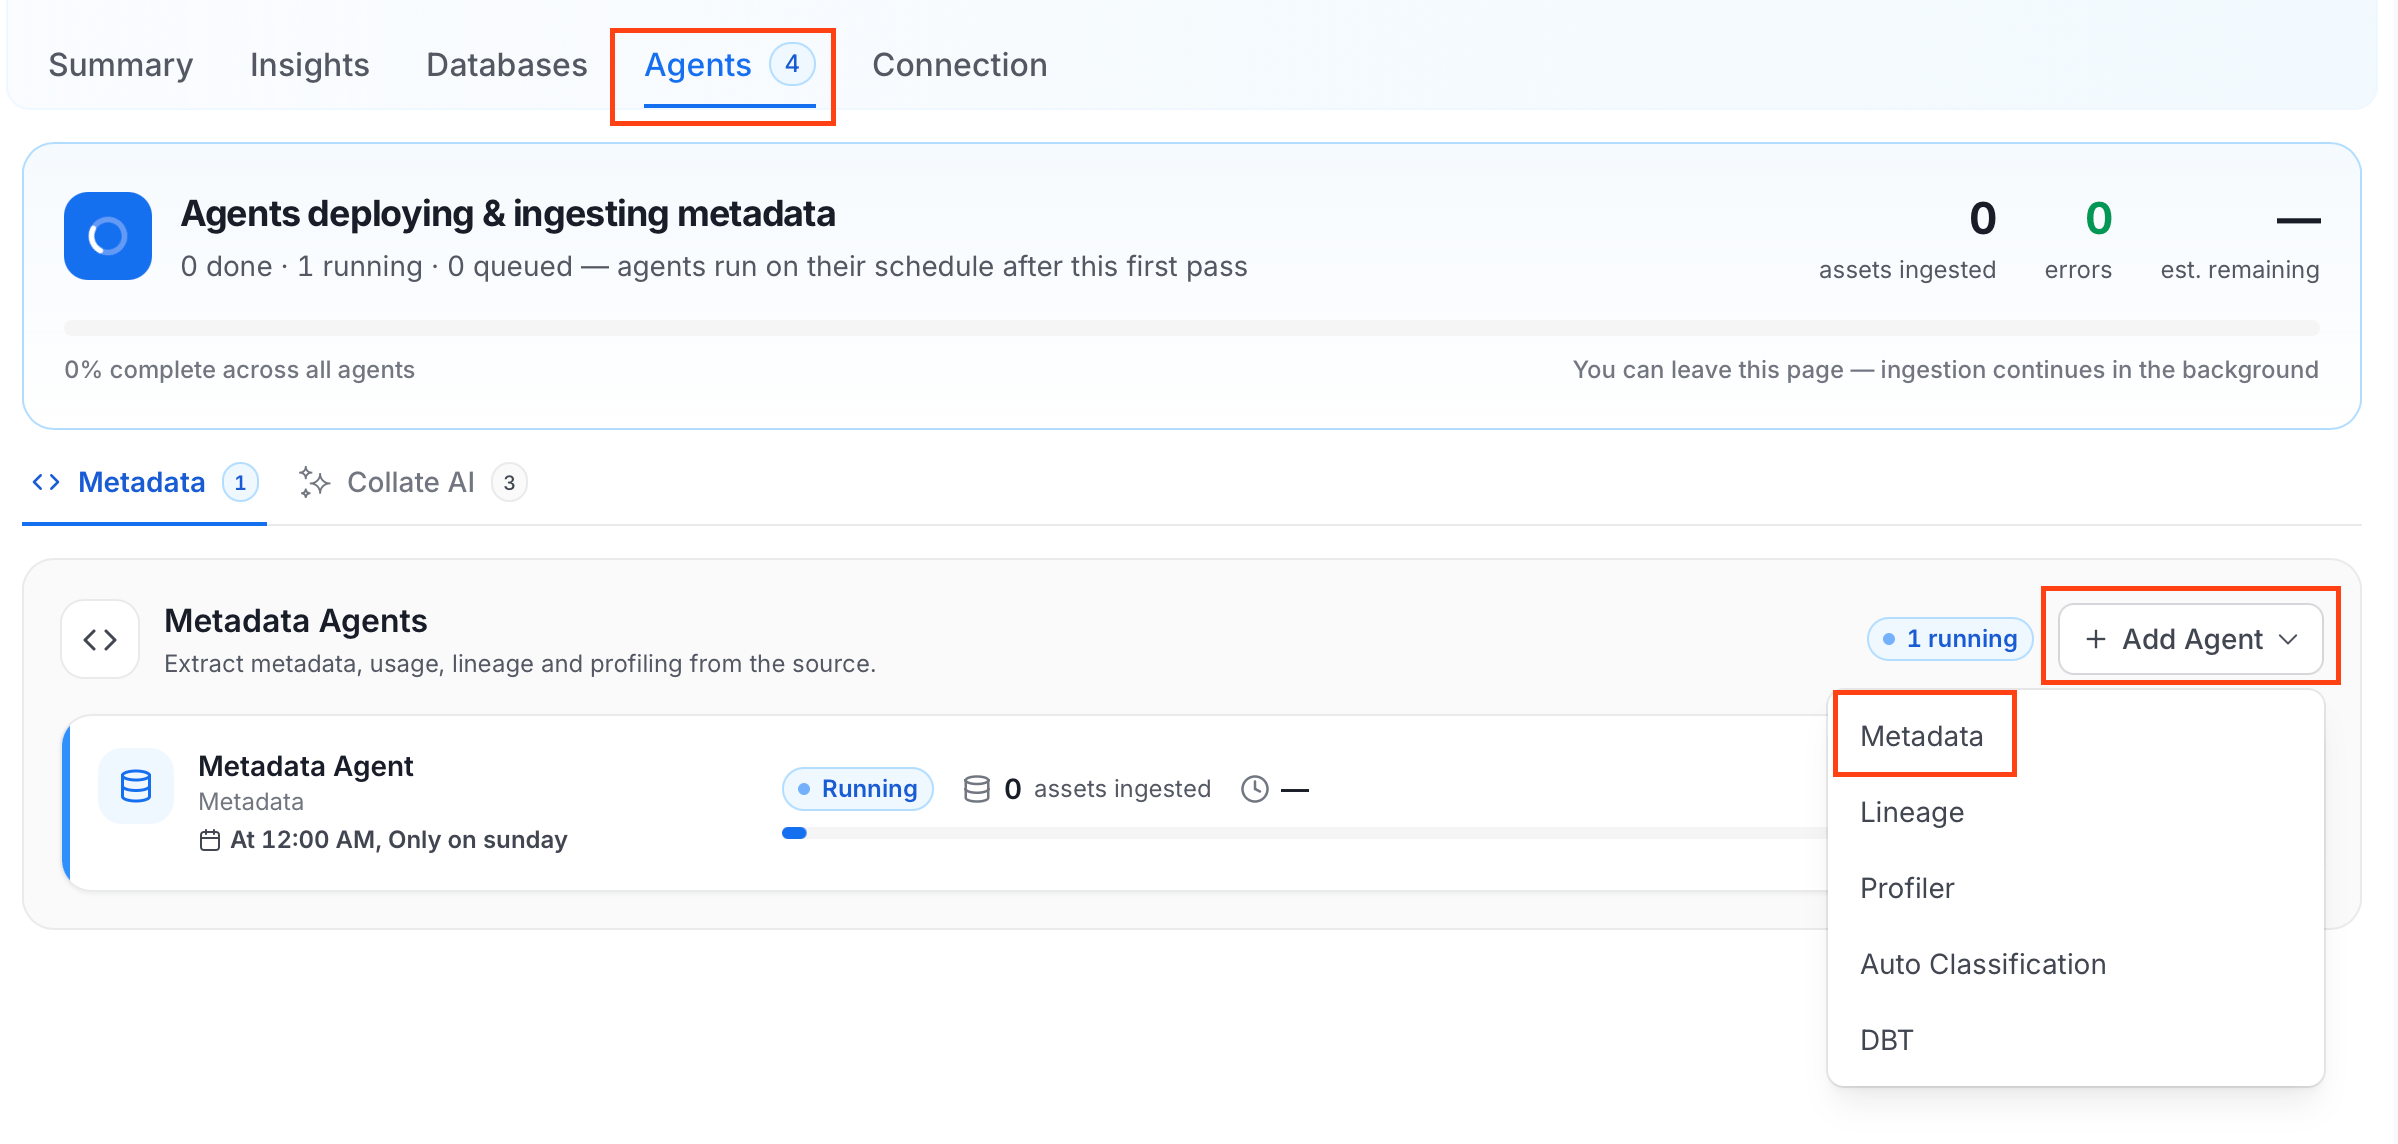
The Metadata Agent extracts dashboards, charts, data models, and other structural metadata from your source and keeps your Collate catalog in sync. It powers discovery, lineage, and governance across your data assets. When you click Create & Deploy, Collate automatically deploys a Metadata Agent for this service and triggers the first ingestion run. View its status and run history from the Agents tab on the service detail page. To configure the additional Metadata Agent and schedule ingestion, follow these steps:- Navigate to Settings > Services and select the Dashboards service.
- Select your service and click the Agents tab.
-
Click Add Agent and select Metadata from the dropdown.
-
On the Configure Ingestion page, do the following and click Next.
-
Name this Ingestion: Enter a unique, recognizable name for this ingestion pipeline.

-
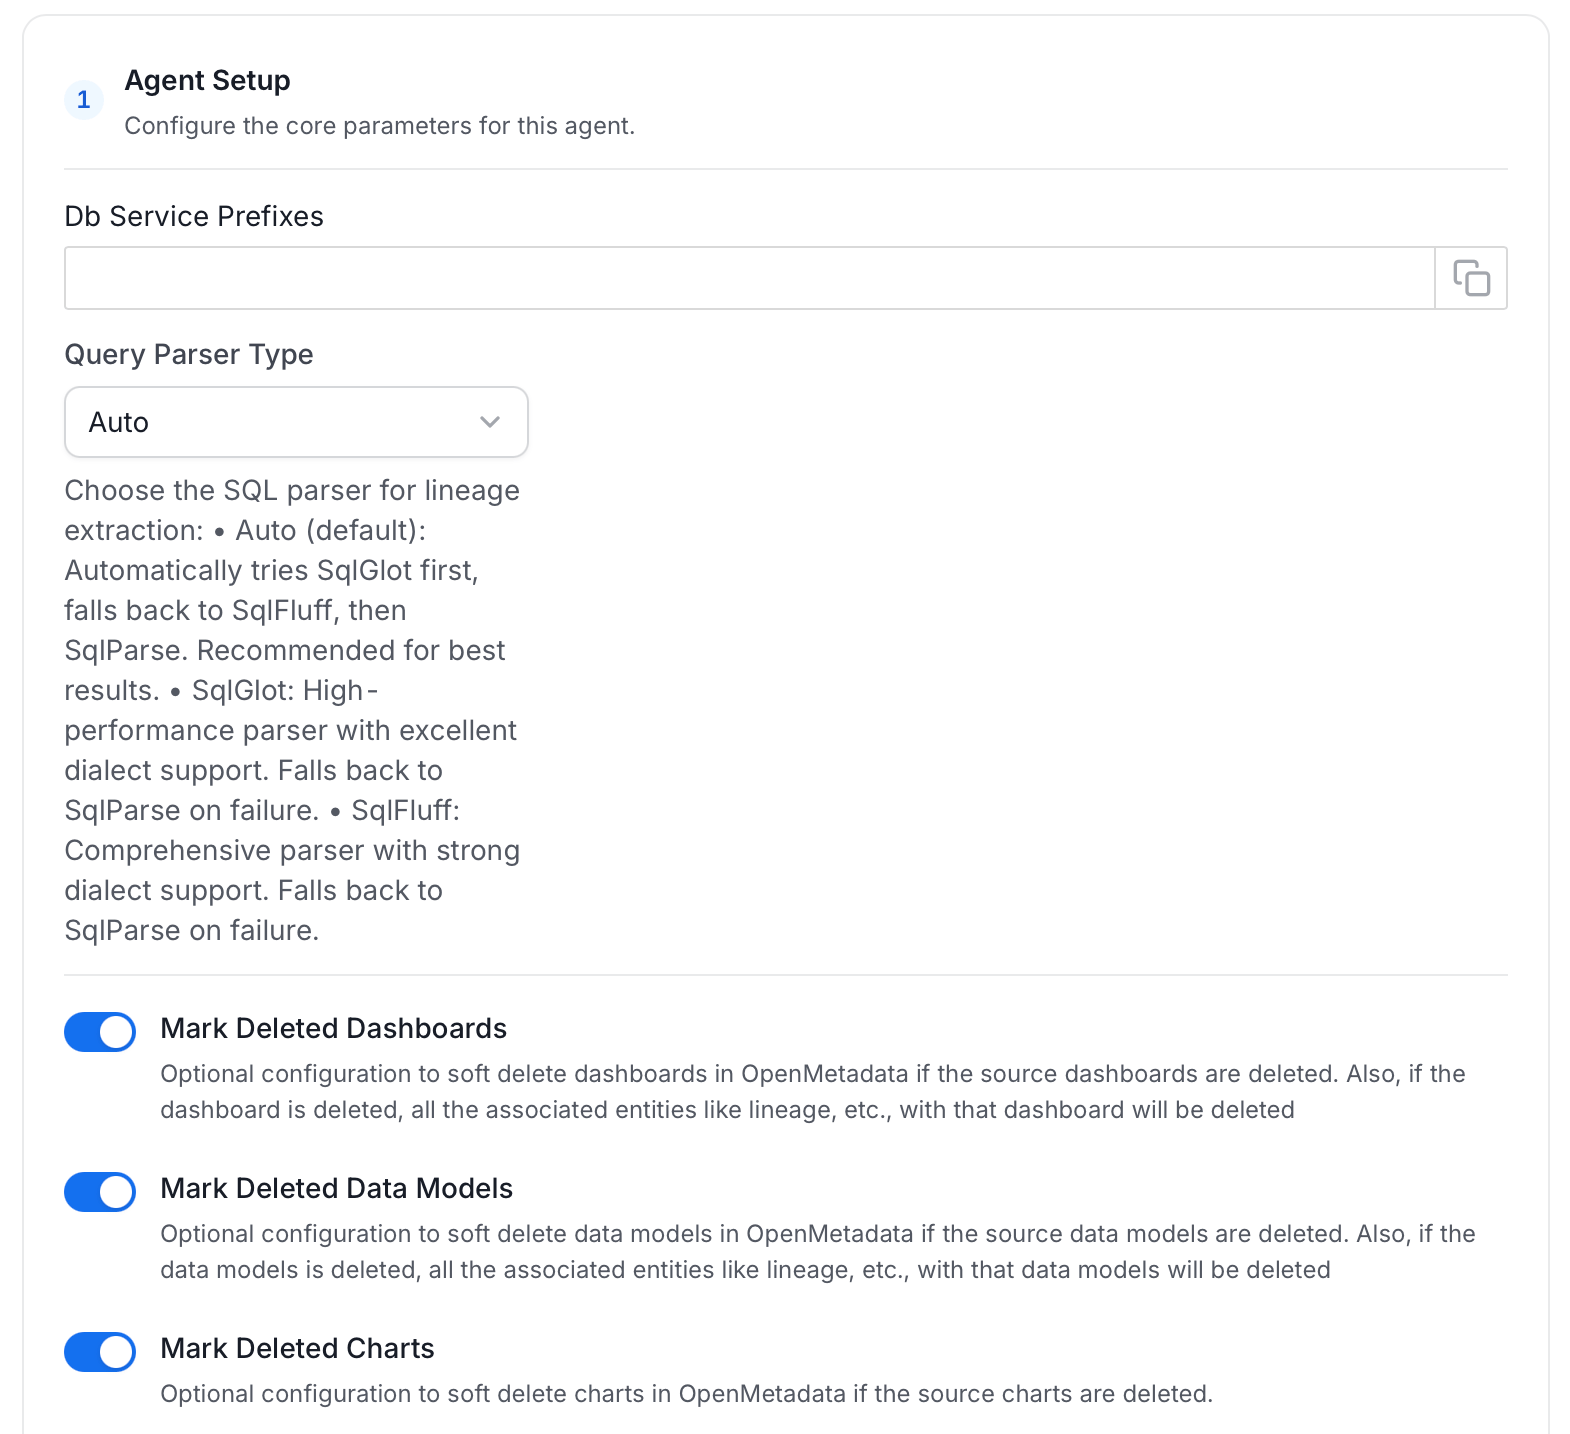
Agent Setup: Configure ingestion parameters. The following fields are available:
-
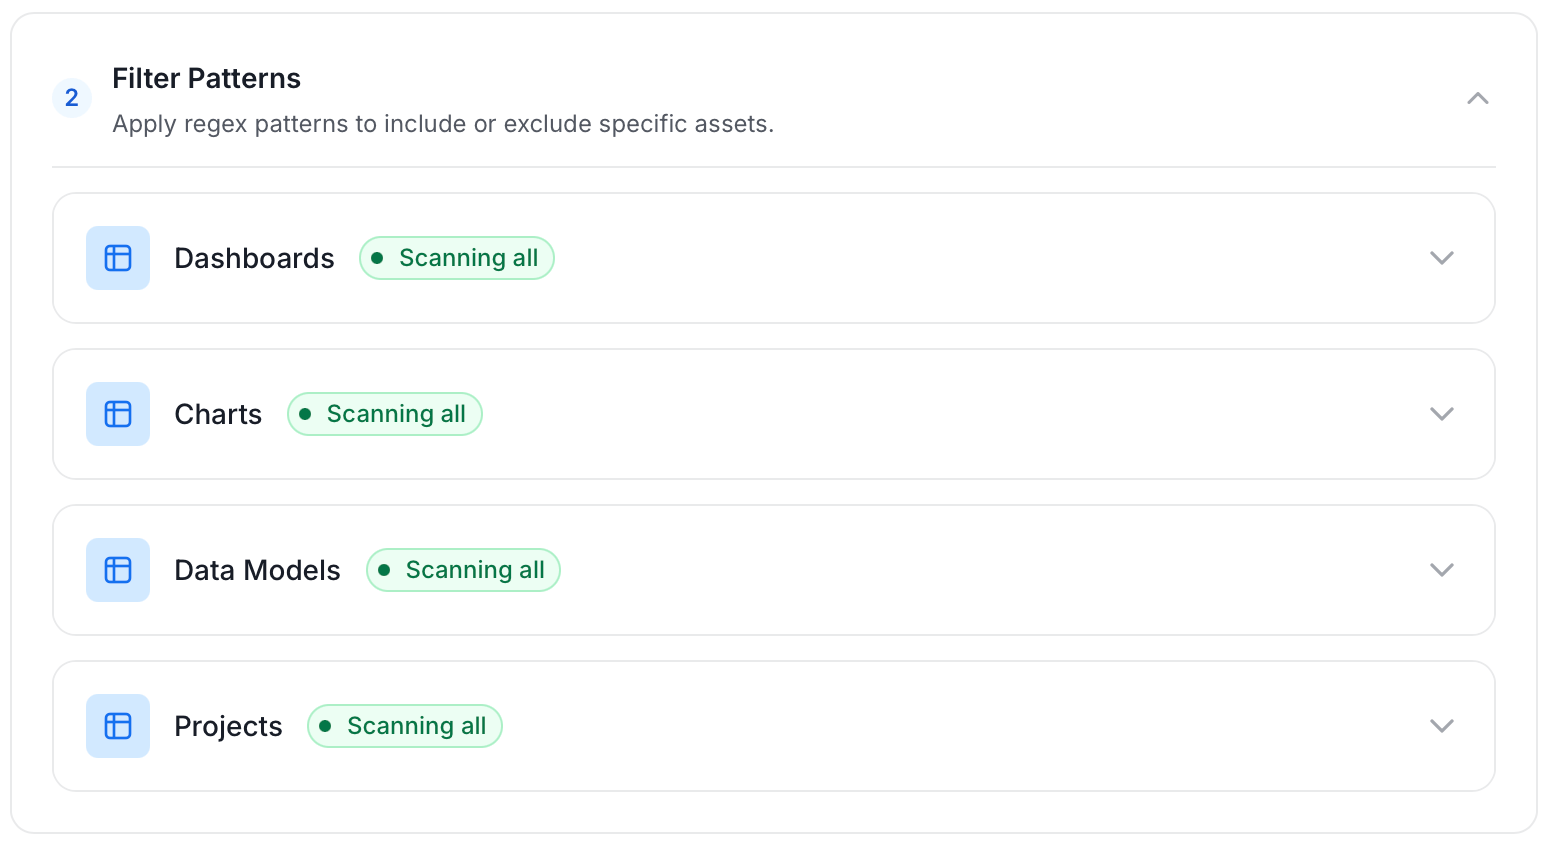
Filter Patterns: Apply include or exclude rules to scope which dashboards, charts, data models, and projects this agent ingests. These follow the same filter options described in Step 5.
-
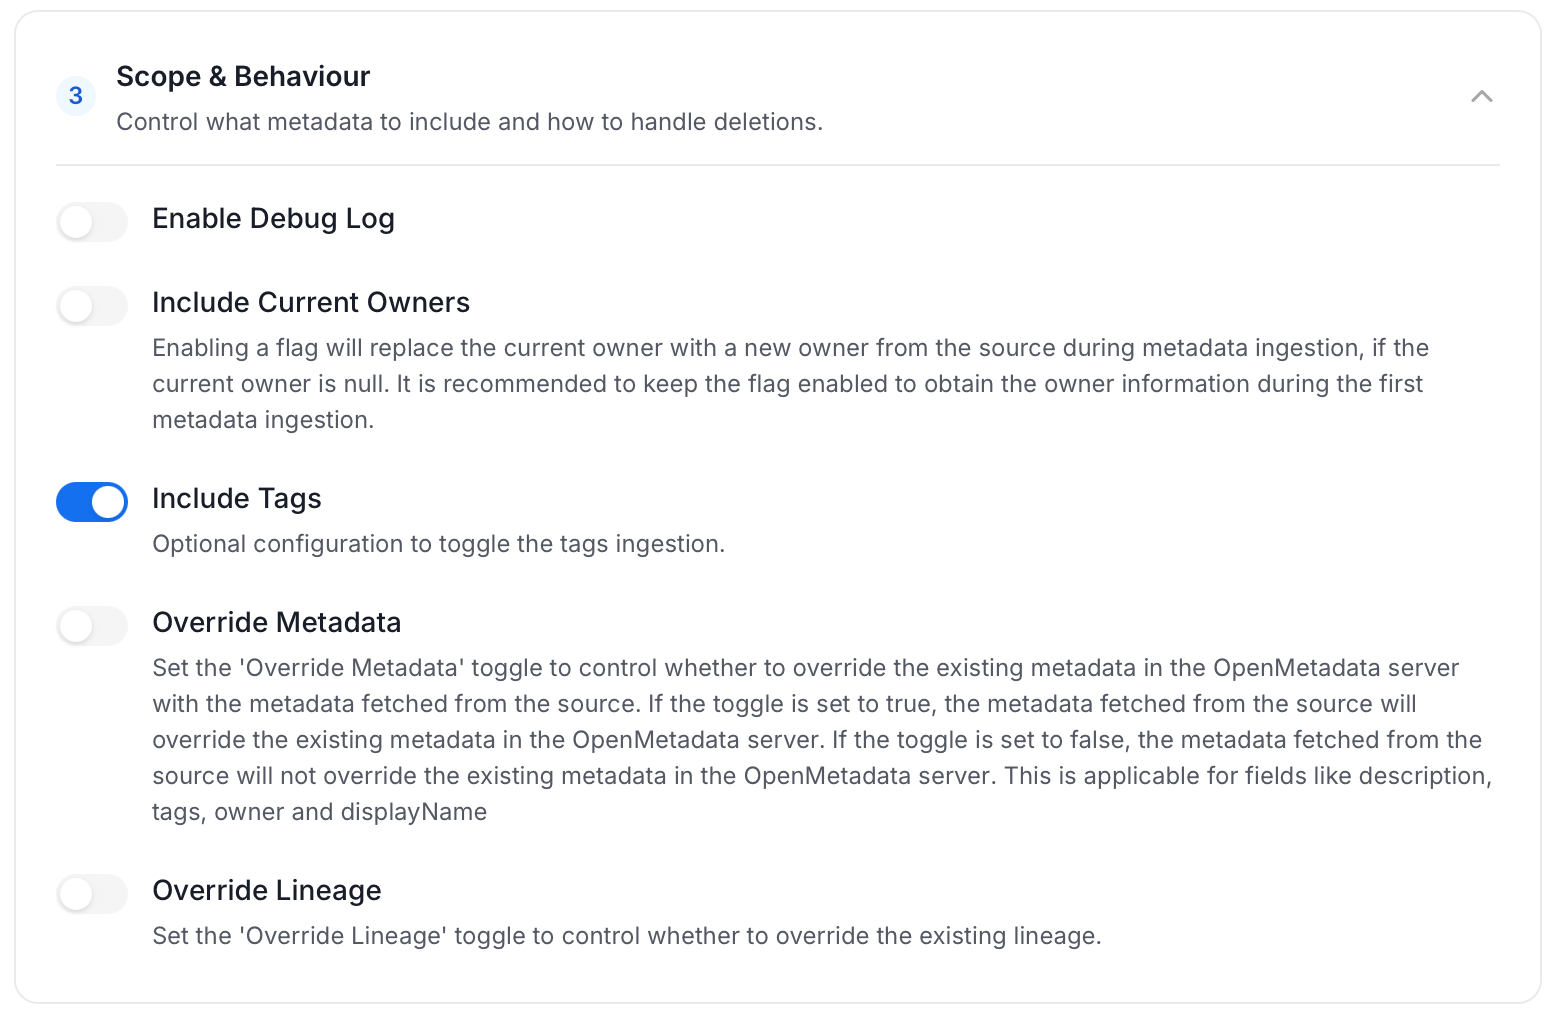
Scope & Behaviour: Control what metadata to include and how to handle deletions. Toggle each option on or off based on your needs:
-
Name this Ingestion: Enter a unique, recognizable name for this ingestion pipeline.
-
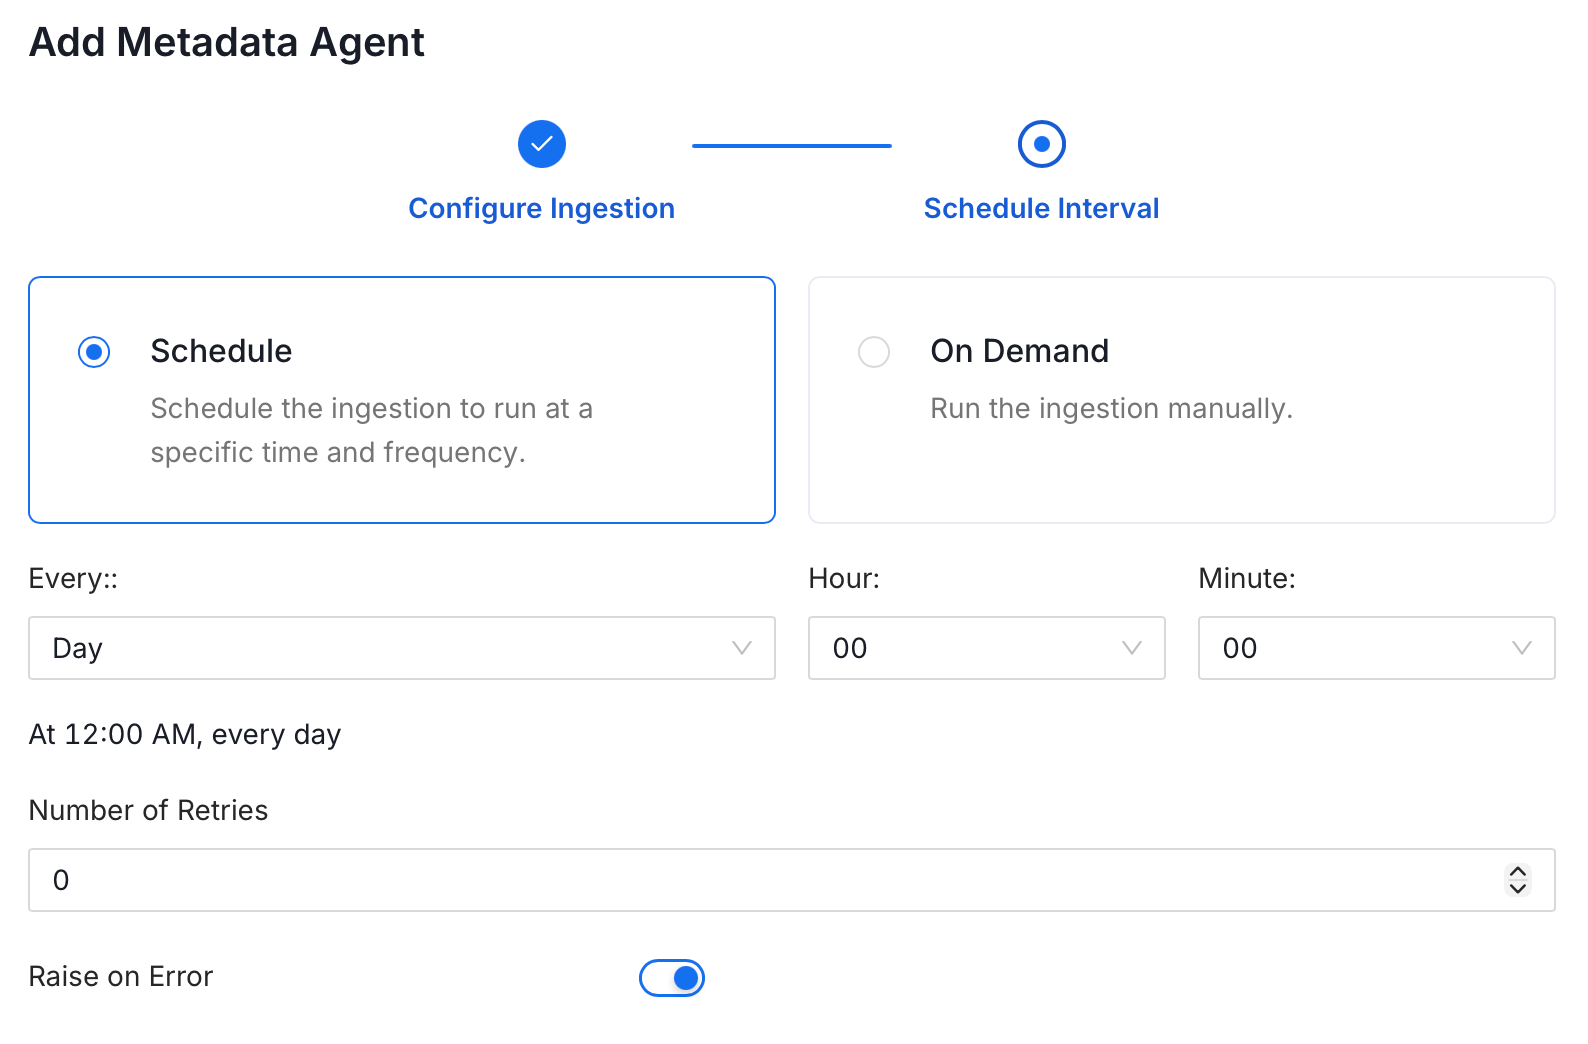
On the Schedule Interval page, set when the agent runs:
- Schedule: Choose a preset interval (Hourly, Daily, Weekly, Monthly) or enter a custom cron expression.
- On-Demand: No automatic schedule. Trigger the agent manually when needed.
- Click Add to deploy the agent.
Lineage
Lineage
Lineage in Collate shows you which database tables power each dashboard. When lineage is set up, you can trace any dashboard back to the exact source tables in your database. There is no separate lineage agent or lineage pipeline—lineage is collected as part of the same metadata ingestion workflow. Configuring the Db Service Prefixes field (covered below) is optional but recommended — it restricts table matching to specific database services. If left blank, Collate attempts to match source tables across all ingested database services.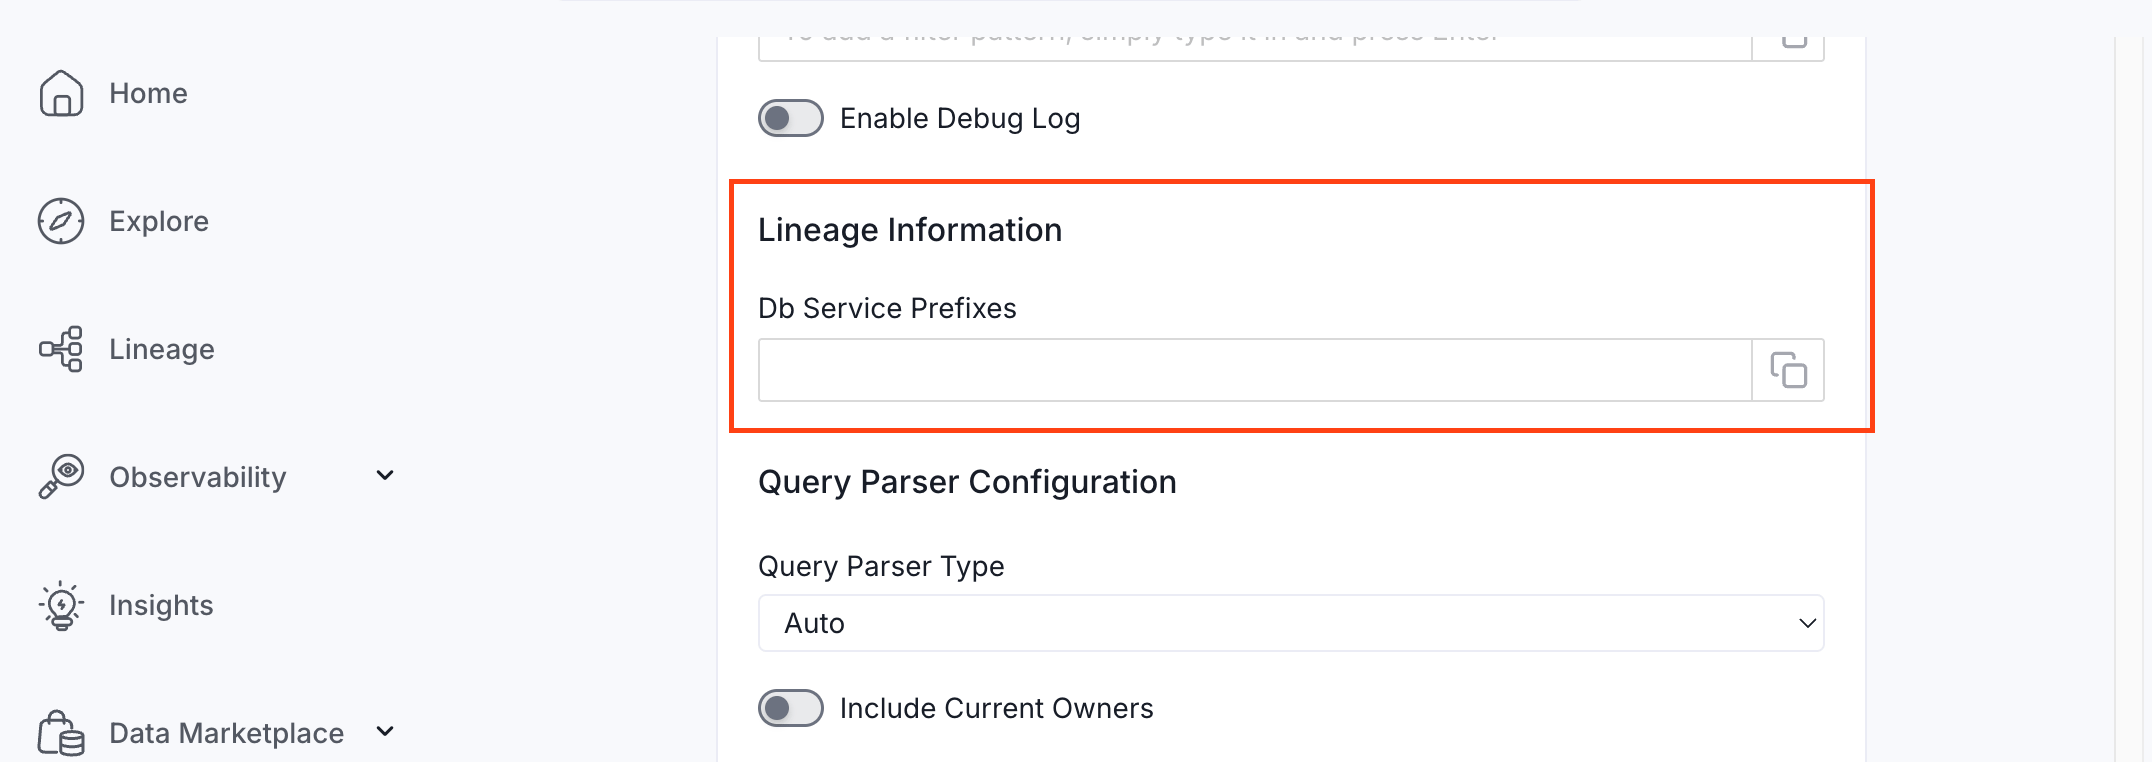
How to Set Up Lineage
- Go to Settings > Services > Dashboards.
- Click the dashboard service you’ve added.
- Go to the Agents tab, then select Add Agent > Add Metadata Agent. If a metadata agent already exists, select the three-dot context menu (⋮) next to it and select Edit.
- In the Configure Ingestion step, scroll down to the Lineage Information section.
- Optionally enter one or more database service names in the Db Service Prefixes field to restrict table matching to specific services. If left blank, Collate searches across all ingested database services.
Troubleshooting
QuickSight Troubleshooting
Learn more about how to troubleshoot common QuickSight connector issues and resolve configuration or ingestion errors.