{icon &&
 }
{name}
{stage}Feature List
{totalAvailableFeatures.map(feature =>
✓ {feature}
)}
{unavailableFeatures.map(feature =>
✕ {feature}
)}
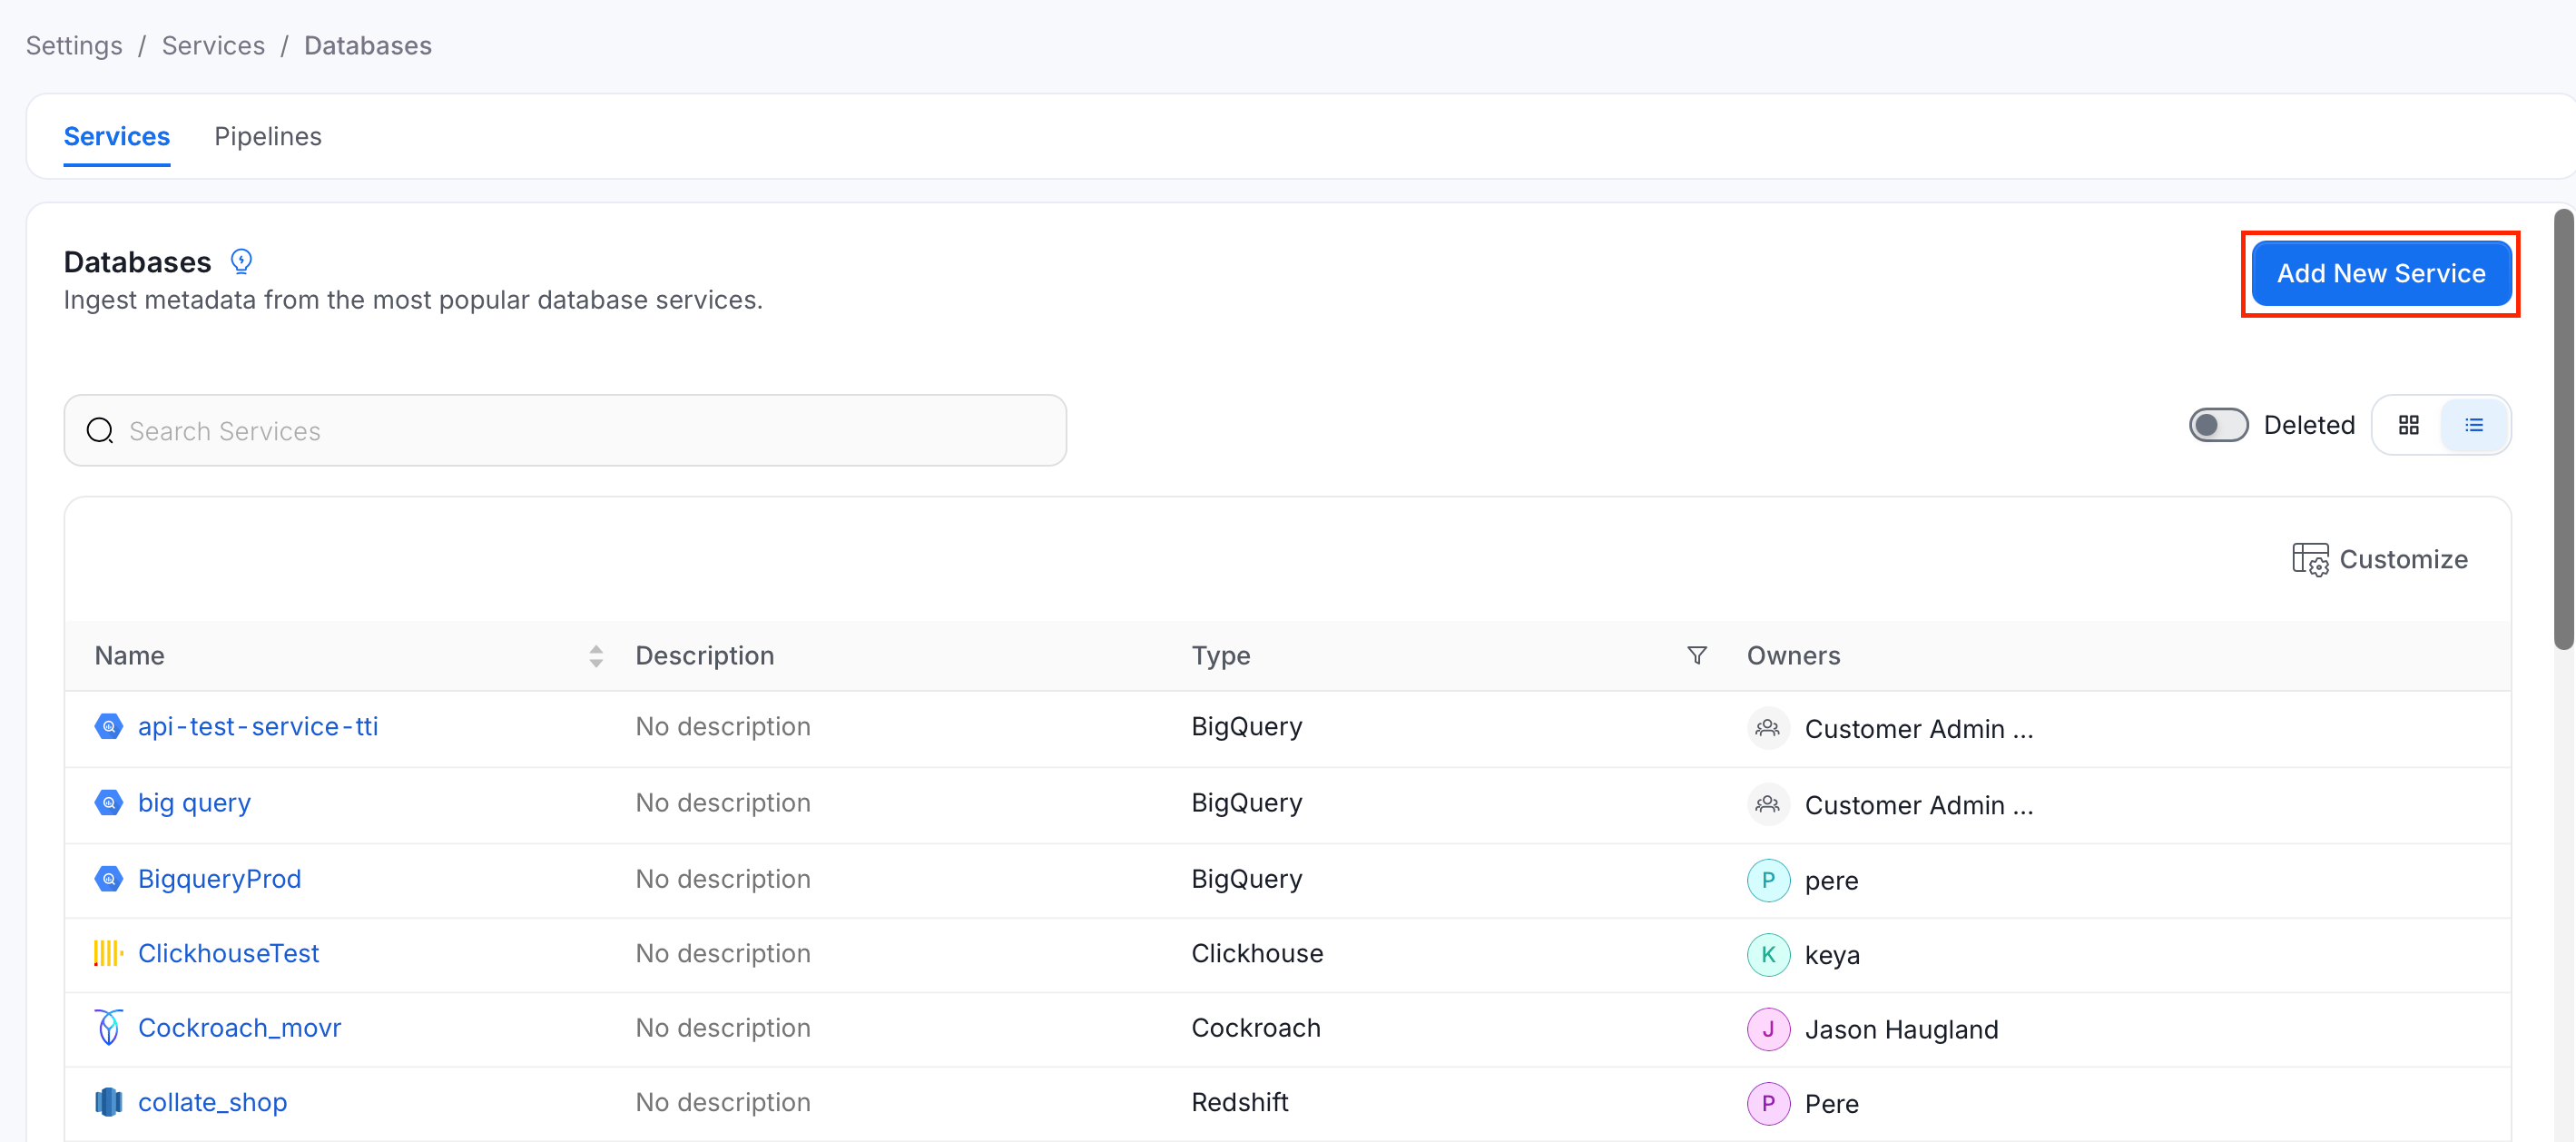
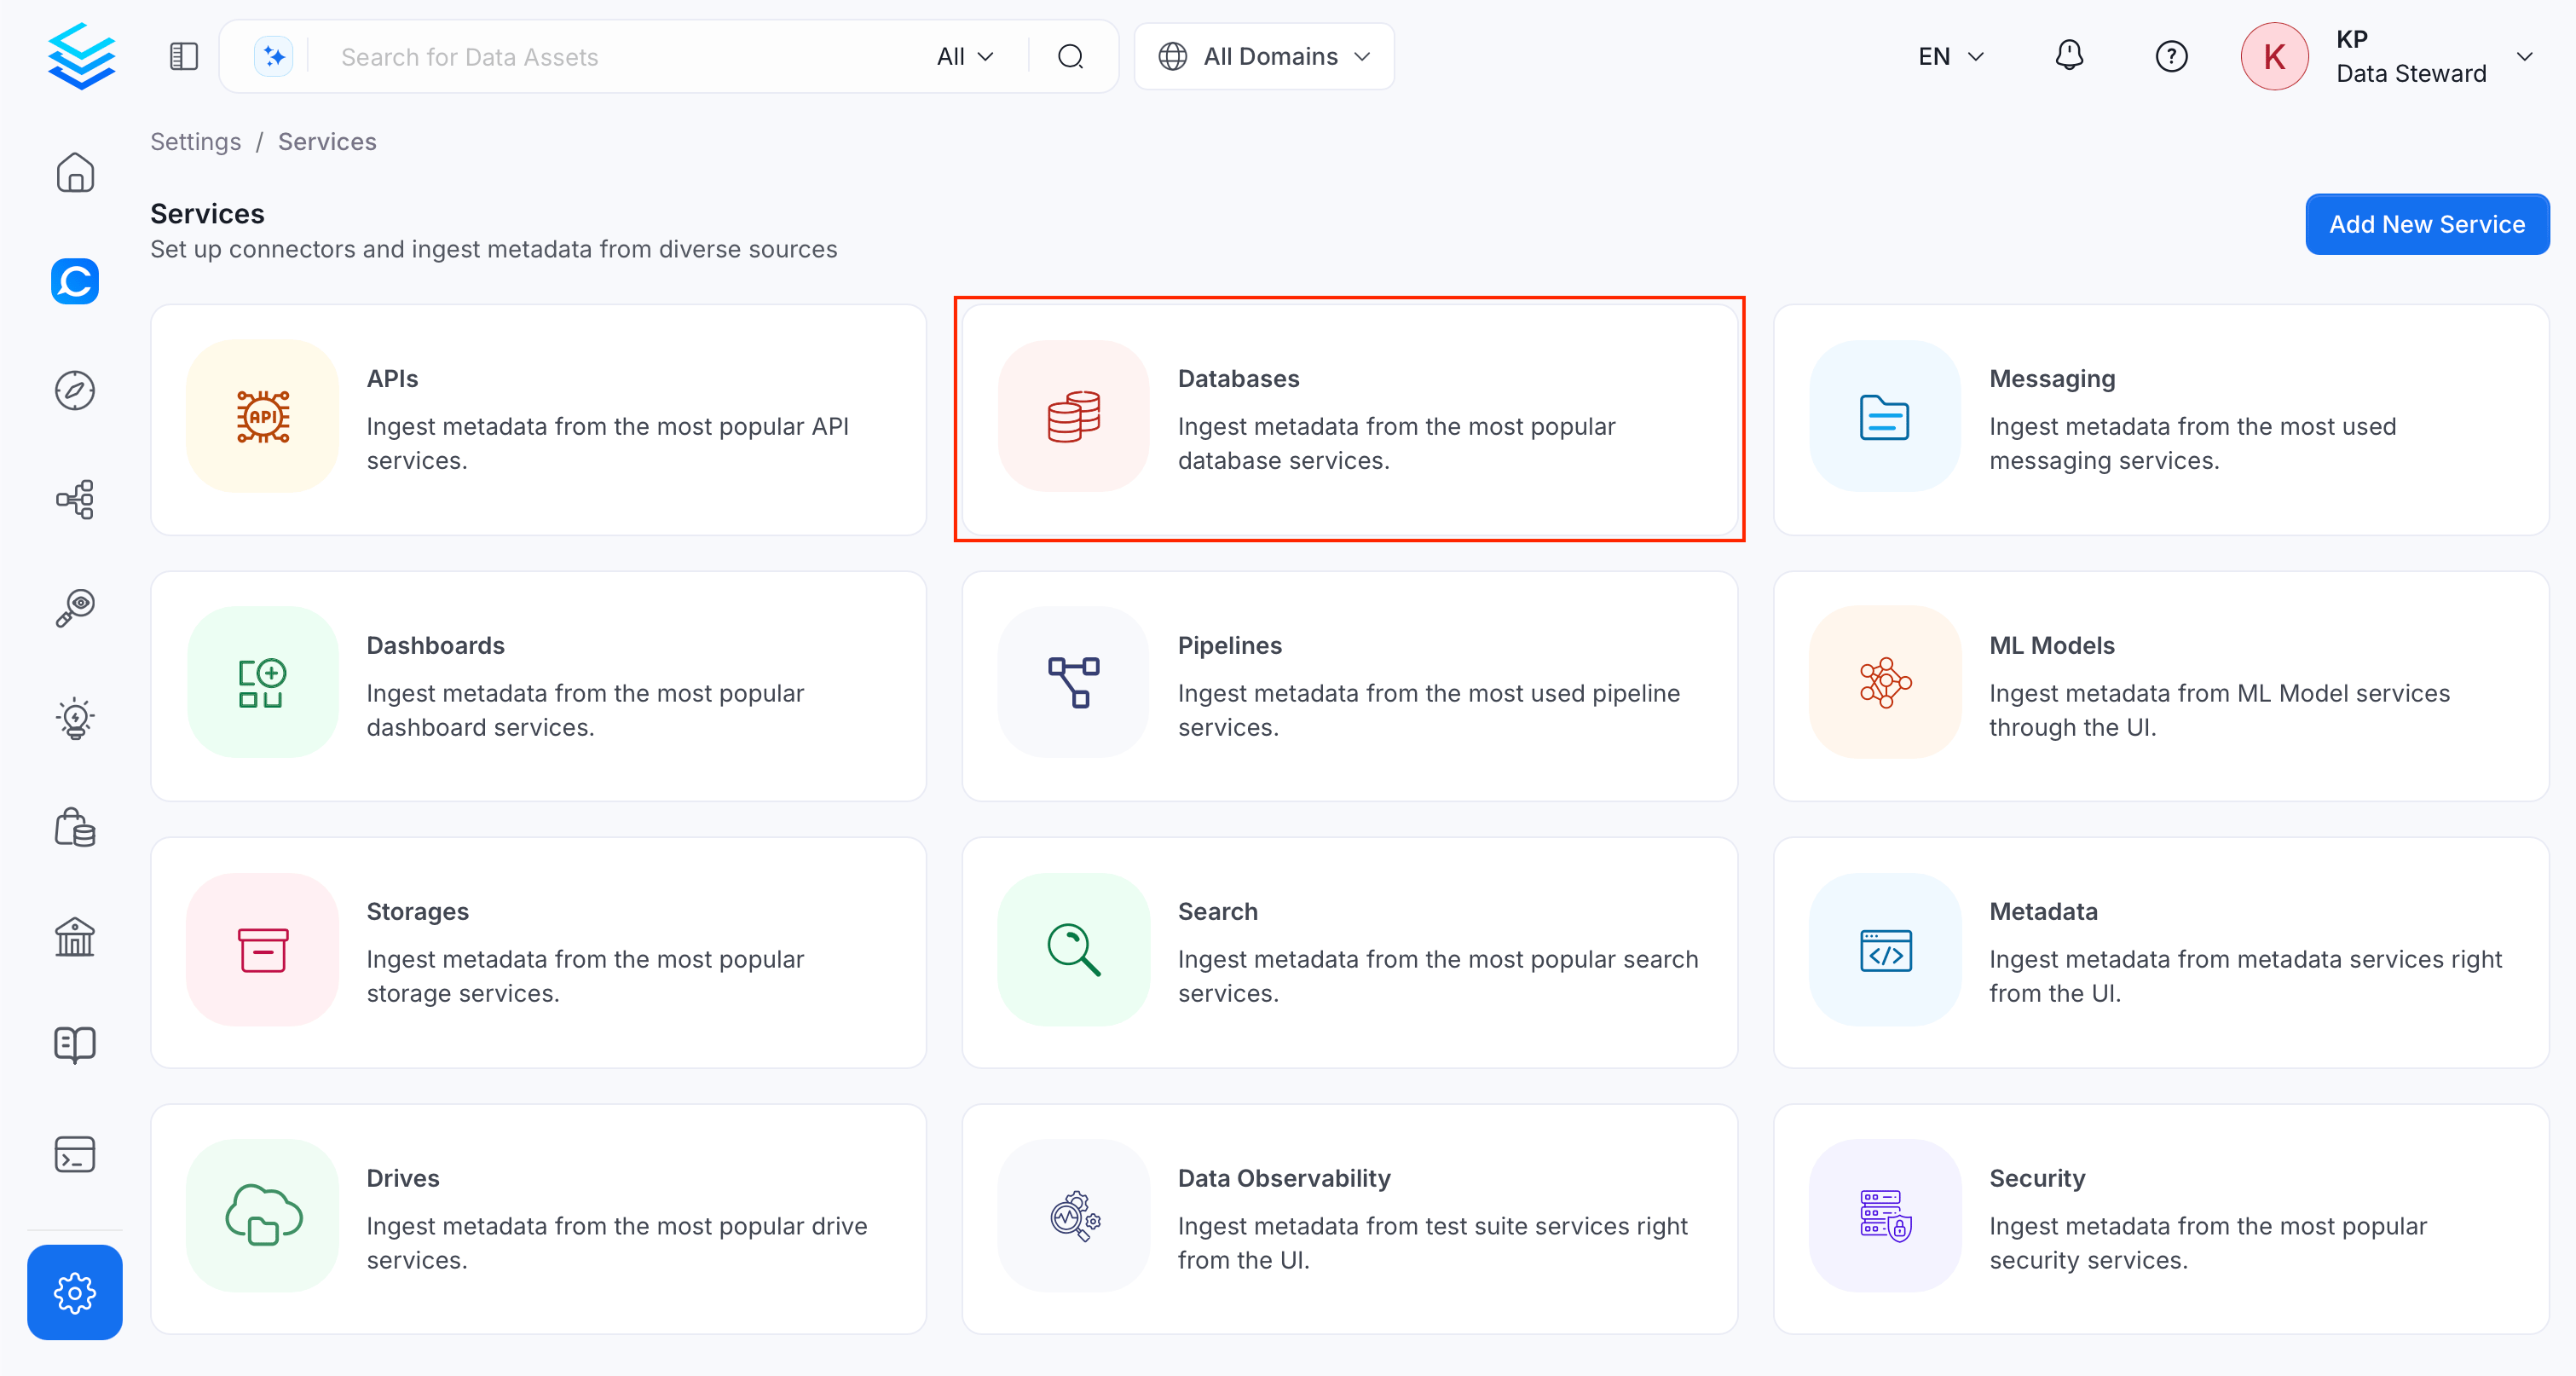 2. Click **Add New Service**.
 ### Step 2: Select a Service and Connector
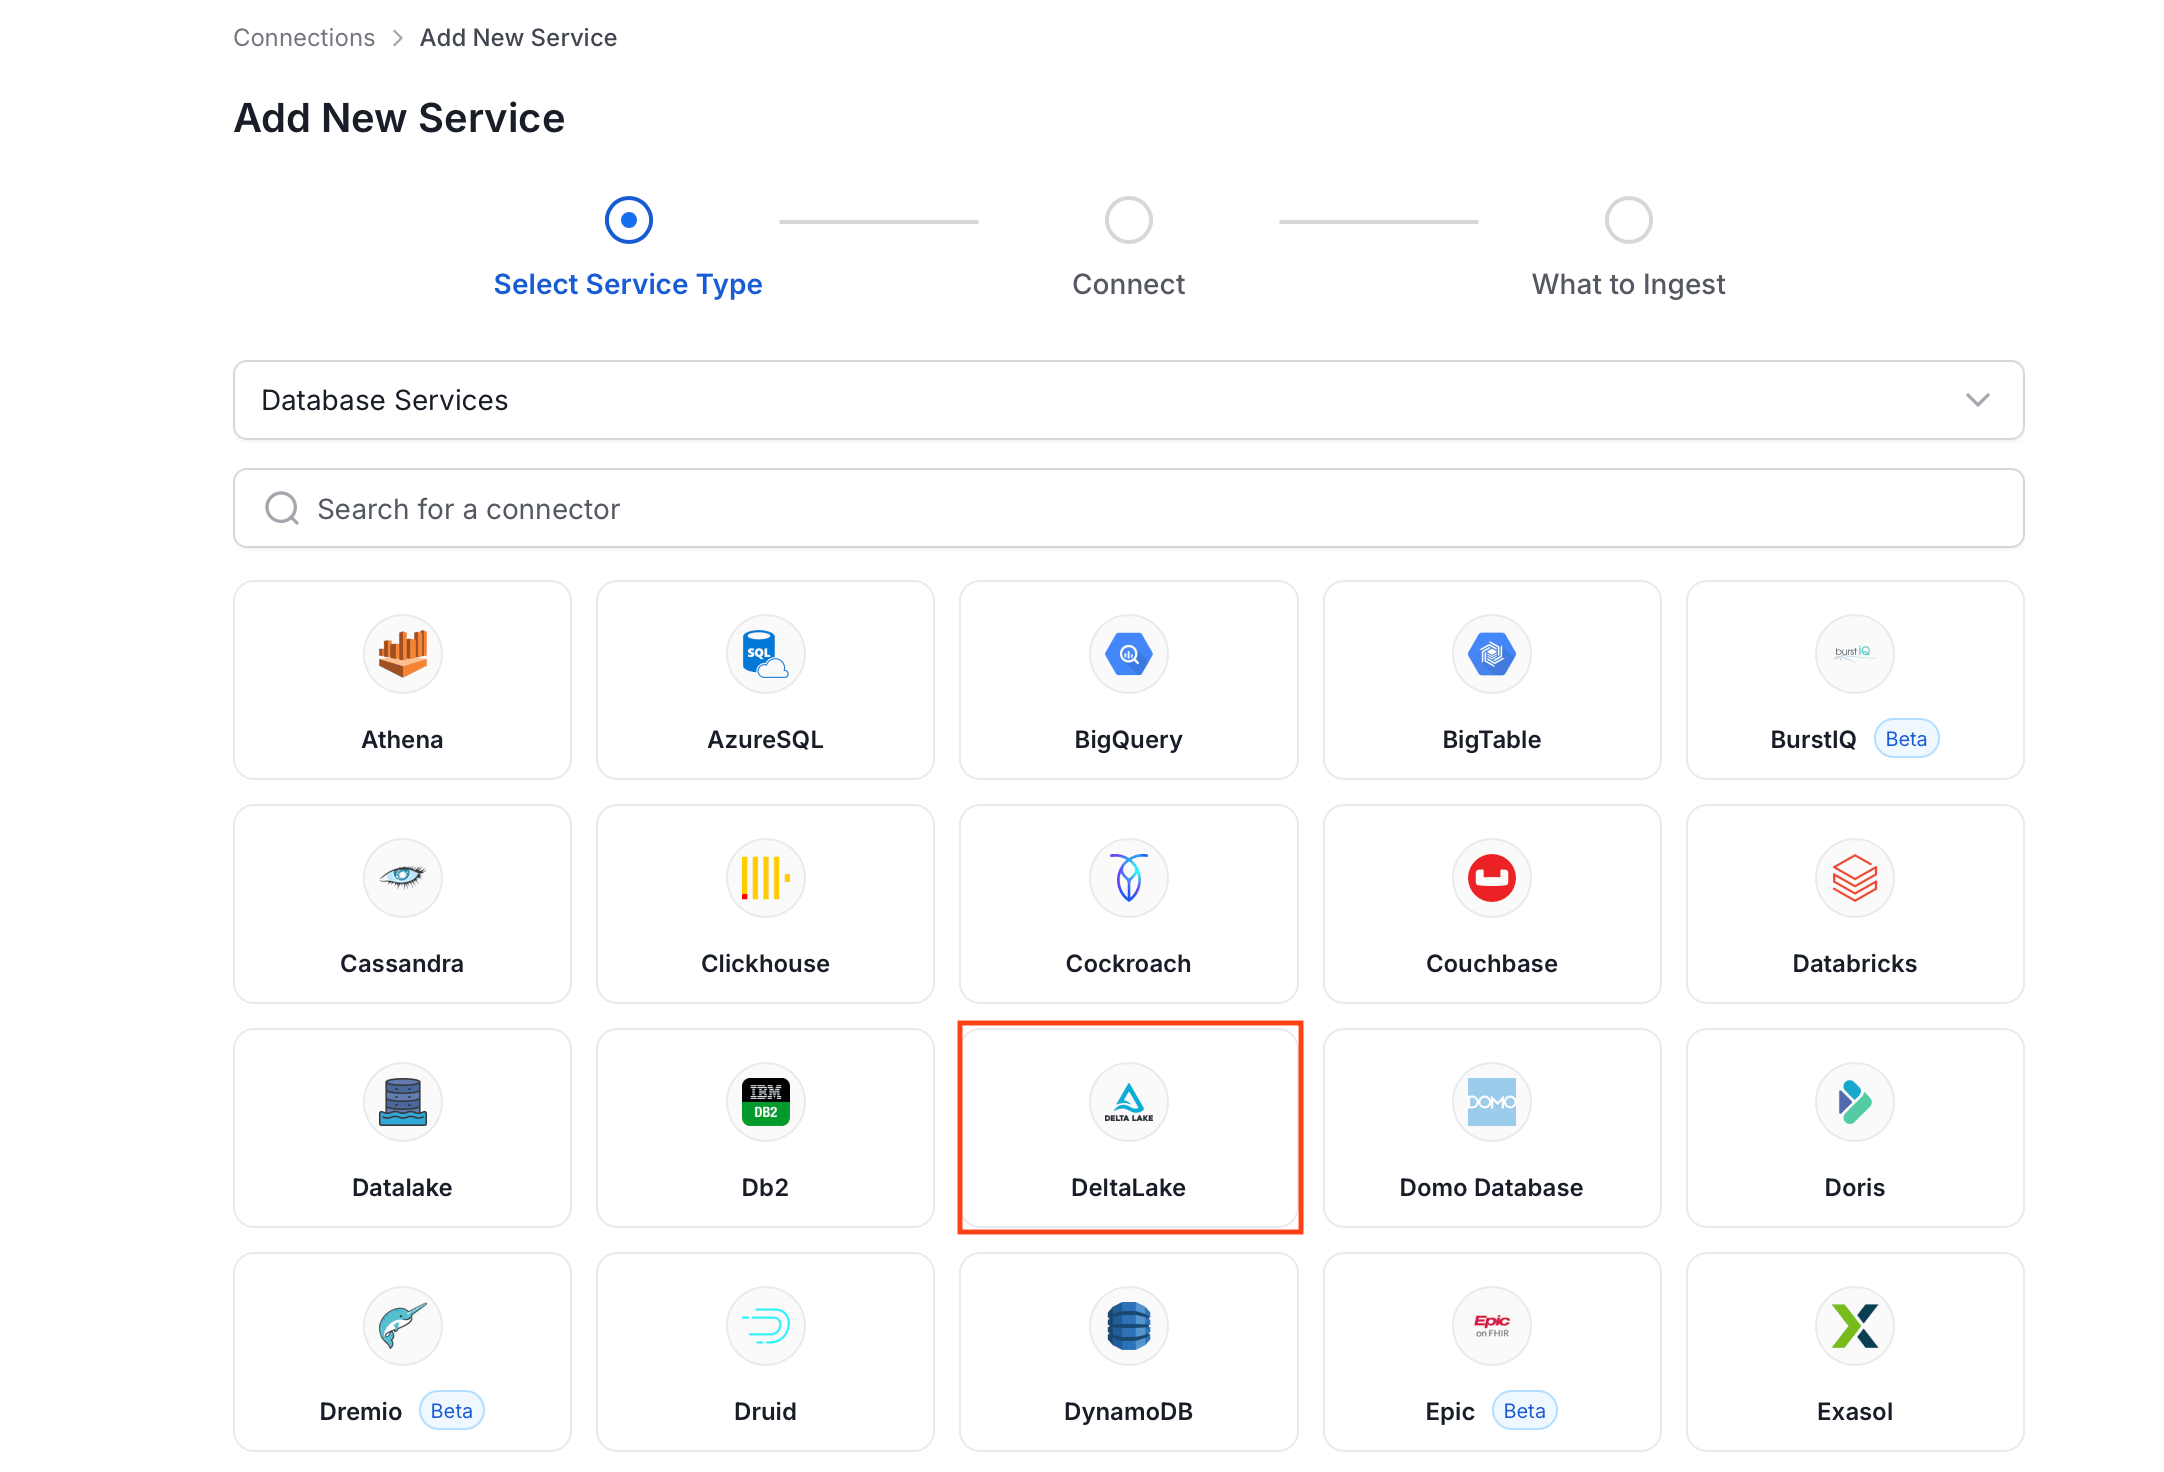
From the service type dropdown, select **Database Services**, then click the **DeltaLake** connector tile.
 ### Step 3: Add Service Name and Description
* Enter a unique, descriptive **Service Name**. Collate identifies services by their service name. Enter a name that distinguishes this deployment from other Delta Lake services you are ingesting metadata from.
* Optional: Enter a **Description** for the service.

 #### Enter Connection Details
Enter the connection details for Delta Lake. The right-hand panel in the UI displays inline help for each field.
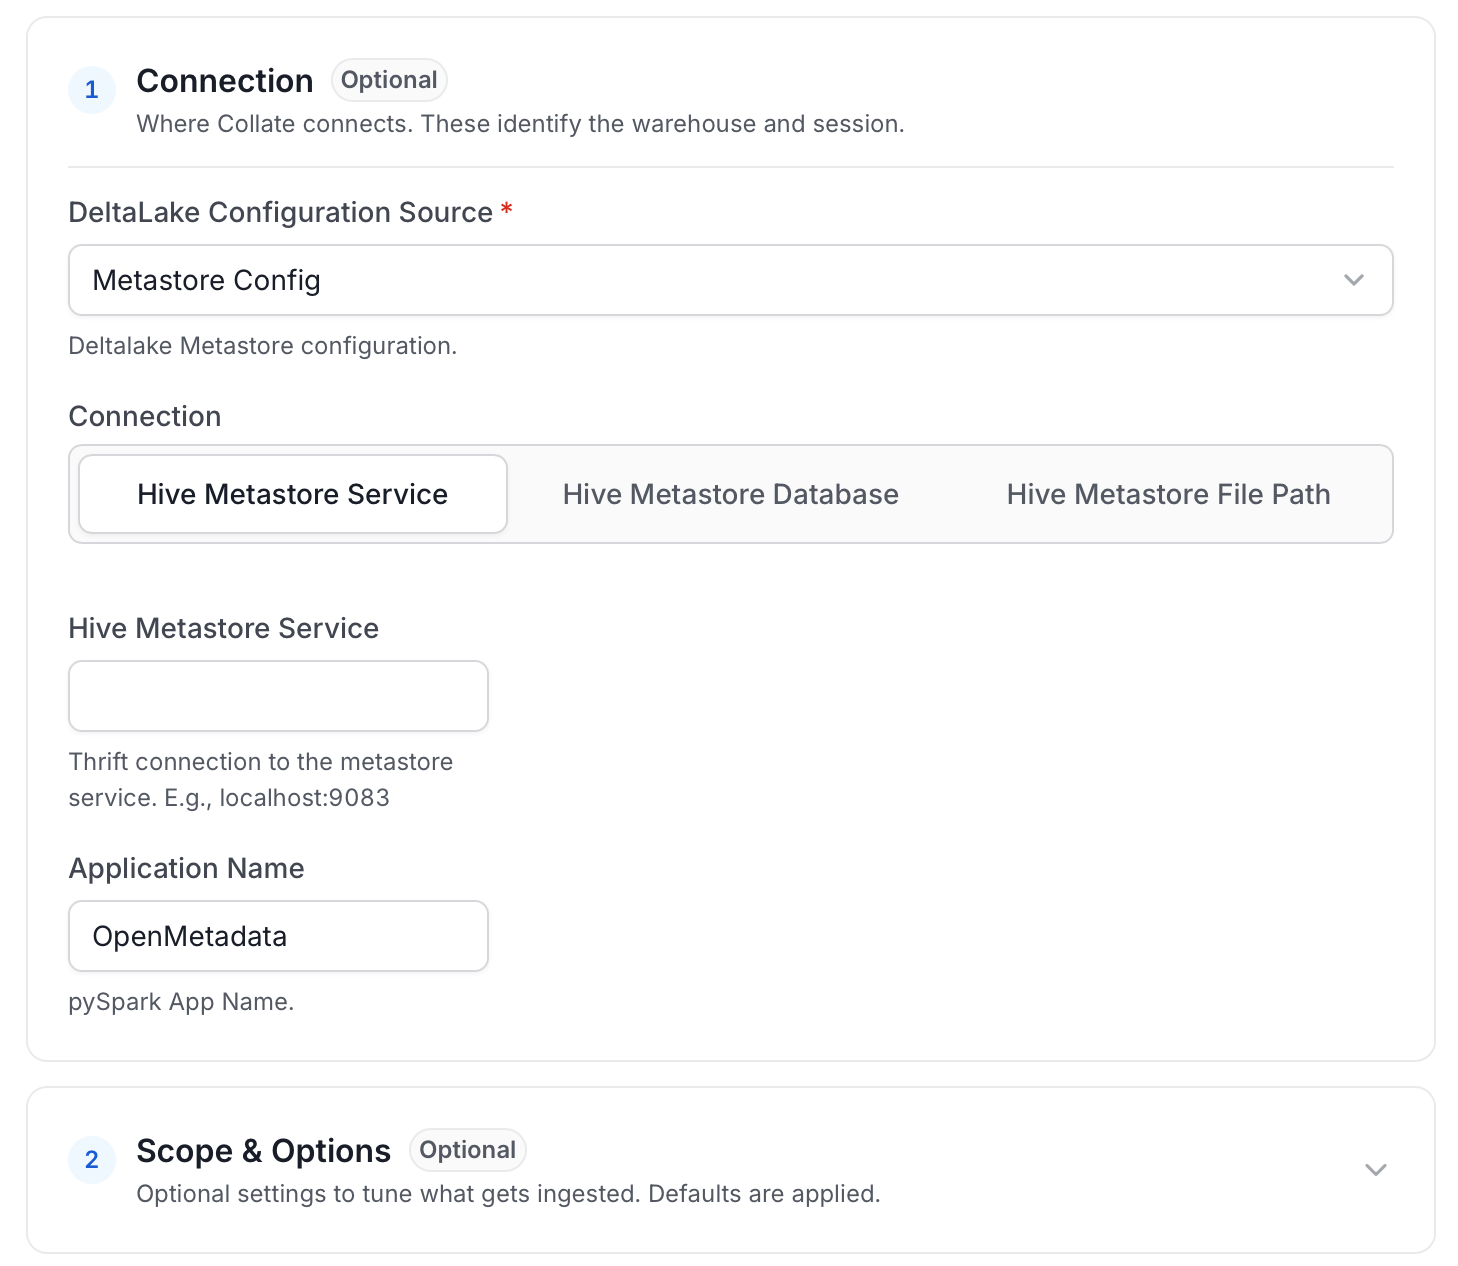 * **Metastore Host Port**: Enter the Host & Port of Hive Metastore Service to configure the Spark Session. Either
of `metastoreHostPort`, `metastoreDb` or `metastoreFilePath` is required.
* **Metastore File Path**: Enter the file path to local Metastore in case Spark cluster is running locally. Either
of `metastoreHostPort`, `metastoreDb` or `metastoreFilePath` is required.
* **Metastore DB**: The JDBC connection to the underlying Hive metastore DB. Either
of `metastoreHostPort`, `metastoreDb` or `metastoreFilePath` is required.
* **appName (Optional)**: Enter the app name of spark session.
* **Connection Arguments (Optional)**: Key-value pairs that Collate passes as extra `config` elements to the Spark Session builder.
Collate runs internally with `pyspark` 3.X and `delta-lake` 2.0.0. This means you need to consider Spark configuration options for 3.X.
**Metastore Host Port**
When connecting to an External Metastore passing the parameter `Metastore Host Port`, Collate prepares a Spark Session with the configuration
```
.config("hive.metastore.uris", "thrift://{connection.metastoreHostPort}")
```
Then, Collate uses the `catalog` functions from the Spark Session to pick up the metadata exposed by the Hive Metastore.
**Metastore File Path**
If instead you use a local file path that contains the metastore information (for example, for local testing with the default `metastore_db` directory), Collate sets
```
.config("spark.driver.extraJavaOptions", "-Dderby.system.home={connection.metastoreFilePath}")
```
To update the `Derby` information. More information about this in a great [SO thread](https://stackoverflow.com/questions/38377188/how-to-get-rid-of-derby-log-metastore-db-from-spark-shell).
* For all supported configurations, see the [Spark configuration documentation](https://spark.apache.org/docs/latest/configuration.html).
* For more information about the Hive metastore, see the [Spark Hive tables documentation](https://spark.apache.org/docs/latest/sql-data-sources-hive-tables.html) and *The Internals of Spark SQL* [book](https://jaceklaskowski.gitbooks.io/mastering-spark-sql/content/spark-sql-hive-metastore.html).
**Metastore Database**
You can also connect to the metastore by directly pointing to the Hive Metastore db, for example, `jdbc:mysql://localhost:3306/demo_hive`.
Here, provide all the common database settings (url, username, password), and the driver class name for JDBC metastore.
You will need to provide the driver to the ingestion image, and pass the `classpath` which will be used in the Spark Configuration under `spark.driver.extraClassPath`.
#### Connection Details for StorageConfig - S3
* **AWS Access Key ID and AWS Secret Access Key**: When you interact with AWS, you specify your AWS security credentials to verify who you are and whether you have
permission to access the resources that you are requesting. AWS uses the security credentials to authenticate and
authorize your requests ([docs](https://docs.aws.amazon.com/IAM/latest/UserGuide/security-creds.html)).
Access keys consist of two parts: An **access key ID** (for example, `AKIAIOSFODNN7EXAMPLE`), and a **secret access key** (for example, `wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY`).
You must use both the access key ID and secret access key together to authenticate your requests.
You can find further information on [how to manage your access keys](https://docs.aws.amazon.com/IAM/latest/UserGuide/id_credentials_access-keys.html).
* **AWS Region**: Each AWS Region is a separate geographic area in which AWS clusters data centers ([docs](https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/Concepts.RegionsAndAvailabilityZones.html)).
AWS can have instances in multiple regions. Specify the region where the service you want to reach is located.
Note that the AWS Region is the only required parameter when configuring a connection. When connecting to the
services programmatically, you can extract and use the rest of the AWS configurations in different ways.
You can find further information about [configuring your credentials](https://boto3.amazonaws.com/v1/documentation/api/latest/guide/credentials.html#configuring-credentials).
* **AWS Session Token (optional)**: If you are using temporary credentials to access your services, you will need to provide the AWS Access Key ID
and AWS Secret Access Key. Also, these will include an AWS Session Token.
You can find more information on [Using temporary credentials with AWS resources](https://docs.aws.amazon.com/IAM/latest/UserGuide/id_credentials_temp_use-resources.html).
* **Endpoint URL (optional)**: To connect programmatically to an AWS service, you use an endpoint. An *endpoint* is the URL of the
entry point for an AWS web service. The AWS SDKs and the AWS Command Line Interface (AWS CLI) automatically use the
default endpoint for each service in an AWS Region. But you can specify an alternate endpoint for your API requests.
Find more information on [AWS service endpoints](https://docs.aws.amazon.com/general/latest/gr/rande.html).
* **Profile Name**: A named profile is a collection of settings and credentials that you can apply to an AWS CLI command.
When you specify a profile to run a command, the settings and credentials are used to run that command.
Multiple named profiles can be stored in the config and credentials files.
You can inform this field if you'd like to use a profile other than `default`.
Find more information about [Named profiles for the AWS CLI](https://docs.aws.amazon.com/cli/latest/userguide/cli-configure-profiles.html).
* **Assume Role Arn**: Typically, you use `AssumeRole` within your account or for cross-account access. In this field you'll set the
`ARN` (Amazon Resource Name) of the policy of the other account.
A user who wants to access a role in a different account must also have permissions that are delegated from the account
administrator. The administrator must attach a policy that allows the user to call `AssumeRole` for the `ARN` of the role in the other account.
This is a required field if you'd like to `AssumeRole`.
Find more information on [AssumeRole](https://docs.aws.amazon.com/STS/latest/APIReference/API_AssumeRole.html).
* **Assume Role Session Name**: An identifier for the assumed role session. Use the role session name to uniquely identify a session when the same role
is assumed by different principals or for different reasons.
By default, Collate uses the name `OpenMetadataSession`.
Find more information about the [Role Session Name](https://docs.aws.amazon.com/STS/latest/APIReference/API_AssumeRole.html#:~:text=An%20identifier%20for%20the%20assumed%20role%20session.).
* **Assume Role Source Identity**: The source identity specified by the principal that is calling the `AssumeRole` operation. You can use source identity
information in AWS CloudTrail logs to determine who took actions with a role.
Find more information about [Source Identity](https://docs.aws.amazon.com/STS/latest/APIReference/API_AssumeRole.html#:~:text=Required%3A%20No-,SourceIdentity,-The%20source%20identity).
#### Advanced Configuration
Database Services include an Advanced Configuration section for passing extra arguments to the connector and, if needed, changing the connection scheme. You need this only for advanced connectivity scenarios or customizations.
* **Connection Options (Optional)**: Enter the details for any additional connection options that can be sent to the database during the connection. These details must be added as key-value pairs.
* **Connection Arguments (Optional)**: Enter the details for any additional connection arguments such as security or protocol configs that can be sent during the connection. These details must be added as key-value pairs.
 ### Step 5: Configure Ingestion Options
In the **What to Ingest** step, use filter patterns to control which assets Collate ingests from your database service. Filter rules match asset names using the following match types.
#### How Filter Patterns Work
* **Include**: Add one or more comma-separated values. Each value uses one of the following match types. Collate ingests only assets whose names match at least one rule. Leave blank to include all assets.
* **Exclude**: Add one or more comma-separated values. Each value uses one of the following match types. Collate skips any asset whose name matches a rule. Leave blank to exclude nothing.
Rules match asset names using one of five match types:
* **contains**: matches any name containing the value. For example, `sales` matches `my_sales_data` and `sales_2024`.
* **starts with**: matches names beginning with the value. For example, `prod_` matches `prod_db` and `prod_schema`.
* **ends with**: matches names ending with the value. For example, `_raw` matches `events_raw` and `logs_raw`.
* **is exactly**: matches the exact name only. For example, `analytics` matches only `analytics`.
* **matches regex**: matches names using a regular expression. For example, `^prod_.*_v\d+$` matches `prod_events_v1`.
When both Include and Exclude are set, Exclude takes priority.
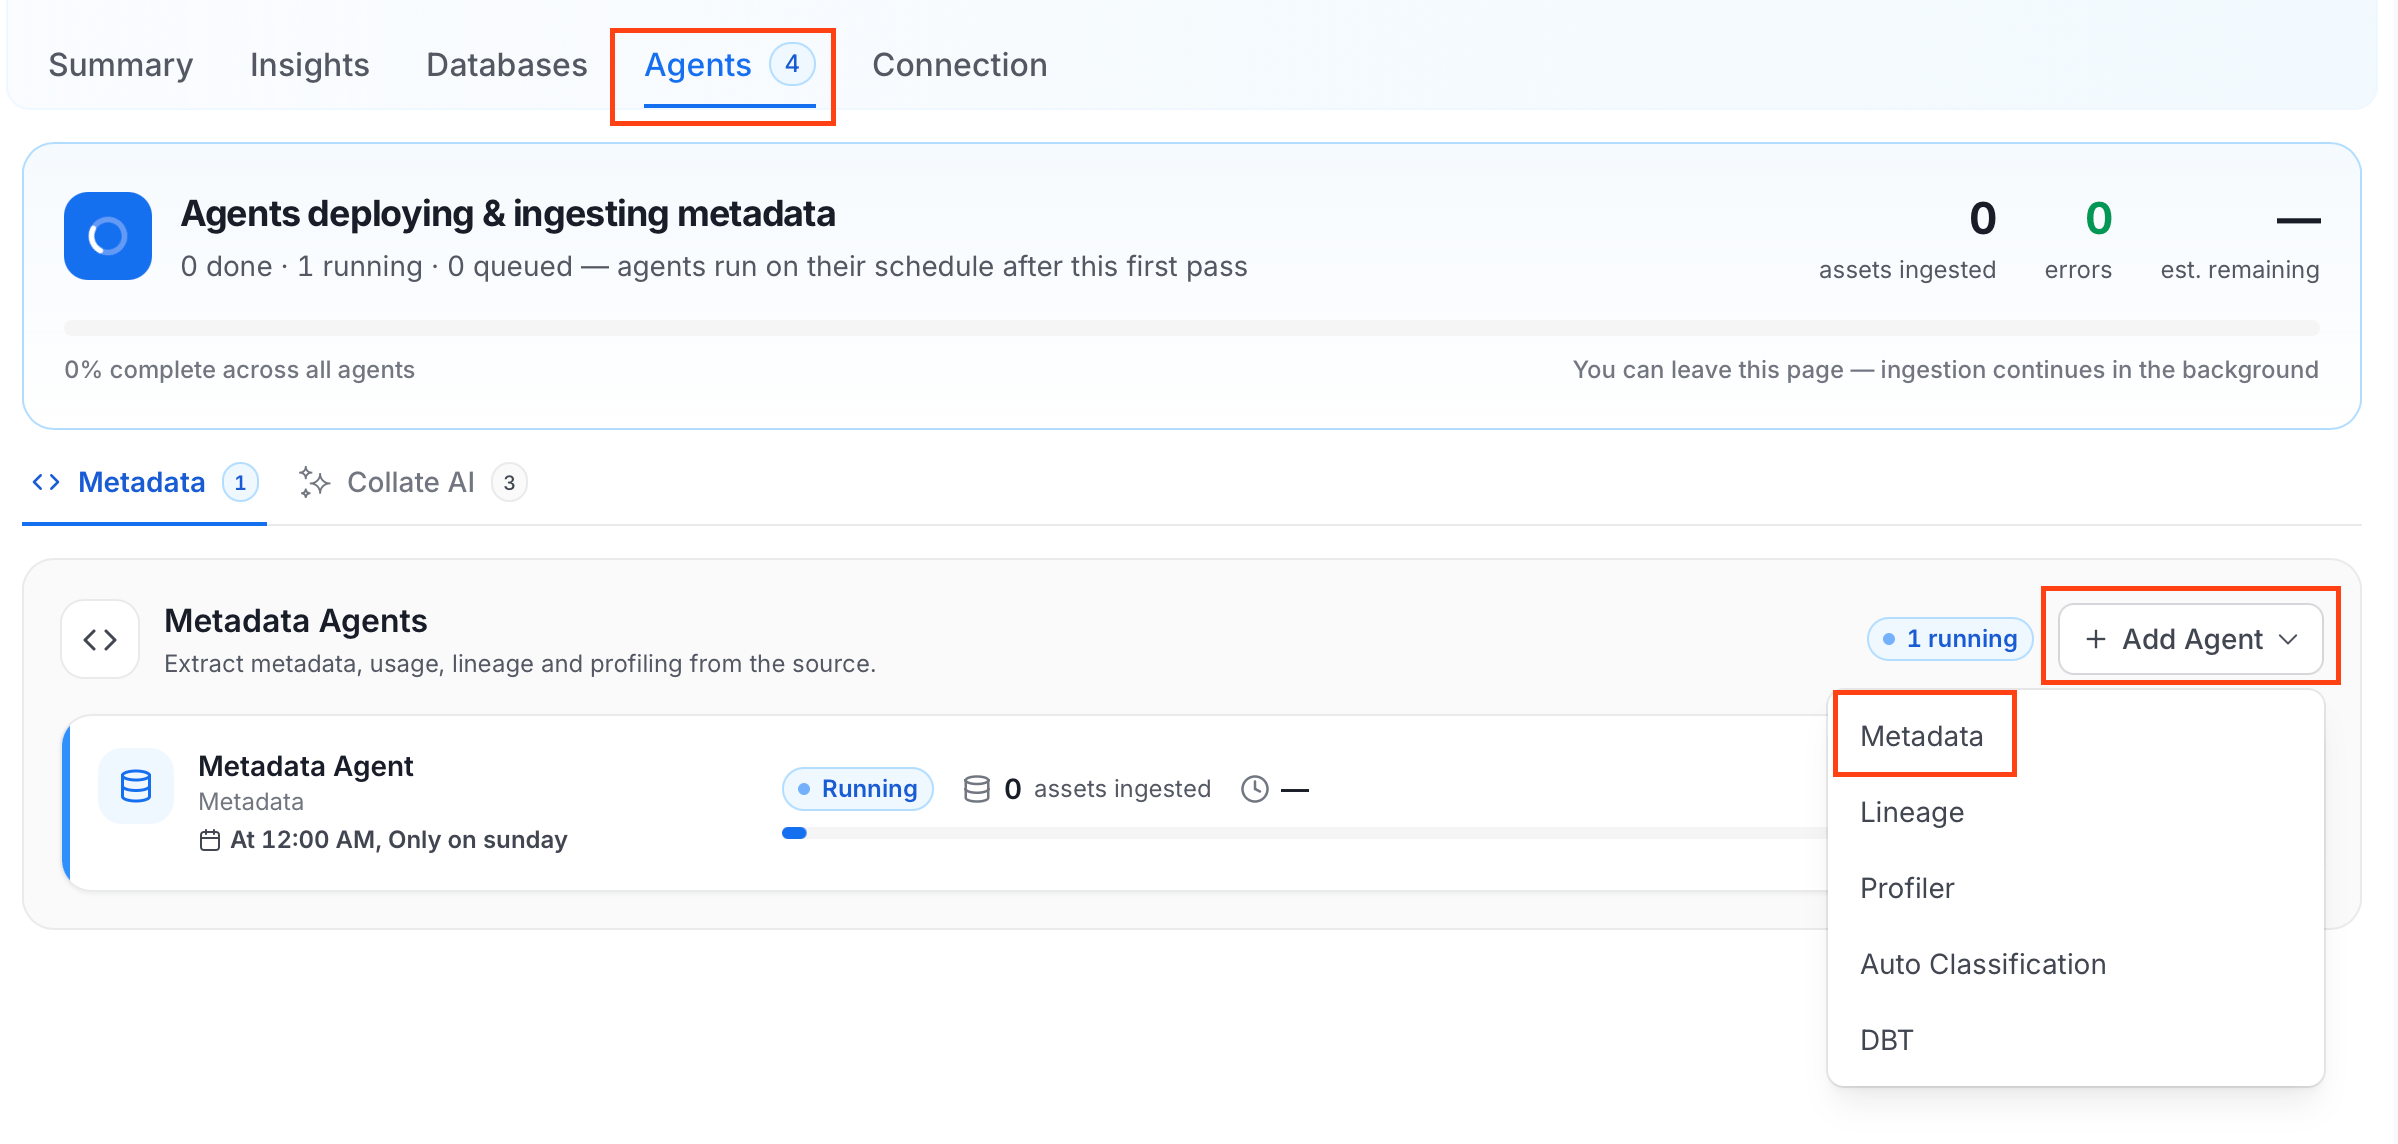 For some services, the dropdown is not available and clicking **Add Agent** takes you directly to the agent configuration page.
4. On the **Configure Ingestion** page, do the following and click **Next**.
* **Name this Ingestion**: Enter a unique, recognizable name for this ingestion pipeline.
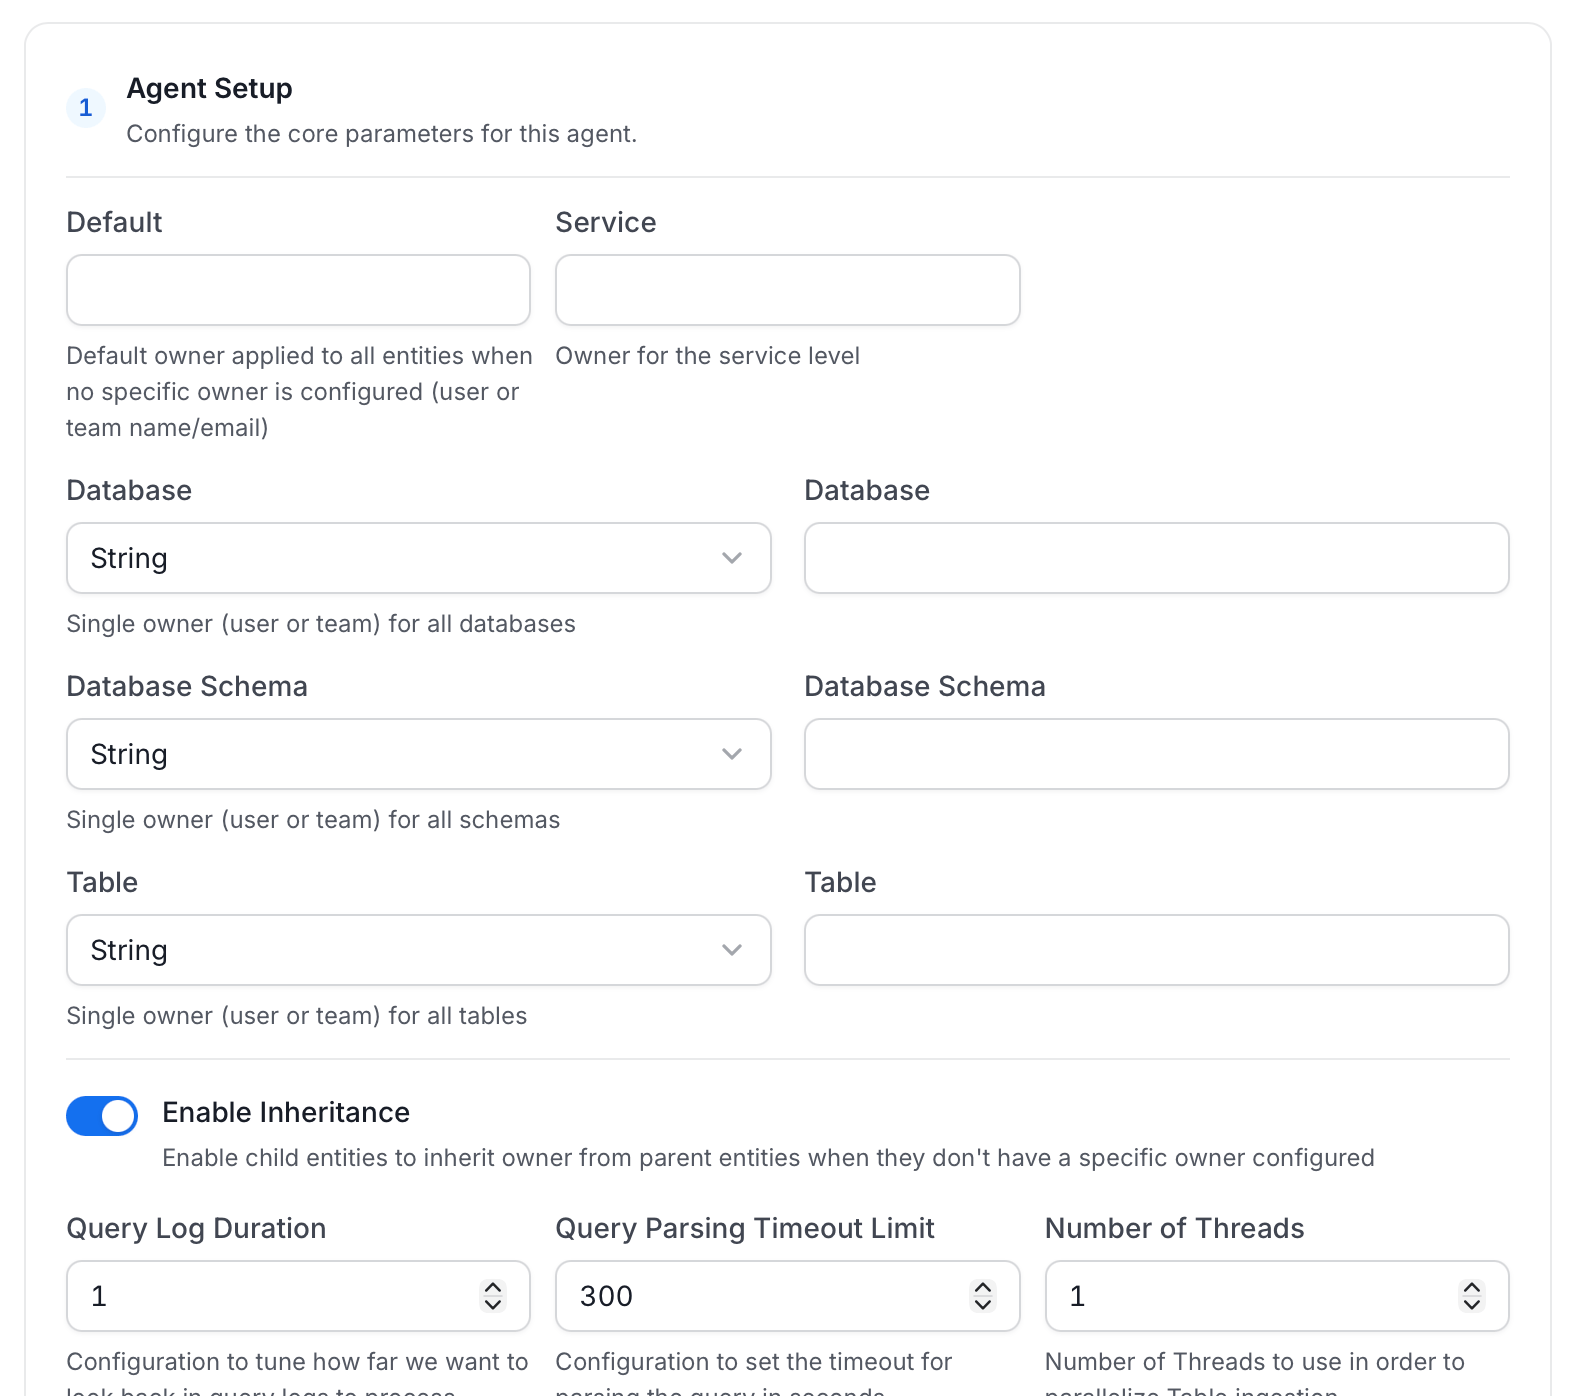
 * **Agent Setup**: Configure core parameters for metadata extraction. The following fields are available:
| Field | Default | Description |
| - | - | - |
| **Default Owner** | — | Owner applied to any entity that has no owner from a more specific field below. Accepts a user or a team, by name or email. |
| **Service Owner** | — | Not applied during ingestion. This field doesn't affect the owners of databases, schemas, or tables. |
| **Database Owner** | — | Owner assigned to every database this agent ingests. Accepts either one owner for all of them, or a mapping of specific owners per database. |
| **Database Schema Owner** | — | Owner assigned to every schema this agent ingests. Accepts either one owner for all of them, or a mapping of specific owners per schema. |
| **Table Owner** | — | Owner assigned to every table this agent ingests. Accepts either one owner for all of them, or a mapping of specific owners per table. |
| **Enable Inheritance** | On | When on, a schema or table with no match of its own inherits the owner resolved for its parent. Default Owner still applies when nothing else resolves an owner. |
| **Query Log Duration** | 1 | How many days of query logs to look back through when processing stored procedure results. |
| **Query Parsing Timeout Limit** | 300 | How many seconds to spend parsing a single query before giving up on it and moving to the next. Raise this if large or complex queries are being skipped. |
| **Number of Threads** | 1 | How many tables to ingest in parallel. Raising this can speed up ingestion on databases with many tables, at the cost of more load on the source. |
| **Incremental Extraction** | Off | When on, a run extracts only entities that changed since the last successful run, instead of re-scanning everything every time. Faster on large, mostly-unchanged databases. |
| **Successful Pipeline Run Lookback Days** | 7 | Only used when Incremental Extraction is on. How many days back to search for a prior successful run to use as the starting point for "what changed since then." |
| **Safety Margin Days** | 1 | Only used when Incremental Extraction is on. Extra days added before that starting point, as a buffer so changes that were still in flight when the last run finished aren't missed. |
| **Extract JSON Schema** | Off | Sample values in JSON columns to infer and ingest their schema, so the individual fields inside a JSON column are visible in Collate rather than just "JSON". Requires `SELECT` permission on the sampled tables; if that permission is missing, the JSON column is still ingested, just without a detailed schema. |
| **JSON Schema Sample Size** | 10 | Only used when Extract JSON Schema is on. Number of rows sampled per JSON column to infer its schema. A larger sample gives more accurate results but takes longer to run. |
For more information, see [Hierarchical Owner Configuration](/how-to-guides/guide-for-data-users/ingestion/workflows/metadata/hierarchical-owner-configuration).
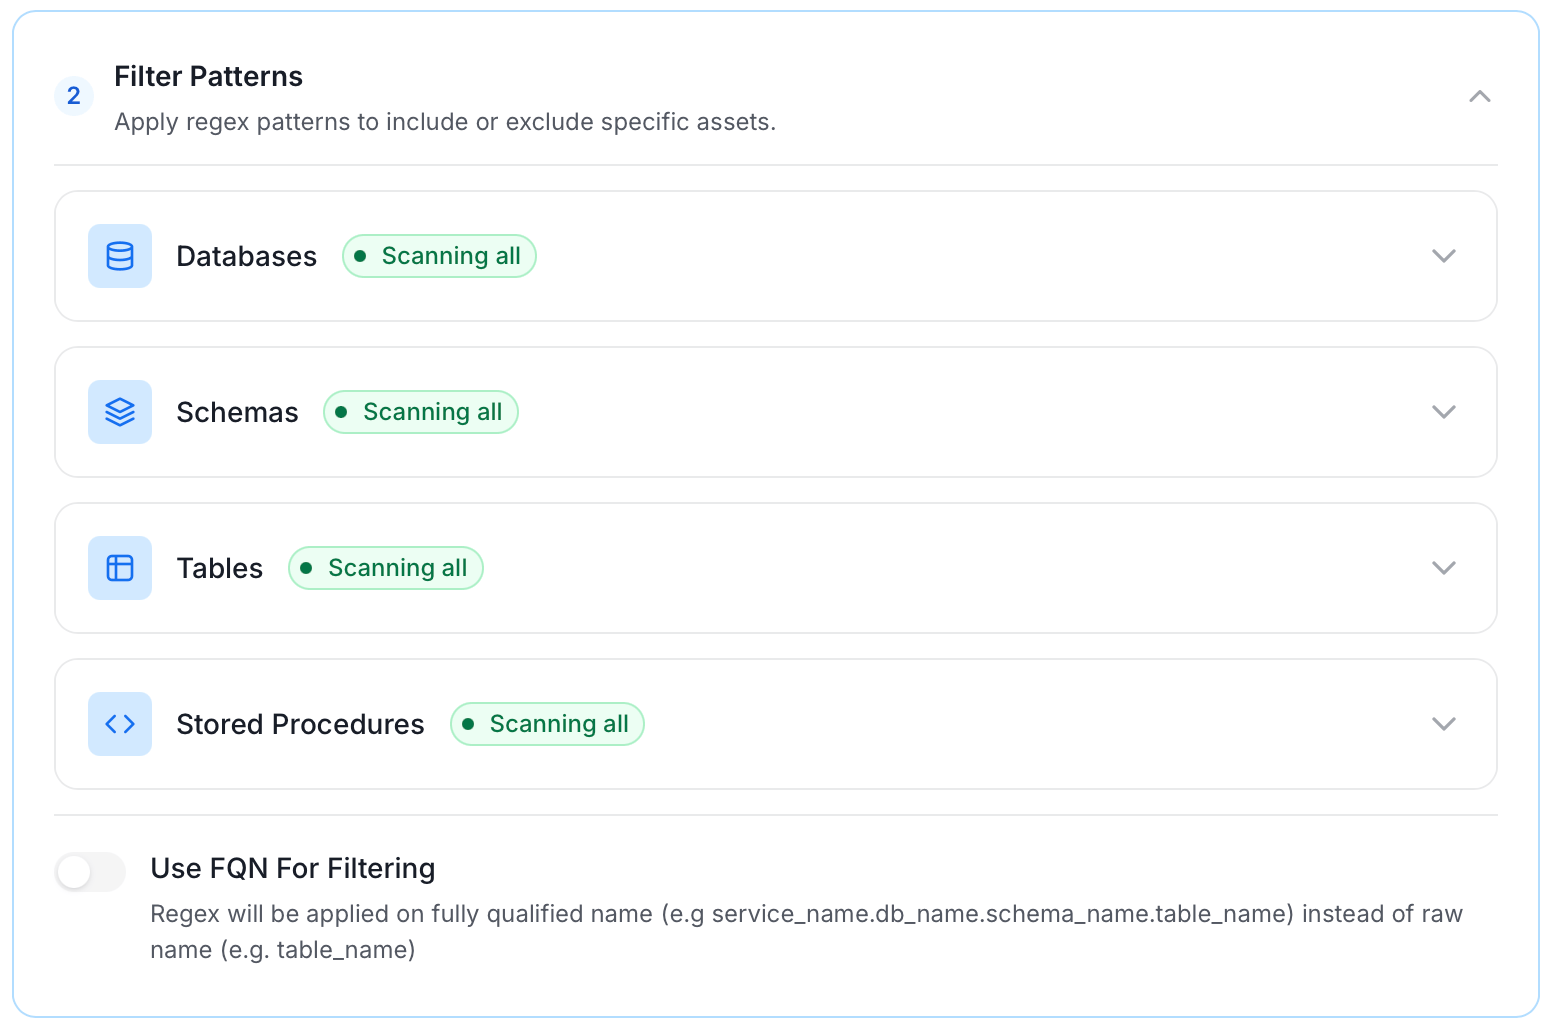
 * **Filter Patterns**: Apply include or exclude rules to scope which databases, schemas, tables, and stored procedures this agent ingests. These follow the same filter options described in **Step 5**.
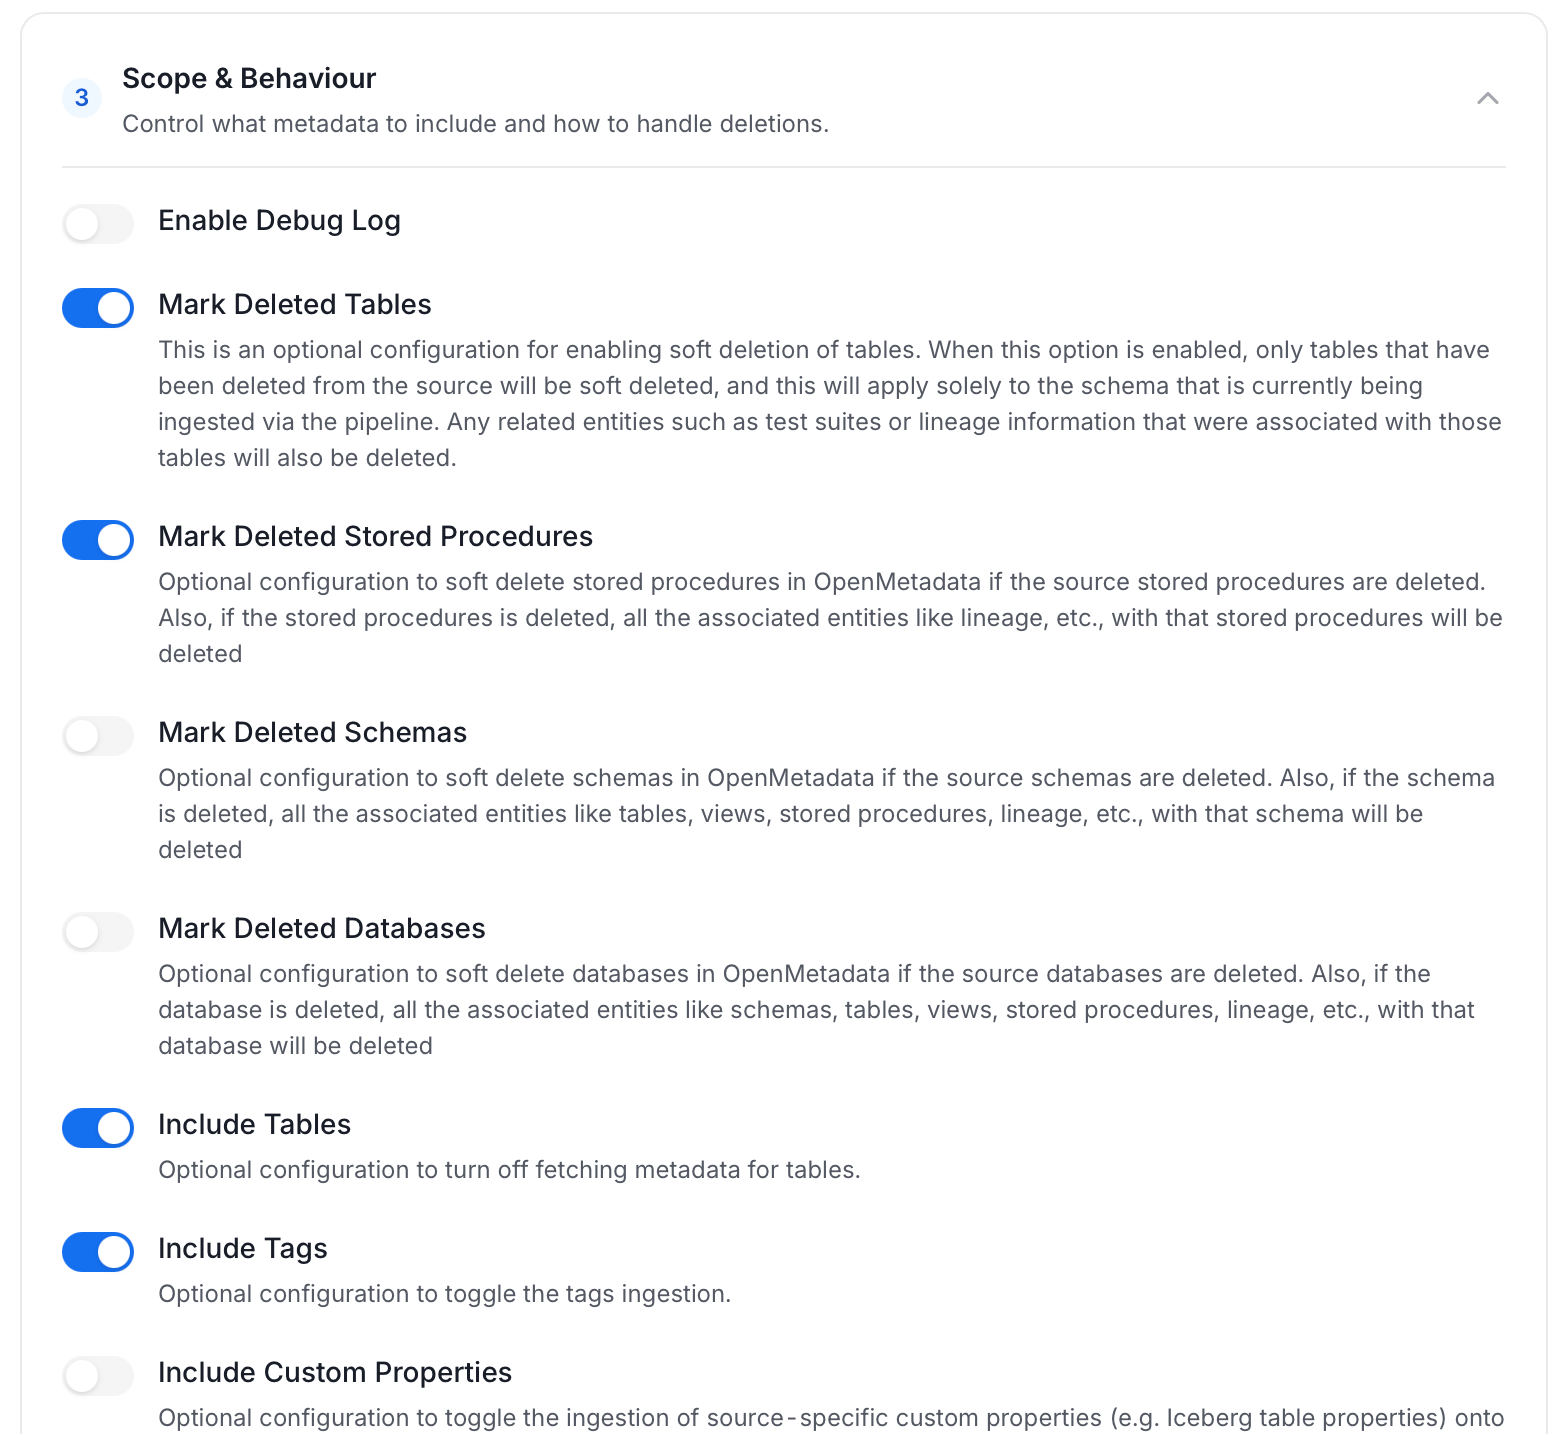
 * **Scope & Behaviour**: Control how the agent handles metadata during ingestion. Toggle each option on or off based on your needs:
| Toggle | Default | Description |
| - | - | - |
| **Include Tables** | On | Ingest tables and their columns. Turn off to skip tables entirely, for example if this agent exists only to pull tags or stored procedures. |
| **Include Tags** | On | Ingest tags already defined on tables/columns in the source system (for example, a classification tag applied in Snowflake) and bring them into Collate as tags on the same assets. |
| **Include Stored Procedures** | On | Ingest stored procedures as their own assets, so they show up in the catalog and can be linked into lineage. |
| **Include DDL Statements** | Off | Also ingest the raw `CREATE TABLE` / `CREATE VIEW` statement for each asset, so it's viewable in Collate alongside the asset's metadata. |
| **Include Owners** | Off | When an ingested asset's owner in the source system is an email that matches an existing Collate user, assign that user as the asset's owner. Never overwrites an owner an asset already has in Collate. |
| **Include Custom Properties** | Off | Ingest source-specific metadata that doesn't map to a standard Collate field (for example, a database-specific attribute) into custom properties on the asset, if custom properties have been defined for that entity type. |
| **Mark Deleted Tables** | On | If a table this agent previously ingested no longer exists in the source, soft-delete it in Collate too. Only affects tables within schemas this agent actually scans. |
| **Mark Deleted Stored Procedures** | On | Same as Mark Deleted Tables, but for stored procedures. |
| **Mark Deleted Schemas** | Off | If an entire schema this agent previously ingested no longer exists in the source, soft-delete the schema and everything in it. |
| **Mark Deleted Databases** | Off | If an entire database this agent previously ingested no longer exists in the source, soft-delete the database and everything in it. |
| **Override Metadata** | Off | On: values from the source (descriptions, tags, owners, display names) always overwrite what's currently in Collate, even if someone edited it there. Off: Collate only fills in fields that are still empty, so manual edits in Collate are preserved. |
| **Enable Debug Log** | Off | Run this ingestion at DEBUG log verbosity instead of the normal level. Turn on when troubleshooting a failing or unexpected run; leave off otherwise, since debug logs are much larger. |
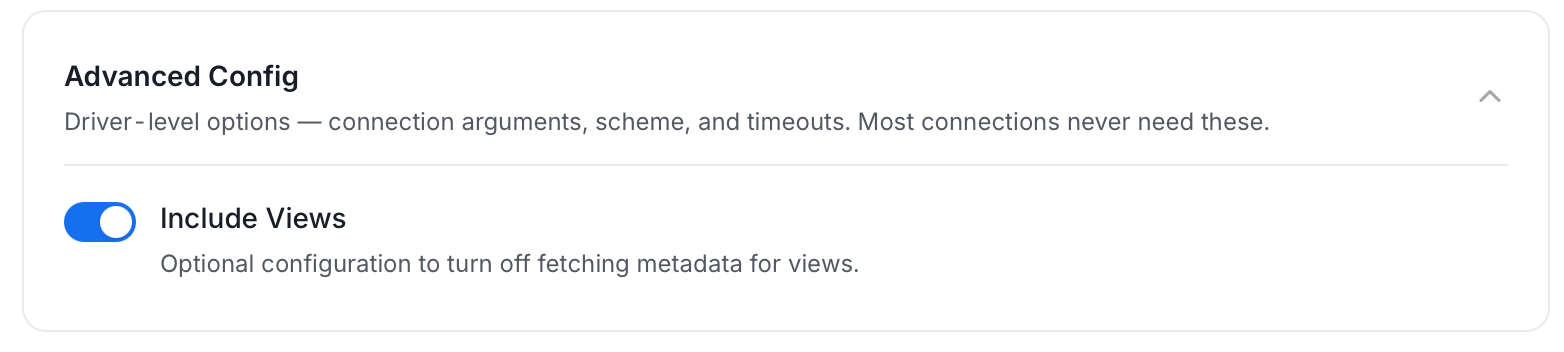
 * **Advanced Config**: Driver-level options (connection arguments, scheme, and timeouts). Most connections never need these, and they vary by connector. This section also has one ingestion-scope toggle:
| Toggle | Default | Description |
| - | - | - |
| **Include Views** | On | Ingest views in addition to tables. Turn off to skip views entirely. Because view lineage is derived from parsing each view's SQL definition, turning this off also stops view-based lineage from being generated for this service. |
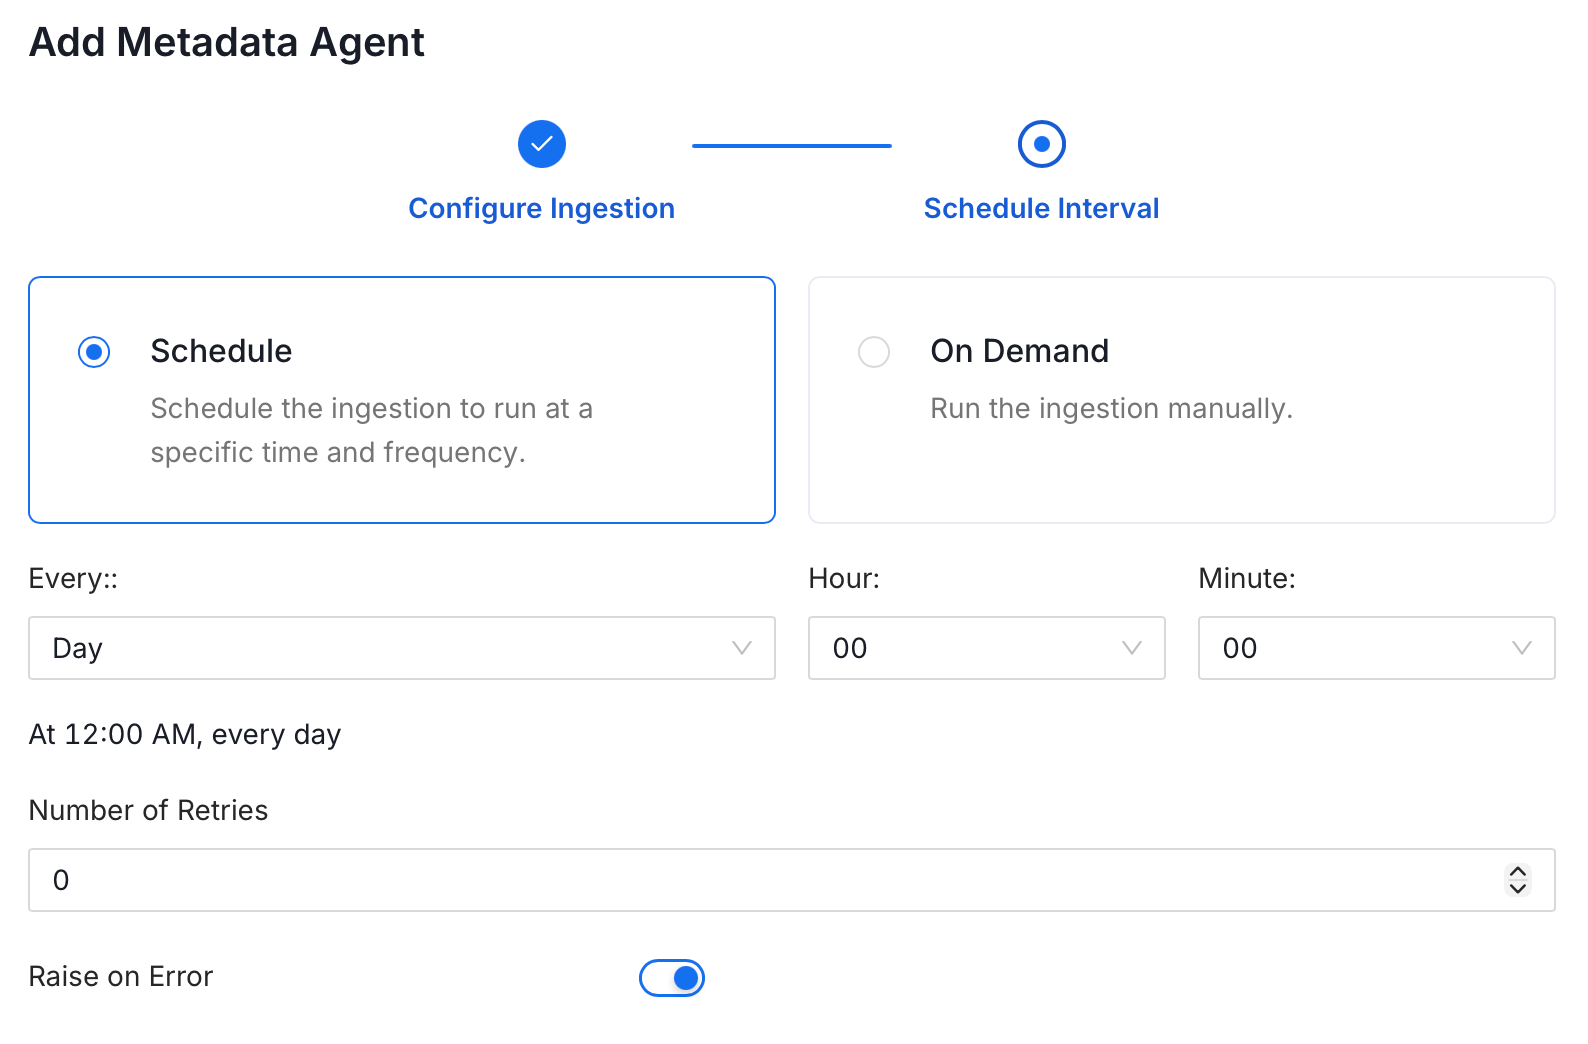
 5. On the **Schedule Interval** page, set when the agent runs:
* **Schedule**: Choose a preset interval (Hourly, Daily, Weekly, Monthly) or enter a custom cron expression.
* **On-Demand**: No automatic schedule. Trigger the agent manually when needed.
 6. Click **Add** to deploy the agent.
## Troubleshooting