> ## Documentation Index
> Fetch the complete documentation index at: https://docs.getcollate.io/llms.txt
> Use this file to discover all available pages before exploring further.

# Looker Connector | Integrate BI with Collate Docs

> Connect Looker dashboards to Collate with our comprehensive connector guide. Setup instructions, configuration steps, and metadata extraction tips.

export const ConnectorDetailsHeader = ({name, icon, stage, availableFeatures, unavailableFeatures = [], availableFeaturesCollate = []}) => {
  const showSubHeading = availableFeatures?.length > 0 || unavailableFeatures?.length > 0 || availableFeaturesCollate?.length > 0;
  const totalAvailableFeatures = [...availableFeatures || [], ...availableFeaturesCollate || []];
  return <div className="container">
      <div className="Heading">
        <div className="flex items-center gap-3">
          {icon && <div className="IconContainer">
              <img src={icon} alt={name} noZoom className="ConnectorIcon" />
            </div>}
          <h1 className="ConnectorName">{name}</h1>
          <span className={`StageBadge ${stage === 'PROD' ? 'prod' : 'beta'}`}>
            {stage}
          </span>
        </div>
      </div>
      {showSubHeading && <div className="SubHeading">
          <div className="FeaturesHeading">Feature List</div>
          <div className="FeaturesList">
            {totalAvailableFeatures.map(feature => <div className="FeatureTag AvailableFeature" key={feature}>
                ✓ {feature}
              </div>)}
            {unavailableFeatures.map(feature => <div className="FeatureTag UnavailableFeature" key={feature}>
                ✕ {feature}
              </div>)}
          </div>
        </div>}
    </div>;
};

<ConnectorDetailsHeader icon="/public/images/connectors/looker.webp" name="Looker" stage="PROD" availableFeatures={["Dashboards", "Charts", "Owners", "Datamodels", "Projects", "Lineage", "Usage"]} unavailableFeatures={["Tags"]} />

This section provides guides and references to use the Looker connector.
Configure and schedule Looker metadata and profiler workflows from the Collate UI:

* [Requirements](#requirements)
* [Metadata Ingestion](#metadata-ingestion)
* [Entity Mapping](#entity-mapping)
* [Lineage](#lineage)
* [Troubleshooting](/connectors/dashboard/looker/troubleshooting)

## Requirements

Collate ingests two types of metadata from Looker:

* Dashboards & Charts
* LookML Models
  For the `project` metadata being ingested:
* The actual LookML Project an Explore or View is developed in.
* For Dashboards, the folder name from the UI, since there is no other hierarchy involved there.
  In terms of permissions, a user with access to the Dashboards and LookML Explores to be ingested is required.
  Create your API credentials by following [Looker API authentication](https://cloud.google.com/looker/docs/api-auth).
  However, LookML Views are not present in the Looker SDK. Instead, that information must be extracted directly from
  the GitHub repository holding the source `.lkml` files. To get this metadata, a GitHub token
  with read only access to the repository is required. For steps, see [Creating a personal access token](https://docs.github.com/en/enterprise-server@3.4/authentication/keeping-your-account-and-data-secure/creating-a-personal-access-token).

<Tip>
  **Tip**: The GitHub credentials are completely optional. Without them, Collate cannot ingest metadata
  out of LookML Views, including their lineage to the source databases.
  Moreover, Looker lineage only supports LookML views configured with `sql_table_name` and `derived_table` in plain SQL.
  Liquid variables are not yet supported.
</Tip>

## Entity Mapping

The Looker connector maps Looker assets to Collate entities as follows:

| Looker Asset | Collate Entity | Description |
| - | - | - |
| **Dashboards** | **Dashboard** | Looker dashboards are mapped to Collate Dashboard entities. |
| **Dashboard Elements** (tiles) | **Chart** | Visualization tiles within a Looker dashboard are mapped to Collate Chart entities. |
| **Explores** and **Views** (LookML) | **Data Models** | LookML Explores and Views are mapped to Collate Data Model entities. |
| **Folders** (Dashboards) / **LookML Projects** (Explores & Views) | **Project field** | The project field means something different depending on the entity: for a Dashboard it stores the Looker folder name, while for an Explore or View it stores the LookML project (Git repository) it belongs to. |

### Example Structure

**Looker Structure**:

```
Folder: Sales Team
└── Dashboard: Revenue Overview
    ├── Tile: Monthly Revenue
    └── Tile: Regional Breakdown
LookML Project: sales_analytics
├── Explore: revenue
└── View: orders
```

**Collate Structure**:

```
Dashboard: "Revenue Overview" (Project: "Sales Team")
├── Chart: "Monthly Revenue"
└── Chart: "Regional Breakdown"
Data Model: "revenue" (Project: "sales_analytics")
Data Model: "orders" (Project: "sales_analytics")
```

This mapping ensures that:

* Looker dashboards appear as Collate dashboards, organized by their Looker folder
* Dashboard tiles appear as charts underneath their dashboard
* LookML Explores and Views appear as data models, organized by their LookML project
* The project field is sourced differently depending on entity type: a Looker folder for Dashboards, a LookML project for Data Models

## Metadata Ingestion

To ingest metadata from Looker, you need to create a service connection. The service connects Looker with Collate. Once you create a service, Collate automatically starts ingesting metadata.

### Step 1: Add New Service

Open the Services page and start a new service.

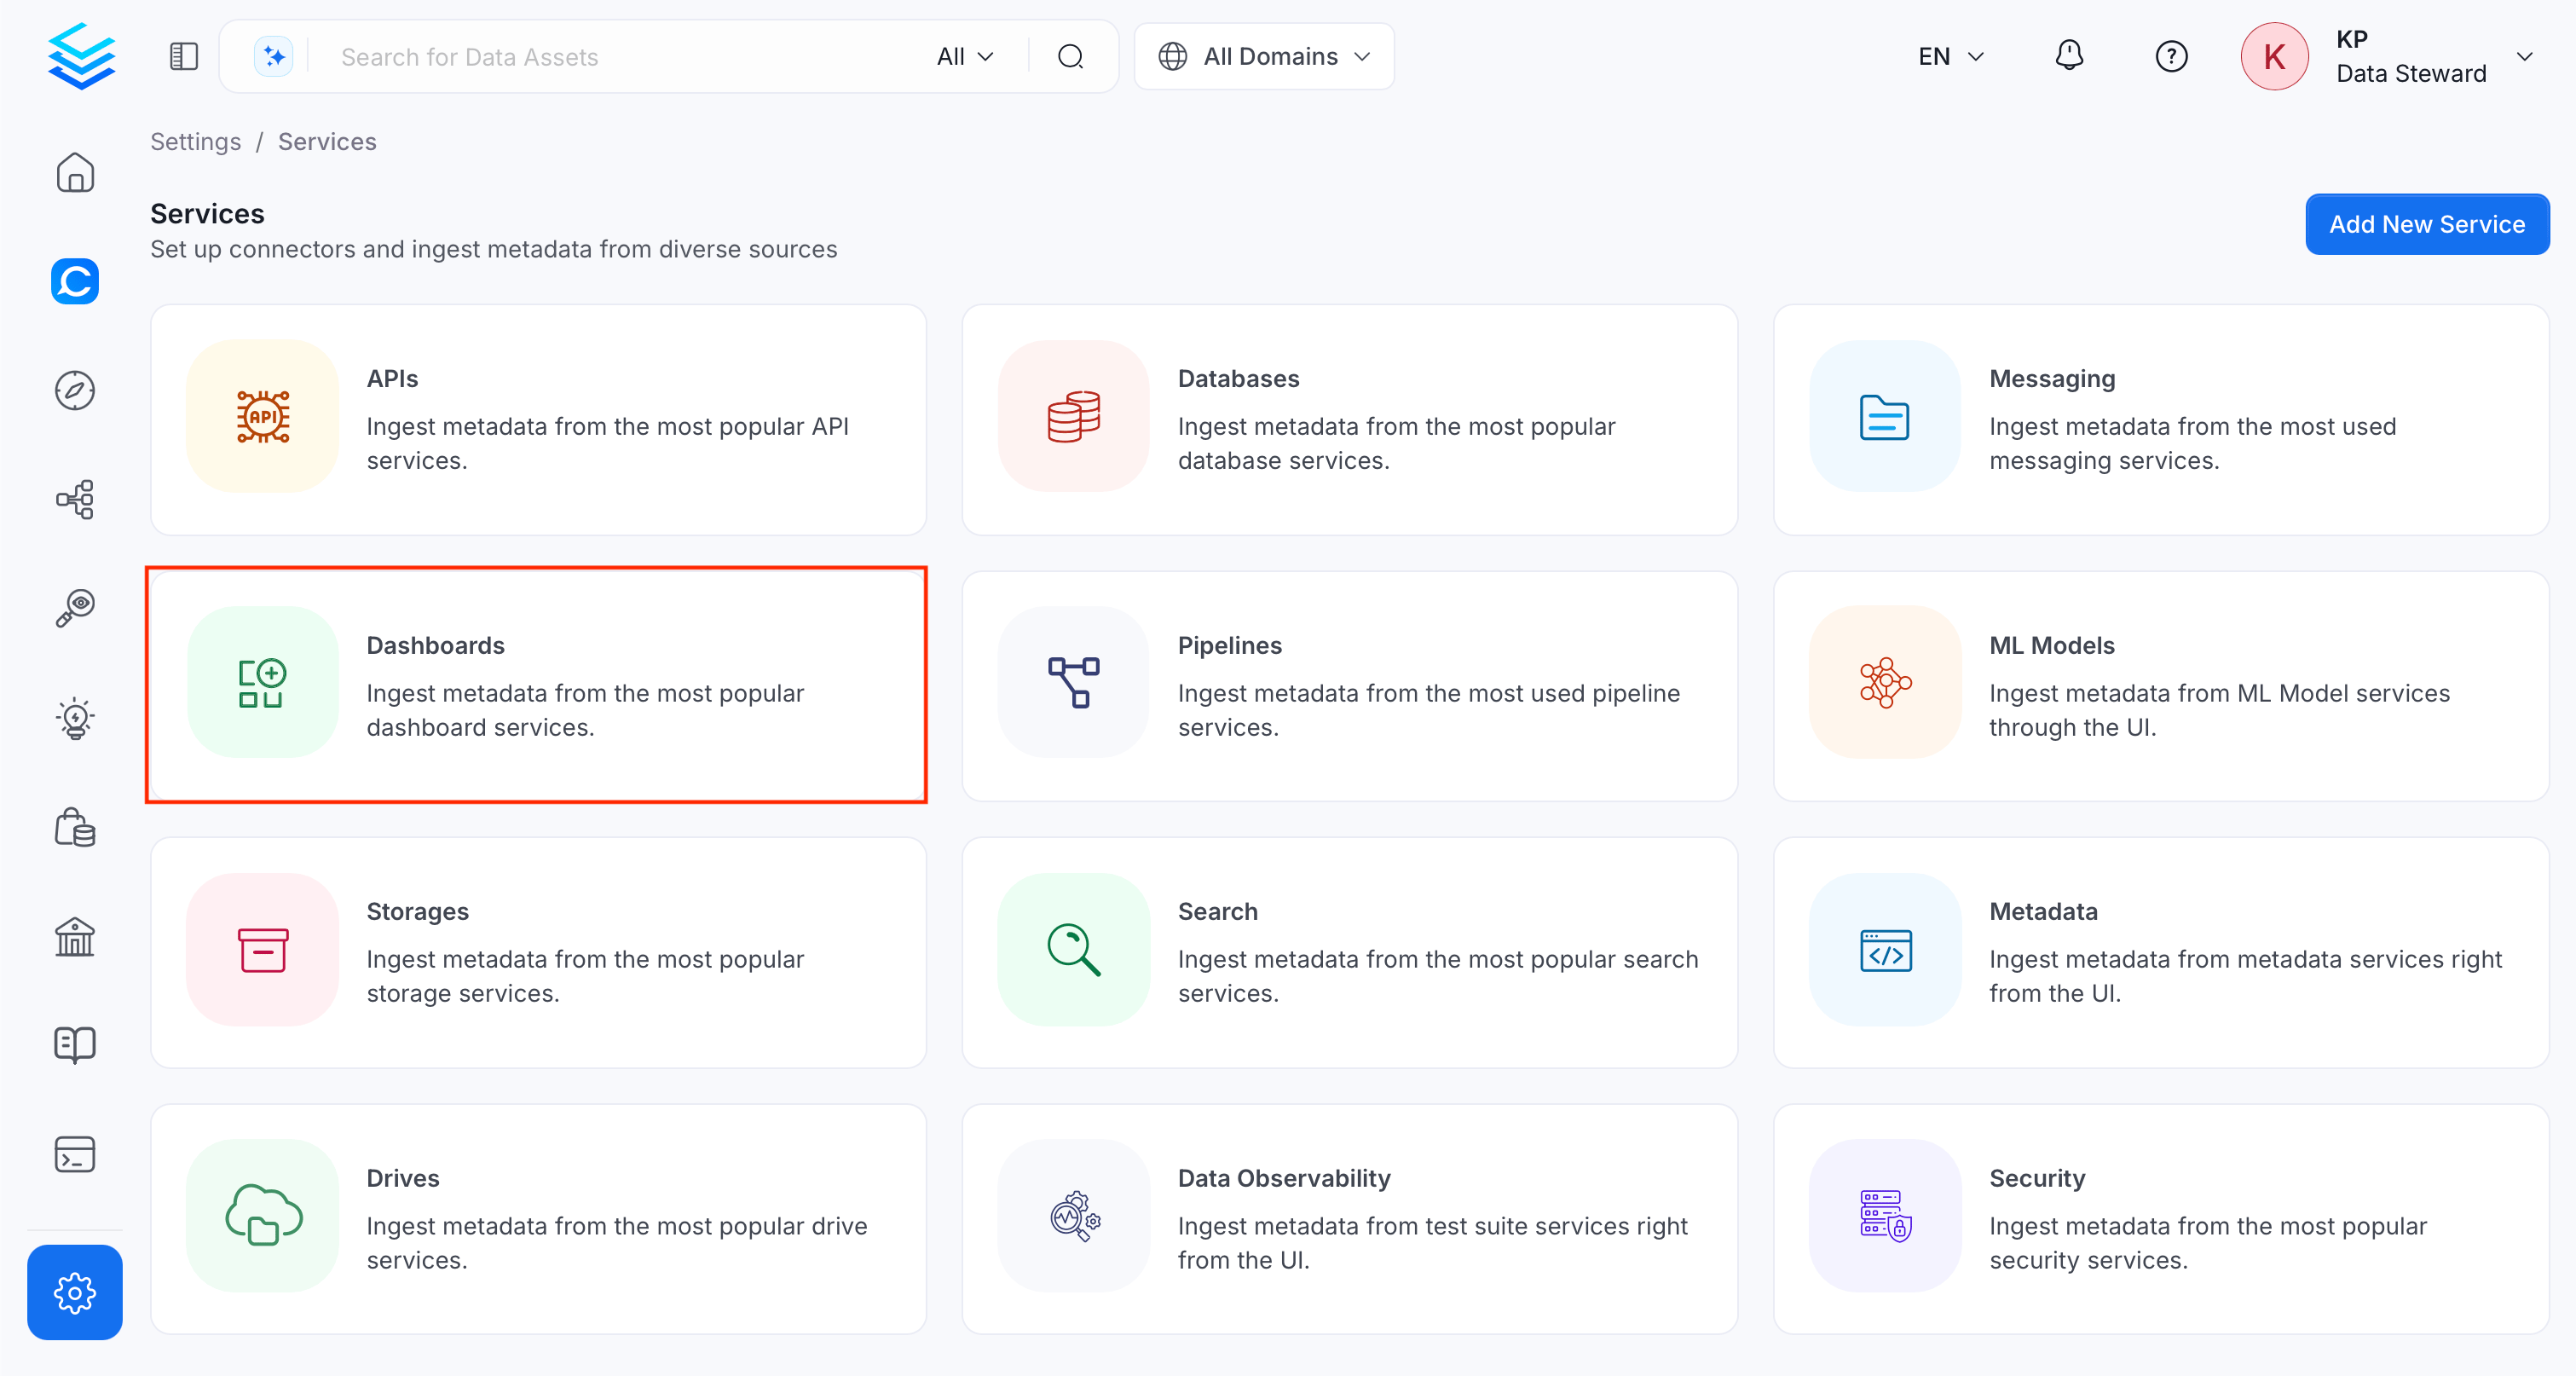
1. Navigate to **Settings** > **Services** and select **Dashboard Services**.

   <img src="https://mintcdn.com/collatedocs/uYKcw5sAfx_Tl0Ed/public/images/connectors/metadata-ingestion/classic/dashboard/visit-services.png?fit=max&auto=format&n=uYKcw5sAfx_Tl0Ed&q=85&s=8241712a8eabeb28c58eac6aa006edf6" alt="Navigate to Services" width="3022" height="1614" data-path="public/images/connectors/metadata-ingestion/classic/dashboard/visit-services.png" />

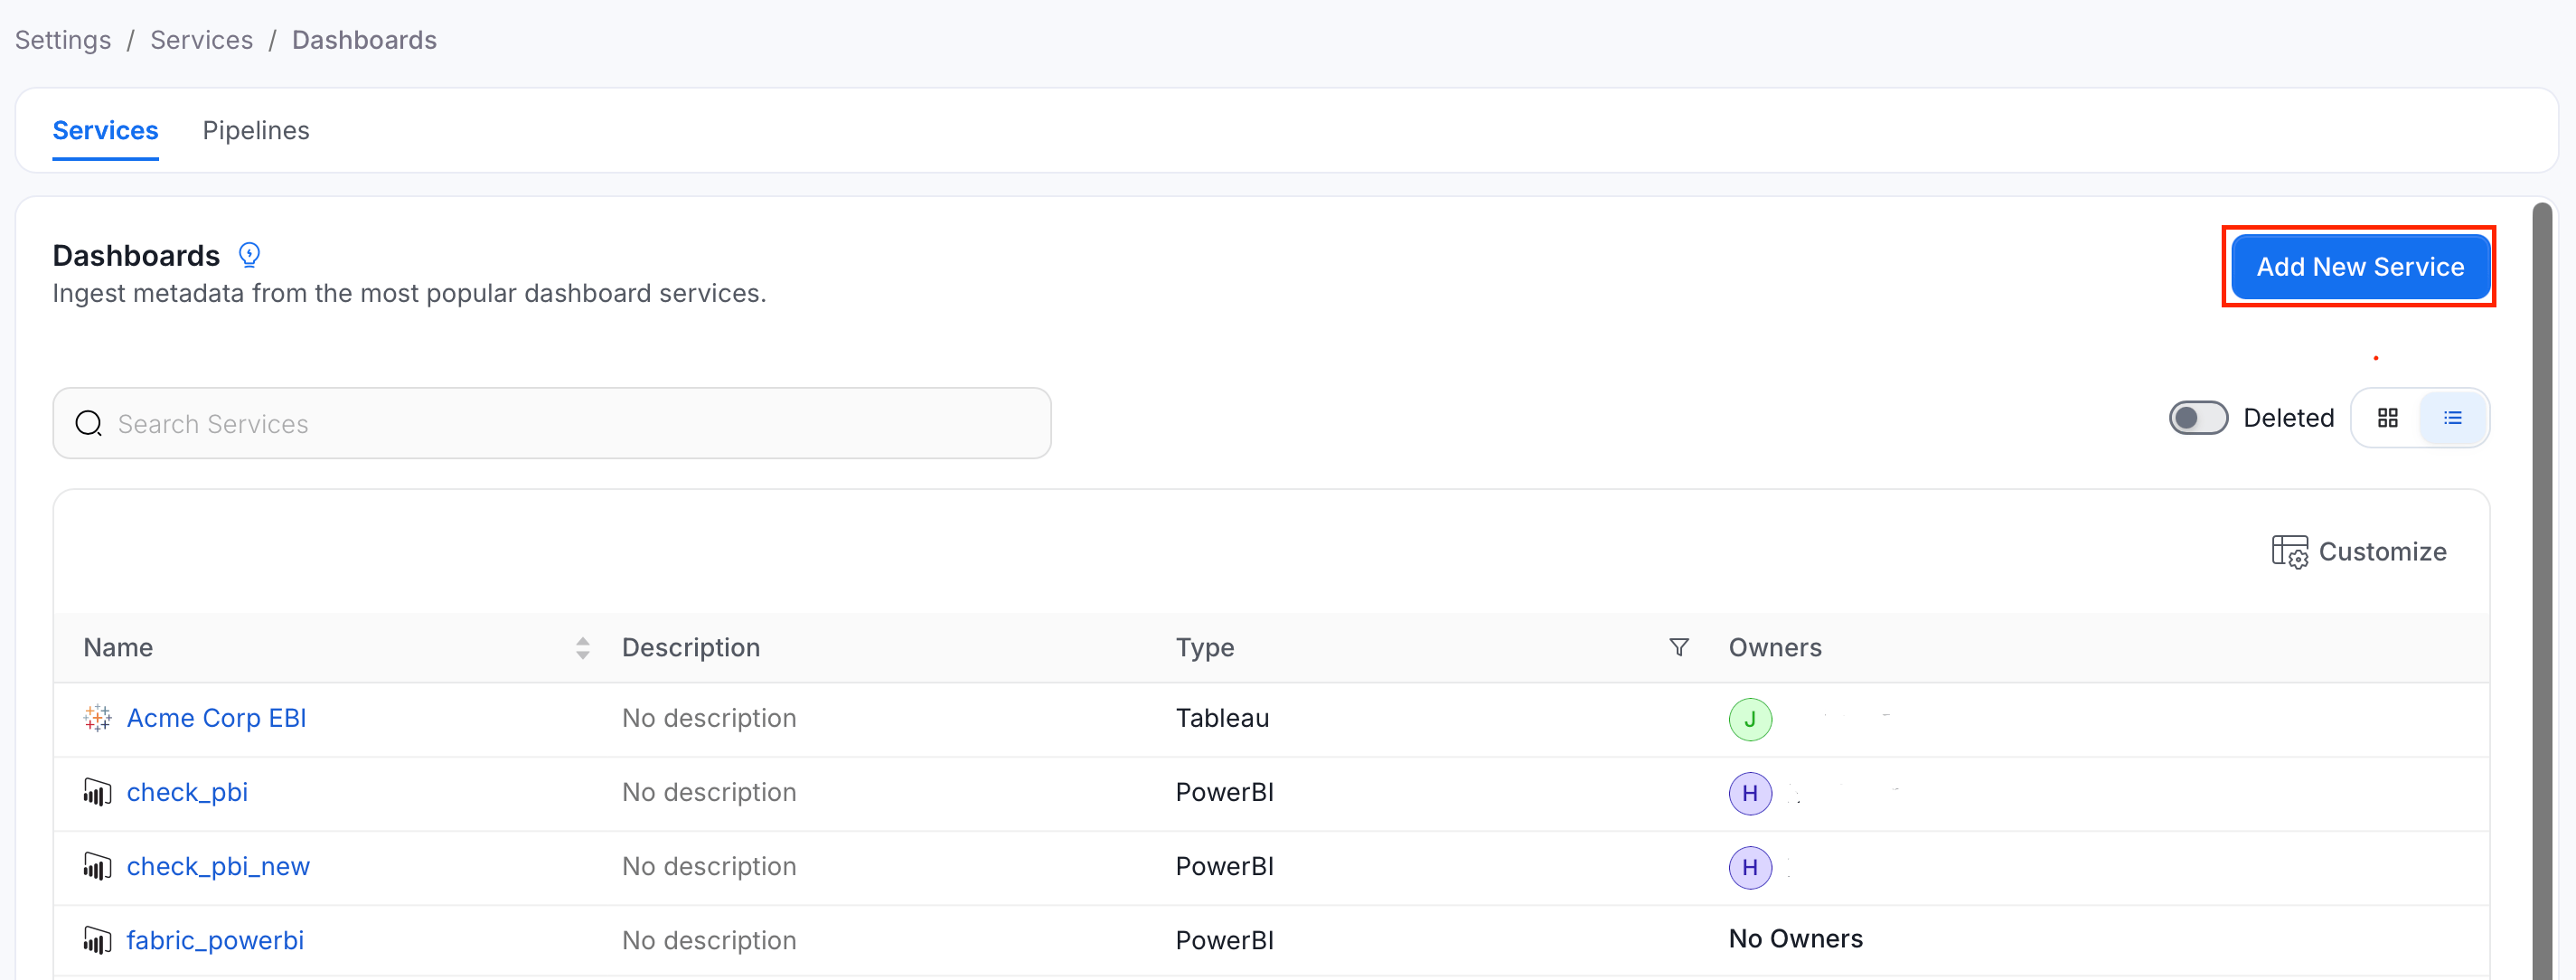
2. Click **Add New Service**.

   <img src="https://mintcdn.com/collatedocs/uYKcw5sAfx_Tl0Ed/public/images/connectors/metadata-ingestion/classic/dashboard/add-new-service.png?fit=max&auto=format&n=uYKcw5sAfx_Tl0Ed&q=85&s=c8bb1249acedea7162a7e0f57ace0039" alt="Add New Service" width="2850" height="1084" data-path="public/images/connectors/metadata-ingestion/classic/dashboard/add-new-service.png" />

### Step 2: Select a Service and Connector

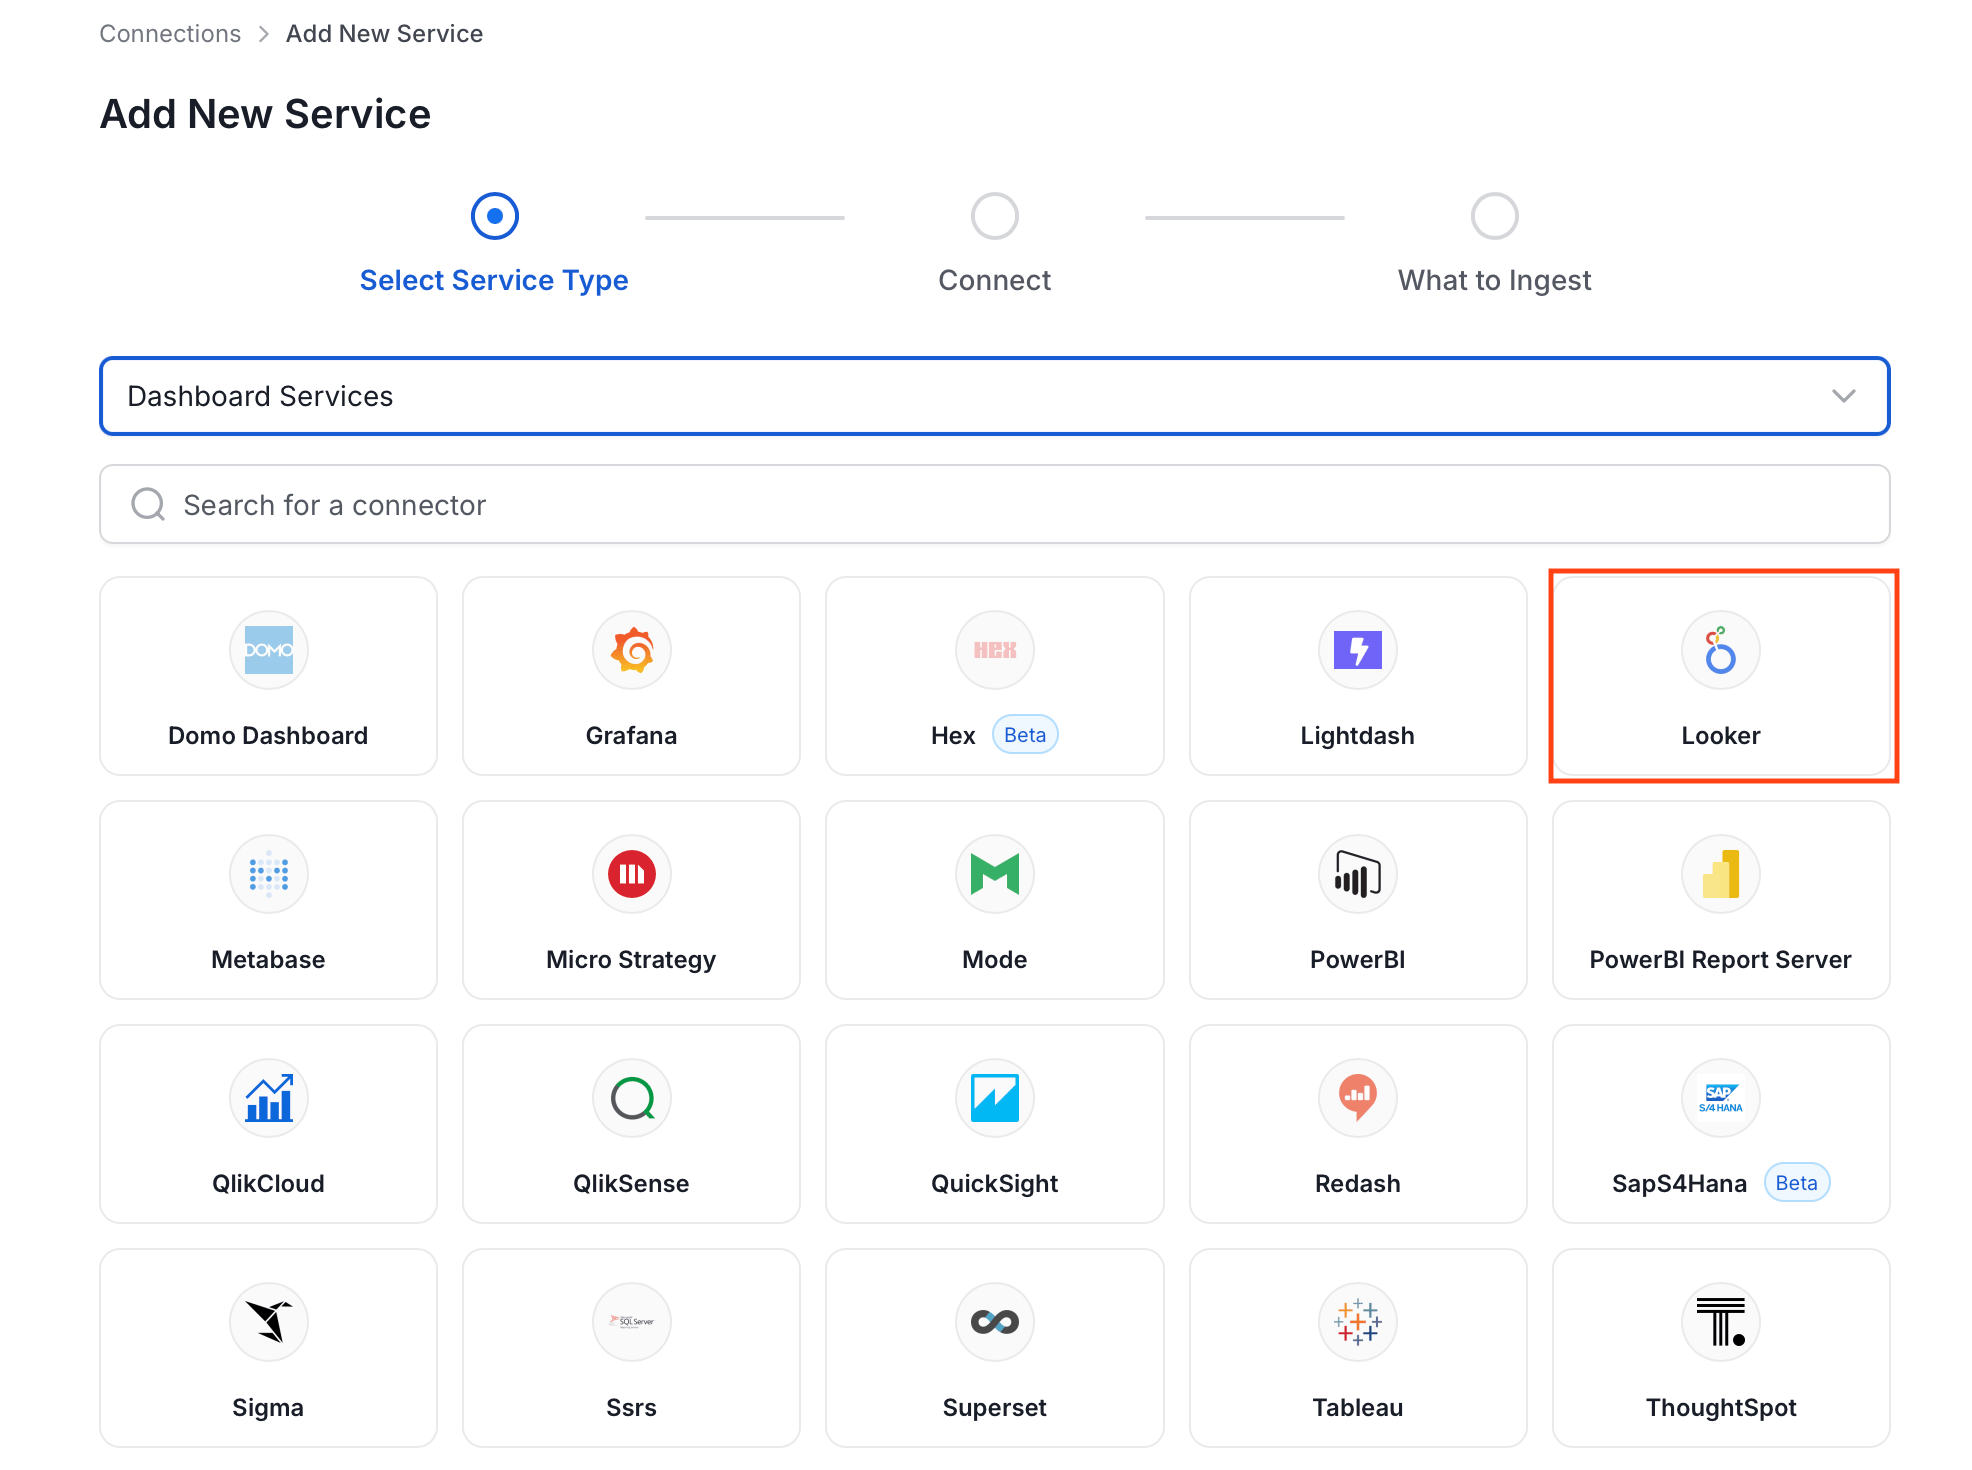
From the service type dropdown, select **Dashboard Services**, then click the **Looker** connector tile.
<img src="https://mintcdn.com/collatedocs/VsJxWKWlvReeFtlo/public/images/ai-2.0/connectors/metadata-ingestion/Dashboard/select-service/looker.png?fit=max&auto=format&n=VsJxWKWlvReeFtlo&q=85&s=065a6615ecf14c560be6fb2904bf1359" alt="Select Service" width="1972" height="1470" data-path="public/images/ai-2.0/connectors/metadata-ingestion/Dashboard/select-service/looker.png" />

### Step 3: Add Service Name and Description

* Enter a unique, descriptive **Service Name**. Collate identifies services by their service name. Enter a name that distinguishes this deployment from other Looker services you are ingesting metadata from.
* Optional: Enter a **Description** for the service.

<img src="https://mintcdn.com/collatedocs/kTp2dTyiNAX4Np5A/public/images/ai-2.0/connectors/metadata-ingestion/Dashboard/service-name/looker.png?fit=max&auto=format&n=kTp2dTyiNAX4Np5A&q=85&s=bebc36e4fee23c2c7bbc76870e779807" alt="Add New Service Name" width="1514" height="856" data-path="public/images/ai-2.0/connectors/metadata-ingestion/Dashboard/service-name/looker.png" />

<Note>
  **Note**: The service name can't be changed after you set it.
</Note>

### Step 4: Configure Connection Options

Specify where ingestion runs, provide your source credentials, and verify the connection.

#### Select Ingestion Runner

Select an **Ingestion Runner**: the runner where the ingestion pipeline will execute.

<img src="https://mintcdn.com/collatedocs/bv5oe4uRjuorTJO1/public/images/ai-2.0/connectors/metadata-ingestion/select-ingestion-runner.png?fit=max&auto=format&n=bv5oe4uRjuorTJO1&q=85&s=1249f828648614445e8a976ea1933487" alt="Add Name and Select Ingestion Runner" width="1444" height="506" data-path="public/images/ai-2.0/connectors/metadata-ingestion/select-ingestion-runner.png" />

#### Enter Connection Details

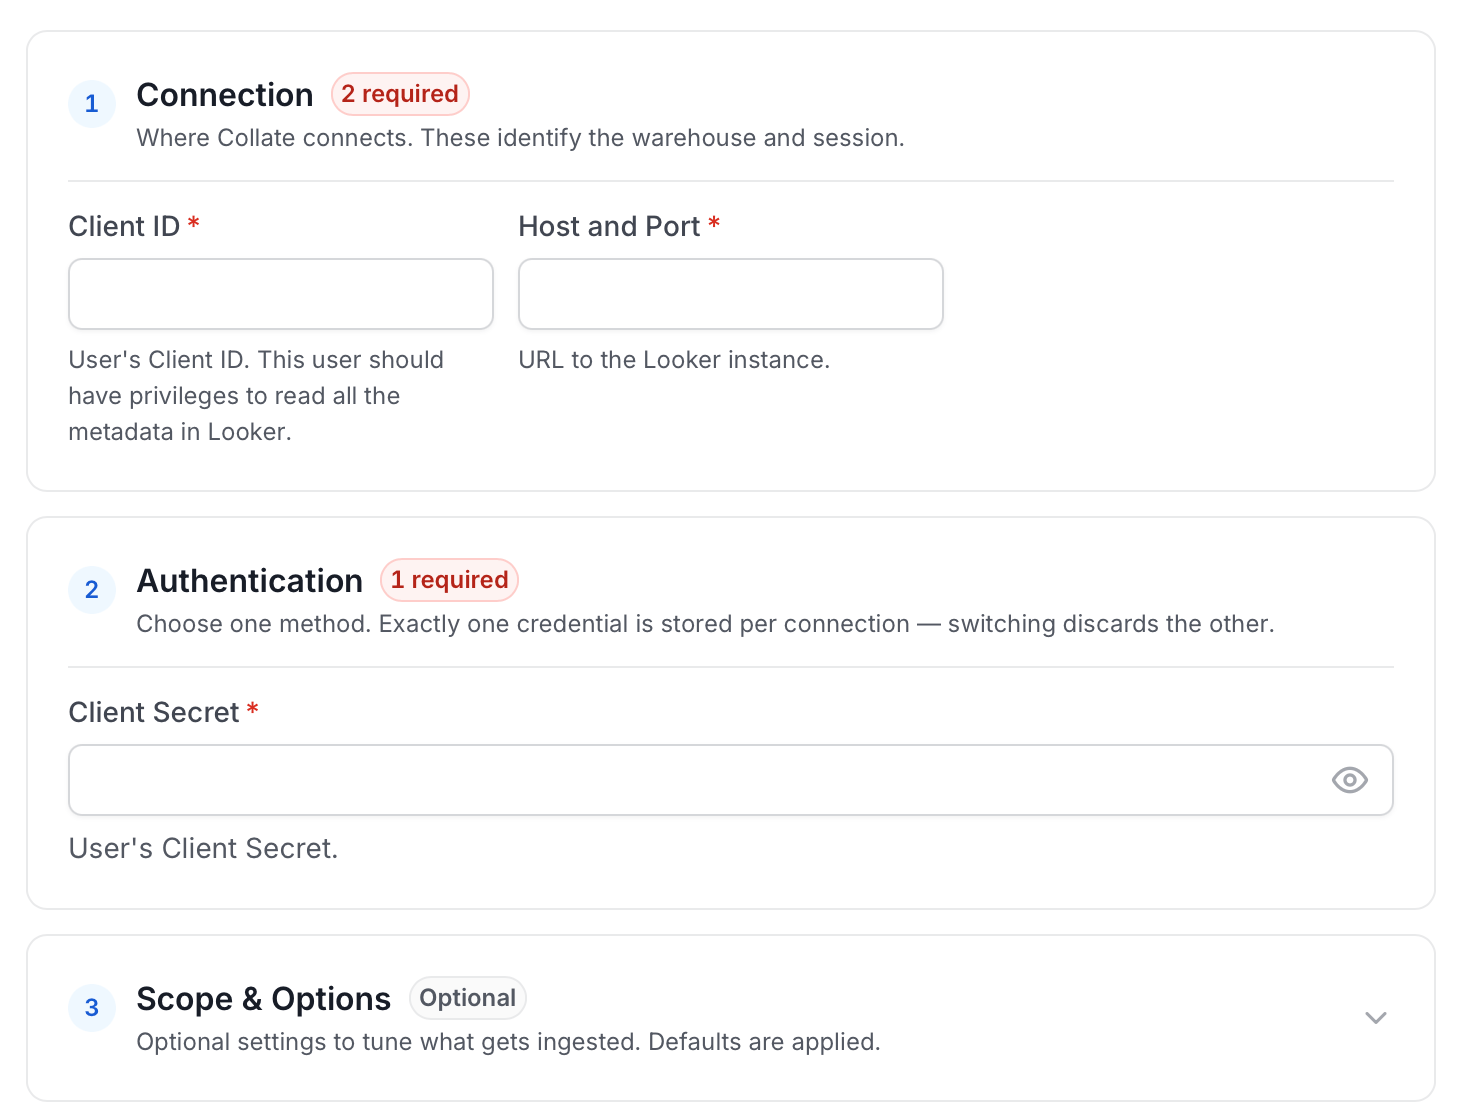
Enter the connection details for Looker. The right-hand panel in the UI displays inline help for each field.
<img src="https://mintcdn.com/collatedocs/VsJxWKWlvReeFtlo/public/images/ai-2.0/connectors/metadata-ingestion/Dashboard/connection-details/looker.png?fit=max&auto=format&n=VsJxWKWlvReeFtlo&q=85&s=aba8ec463a51a6d95138668ba8a03f87" alt="Configure Service Connection" width="1458" height="1116" data-path="public/images/ai-2.0/connectors/metadata-ingestion/Dashboard/connection-details/looker.png" />

**Connection**

* **Client ID**: User's Client ID to authenticate to the SDK. This user should have privileges to read all the metadata in Looker.
* **Host and Port**: URL to the Looker instance, for example, `https://my-company.region.looker.com`.

**Authentication**

* **Client Secret**: User's Client Secret for the same ID provided.

**Scope & Options**

* **Git Credentials**: Choose how to extract the `.lkml` files that hold your LookML views and their lineage to source tables:
  * **No Git Credentials**: Default option. Skips LookML view ingestion and lineage to source tables.
  * **Local Path**: Path to the repository on the local file system where the ingestion pipeline runs, for example `/opt/looker/repo`.
  * **GitHub Credentials**: Credentials for a GitHub repository.

    * **Git Host URL**: GitHub instance URL. For GitHub.com, use `https://github.com`.
    * **Repository Owner**: The owner (user or organization) of a GitHub repository. For example, in [https://github.com/open-metadata/OpenMetadata](https://github.com/open-metadata/OpenMetadata), the owner is `open-metadata`.
    * **Repository Name**: The name of a GitHub repository. For example, in [https://github.com/open-metadata/OpenMetadata](https://github.com/open-metadata/OpenMetadata), the name is `OpenMetadata`. To ingest LookML files from multiple repositories under the same owner, provide a comma-separated list, for example `looker-main-repo,looker-secondary-repo,looker-analytics-repo`.
    * **API Token**: Token to use the API. This is required for private repositories and to avoid hitting API rate limits.

    To create a fine-grained personal access token, see [Creating a fine-grained personal access token](https://docs.github.com/en/authentication/keeping-your-account-and-data-secure/creating-a-personal-access-token#creating-a-fine-grained-personal-access-token). When configuring, give repository access to `Only select repositories` and choose the one containing your LookML files. Set `Repository Permissions` to `Read-only` for `Contents`.
  * **BitBucket Credentials**: Credentials for a BitBucket repository.
    * **Git Host URL**: BitBucket instance URL. For BitBucket Cloud, use `https://bitbucket.org`.
    * **Repository Owner**: The owner (user or organization) of the repository.
    * **Repository Name**: The name of the repository. To ingest LookML files from multiple repositories under the same owner, provide a comma-separated list, for example `looker-main-repo,looker-secondary-repo,looker-analytics-repo`.
    * **API Token**: Token to use the API. This is required for private repositories and to avoid hitting API rate limits.
    * **Main Branch**: Main production branch of the repository, for example `main`. This field is required.
  * **GitLab Credentials**: Credentials for a GitLab repository.
    * **Git Host URL**: GitLab instance URL. For GitLab.com, use `https://gitlab.com`.
    * **Repository Owner**: The owner (user or organization) of the repository.
    * **Repository Name**: The name of the repository. To ingest LookML files from multiple repositories under the same owner, provide a comma-separated list, for example `looker-main-repo,looker-secondary-repo,looker-analytics-repo`.
    * **API Token**: Token to use the API. This is required for private repositories and to avoid hitting API rate limits.

#### Test Connection

1. Click **Test Connection** to verify the credentials.
2. After the test succeeds, click **Save**.
<img src="https://mintcdn.com/collatedocs/bv5oe4uRjuorTJO1/public/images/ai-2.0/connectors/metadata-ingestion/test-connection.png?fit=max&auto=format&n=bv5oe4uRjuorTJO1&q=85&s=3365cff7bb9d82c85a2ff9ab559d6f11" alt="Test Connection" width="1446" height="188" data-path="public/images/ai-2.0/connectors/metadata-ingestion/test-connection.png" />

### Step 5: Configure Ingestion Options

In the **What to Ingest** step, use filter patterns to control which assets Collate ingests from your dashboard service. Filter rules match asset names using the following match types.

#### How Filter Patterns Work

* **Include**: Add one or more comma-separated values. Each value uses one of the following match types. Collate ingests only assets whose names match at least one rule. Leave blank to include all assets.
* **Exclude**: Add one or more comma-separated values. Each value uses one of the following match types. Collate skips any asset whose name matches a rule. Leave blank to exclude nothing.

Rules match asset names using one of five match types:

* **contains**: matches any name containing the value. For example, `sales` matches `my_sales_data` and `sales_2024`.
* **starts with**: matches names beginning with the value. For example, `prod_` matches `prod_db` and `prod_schema`.
* **ends with**: matches names ending with the value. For example, `_raw` matches `events_raw` and `logs_raw`.
* **is exactly**: matches the exact name only. For example, `analytics` matches only `analytics`.
* **matches regex**: matches names using a regular expression. For example, `^prod_.*_v\d+$` matches `prod_events_v1`.

When both Include and Exclude are set, Exclude takes priority.
<Tip>
  **Tip**: Leave all filter patterns empty to ingest all dashboards and charts available in the source.
</Tip>

#### Filter Options

The Dashboard and Chart sections each include the following filter options:

* **Dashboard**: Controls which dashboards Collate ingests from the source.
* **Chart**: Controls which charts within the ingested dashboards are included.

Each section provides the following controls:

* **Scan Mode**: Choose between the following scan modes:
  * **Scan all**: Ingests every asset of that type the connector can access. This is the default.
  * **Only specific**: Enables include rules so only assets matching at least one rule are ingested.
* **Exclude system toggle**: Use this toggle to filter out system-reserved names defined by the connector for that asset type.
* **Always exclude**: Add permanent exclusion rules (shown in red). Assets matching these rules are never ingested, regardless of include rules.
* **Preview**: Shows a real-time summary of what will be in scope based on your current rules.
* **Include rules**: In **Only specific** mode, click **+ Add** to define a rule. Added rules appear as chips. An asset is included if it matches any rule.

<Tip>
  **Tip**: If [AutoPilot](/how-to-guides/admin-guide/applications/autopilot) is enabled, usage tracking, data lineage, and other downstream workflows start automatically after the first metadata ingestion completes.
</Tip>

### Step 6: Create & Deploy

Click **Create & Deploy** to deploy the agent and start the first metadata ingestion run. Collate saves the service configuration and immediately begins pulling metadata from the source.

To monitor ingestion progress or view the service you just added, go to **Settings** > **Services** and select your service.

## Configure Metadata Agent and Schedule Ingestion

The **Metadata Agent** extracts dashboards, charts, data models, and other structural metadata from your source and keeps your Collate catalog in sync. It powers discovery, lineage, and governance across your data assets.

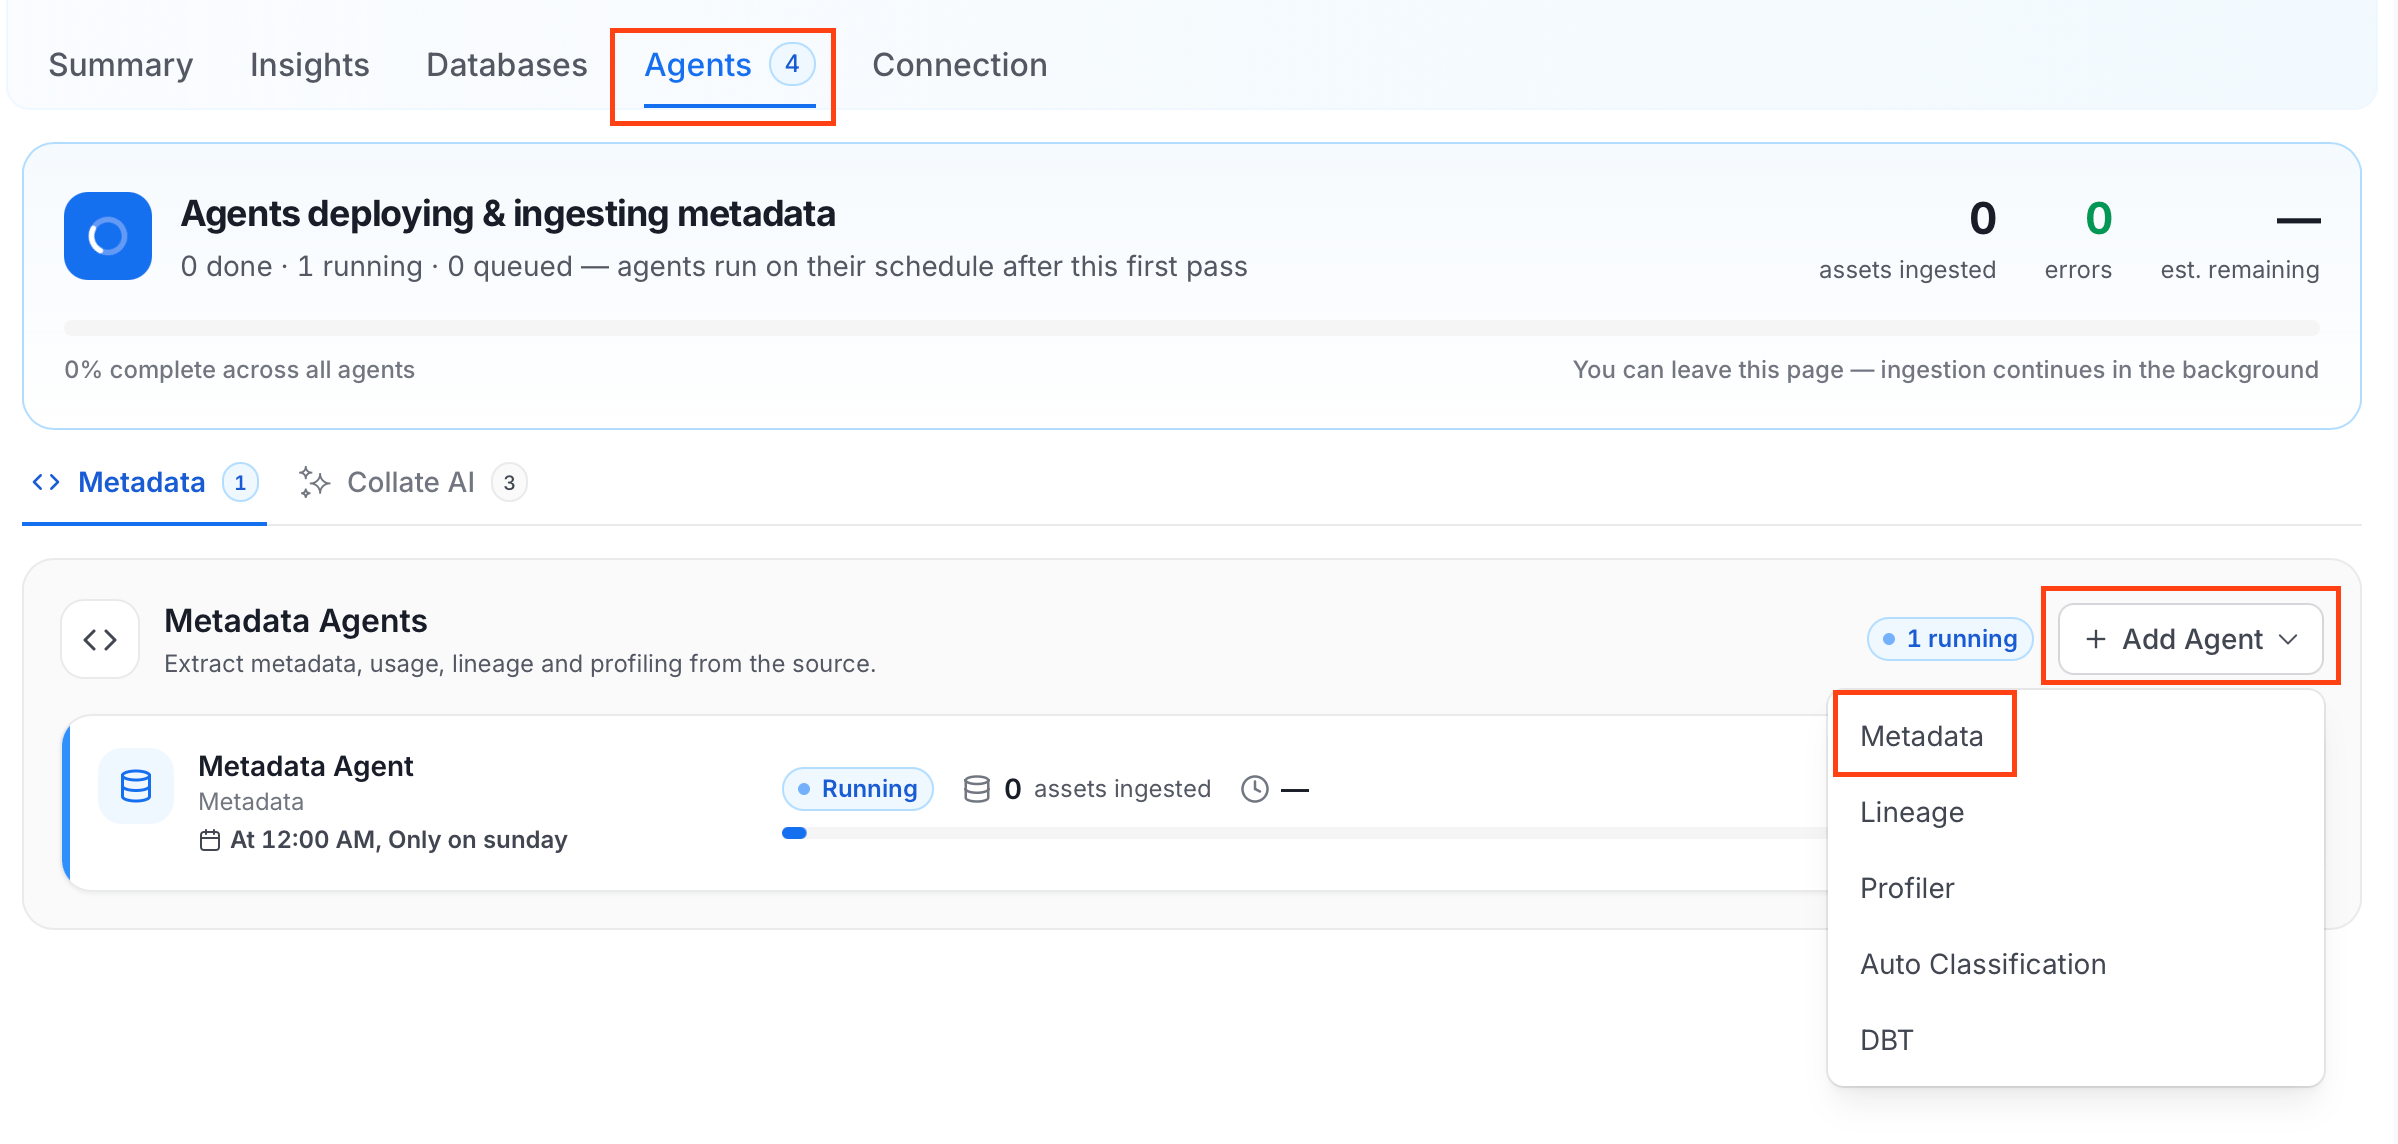
When you click **Create & Deploy**, Collate automatically deploys a Metadata Agent for this service and triggers the first ingestion run. View its status and run history from the **Agents** tab on the service detail page.

To configure the additional Metadata Agent and schedule ingestion, follow these steps:

1. Navigate to **Settings** > **Services** and select the **Dashboards** service.

2. Select your service and click the **Agents** tab.

3. Click **Add Agent** and select **Metadata** from the dropdown.
   <img src="https://mintcdn.com/collatedocs/bv5oe4uRjuorTJO1/public/images/ai-2.0/connectors/metadata-ingestion/add-metadata-agent.png?fit=max&auto=format&n=bv5oe4uRjuorTJO1&q=85&s=accad7d1c4ddf209781bff851d51d464" alt="Add Metadata Agent" width="2398" height="1144" data-path="public/images/ai-2.0/connectors/metadata-ingestion/add-metadata-agent.png" />
   For some services, the dropdown is not available and clicking **Add Agent** takes you directly to the agent configuration page.

4. On the **Configure Ingestion** page, do the following and click **Next**.

   * **Name this Ingestion**: Enter a unique, recognizable name for this ingestion pipeline.

     <img src="https://mintcdn.com/collatedocs/bv5oe4uRjuorTJO1/public/images/ai-2.0/connectors/metadata-ingestion/metadata-agent-name.png?fit=max&auto=format&n=bv5oe4uRjuorTJO1&q=85&s=d5ec1f0f3742cadab8cd54c602c97239" alt="Name this Ingestion" width="1578" height="644" data-path="public/images/ai-2.0/connectors/metadata-ingestion/metadata-agent-name.png" />

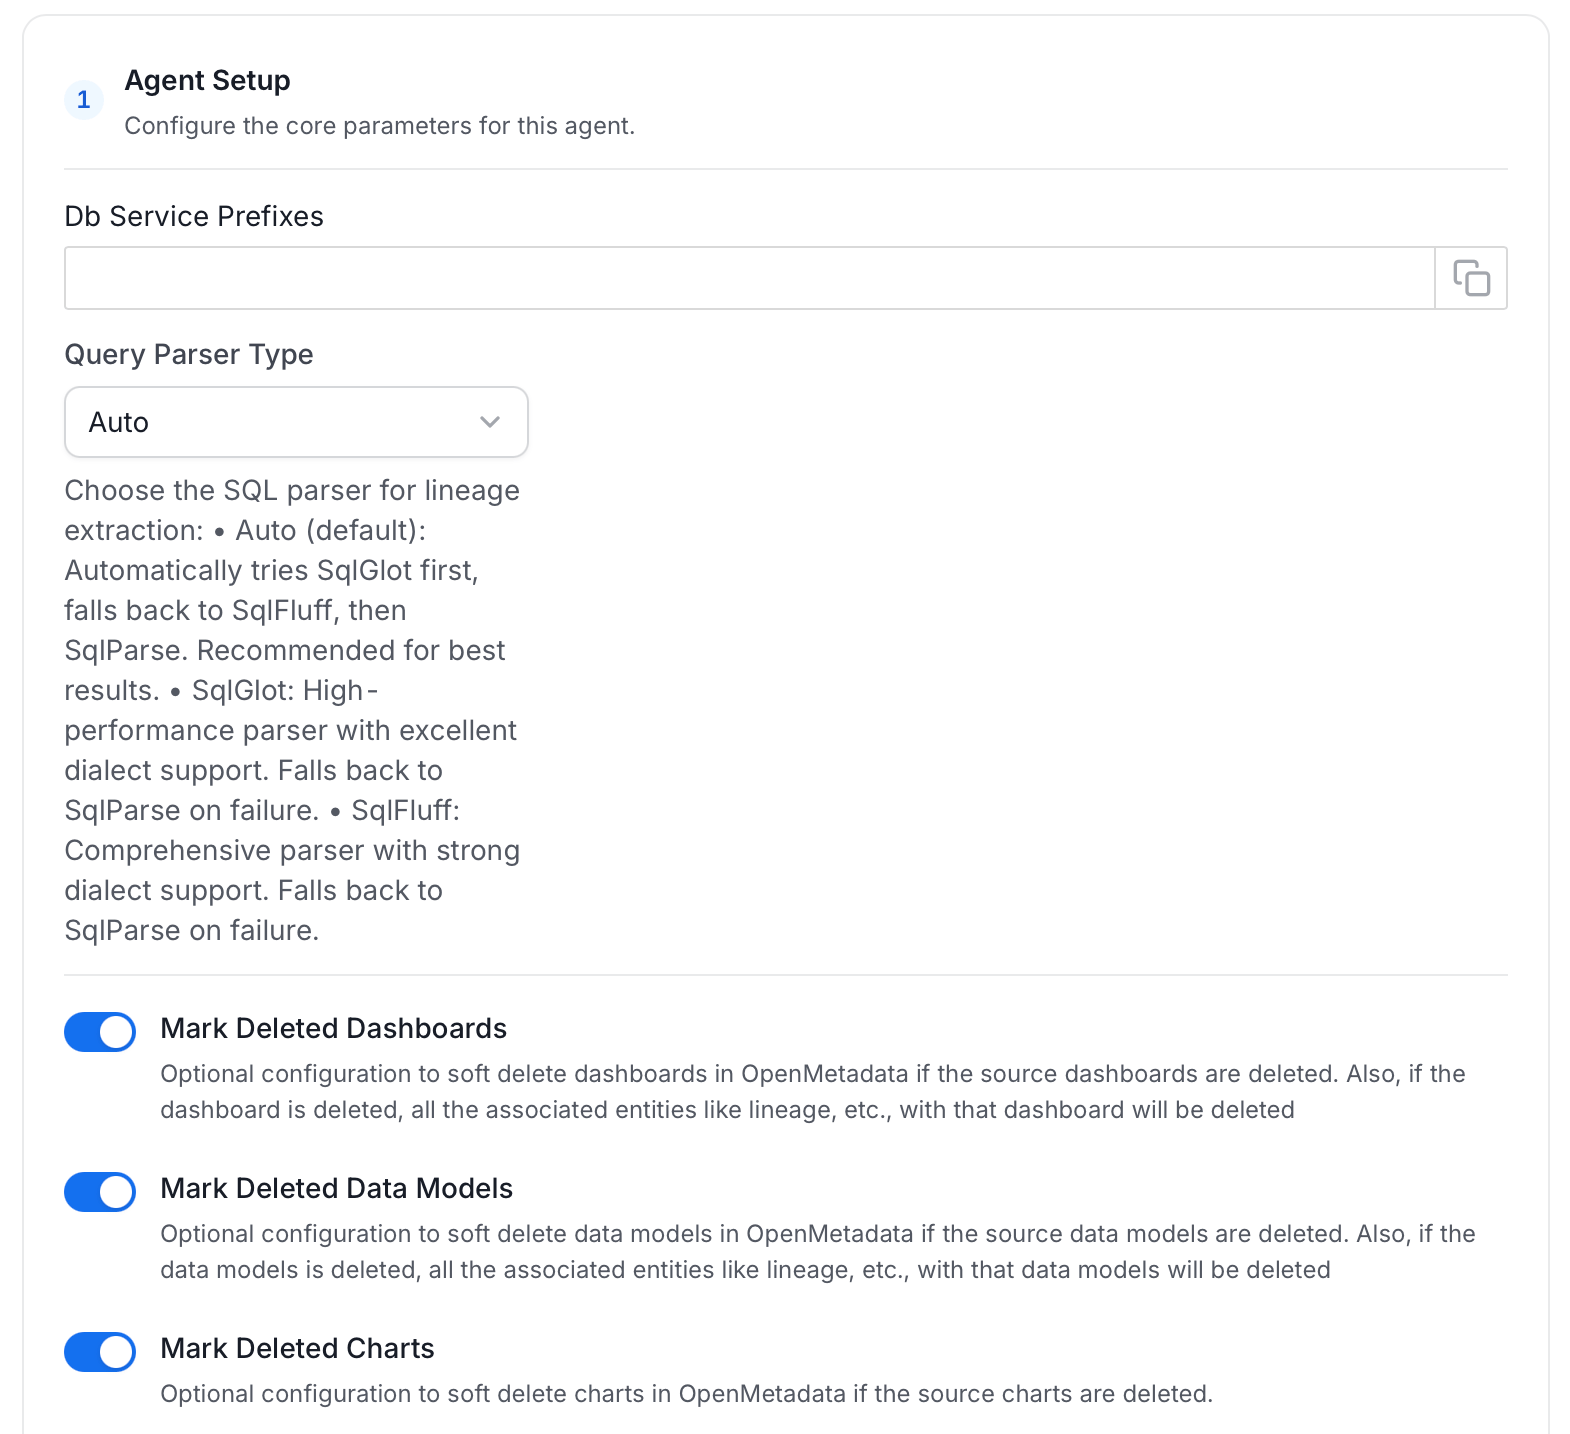
   * **Agent Setup**: Configure ingestion parameters. The following fields are available:

     | Field | Default | Description |
     | - | - | - |
     | Db Service Prefixes | — | List of database service name prefixes used to resolve lineage between dashboards and database assets. Accepted formats: `DBService`, `DBService.Database`, `DBService.Database.Schema`, `DBService.Database.Schema.Table`. |
     | Query Parser Type | Auto | Select the SQL parser used for lineage extraction from dashboard queries. **Auto** selects the best available parser automatically. **SqlGlot** is a high-performance parser with excellent dialect support; falls back to SqlParse on failure. **SqlFluff** is a comprehensive parser with strong dialect support; falls back to SqlParse on failure. |
     | Mark Deleted Dashboards | On | Soft-delete dashboards in Collate when they are removed from the source. Associated lineage is also deleted. |
     | Mark Deleted Data Models | On | Soft-delete data models in Collate when they are removed from the source. Associated lineage is also deleted. |
     | Mark Deleted Charts | On | Soft-delete charts in Collate when they are removed from the source. |
     | Include Data Models | On | Ingest data model metadata. |
     | Include Draft Dashboards | On | Ingest dashboards that are in draft state. |
     | Include Usage | On | Collect and ingest usage statistics for dashboards. |
     <img src="https://mintcdn.com/collatedocs/VsJxWKWlvReeFtlo/public/images/ai-2.0/connectors/metadata-ingestion/Dashboard/dashboard-agent-setup.png?fit=max&auto=format&n=VsJxWKWlvReeFtlo&q=85&s=4331bedb92cf4fc886548ed7e9d9caf7" alt="Agent Setup" width="1570" height="1434" data-path="public/images/ai-2.0/connectors/metadata-ingestion/Dashboard/dashboard-agent-setup.png" />

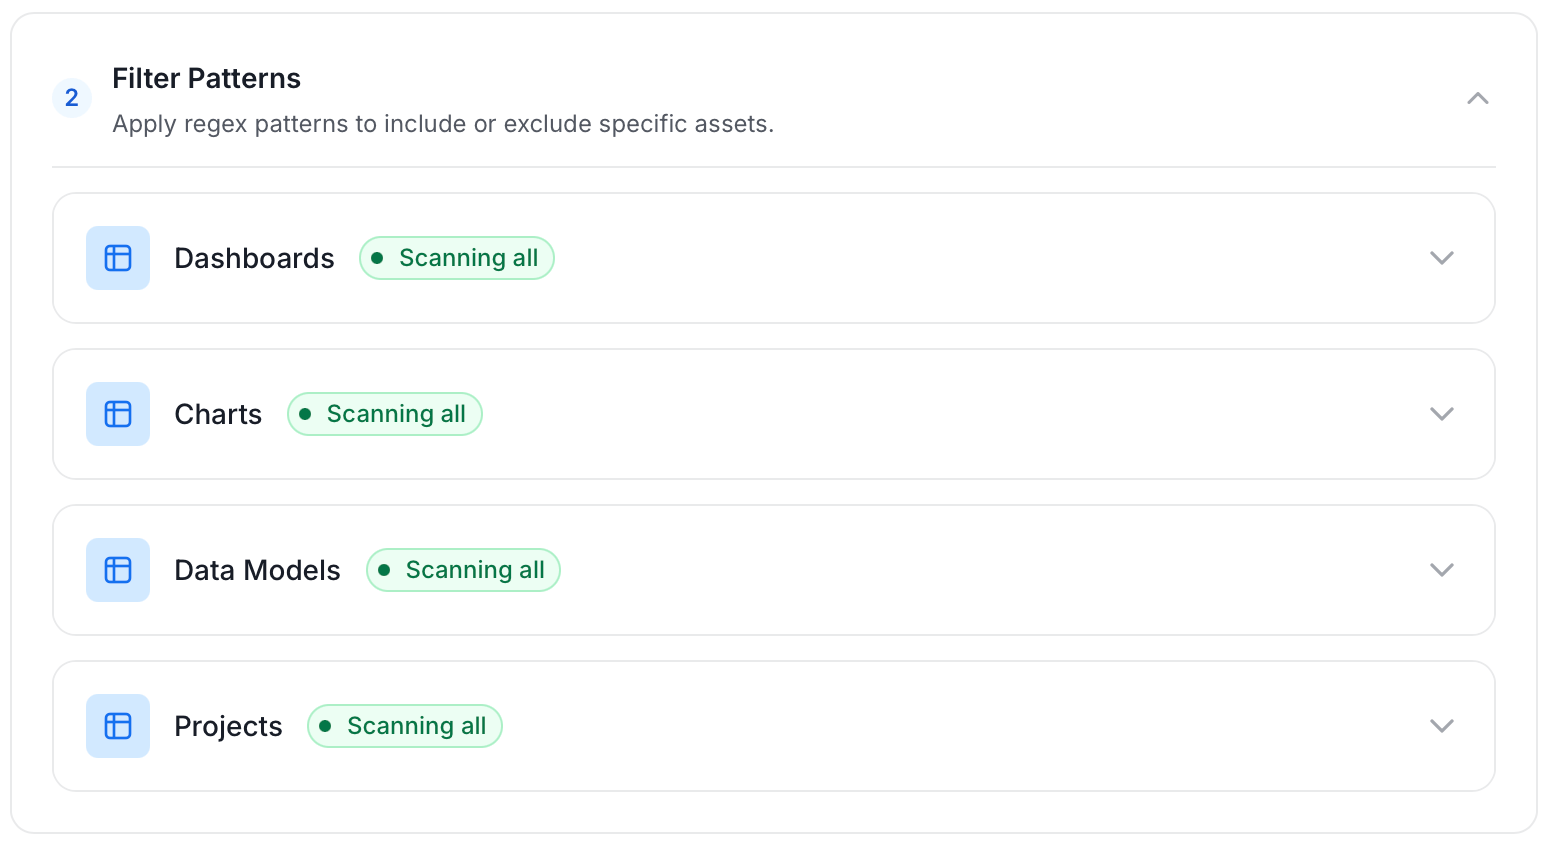
   * **Filter Patterns**: Apply include or exclude rules to scope which dashboards, charts, data models, and projects this agent ingests. These follow the same filter options described in **Step 5**.
     <img src="https://mintcdn.com/collatedocs/VsJxWKWlvReeFtlo/public/images/ai-2.0/connectors/metadata-ingestion/Dashboard/dashboard-filter-pattern.png?fit=max&auto=format&n=VsJxWKWlvReeFtlo&q=85&s=fafba3522eb159607f520f8252cace56" alt="Filter Patterns" width="1546" height="844" data-path="public/images/ai-2.0/connectors/metadata-ingestion/Dashboard/dashboard-filter-pattern.png" />

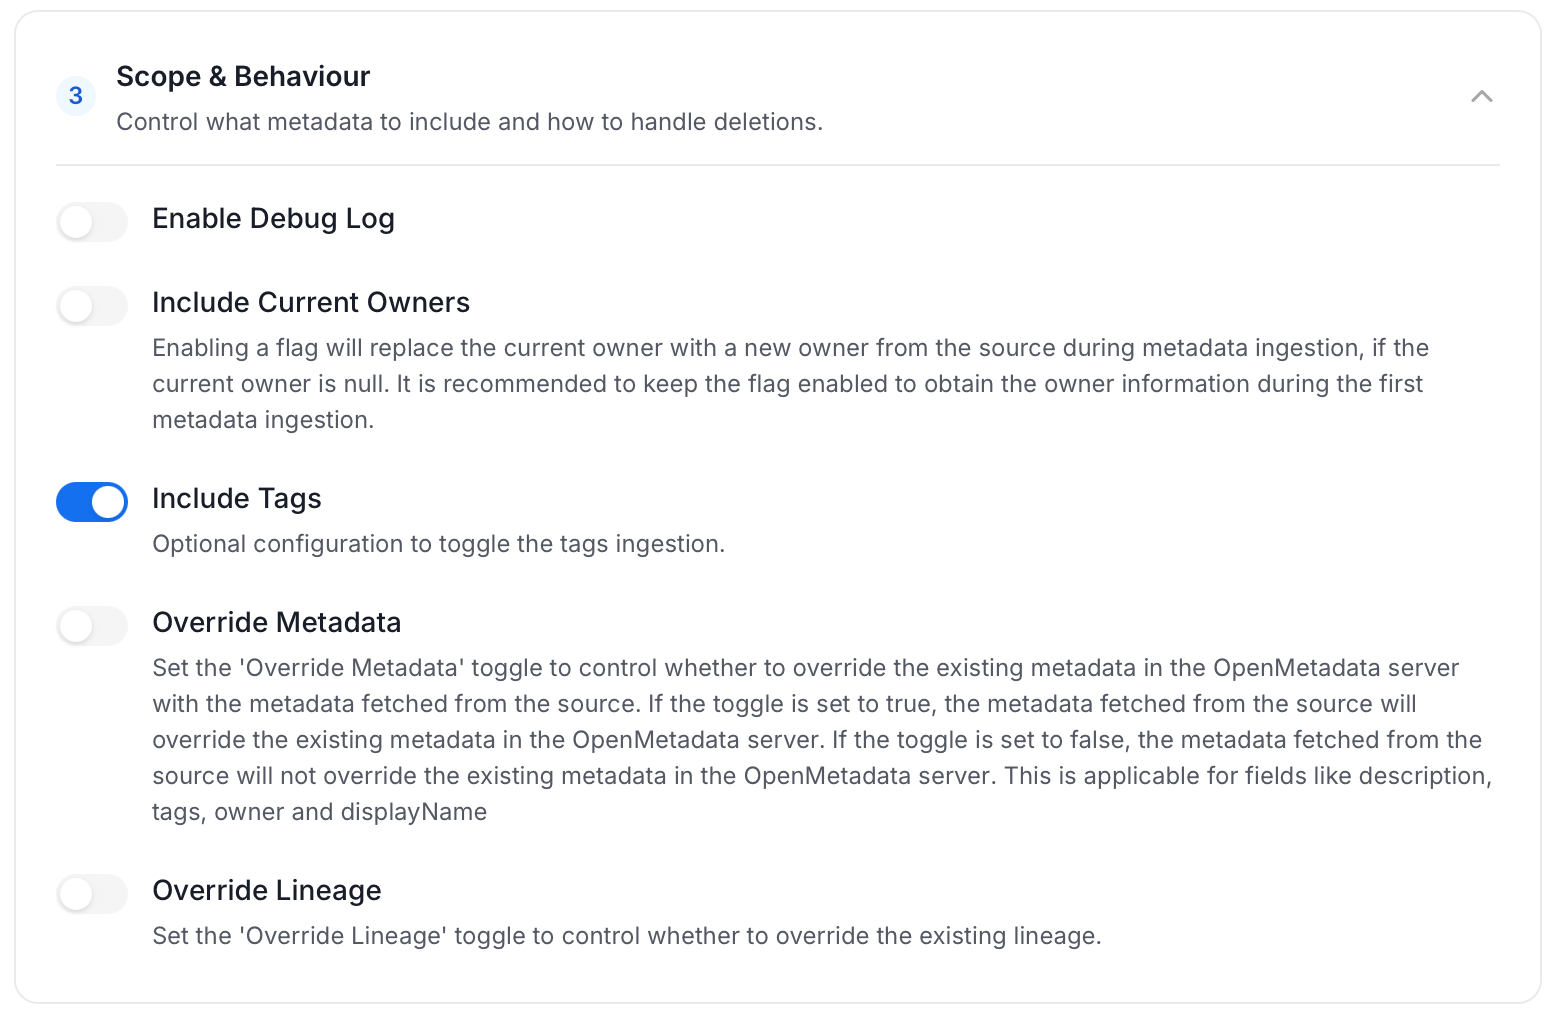
   * **Scope & Behaviour**: Control what metadata to include and how to handle deletions. Toggle each option on or off based on your needs:

     | Toggle | Default | Description |
     | - | - | - |
     | Enable Debug Log | Off | Sets the ingestion log level to DEBUG. Useful for troubleshooting. |
     | Include Current Owners | Off | When enabled, replaces the current owner with a new owner from the source if the current owner is null. Recommended to keep enabled during the first metadata ingestion to capture owner information. |
     | Include Tags | On | Ingest tags from the source. |
     | Override Metadata | Off | When on, source values overwrite existing descriptions, tags, owners, and display names in Collate. When off, Collate only updates fields that have no existing value. |
     | Override Lineage | Off | When on, existing lineage is replaced with newly extracted lineage on each run. |
     <img src="https://mintcdn.com/collatedocs/VsJxWKWlvReeFtlo/public/images/ai-2.0/connectors/metadata-ingestion/Dashboard/dashboard-scope-bahaviour.png?fit=max&auto=format&n=VsJxWKWlvReeFtlo&q=85&s=b62494bc009ab02b79062e74519e89de" alt="Scope & Behaviour" width="1552" height="1014" data-path="public/images/ai-2.0/connectors/metadata-ingestion/Dashboard/dashboard-scope-bahaviour.png" />

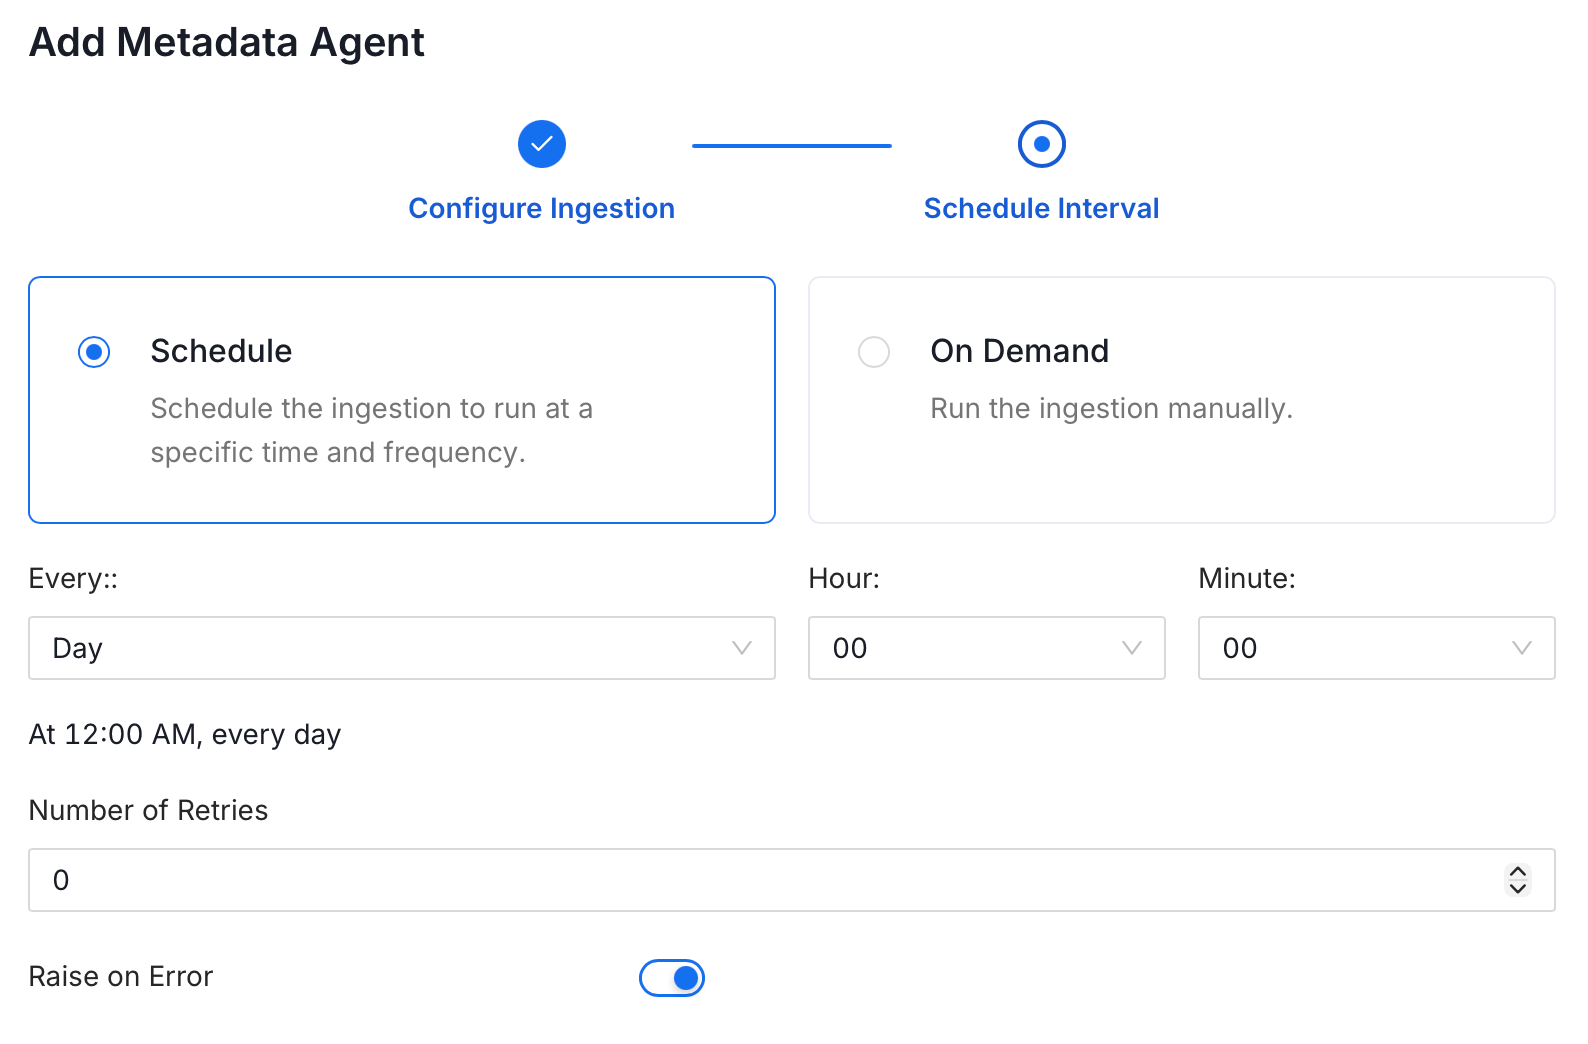
5. On the **Schedule Interval** page, set when the agent runs:

   * **Schedule**: Choose a preset interval (Hourly, Daily, Weekly, Monthly) or enter a custom cron expression.
   * **On-Demand**: No automatic schedule. Trigger the agent manually when needed.
   <img src="https://mintcdn.com/collatedocs/bv5oe4uRjuorTJO1/public/images/ai-2.0/connectors/metadata-ingestion/schedule.png?fit=max&auto=format&n=bv5oe4uRjuorTJO1&q=85&s=25cc1d78f6f2a8bd115830d034d1d8d1" alt="Schedule Interval" width="1588" height="1044" data-path="public/images/ai-2.0/connectors/metadata-ingestion/schedule.png" />

6. Click **Add** to deploy the agent.

## Lineage

## Lineage

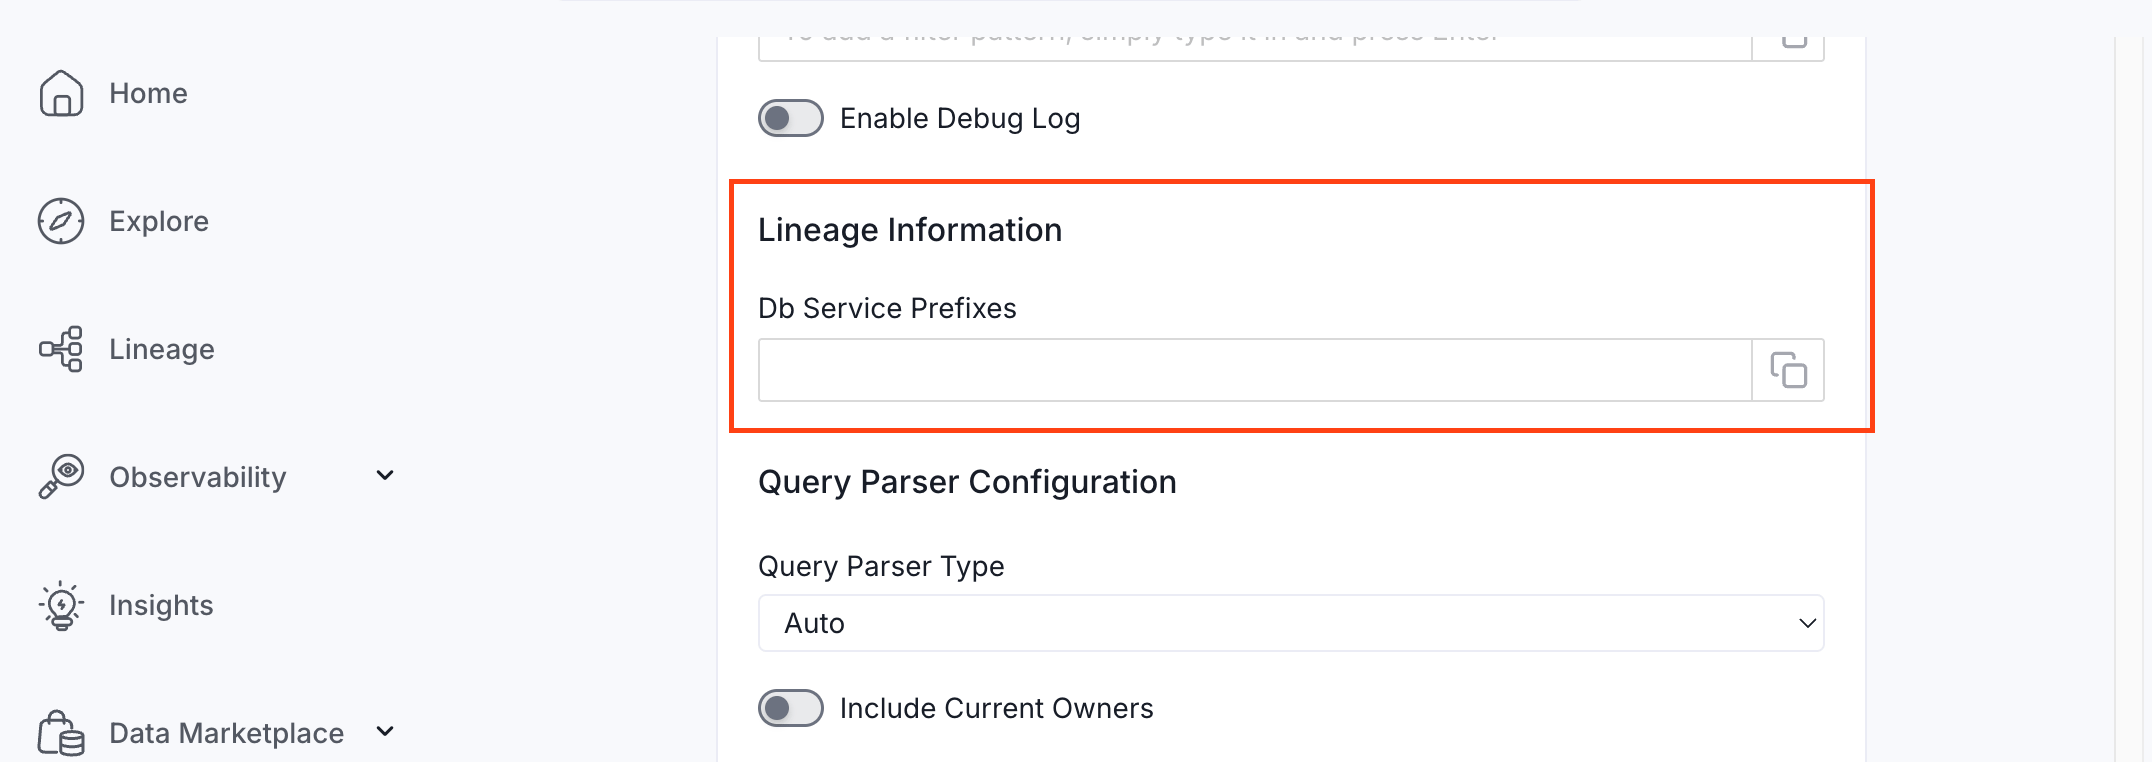
Lineage in Collate shows you which database tables power each dashboard. When lineage is set up, you can trace any dashboard back to the exact source tables in your database.

There is no separate lineage agent or lineage pipeline—lineage is collected as part of the same metadata ingestion workflow. Configuring the **Db Service Prefixes** field (covered below) is optional but recommended — it restricts table matching to specific database services. If left blank, Collate attempts to match source tables across all ingested database services.
<img src="https://mintcdn.com/collatedocs/tp-XigydVK-rcvyo/public/images/connectors/lineage-information.png?fit=max&auto=format&n=tp-XigydVK-rcvyo&q=85&s=273bde211d6de5be2fd19a12c371e1a9" alt="Lineage Information" width="2152" height="762" data-path="public/images/connectors/lineage-information.png" />

### How to Set Up Lineage

1. Go to **Settings** > **Services** > **Dashboards**.
2. Click the dashboard service you've added.
3. Go to the **Agents** tab, then select **Add Agent** > **Add Metadata Agent**.

   If a metadata agent already exists, select the three-dot context menu (⋮) next to it and select **Edit**.
4. In the **Configure Ingestion** step, scroll down to the **Lineage Information** section.
5. Optionally enter one or more database service names in the **Db Service Prefixes** field to restrict table matching to specific services. If left blank, Collate searches across all ingested database services.

The **Db Service Prefixes** field helps Collate locate the source tables and draw the lineage path from table to dashboard.

**Examples of valid entries:**

| What you enter | What it matches |
| - | - |
| `SnowflakeProd` | All tables in the Snowflake service named `SnowflakeProd` |
| `SnowflakeProd.sales_db` | Tables in the `sales_db` database within `SnowflakeProd` |
| `SnowflakeProd.sales_db.public` | Tables in the `public` schema within `sales_db` |

<Tip>
  If your dashboards pull data from multiple database services, add each service as a separate entry in the **Db Service Prefixes** field.
</Tip>

## Troubleshooting

<Columns cols={2}>
  <Card title="Looker Troubleshooting" href="/connectors/dashboard/looker/troubleshooting">
    Learn more about how to troubleshoot common Looker connector issues and resolve configuration or ingestion errors.
  </Card>
</Columns>


This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.